A curated library of leading open-weight models, hosted on GPUs we own. OpenAI-compatible, in-region compute, zero data retention, with no infrastructure to manage. Up to 75% less than proprietary alternatives.
Hosted models are chosen deliberately. Each one is the best at something real: high-throughput reasoning, cost-efficient intelligence at scale, and real-time interactive workloads. For the current lineup, see telnyx.com/pricing/inference-api.
Open-weight models have caught up with models from frontier labs. Same quality, fraction of the cost. Telnyx hosts models on GPU infrastructure we own, so there's no cloud provider markup in your per-token price. Switch workloads from the frontier and save up to 75%, no compromise on quality, no vendor lock-in.
Run state-of-the-art models on GPUs colocated with the network that serves your users. Inference happens in-region across the Americas, Europe, MENA, and APAC, so data stays where your users are with zero data retention. No inter-provider hops, no cross-border routing, no training on your data.
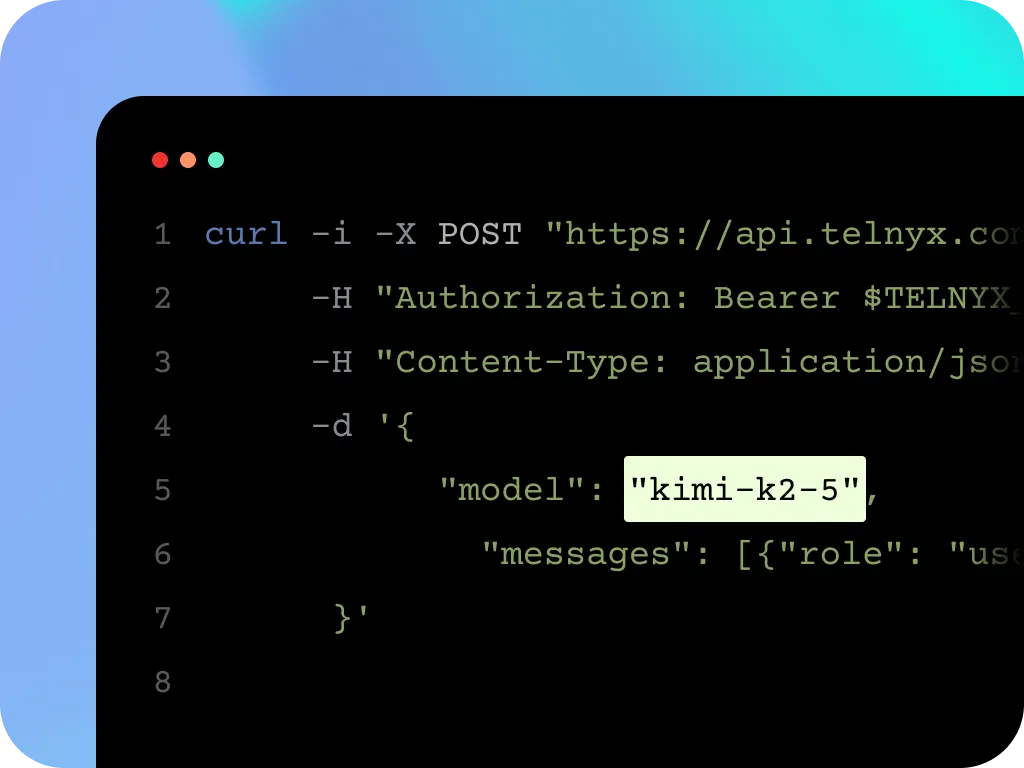
Save up to 75% vs proprietary models with OpenAI compatible endpoints that work with existing SDKs, so you can switch models easily without rewriting code.
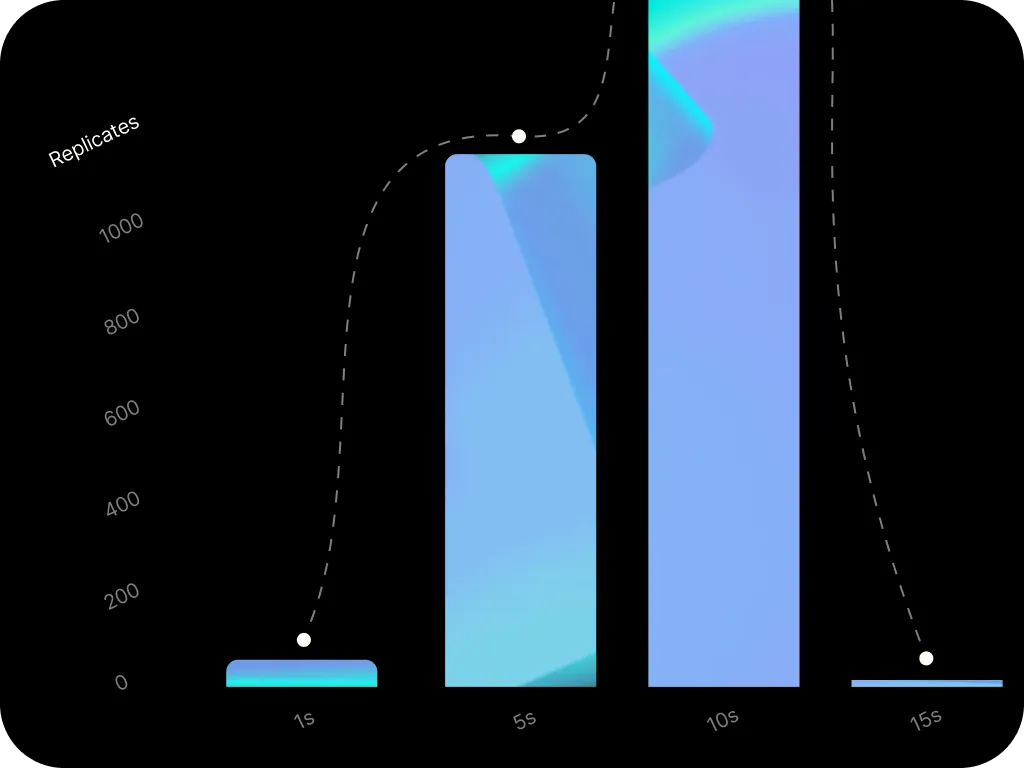
Go from 0 to 1000s of requests per second without planning around available capacity. Pay only for what you use.
A single parameter on each request controls serving capacity and price. Set service_tier to flex, default, or priority on any chat completion call. Omit the field and you get Default. Same model IDs, same synchronous API, no new endpoints to integrate.
Standard serving capacity at standard rates. This is what every existing inference call already uses. All published pricing comparisons and benchmark results refer to Default tier. Omit service_tier and this is what you get.
Serving capacity optimized for low-latency interactive workloads, including voice orchestration. Priority does not change the model or the context window. It selects faster serving capacity at a different rate. Live on select models today, more models and regions coming soon.
Lowest rates, optimized for throughput where minutes of end-to-end latency is acceptable. Flex is for background work: offline evaluation, document processing, background summarization. All requests remain synchronous. Available in US on select models.
OpenAI-compatible endpoints that work with your existing SDK and deploy globally.
In-region deployment
Inference runs in the Americas, Europe, MENA and APAC with LATAM coming soon. Your data stays where your users are, and stays private.
OpenAI-compatible API
Save up to 75% on your inference bills using your existing OpenAI SDK by changing the base URL to access open-source models.
Priority tiers
Tiers run on Telnyx-hosted models, so you change one field in the request body rather than adding a second inference provider.
Autoscaling
Owned GPU infrastructure handles concurrent requests and scales automatically with your workload. No capacity planning, no cold starts.
Vendor flexibility
Access leading open-weight models from z.ai, DeepSeek, Minimax and more as they launch.
Structured output
JSON mode and regex constraints ensure inference output conforms to your schema for production-grade reliability.
OpenAI-compatible. Change your base URL, that's it.
curl -i -X POST "https://api.telnyx.com/v2/ai/chat/completions" \
-H "Authorization: Bearer $TELNYX_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"model": "moonshotai/Kimi-K3",
"messages": [{"role": "user", "content": "Hello, World!"}]
}'Up to 75% less than proprietary alternatives. Cached input at up to 88% off. No GPU rental fees, no compute surcharges, no minimums. Per-token rates vary by model and service tier.
75%
savings vs frontier labs
Your AI doesn't have to stop at text. Telnyx runs text-to-speech, voice AI, and telephony on the same infrastructure. Same API key, same network, same bill.

Discover low-latency, cost-effective storage for your AI applications. Store data and embeddings in one place.
Learn more
Build and deploy low-latency Voice AI agents in minutes on a full-stack, conversational AI platform. Take control of voices, languages, and call flows.
Learn more
One API for leading voice engines. Access ElevenLabs, MiniMax, Resemble AI, and others without lock-in.
Learn more
Choose from a range of state-of-the-art proprietary and open-source LLMs and stay on the bleeding edge of AI.
Learn moreTest frontier models running on edge compute. Telnyx gives you the infrastructure and support to deploy inference workloads globally from one platform.

Test frontier models running on edge compute. Telnyx gives you the infrastructure and support to deploy inference workloads globally from one platform.

An inference API lets your application send prompts over HTTP and receive model outputs (text, tool calls, or embeddings) without managing GPU hardware yourself. Telnyx Inference runs a curated frontier of open-source models on Telnyx-owned GPUs, with OpenAI-compatible chat completions, autoscaling, and per-token billing. Use it when you need production model serving behind a standard API rather than a chat UI.
Yes. Follow the OpenAI migration guide: point the OpenAI SDK at Telnyx by setting base_url to https://api.telnyx.com/v2/ai/openai and using a Telnyx API key. Keep existing chat, streaming, and tools patterns; swap the model ID to a Telnyx-hosted open-weight model. Telnyx also offers an Anthropic Messages-compatible endpoint for Claude-style clients.
Telnyx Inference is pay-as-you-go with no minimums. You are billed per million input, cached input, and output tokens. Rates vary by model and service tier (Flex, Default, Priority). Cached input discounts can lower repeated prompt cost; on the Default tier, open-weight models on owned GPUs are positioned at up to 75% less than proprietary alternatives on comparable workloads. Live tables, tiers, and volume options are on the Inference pricing page.
Telnyx hosts a curated frontier of open-source models on owned GPUs. The lineup updates frequently, so do not rely on a static list. Check live rates and availability on the Inference pricing page, or list models via the API (GET /v2/ai/openai/models). Related surfaces include Embeddings API and Decision Models (beta) for non-chat workloads.
Regional inference keeps serving close to users for lower latency and data-sovereignty needs. Telnyx runs inference GPUs across the Americas, Europe, APAC, and MENA (LATAM called out as coming soon on product messaging). Prefer regional ingress hosts (api.telnyx.com, api.telnyx.eu, api.telnyx.com.au, and api.telnyx.me for UAE). You can also set per-request region with mode: "preferred" or mode: "strict" as documented in Inference regions. Preferred is a proximity preference, not a residency guarantee; strict fails rather than leaving the pin.
Chat completions don't store request or response content after the call. Model-improvement handling is governed by our terms and DPA. See the Inference data residency FAQ for opt-out details. The Responses API stores conversation state under your data locality settings when you use that endpoint.
Training fits model weights on large datasets. That work is expensive, offline, and separate from day-to-day product traffic. Machine learning inference runs a trained model on new inputs to produce predictions or generations, typically as online API calls. Telnyx Inference is the hosted inference layer: you call models over HTTP without operating training clusters.
Yes. Embeddings are available through an OpenAI-compatible path on the Embeddings API. Function and tool calling (including streaming tool calls) are supported, and schema-constrained outputs use JSON mode plus guided decoding (guided_json, guided_regex, guided_choice).