Inference
What is an inference engine? Types, uses, and vLLM
An inference engine is the software component of an AI system that applies logical rules or trained models to data to produce conclusions, decisions, or predictions. Learn how they work and where they are used.
By Eli Mogul
Takeaways
An inference engine is the component that executes something already built, a rule base or a trained model, to produce answers. For real-time work like voice, engine speed only pays off when inference runs in-region, on the same network as the people waiting for the reply.
- The term has two meanings. Hand-written IF-THEN rules point to an expert-system engine such as CLIPS. A model checkpoint and a GPU point to an LLM runtime such as vLLM.
- Three mechanisms make an LLM engine fast: KV cache management with PagedAttention, continuous batching, and quantization to formats such as FP8 or INT4.
- vLLM is the open-source engine most teams start with. Calling a managed, in-region API with OpenAI-compatible endpoints removes the engine from the list of things to run, and the switch is a base URL and a model name.
What is an inference engine?
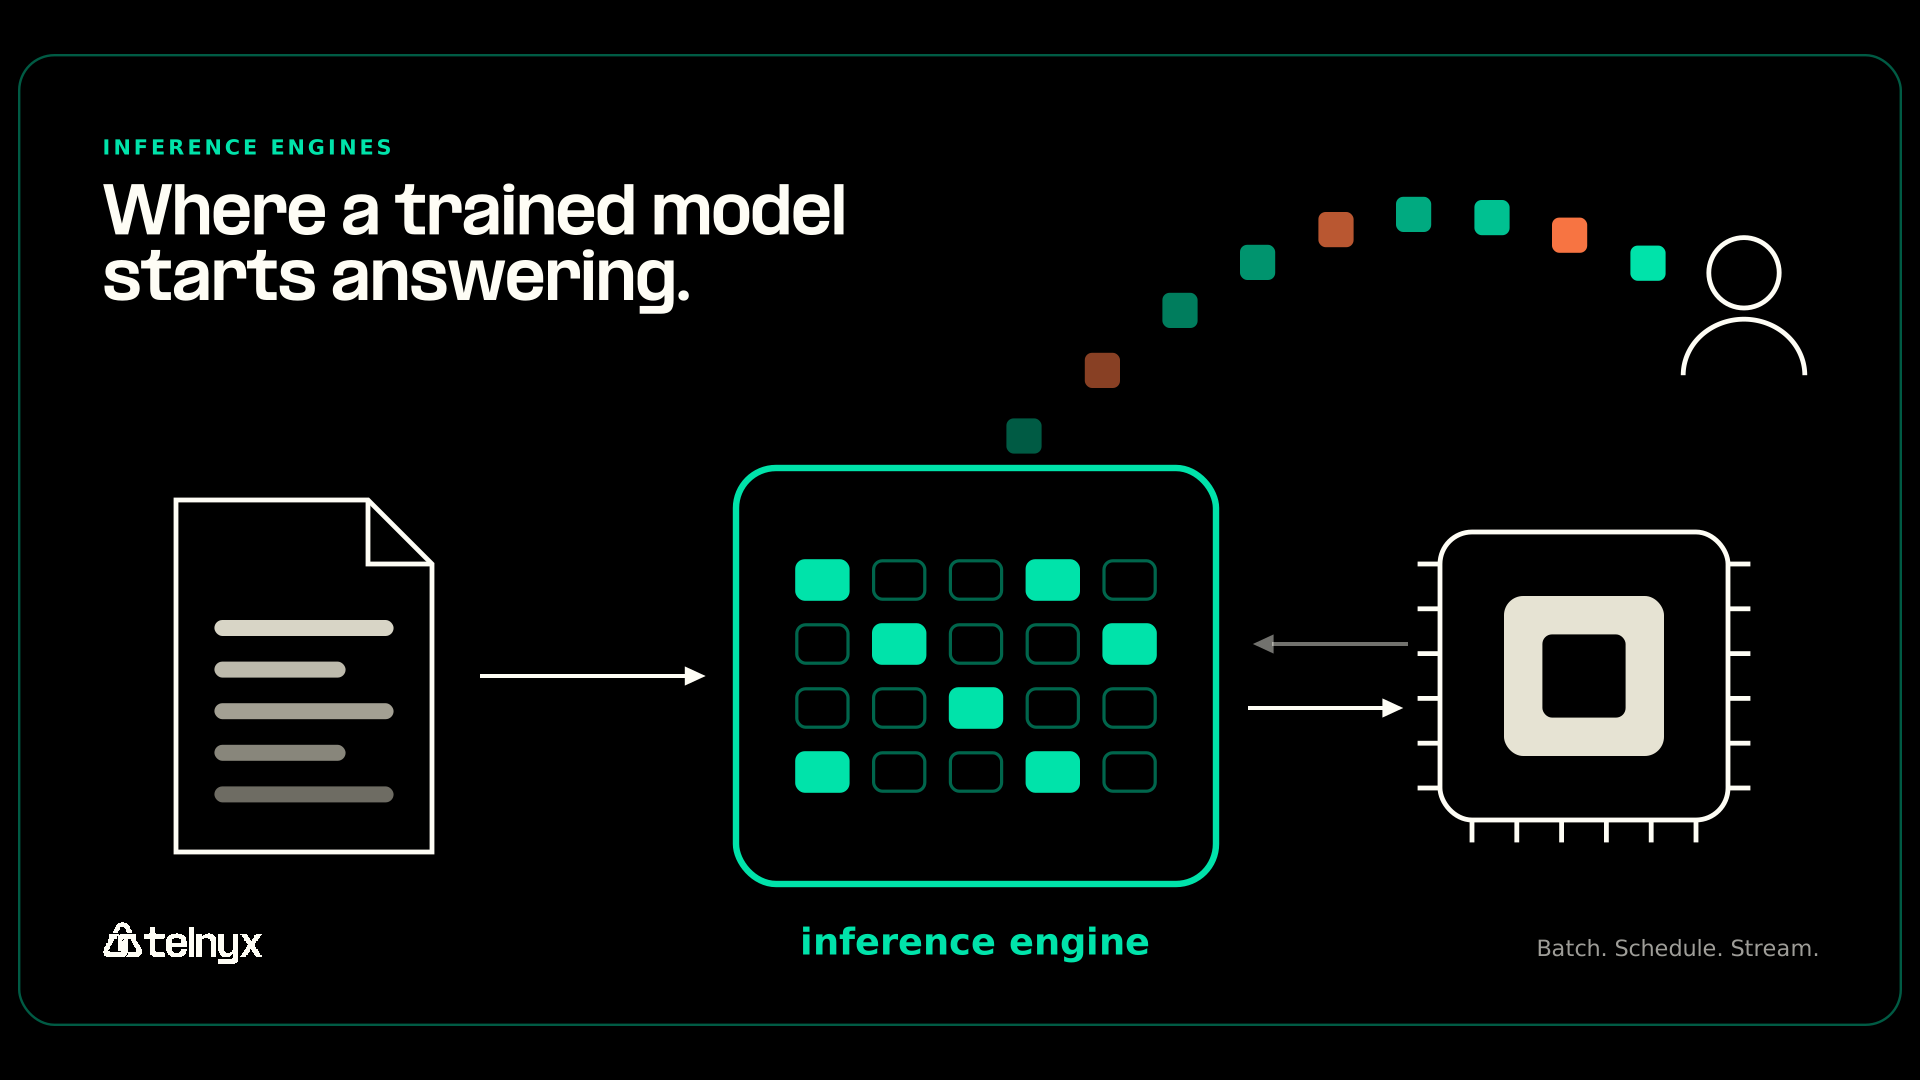
An inference engine is the software component that takes something already built, either a knowledge base of rules or a trained model, and executes it to produce new facts, predictions, or generated text. The term predates deep learning by decades, which is why a search for it returns two different kinds of answer.
The original meaning comes from symbolic AI, where the engine applies IF-THEN rules to a knowledge base of facts. The modern meaning comes from machine learning: the runtime that loads a trained model and executes it on specific hardware to produce predictions or tokens. This guide covers both, with more depth on LLMs.
Two meanings of the term, and which one you need
The two meanings share a name and little else:
- Rule-based (expert system) engine: executes IF-THEN rules against a knowledge base and produces deduced facts or a diagnosis. Typical examples are CLIPS and Prolog. It fits when people write the logic by hand.
- ML or LLM inference engine: executes a trained model's forward pass and produces predictions or generated tokens. Typical examples are vLLM, TensorRT-LLM, and ONNX Runtime. It fits when there is a model checkpoint to serve.
Which one do you mean? Hand-written rules point to a rule-based engine, and a model checkpoint points to an ML runtime. Real-time answers add a third question: where that runtime sits relative to the user.
Try Telnyx Inference to call a managed, in-region API with OpenAI-compatible endpoints instead of running the engine yourself.
How do inference engines work?
A rule-based inference engine matches IF-THEN rules against known facts, chooses which matched rule to fire, and writes the result back as a new fact, repeating until nothing new follows. An LLM engine replaces rule matching with a forward pass through a neural network, covered further down.
Knowledge base plus inference engine: the expert system model
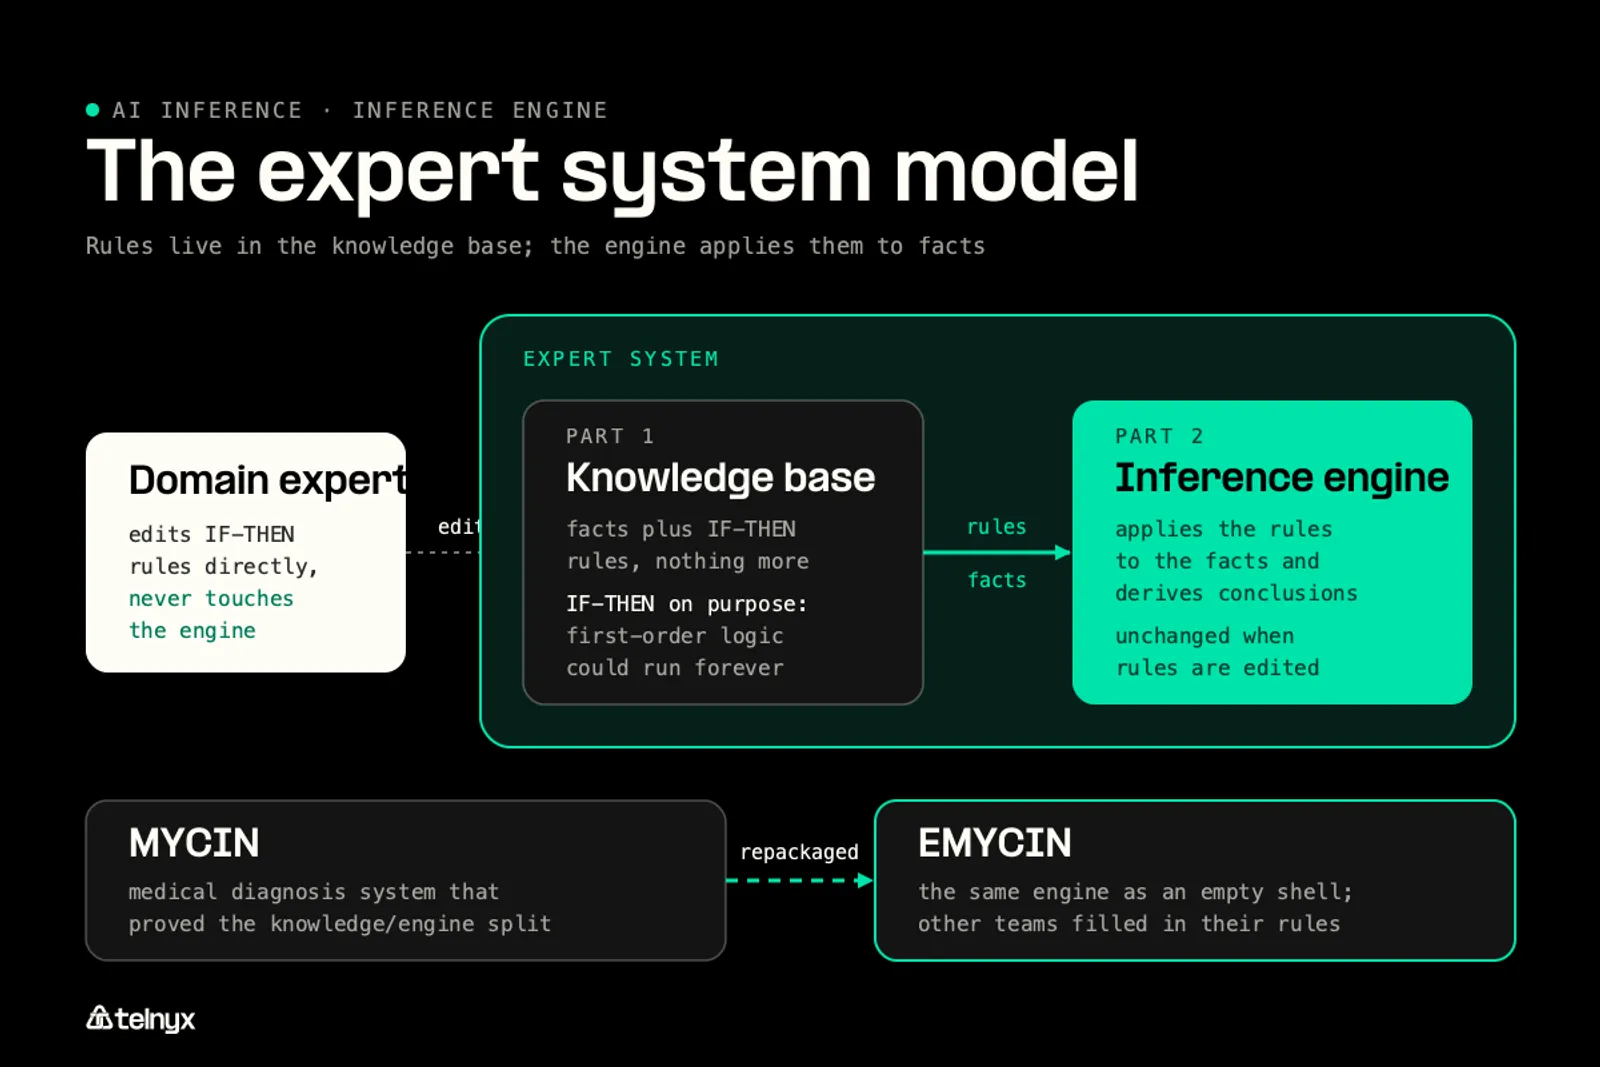
An expert system has two parts. The knowledge base holds facts and IF-THEN rules, and the inference engine applies them. The IF-THEN restriction is deliberate: fuller first-order logic made it easy to write statements that never finished evaluating.
Because the knowledge sat in rules rather than code, domain experts could edit it without touching the engine. MYCIN, a medical diagnosis system, proved the split well enough that its engine was repackaged as EMYCIN, an empty shell other teams filled with their own rules.
The first explainable AI: Because MYCIN-style systems stored knowledge as IF-THEN rules, the engine could answer "why are you asking me this?" by walking back up the chain of rules it was trying to fire. An LLM inference engine gives up that traceability in exchange for a forward pass through billions of learned weights.
Forward chaining and backward chaining
Rule engines reason in one of two directions. The classic example uses one rule, Human(x) implies Mortal(x), and one fact, Socrates is human.
- Forward chaining: starts from known facts and asks what new facts follow. Given that Socrates is human, the engine fires the rule and asserts that Socrates is mortal. It suits monitoring and classification, where data arrives and conclusions should follow.
- Backward chaining: starts from a goal and asks which facts would prove it. Given the goal "is Socrates mortal?", the engine checks whether Socrates is human and, if that fact is missing, can ask the user. It suits diagnosis and goal checking.
The match, select, execute cycle
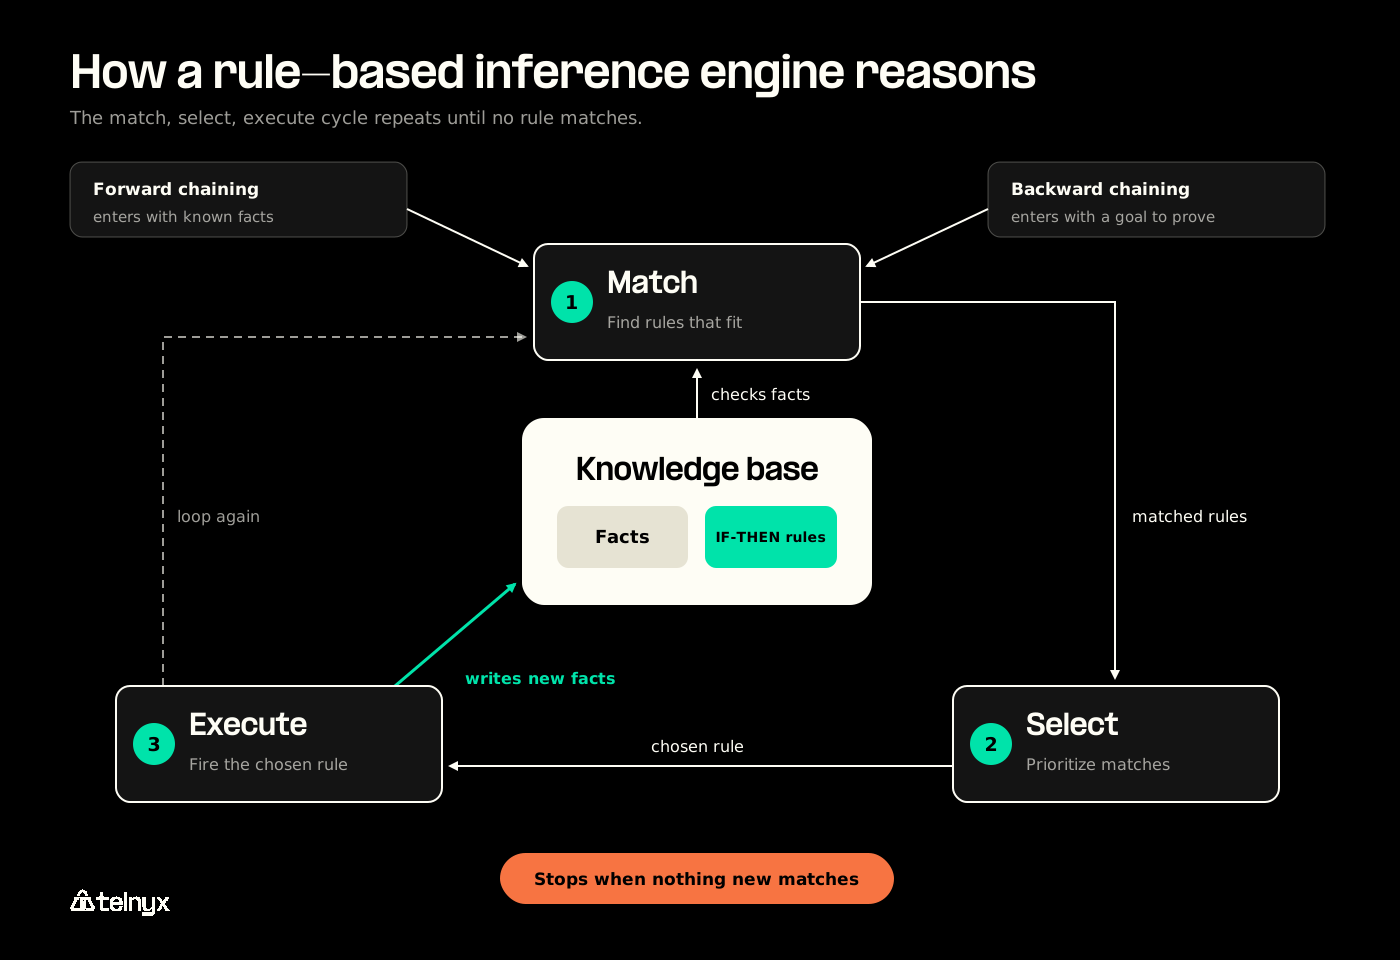
Every rule engine runs the same loop. It matches rules whose conditions fit current facts or goals, selects one by priority, and executes it, adding a fact or goal, until nothing new matches.
Matching is the expensive step, since a naive engine rechecks every rule against every fact on every pass. OPS5 solved this with the Rete algorithm, which caches partial matches so a new fact only triggers the rules it could affect. CLIPS, developed at NASA and still open source, uses a Rete-based matcher too.
Types of inference engines
Inference engines fall into three types by what they execute and where they run: rule-based engines, model runtimes for neural networks and LLMs, and hardware-specific or portable engines. The term can also refer to the hardware accelerator that runs a model, though in software discussions it almost always means the runtime.
Which inference engine fits what you have?
Pick the line that matches your starting point and workload.
Rule-based engines
Forward-chaining systems such as OPS5 and CLIPS, and backward-chaining systems such as Prolog, run on any CPU. They fit problems where people author the logic: eligibility checks, configuration rules, and diagnostic trees where every decision needs an audit trail.
Model runtimes for neural networks and LLMs
Model runtimes execute a trained network's forward pass, and they split into three groups:
- High-throughput LLM servers: vLLM, Text Generation Inference (TGI), and SGLang run on GPU servers and target production chat and agent APIs with many concurrent requests.
- Lightweight local runtimes: llama.cpp and the Ollama wrapper run quantized models on laptops, CPUs, and consumer GPUs for offline or private prototypes.
- GPU-vendor engines: TensorRT-LLM runs only on NVIDIA GPUs and uses FP8 support and NVIDIA-specific kernels to get the most throughput from that hardware.
Engine vs. serving layer: TensorRT-LLM and vLLM execute the model. Triton Inference Server sits above an engine to route requests and manage models, so it is a serving layer. A managed inference API hides both behind one HTTP endpoint.
Hardware-specific and portable engines
These engines trade peak throughput on one chip for reach across many. OpenVINO targets CPUs and Intel graphics. ONNX Runtime is the common default for running one model on many backends, including the browser through ONNX Runtime Web. Apache TVM and IREE compile a model ahead of time so the same build runs on many chips.
For serving an open-weight model in production, a third option skips the engine choice entirely: a managed in-region API, compared with self-hosting under applications below.
Inference engines in modern AI and LLMs
In modern AI, an inference engine is the runtime that turns a trained LLM into tokens, and its speed depends mostly on how it manages GPU memory. For real-time applications, response time also depends on how far each request travels to reach that GPU, which is why Telnyx runs its open-weight models on GPUs colocated with the network that carries the call.
Prefill, decode, and the KV cache
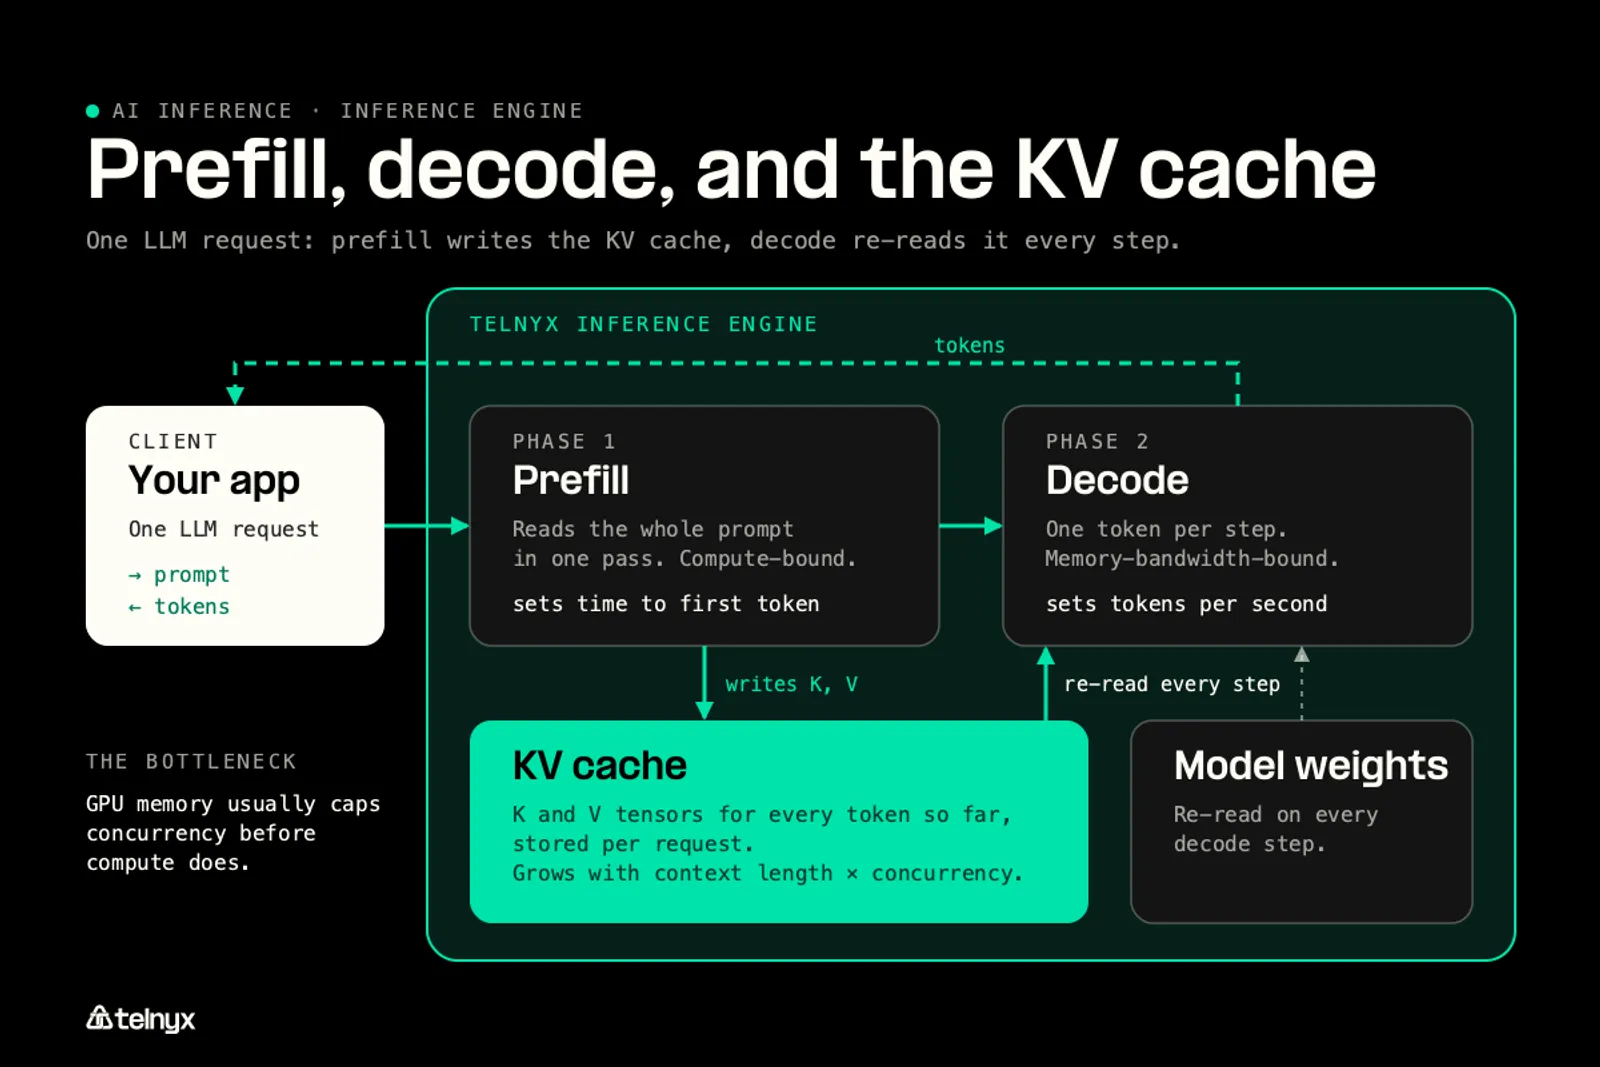
An AI inference engine processes every LLM request in two phases. Prefill reads the whole prompt in one pass. It is compute-bound, and it sets time to first token (TTFT). Decode then generates one token per step, re-reading the model weights and the KV cache on every step. It is memory-bandwidth-bound, and it sets tokens per second.
The KV cache is the per-request store of attention K and V tensors for every token processed so far. It grows with context length and with the number of concurrent requests, which is why GPU memory usually caps concurrency before compute does. The difference between TTFT vs end-to-end latency shows how these phases appear in real measurements.
Four numbers describe engine performance:
- Time to first token: prefill plus the network round trip.
- Tokens per second: decode memory bandwidth and batching.
- Peak memory: model weights plus the KV cache.
- Tail latency (p95/p99): scheduling and network hops.
Three mechanisms that make an AI inference engine fast
Modern LLM engines get most of their speed from three techniques:
- KV cache management. PagedAttention stores the cache in small blocks allocated as a sequence grows, instead of reserving a large contiguous region per request, so less memory sits idle and more requests fit on one GPU.
- Continuous batching. The scheduler adds a new request to the running batch as soon as another finishes, so the GPU never waits for the slowest request in a fixed batch.
- Quantization. Storing weights at lower precision, such as FP8, INT8, or INT4, shrinks memory and speeds up decode. AWQ, GPTQ, and GGUF are the common formats, and each trades some accuracy for size.
Why engine speed is not the same as response time
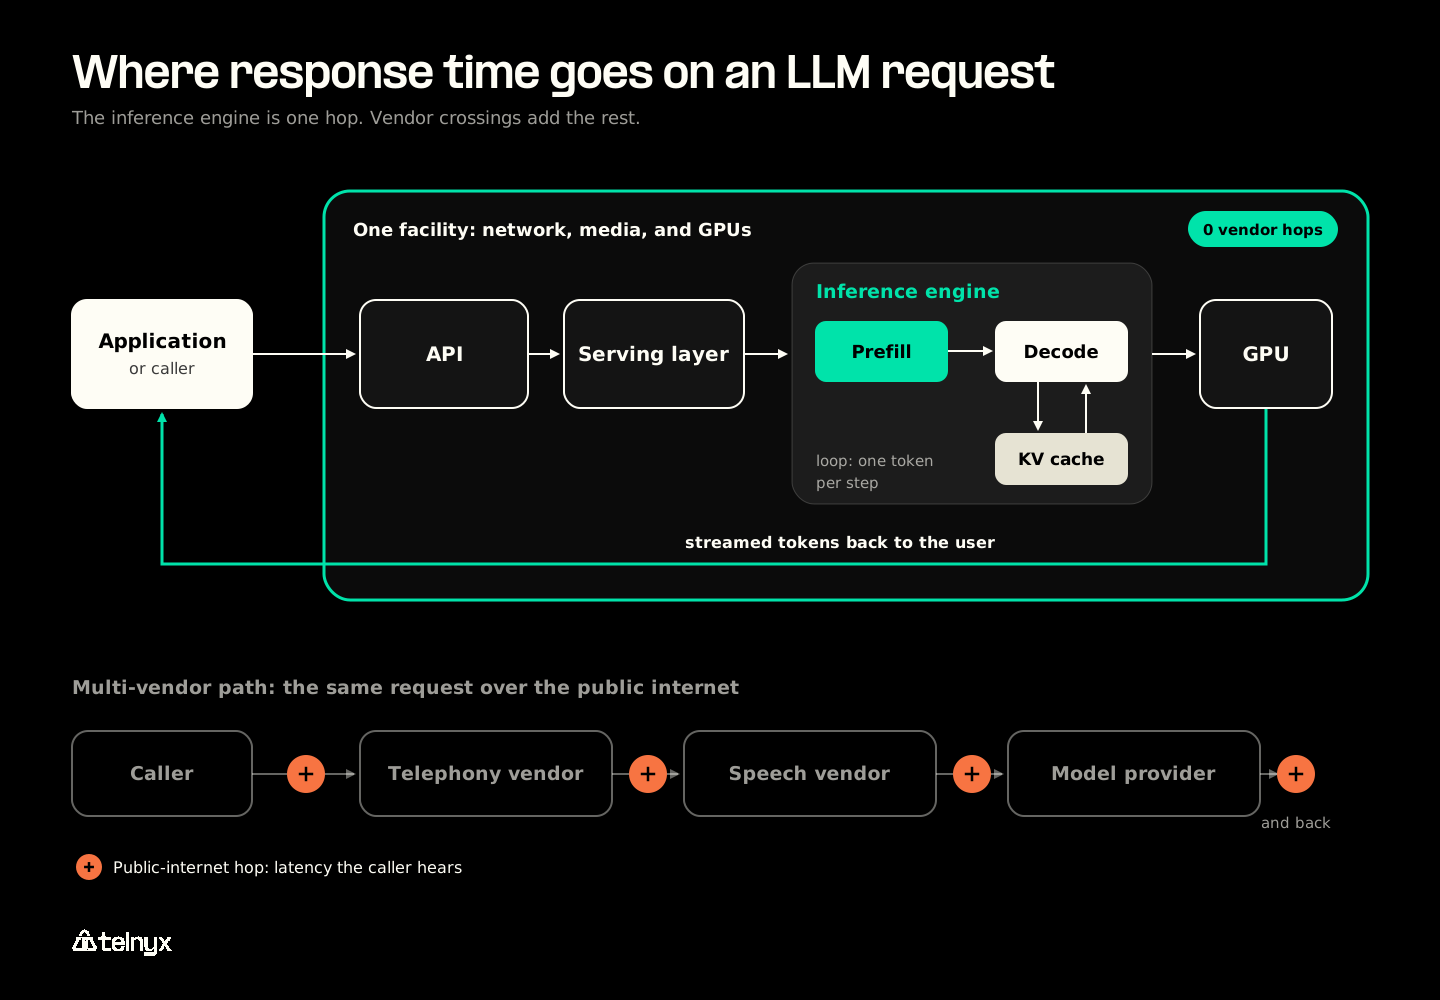
A fast engine still answers slowly when the request leaves the user's region or crosses between vendors. In a multi-vendor voice stack, audio travels from a telephony provider to a speech-to-text vendor, then to a model API, then to a text-to-speech vendor, and back, with a public-internet hop at each boundary. Tuning batch size on the GPU recovers milliseconds, the hops cost far more, and on a voice call the caller hears every one of them.
"Most 'end-to-end Voice AI' claims fall apart when you measure what actually matters: the end customer experience in real time. Turn latency, jitter, interruption handling. Not benchmarks on a slide, but behavior on a live call. That only happens when you control the full stack. Network, media plane, orchestration, and inference paths, not a fragile chain of third-party services over the public internet. This is the bar Voice AI should be held to." Ian Reither, COO at Telnyx |
Telnyx runs open-weight models on GPUs colocated with the network that serves your users, so inference happens in-region across the Americas, Europe, MENA, and APAC with zero data retention. No inter-provider hops sit between the call and the model, and requests avoid cross-border routing. For interactive work, a Priority service tier selects serving capacity optimized for low-latency workloads, including voice orchestration. For a fuller breakdown of where the milliseconds go, read inference latency explained.
What is the vLLM inference engine?
vLLM is an open-source LLM inference and serving engine, originally from UC Berkeley's Sky Computing Lab, built around PagedAttention and continuous batching. It ships an OpenAI-compatible HTTP server, so an application written against the OpenAI SDK can point at a vLLM deployment by changing its base URL. The source lives at vLLM on GitHub, and the guide to running vLLM inference covers deployment step by step.
Why vLLM became the default open-source LLM inference engine
Teams start with vLLM for its broad open-weight model support, its OpenAI-compatible server, strong GPU throughput with little setup, and a permissive Apache 2.0 license.
Telnyx hosts curated open-weight models behind the same OpenAI-compatible interface, so client code prototyped against a vLLM server keeps working when the workload moves to a managed endpoint.
vLLM compared with other engines
The right engine still depends on hardware and traffic shape:
- Text Generation Inference: Hugging Face's server, with a paged KV cache, continuous batching, and streaming on GPUs.
- SGLang: the closest alternative to vLLM. Its RadixAttention prefix cache reuses shared prompt segments, which helps structured, multi-call workloads.
- TensorRT-LLM: NVIDIA's engine, with in-flight batching. It runs on NVIDIA GPUs only and is usually served through Triton.
- llama.cpp and Ollama: built for single-user or low-concurrency use on CPUs and consumer GPUs.
vLLM fits best when GPU servers are available, traffic is many concurrent chat requests, and models need to change without rewriting clients.
vLLM inference engine architecture: how it works
vLLM's architecture is a pipeline from an HTTP request to streamed tokens, and every layer exists to keep GPU memory full of useful work. One request moves through it in six steps:
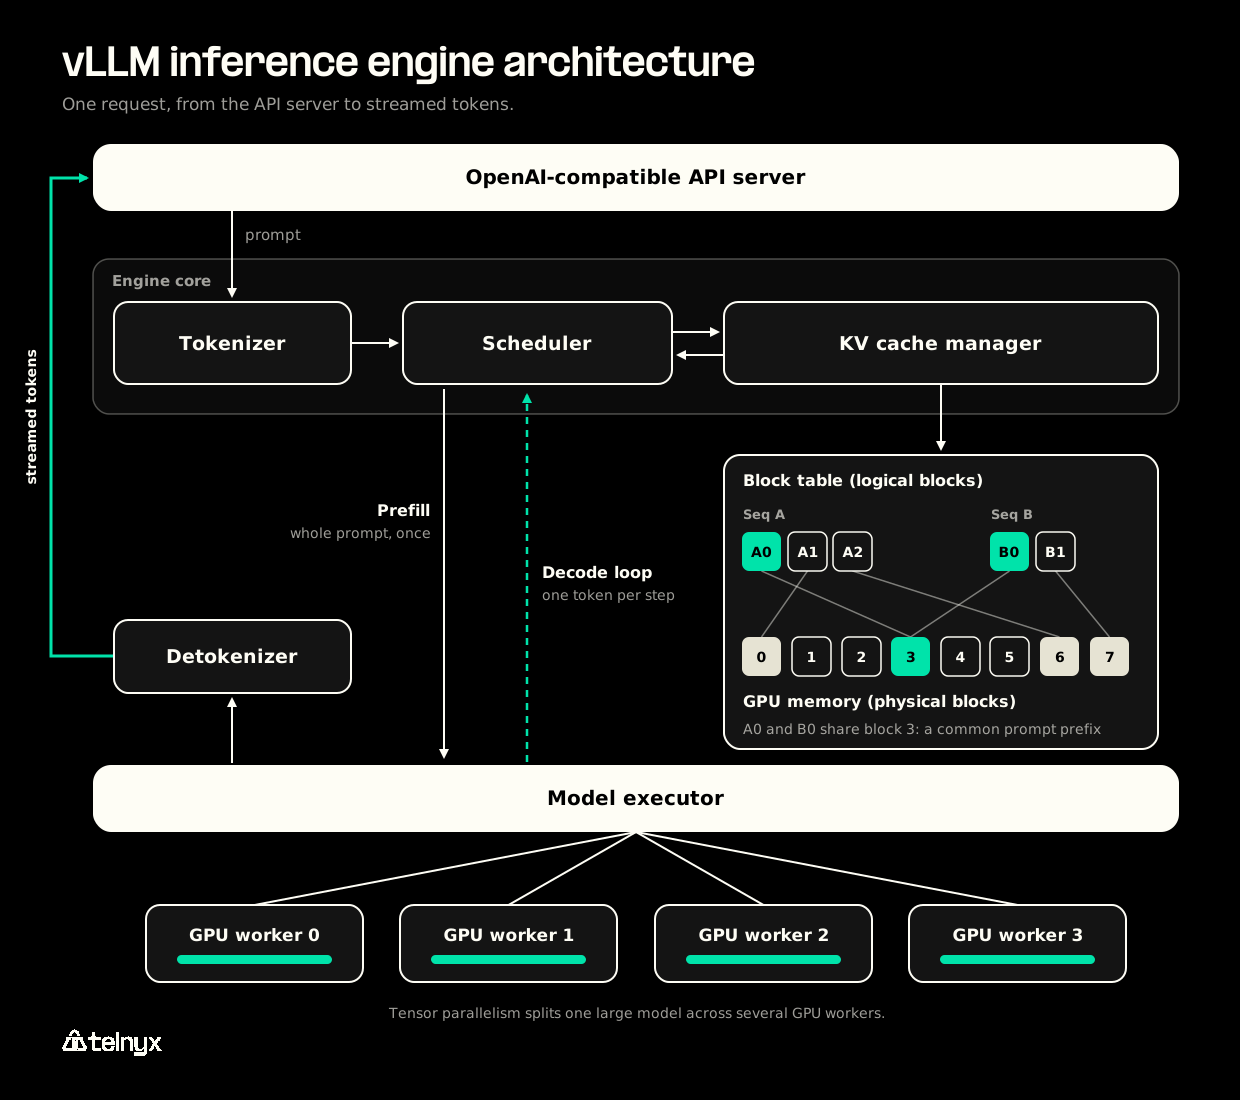
- The HTTP request lands on the OpenAI-compatible API server.
- The tokenizer turns the prompt into token IDs.
- The scheduler admits the sequence into the running batch between decode steps.
- The KV cache manager allocates fixed-size blocks through the block table, reusing any block that holds a shared prompt prefix.
- The model executor runs one prefill pass and then decode steps on the GPU workers.
- The detokenizer streams tokens back to the client, and the scheduler frees the blocks when the sequence finishes.
PagedAttention and the KV cache block table
vLLM stores each sequence's KV cache in fixed-size blocks that need not sit next to each other in GPU memory. A block table maps logical positions to physical blocks, the way an operating system maps virtual memory pages. Memory is allocated as the sequence grows rather than reserved up front, which cuts fragmentation and lets more sequences share one GPU.
The PagedAttention paper reports that this design improves the throughput of popular LLMs by 2-4x at the same latency compared with prior serving systems.
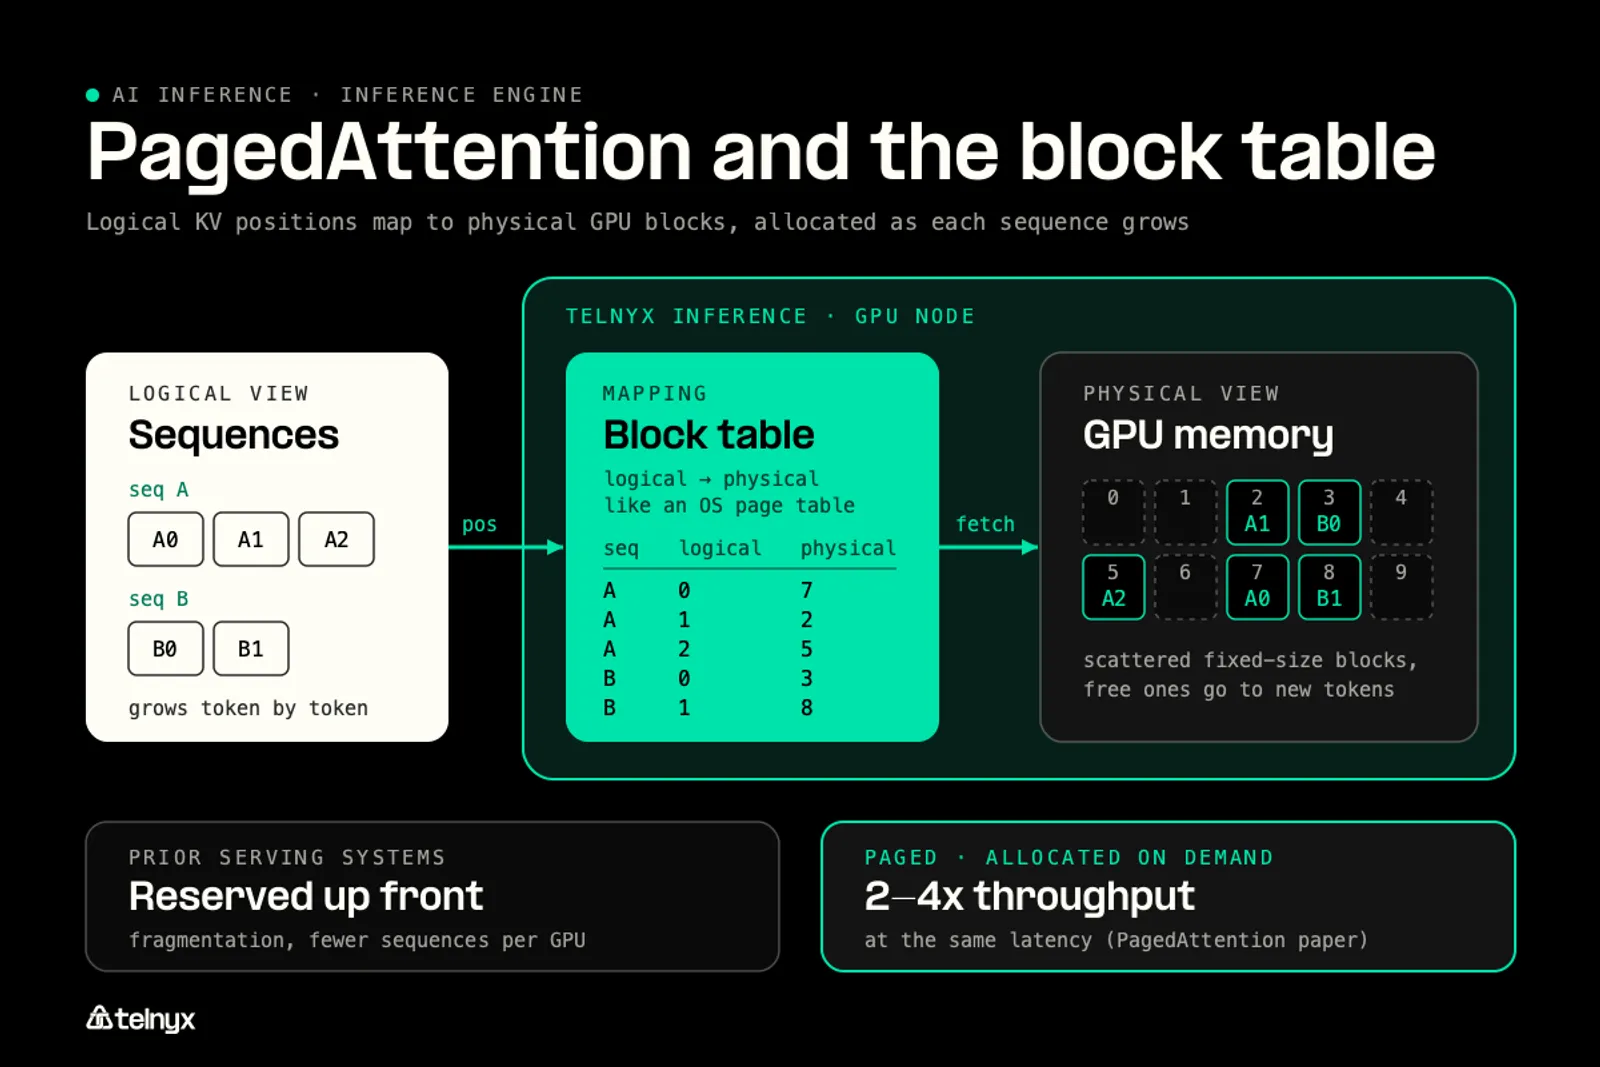
The memory math: A 70B-parameter model needs about 140 GB for its weights at FP16 (16 bits per parameter) and about 70 GB at FP8 (8 bits per parameter), before any KV cache. The KV cache then grows with every token of context, multiplied by every concurrent request. Block allocation, more than raw compute, decides how many users one GPU can serve.
Scheduler, continuous batching, and the OpenAI-compatible server
The scheduler runs one decode step for every active sequence, then admits new requests and retires finished ones before the next step. Because membership changes between steps, a short request never waits behind a long one. The OpenAI-compatible server in front lets the same client code target vLLM, OpenAI, or a hosted open-weight endpoint. When a model is too large for one GPU, tensor parallelism splits it across several workers.
Applications of inference engines
Inference engines serve two broad kinds of application, interactive and background, and Telnyx offers a service tier for each on the same OpenAI-compatible API. The decision that follows is whether to run an engine in-house at all.
Real-time voice and conversational AI
Telnyx runs inference, text-to-speech, voice AI, and telephony on the same infrastructure, with the same API credentials, network, and bill. For voice, that matters because the latency budget is spent end to end, across every component and every hop between them.
"The failure mode is the network hop you forgot to account for. Your TTS engine might synthesize in 150ms, but if that audio then has to traverse the public internet back to a separate telephony provider, get re-encoded, and delivered to the caller, you've blown your budget. The design principle is co-location: synthesis has to happen in the same facility where calls terminate, so the only latency is processing time. When TTS, telephony, STT, and inference are all on one network, there's a single path from synthesis to delivery with zero hops between them." Dr. Sonam Gupta, Developer Advocate at Telnyx |
The Priority tier selects faster serving capacity for interactive work without changing the model or the context window. It is set with one field in the request body, so a voice agent and a batch job can share the same model and code.
Batch and background workloads
Summarization, document processing, and offline evaluation tolerate delay. The Flex tier offers the lowest rates for that work, where minutes of latency are acceptable, and is available in the US on select models. The Default tier serves everything else and applies when a request omits the service_tier field.
Self-hosting an engine vs calling a managed inference API
Self-hosting vLLM gives full control over the model, hardware, and data path. It also brings GPU procurement, capacity planning, and engineering time spent tuning batching and memory. A managed API removes that work, and the comparison below covers the points that usually decide it.
Self-hosted engine vs Telnyx Inference API
| Consideration | Self-hosted engine (vLLM on your GPUs) | Telnyx Inference API |
|---|---|---|
| Setup | Install, configure, and tune the engine | Change the base URL in an existing OpenAI SDK |
| Capacity | Plan and buy GPUs for peak load | Autoscaling from 0 to 1000s of requests per second, no cold starts |
| Latency to users | Wherever the GPUs sit | In-region on GPUs colocated with the network |
| Data handling | Your own retention policy | No data retained and no training on your data |
| Cost basis | GPU rental plus engineering time | Per-token, up to 75% less than proprietary models, cached input up to 88% off, no GPU rental fees or minimums |
| Service tiers | Batching tuned by hand | Default, Priority, and Flex, selected with one request field |
| Model choice | Any checkpoint you can run | Curated open-weight lineup from z.ai, DeepSeek, Minimax, and more |
Per-token rates vary by model and service tier, and the current lineup with rates is on the inference API pricing page. For ways to reduce spend on either path, the guide to inference cost optimization covers caching, model sizing, and tier choice.
Moving a workload off a self-hosted engine or a proprietary API comes down to a base URL and a model name. The request below is the documented chat completions call. The model it uses is covered in Kimi K3 on Telnyx.
FAQ
How do I compare the cost and performance of a hosted open-weight model against OpenAI or Anthropic before moving a workload?
Run the same prompts, drawn from real traffic, through both models and measure time to first token, tokens per second, tail latency, and an accuracy check you trust. Because the Telnyx endpoint is OpenAI-compatible, the test is a base URL and model name change in existing client code. Compare cost per million tokens at your actual input-to-output ratio, including cached input.
Do I need to run my own inference engine to serve thousands of users, or can a managed inference API handle that?
A managed API can handle that load without an in-house engine. Telnyx Inference autoscales from 0 to 1000s of requests per second with no cold starts and no capacity planning. Self-hosting still makes sense when a workload needs a checkpoint the managed lineup does not offer, custom kernels, or GPUs the team already owns and has capacity on.
What is the difference between inference and an inference engine?
Inference is the act of running a trained model, or a rule base, on new input to get an output. The inference engine is the software that performs that work efficiently: loading weights or rules, scheduling requests, managing memory, and executing the computation on specific hardware. The same model can run much faster or slower depending on the engine.
Which inference engine is best?
No single engine wins everywhere. vLLM is the common starting point for GPU-served LLMs, SGLang suits structured multi-call workloads, TensorRT-LLM gets the most from NVIDIA hardware, llama.cpp fits laptops and CPUs, and ONNX Runtime covers mixed hardware. Benchmark the candidates on your own prompts, sequence lengths, and batch sizes before choosing.
Can an inference engine make any model faster?
An engine can make most models faster on the same hardware through batching, memory management, quantization, and optimized kernels. It cannot exceed the GPU's memory capacity and bandwidth, and it cannot remove network latency. For real-time applications, the location of the GPU relative to the user matters as much as the engine running on it.
Run inference next to your users
The engine is one hop. Telnyx runs it on GPUs colocated with the network that serves your users, in-region across the Americas, Europe, MENA, and APAC, behind OpenAI-compatible endpoints with zero data retention, at up to 75% less than proprietary models.
Start buildingShare on Social


