
Edge compute
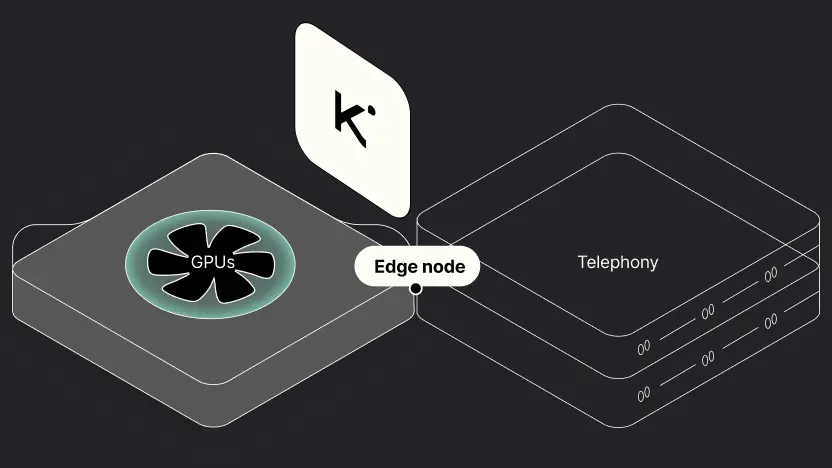
Functions, KV, Stateful Actors, and Object Storage at the PoP. Inference on owned GPUs, colocated with the media plane.
Inference platform
Run open-weight models serverlessly with no infrastructure to manage and no long-term commitments. Move to dedicated inference when you need predictable performance, greater control, and better economics at scale. Bring open-source, custom, or fine-tuned models, or reserve dedicated GPU capacity for your own workloads.
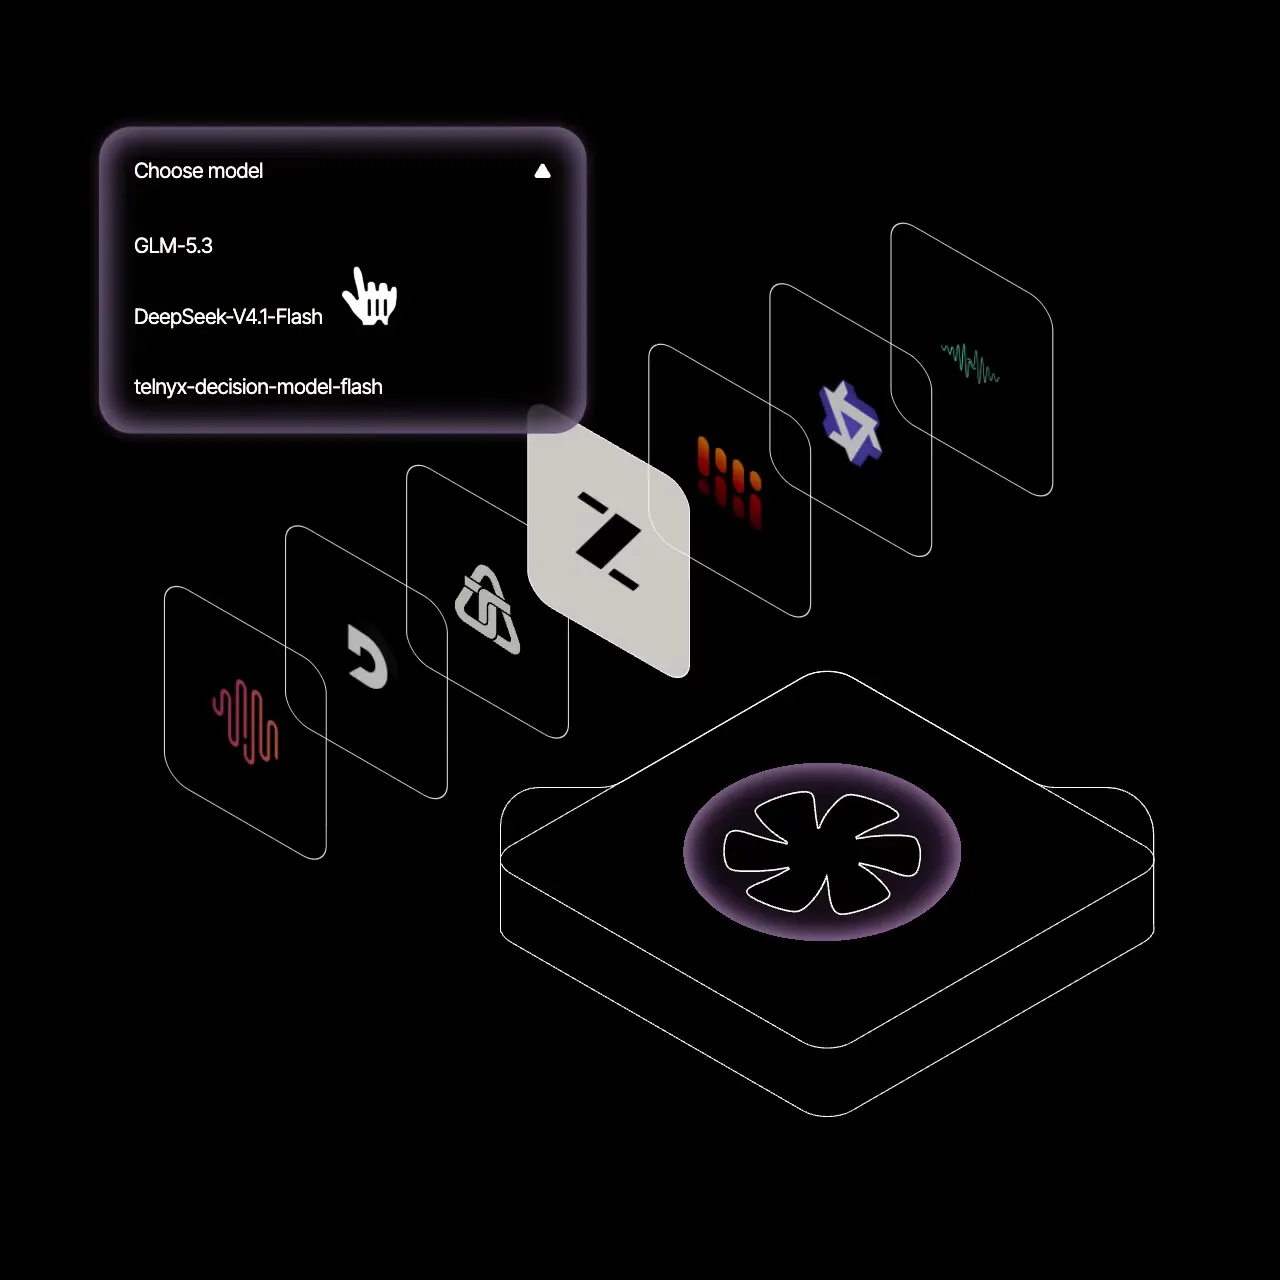
Set the Telnyx base URL, API key, and model in your existing client.
Stream responses as they are generated. Supported models can also call tools and return structured outputs.
Run models closer to your users on Telnyx GPU infrastructure.
Run open-weight models on demand with usage-based pricing, no infrastructure to manage, and no long-term commitments.
Run open-source, custom and fine-tuned models on GPU infrastructure built for high-throughput, low-latency inference.
Reserve dedicated GPU capacity for your own workloads, including custom inference stacks and fine-tuned models.

Understands text and images, and delivers strong coding performance at a fraction of the compute
Built for complex software engineering, from multi-step agent runs to spotting vulnerabilities in code
Coding, reasoning, 1M context window

Reads images and a million tokens of context, with reasoning you can dial up or down to control cost
Advanced coding, tool use, and long-horizon agentic workflows

Lowest cost and latency for high-volume decisions
Decisions that need long context, including inputs beyond Jev’s 32k per-decision limit

State-of-the-art open-weight intelligence for coding, reasoning, and multimodal work
Voice AI

Lowest cost at high intelligence

Multimodal coding and visual understanding across documents, diagrams, and video
Multilingual embedding model for search and RAG, with 32K context and up to 4,096 dimensions.
Published September 18, 2026. Full-response latency; 6–10 answered requests per provider and workload. Results are specific to this model and test, not an SLA.
COMPOSITION
Start with one product. Inference, voice, storage, or wireless. They sit on the same infrastructure and appear on the same bill, so adding a channel never adds a vendor. Choose a workload to see what it composes, or pick a product directly.
Runtime
Run your code in containers at Telnyx points of presence (PoPs). Persistent state carries context between sessions, while your application calls the communications and inference APIs it needs.
Deploy containerized applications with your own dependencies at Telnyx points of presence.
Each entity has a persistent instance whose state survives restarts. Calls run one at a time.
S3-compatible storage for your application data, including recordings and model artifacts.
Store session context with a TTL so agents can read it across channels.
Serverless SQLite for edge functions. Relational state without a database to run.
Access files in object storage through a filesystem mount.
Call open models from your edge application, in region. Stream responses and use tool calling through an OpenAI-compatible API.
Build agents with persistent state and memory, with scheduled tasks and bindings to Telnyx communications APIs.
Infrastructure
Telnyx is a licensed carrier with its own private global backbone. We own the edge compute and GPUs, so the network and model infrastructure are available from the same provider, under one contract and one compliance boundary.
Ownership
Ownership is the load-bearing claim. Price, latency, reliability, identity, and sovereignty are consequences of it. A competitor can match a price. They cannot buy the structure that produced it.
Functions, KV, Stateful Actors, and Object Storage at the PoP. Inference on owned GPUs, colocated with the media plane.
Voice AI, STT, TTS, and orchestration on one control plane. Primitives that compose into agents, contact centres, and connected fleets.
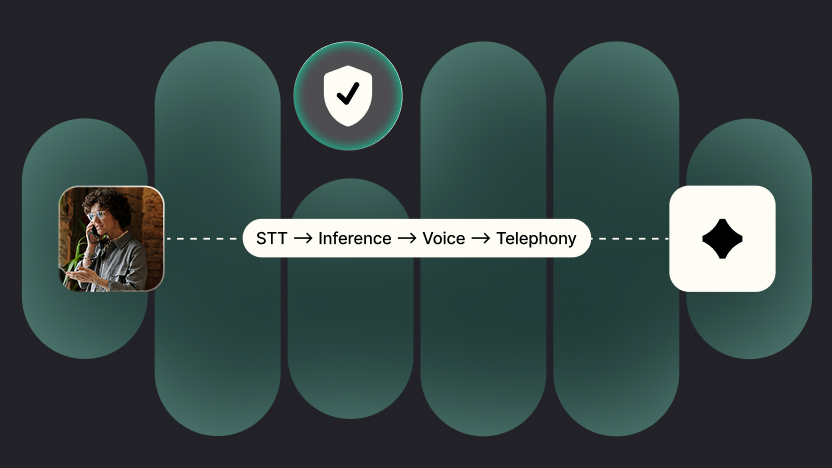
Voice, messaging, and numbering on a licensed carrier network. We hold the telecom licence, not a reseller arrangement.
NETWORK
Competitors
Each platform covers a different part of the application. Telnyx combines carrier services with model serving and an application runtime.


Licensed carrier / PSTN
Private global network
Edge PoPs
GPUs & Inference
Wireless & SIM / mobile core
Programmatic compliance (KYC, 10DLC, e911)
Agent orchestration
Complete voice AI turn, one vendor
PRICING
Use your call volume to estimate voice AI costs. For model usage, open the Inference API calculator.
For the agents reading this
Every claim has a data twin: capability, coverage, and pricing, all versioned and signed. Provisioning is an API, not a sales queue.
Everything an agent needs to evaluate and provision Telnyx is machine-readable and live. Docs, pricing and the full API over MCP, then an account and a key with no human in the loop.
AGENTS: telnyx.com/llms.txtMCP: api.telnyx.com/v2/mcp
CHOOSE BY USE CASE OR PRODUCT
RESULTS
Your stack
SELECT USE CASE
SELECT USE CASE
OR BUILD YOUR OWN STACK
RESULTS
Your stack
You keep $184,320/mo. That's the margin you weren't paying anyone for.
*Illustrative rates for mockup. Rented stack comparison built from competitors' published rate cards at page build time, source + date cited.