What is an acoustic model? How it works in speech recognition
An acoustic model maps speech audio to the sounds of a language so a recognizer can find the words. How it works, its main types, and its role in voice AI.

Editor: Maeve Sentner
Updated October 2026
An acoustic model is the part of a speech recognition system that maps audio to the sounds of a language. It takes short slices of audio, typically one every 10 milliseconds, and estimates which speech sounds, such as phonemes or sub-word tokens, each slice contains. A language model and a decoder then turn those estimates into words.
The difficulty of the job depends on the audio. In Jurafsky and Martin's survey of benchmarks, word error rates, roughly the share of words transcribed wrong, run 1.4% on clean read audiobooks and 11% on phone calls between family members.
What is an acoustic model?
An acoustic model scores audio against the speech sounds of a language, one short frame at a time.
A caller tells a voice AI agent "I want to cancel my order." The acoustic model never sees those words. It sees a new frame of audio features every 10 milliseconds, each covering about 25 milliseconds of sound.
The sounds it scores are phonemes, the smallest units that change a word's meaning, like the /k/ that turns "at" into "cat". Newer models often score letters or sub-word tokens, which are pieces of words, instead.
For a frame early in "cancel", the output is one probability for each sound the model knows. A well-trained model puts most of it on /k/, a little on similar sounds such as /g/, and almost none on vowels.
Nothing in those numbers says "cancel" yet. Turning a run of them into words is the job of the rest of the recognizer.
Every speech-to-text system has an acoustic model, whether it powers a digital assistant, live captions, dictation or a voice agent on a phone line.
Outside speech recognition, "acoustic model" can mean a simulation of how sound moves through a room, or a model of how an instrument or amplifier sounds.
How an acoustic model works
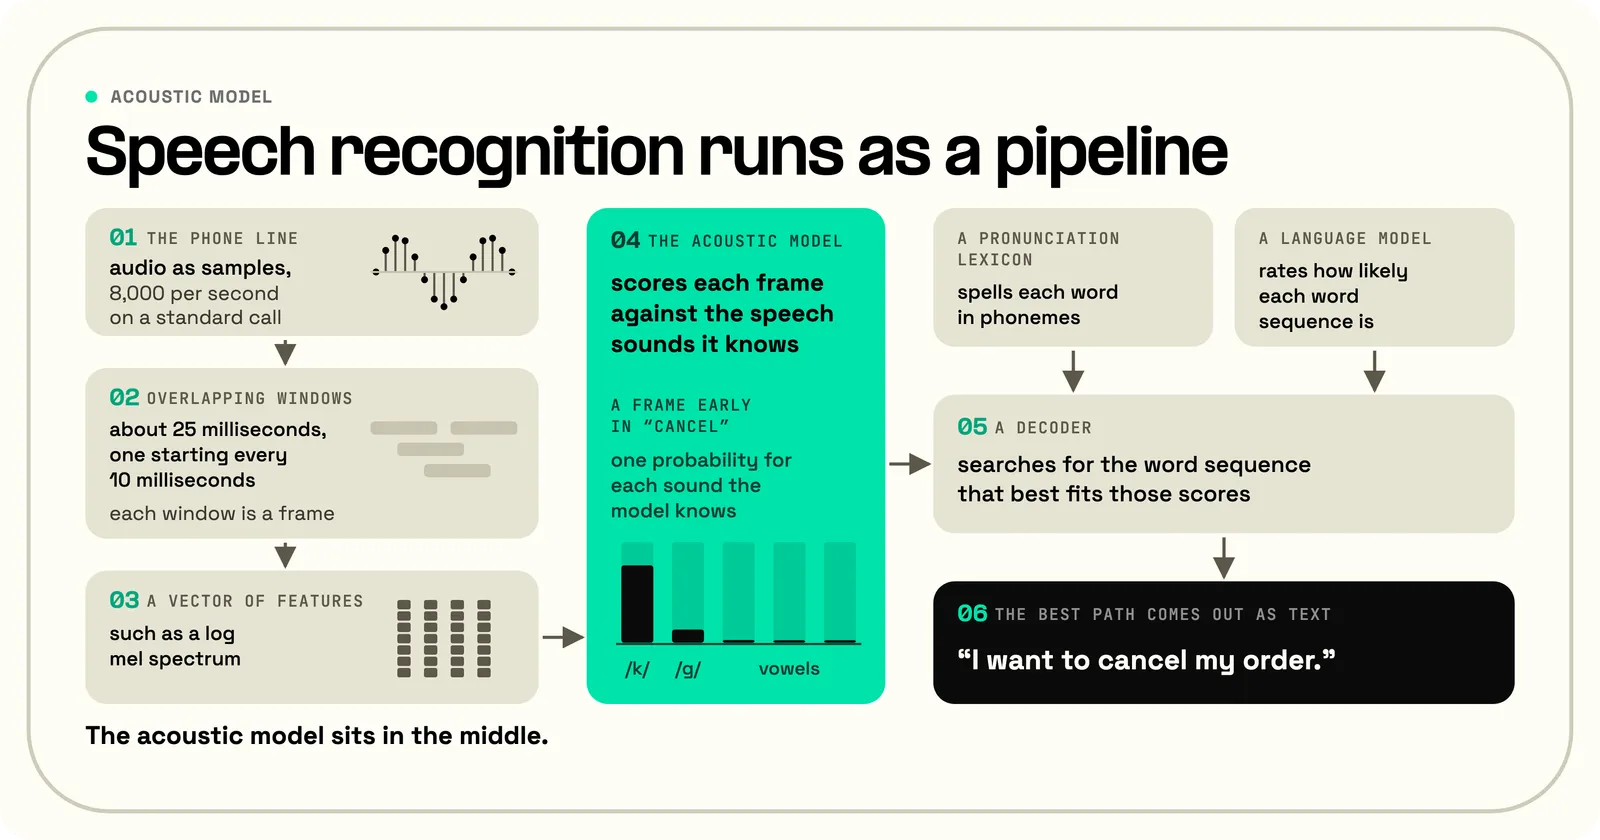
Speech recognition runs as a pipeline, and the acoustic model sits in the middle. For the caller on the phone line, a classic recognizer works like this:
- The phone line delivers audio as samples, 8,000 per second on a standard call.
- The audio is cut into overlapping windows of about 25 milliseconds, one starting every 10 milliseconds. Each window is a frame.
- Each frame becomes a vector of features, such as a log mel spectrum, which describes how much energy the sound has in each frequency band, or mel-frequency cepstral coefficients (MFCCs), a compressed summary of that spectrum.
- The acoustic model scores each frame against the speech sounds it knows.
- A decoder searches for the word sequence that best fits those scores, using a pronunciation lexicon that spells each word in phonemes and a language model that rates how likely each word sequence is.
- The best path comes out as text: "I want to cancel my order."
Inside step 4, a modern acoustic model is a neural network. A hybrid network reads one frame plus a few on either side and outputs a probability for each sound it knows.
Newer encoders read far more context. Whisper's encoder takes in 30 seconds of audio at once.
Types of acoustic models
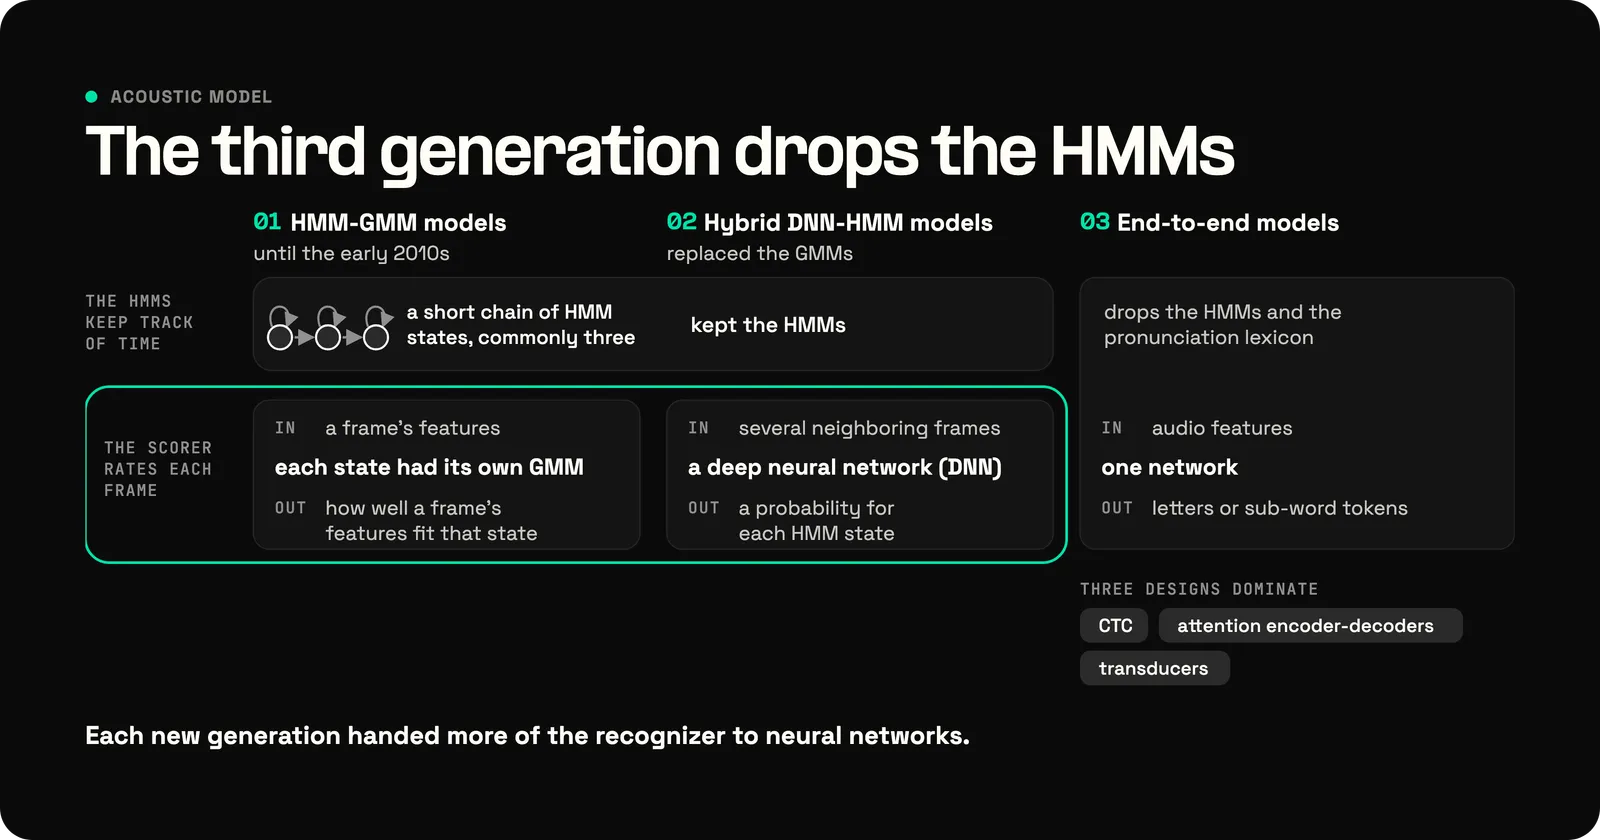
Acoustic models have gone through three generations, and each new one handed more of the recognizer to neural networks.
In the first two, the acoustic model is a set of hidden Markov models (HMMs) plus a scorer. The HMMs keep track of time, and the scorer rates each frame.
HMM-GMM models
Until the early 2010s, most acoustic models paired HMMs with Gaussian mixture models (GMMs).
Each phoneme was modeled as a short chain of HMM states, commonly three, passed through left to right. A state can repeat for as many frames as the sound lasts, so one model fits fast and slow speech.
Each state had its own GMM, which rated how well a frame's features fit that state.
In Hinton and colleagues' words, the HMMs dealt with "the temporal variability of speech" and the GMMs determined "how well each state of each HMM fits a frame".
Large systems used "triphone" HMMs, which model each phoneme with the phonemes on either side, so the /k/ in "cat" and the /k/ in "cool" get separate states.
Mohri, Pereira and Riley describe one such system for a 40,000-word task. Its acoustic model had 7,208 HMM states, each scored by a mixture of up to twelve Gaussians.
Beside it sat a 40,000-word pronunciation dictionary and a trigram language model, which predicts each word from the two before it.
Hybrid DNN-HMM models
The second generation kept the HMMs and replaced the GMMs with a deep neural network (DNN). The network reads several neighboring frames and outputs a probability for each HMM state.
Hinton and colleagues report that on a benchmark of recorded telephone conversations, swapping the GMMs for a DNN cut the word error rate from 27.4% to 18.5%.
End-to-end models
The third generation drops the HMMs and the pronunciation lexicon. One network maps audio features straight to letters or sub-word tokens. Three designs dominate:
- Connectionist temporal classification (CTC), from Graves and colleagues, outputs a label or a "blank" for every frame. Repeats and blanks are then removed, so the run "c, c, blank, a, blank, n" reads "can".
- Attention encoder-decoders, such as Listen, Attend and Spell and Whisper, learn "all the components of a speech recognizer jointly". Their decoder acts as a language model that hears the audio.
- Transducers, introduced by Graves, pair a CTC-style acoustic encoder with a separate predictor network that models the text produced so far.
In these models, "acoustic model" usually means the encoder: the part that turns audio into representations of speech sounds.
In attention models, "decoder" means the network's second half, not the word search of step 5. A CTC model has no second half, so a search turns its frame outputs into text.
How acoustic models are trained
Acoustic models learn from transcribed audio: recordings paired with the words spoken in them.
A transcript gives words, not a label for each frame. Hybrid systems get frame labels from an older model: Hinton and colleagues used a GMM-HMM system to produce a "forced alignment" that assigns each frame an HMM state.
CTC skips that step. It scores the network on the whole transcript, summed over every way the transcript could line up with the frames.
Transcripts are expensive, so modern models also learn from audio alone. wav2vec 2.0 hides stretches of its internal version of the audio and learns to pick the true hidden piece out of decoys.
The model then fine-tunes on a small transcribed set with CTC.
With 53,000 hours of untranscribed audio and ten minutes of transcribed speech, it reached word error rates of 4.8% and 8.2% on the clean and harder test sets of a standard audiobook benchmark.
With all 960 transcribed hours of that benchmark, it reached 1.8% and 3.3%. All four figures use a separate language model in the search.
Whisper took the opposite route: 680,000 hours of audio paired with transcripts from the internet.
SpecAugment stretches the data further by distorting the training features: warping them in time and masking blocks of frequency channels and time steps.
Its authors chose those distortions so the model holds up when timing shifts, frequency bands drop out or short stretches of speech go missing.
Coverage matters as much as volume. Speech in a regional or ethnic dialect, or by children, "can be quite difficult to recognize if the system is only trained on speakers of standard dialects", Jurafsky and Martin note.
A model meant for rural callers needs recordings of rural callers.
How acoustic models are evaluated
An acoustic model is judged by the word error rate (WER) of the recognizer it sits in. The recognizer's output is aligned with a correct transcript, and every substituted, deleted or inserted word counts as an error:
WER = 100 × (substitutions + deletions + insertions) ÷ words in the correct transcript
If the caller says "I want to cancel my order" and the recognizer writes "I want to council my order", that is one substitution in six words, a WER of about 16.7%.
For languages written without spaces, such as Mandarin, character error rate (CER) is used instead.
Research on acoustic models alone sometimes reports phone error rate, which counts wrong sounds, not wrong words, as Hinton and colleagues did on the TIMIT benchmark.
WER only means something for a given kind of audio. Jurafsky and Martin list 5.8% for recorded phone calls between strangers and 25.5% for dinner parties recorded with distant microphones.
So a fair comparison of two acoustic models holds the rest of the recognizer fixed and runs both on the same audio, ideally recordings like the ones they will hear in production.
Acoustic models in text-to-speech
In text-to-speech, the acoustic model runs the other way, from text to sound. It still deals in acoustic features: it predicts a mel spectrogram, the frame-by-frame energy features of step 3 laid out over time.
A second network, the vocoder, turns that spectrogram into the waveform a listener hears.
Tacotron 2 predicts the spectrogram from characters, one frame at a time.
FastSpeech predicts all the frames at once. Its authors report that this made spectrogram generation 270 times faster than a frame-by-frame Transformer model.
The split between acoustic model and vocoder, and the newer designs that merge them, are covered in neural text-to-speech and in Telnyx's guide to TTS model architectures.
Challenges for acoustic models
Acoustic models fail most often on audio unlike their training data.
Noise and distance top the list. Speech recorded far from the microphone, with other people talking, is the hardest case in Jurafsky and Martin's benchmarks. Cleaning the audio first is the job of speech enhancement.
Conversation is harder than reading. People hesitate, restart and talk over each other.
Accents and dialects raise error rates when the training data lacks them, and so do languages with little training data. Multilingual models run into this directly.
In Whisper, a language's error rate closely tracked its hours of training data, and only 117,000 of its 680,000 hours cover its 96 languages other than English.
Rare words such as product names or surnames may barely appear in training at all.
Phone audio adds its own limit. A standard call is sampled 8,000 times a second, which keeps frequencies only up to about 4 kHz. A model trained on wideband audio hears less of each sound on a phone line.
Acoustic model vs language model
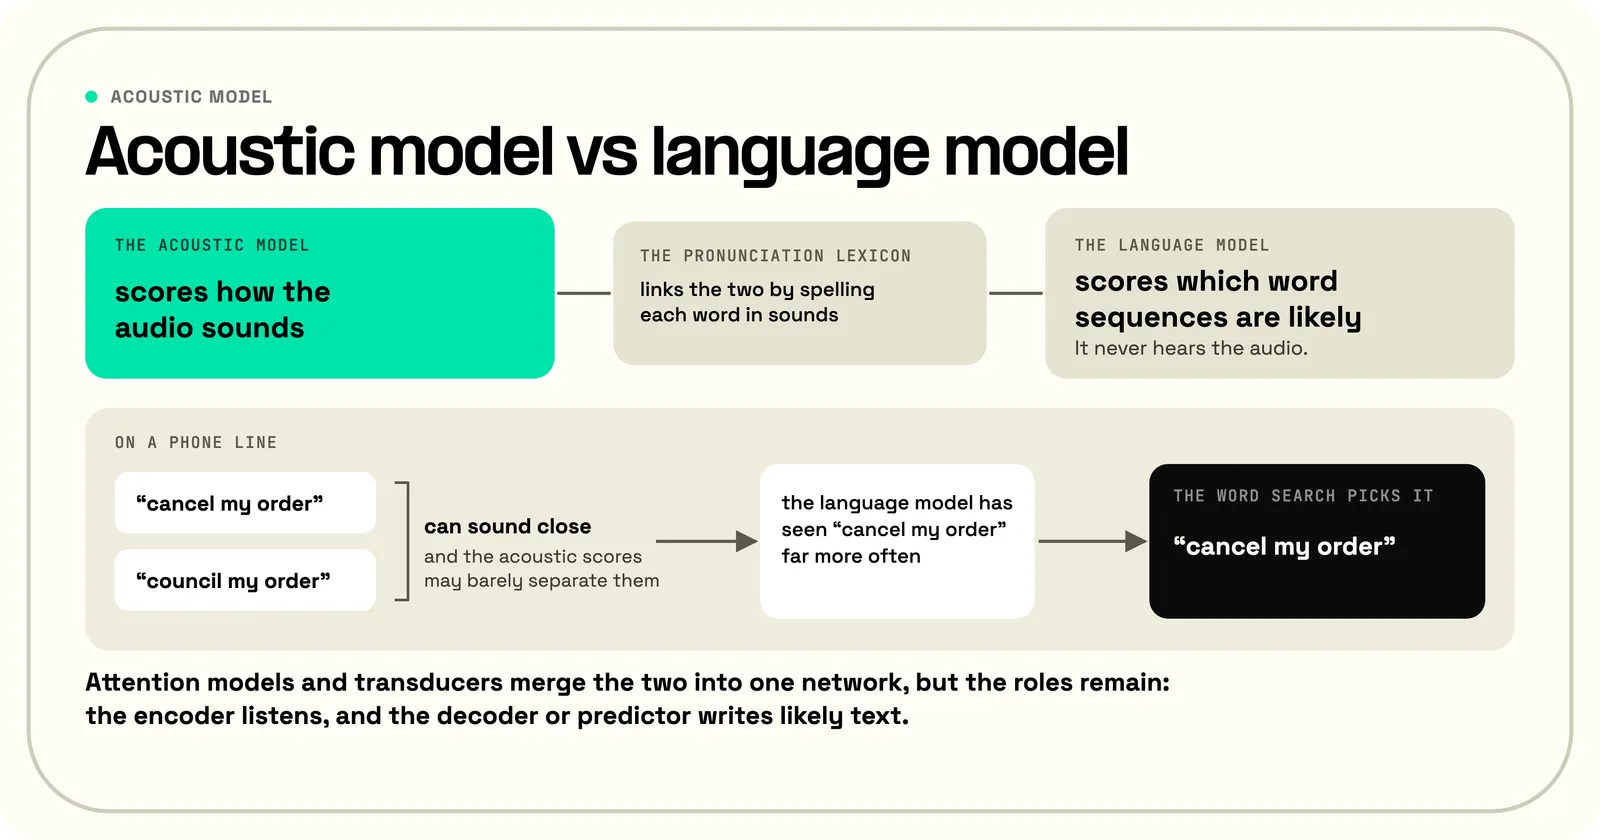
The acoustic model scores how the audio sounds. The language model scores which word sequences are likely. The pronunciation lexicon links the two by spelling each word in sounds.
On a phone line, "cancel my order" and "council my order" can sound close, and the acoustic scores may barely separate them. The language model has seen "cancel my order" far more often, so the word search picks it.
Attention models and transducers merge the two into one network, but the roles remain: the encoder listens, and the decoder or predictor writes likely text.
A CTC model has only the listening half, so it usually borrows a separate language model during the search, and that model can carry much of the accuracy.
Fine-tuned on ten minutes of transcribed speech, wav2vec 2.0 had a 4.8% word error rate on clean audiobooks with a language model in the search, and 40.2% without one.
A speech recognizer's language model is not the same as a large language model that writes answers. It never hears the audio. It only rates how likely each word sequence is.
Acoustic models in voice AI agents
On a phone call, the acoustic model hears narrowband, often noisy audio in real time, so the speech-to-text engine has to suit the line.
The Telnyx Speech-to-Text API lets each stream choose its engine and model, which in effect chooses the acoustic model. One engine is Telnyx's own, which runs a Whisper model on Telnyx's network.
The audio format sets what the acoustic model hears. The streaming endpoint accepts telephone audio directly: its audio formats include G.711 µ-law, which defaults to 8,000 Hz, the format of a standard call in North America.
On one engine, keyword boosting works at the level of words. It raises the recognizer's chances of hearing specific terms, such as product names.
The remaining settings control timing rather than sound scoring. Interim results return partial transcripts while the caller is still speaking.
On one model, end-of-turn detection signals when the caller has finished.
Endpointing sets how long the engine waits in silence before finalizing an utterance, 100 milliseconds by default. Lower values respond faster but can split a sentence at a pause.
Teams that build their own pipeline on the Voice API can bridge call audio into the same streaming endpoint and pick the engine that scores best on their own recordings.
Frequently asked questions
Is ASR considered AI?
Yes. Automatic speech recognition (ASR) is a machine learning task, and modern recognizers are neural networks trained on large amounts of speech. The acoustic model is one of the learned parts.
Which model is used for speech recognition?
Most current systems use end-to-end neural models: attention encoder-decoders such as Whisper, CTC models on self-supervised encoders such as wav2vec 2.0, and transducers. Older systems used HMMs.
What are the best speech recognition models?
The best model is the one with the lowest word error rate on the audio it will hear. Rankings shift with accents, noise and the line, so candidates are best compared on real recordings, as Telnyx's speech-to-text engine guide describes.
What is a good word error rate?
It depends on the audio. On clean read audiobooks, strong systems score about 1.4%; on recorded phone calls between strangers, about 5.8%; on distant-microphone dinner parties, about 25.5%.
What does acoustic modeling in speech recognition focus on?
It focuses on mapping audio features to speech sounds across different voices, accents, microphones and noise. Choosing between words that sound alike is mostly left to the language model.
Sources
- Jurafsky, D., and Martin, J. H. (2026). Speech and Language Processing, chapter 16, "Automatic Speech Recognition" (draft of August 19, 2026).
- Mohri, M., Pereira, F., and Riley, M. (2002). Weighted finite-state transducers in speech recognition. Computer Speech and Language, 16(1).
- Hinton, G., et al. (2012). Deep neural networks for acoustic modeling in speech recognition. IEEE Signal Processing Magazine, 29(6).
- Graves, A., Fernández, S., Gomez, F., and Schmidhuber, J. (2006). Connectionist temporal classification. ICML 2006.
- Graves, A. (2012). Sequence transduction with recurrent neural networks.
- Chan, W., Jaitly, N., Le, Q. V., and Vinyals, O. (2016). Listen, attend and spell. ICASSP 2016.
- Baevski, A., Zhou, H., Mohamed, A., and Auli, M. (2020). wav2vec 2.0: a framework for self-supervised learning of speech representations. NeurIPS 2020.
- Radford, A., et al. (2022). Robust speech recognition via large-scale weak supervision.
- Park, D. S., et al. (2019). SpecAugment: a simple data augmentation method for automatic speech recognition. Interspeech 2019.
- Shen, J., et al. (2018). Natural TTS synthesis by conditioning WaveNet on mel spectrogram predictions. ICASSP 2018.
- Ren, Y., et al. (2019). FastSpeech: fast, robust and controllable text to speech. NeurIPS 2019.
- Telnyx. Engines and models, Audio formats, Keyword boosting, Interim results and Endpointing. Telnyx developer documentation.
Share on Social
Jump to:
What is an acoustic model?How an acoustic model worksTypes of acoustic modelsHow acoustic models are trainedHow acoustic models are evaluatedAcoustic models in text-to-speechChallenges for acoustic modelsAcoustic model vs language modelAcoustic models in voice AI agentsFrequently asked questionsSourcesSign up for emails of our latest articles and news
This content was generated with the assistance of AI. Our AI prompt chain workflow is carefully grounded and preferences .gov and .edu citations when available. All content is reviewed by a Telnyx employee to ensure accuracy, relevance, and a high standard of quality.


