An activation function adds the non-linearity a neural network needs to learn complex patterns. Sigmoid, tanh, ReLU and softmax, plus how to choose one.
Updated September 2026
An activation function is what lets a neural network learn anything more complex than a straight line. At each layer, it adds the non-linearity that makes network depth useful: without it, a hundred stacked layers collapse into the behavior of one. That non-linearity is what lets a network model the curves, decision boundaries, and messy relationships in real data.
Quick answer: An activation function is the function a neuron applies to its weighted sum of inputs to produce its output, and it adds the non-linearity a neural network needs to learn complex patterns. Common activation functions include the sigmoid, tanh, ReLU, and softmax. The choice matters because each shapes a neuron's output differently, which affects how well and how fast a network learns.
An activation function determines a neuron's output. The neuron computes a weighted sum of its inputs, and the activation function maps that sum to the value passed to the next layer. That step is where a network's non-linearity comes from, and older texts call it a transfer function.
The term neuron activation refers to the same idea from the neuron's side. A neuron's activation is its output value after the activation function runs, and a layer's activations are the vector of those outputs, the signal the next layer receives. The name echoes how a biological neuron fires once its input crosses a threshold, but the analogy is loose: the function is a chosen piece of math, not biology.
Neural networks need activation functions to introduce non-linearity. Each layer on its own performs a linear operation, multiplying its inputs by weights and adding a bias, and stacking linear operations only produces another linear operation. That is why a network without activation functions has no more expressive power than a single layer, however deep it runs. Adding a non-linear function between the layers restores that power, letting the network fit relationships a linear model cannot represent.
The XOR problem is the classic demonstration, worked through in Goodfellow and colleagues. Its four data points cannot be split by any single straight line, so a linear model fails on them no matter how it is trained. Add one hidden layer of two neurons with a non-linear activation and the network separates them. That gap, between what a line can carve and what a curve can, is the core reason activation functions exist.
The activation function also shapes how a training signal travels backward through the network. The sigmoid's derivative never exceeds 0.25, and backpropagation multiplies one derivative per layer, so the gradient reaching the earliest layers shrinks geometrically with depth. This is the vanishing gradient problem, and saturation at large inputs makes it worse. It is the main reason ReLU replaced the sigmoid as the default hidden-layer activation in most feedforward and convolutional networks.
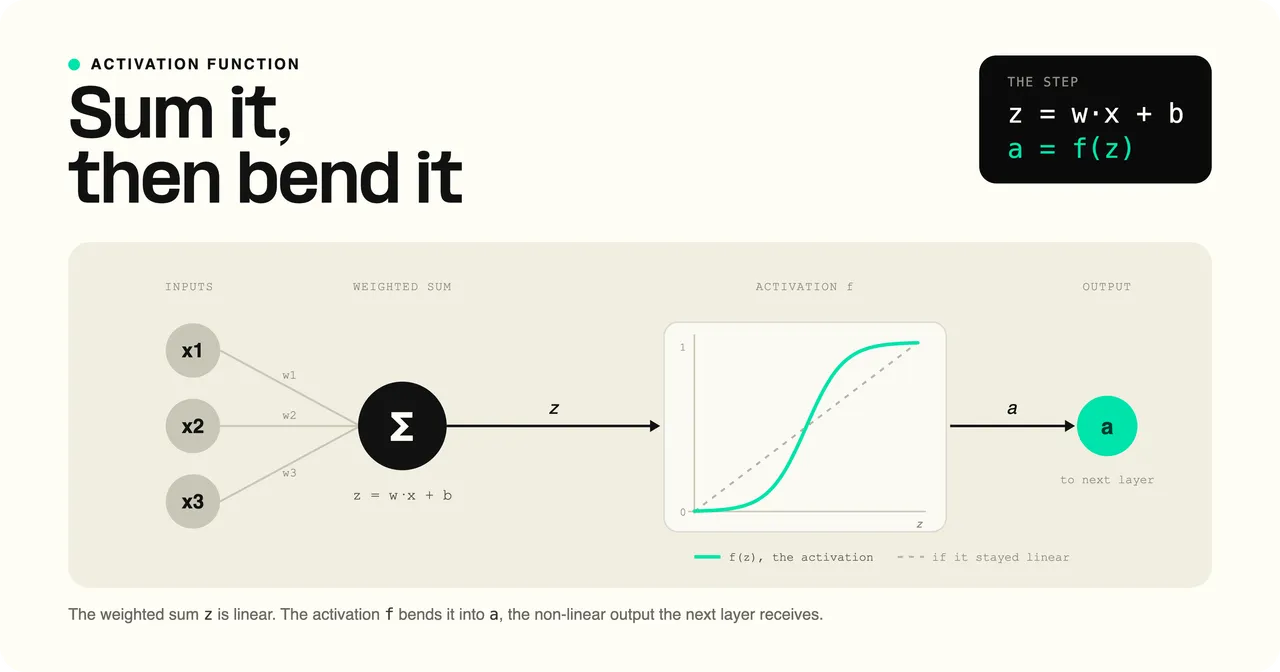
The activation functions you will meet most often are the sigmoid, tanh, ReLU, and softmax, along with the binary step that started the field. Sigmoid, tanh, and ReLU act on one neuron's input at a time, while softmax acts on a whole output layer's set of scores.
The sigmoid function, written σ(x) = 1 / (1 + e^-x), squashes any input into the range 0 to 1 along a smooth S-shaped curve. That bounded output reads naturally as a probability, which is why the sigmoid is the standard choice for the output neuron of a binary classifier. Its weakness is saturation: for large positive or negative inputs the curve flattens, the gradient approaches zero, and learning slows.
The tanh function, (e^x - e^-x) / (e^x + e^-x), has the same S-shape but maps inputs into the range -1 to 1. Because its output is centered on zero rather than 0.5, it often trains faster than the sigmoid in hidden layers, though it saturates at the extremes for the same reason.
The binary step function outputs 1 if the input clears a threshold and 0 otherwise, the rule behind the original perceptron. It matches the idea of a neuron firing or staying silent, but its gradient is zero everywhere, so it cannot be trained with gradient descent and is rarely used today.
The rectified linear unit, or ReLU, returns max(0, x): the input if it is positive and 0 otherwise. It is the default for hidden layers in most feedforward and convolutional networks, while transformer blocks usually use GELU or SwiGLU. Its variants, including leaky ReLU, GELU, and SiLU, address the cases where plain ReLU falls short, and the dedicated ReLU explainer covers them.
Softmax is the multi-class counterpart to the sigmoid. It converts a layer's raw scores into probabilities that sum to 1 using e^zi / Σ e^zj, which is what a classifier needs when an input belongs to exactly one of several classes.
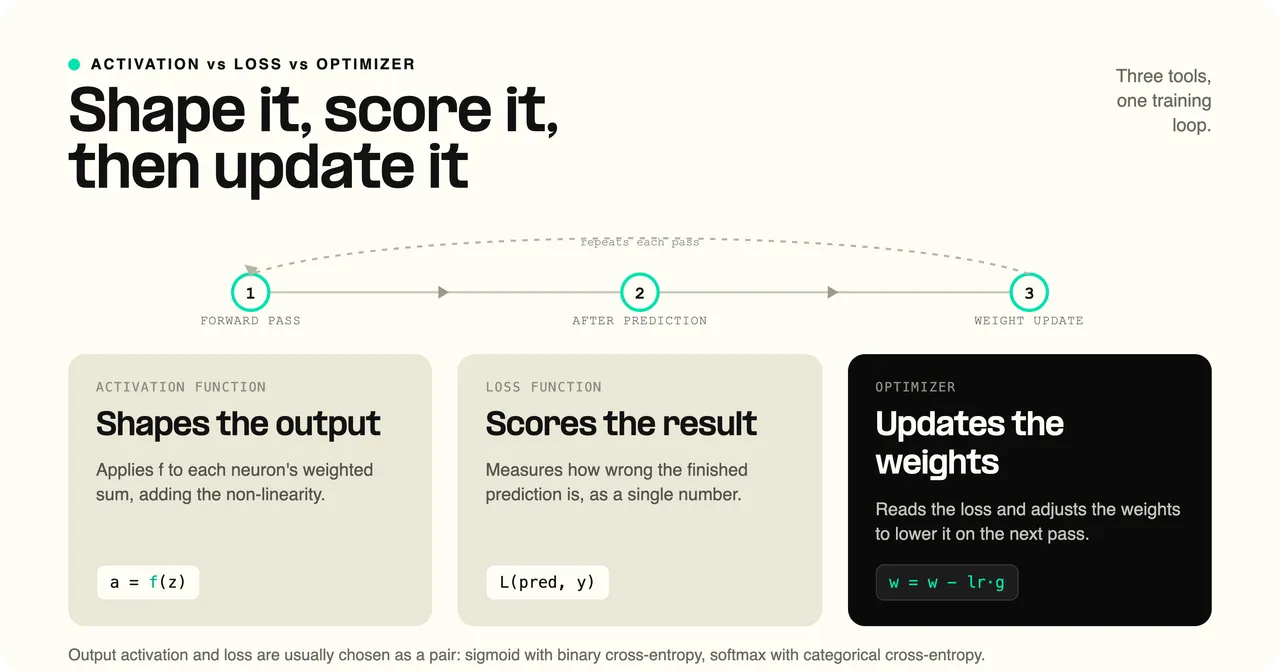
An activation function shapes each neuron's output inside the network during the forward pass, while a loss function scores the network's finished prediction against the correct answer afterward. They answer different questions, which is why a network uses both. The loss produces a single number measuring how wrong the prediction was, and that number is what training works to reduce.
A third tool, the optimizer, reads the loss and adjusts the network's weights to reduce it on the next pass. So the activation shapes the signal, the loss scores the result, and the optimizer changes the weights. The output activation and the loss are usually chosen as a pair: a sigmoid output goes with binary cross-entropy, softmax with categorical cross-entropy, and a linear output with mean squared error.
Choosing an activation function comes down to where the neuron sits in the network. For hidden layers, ReLU is the default and the right starting point for most feedforward and convolutional networks. Switch to leaky ReLU or GELU when you see dead neurons or need smoother gradients, as transformer blocks do.
For the output layer, the task decides. Use the sigmoid for binary classification, where the output is a single probability. Use softmax for multi-class classification, where the output is one probability per class. Use no activation, a plain linear output, for regression, where the network predicts an unbounded number. Tanh still appears inside recurrent networks such as LSTMs, where it regulates the cell state, though ReLU dominates feedforward hidden layers.
The practical rule: start with ReLU in the hidden layers and match the output activation to the task, then change it only if training gives you a reason to.
An activation function introduces non-linearity, which lets a neural network learn relationships that a straight line cannot capture. It maps each neuron's weighted input to an output, and that step is what lets stacked layers model complex patterns.
There is no fixed number, but a handful cover most real use. The core set is the sigmoid, tanh, binary step, ReLU, and softmax, along with ReLU variants such as leaky ReLU, GELU, and SiLU. New functions appear regularly in research, though most networks rely on a small, well-understood group.
No, activation functions and loss functions are not the same. An activation function shapes each neuron's output during the forward pass, and a loss function scores the final prediction to drive training. One runs at every neuron; the other runs once, at the end.
Use the sigmoid function for the output neuron of a binary classifier, where you need a single value between 0 and 1 to read as a probability. Avoid it in the hidden layers of deep networks, because it saturates for large inputs and its gradients vanish, which slows learning. ReLU is the usual hidden-layer choice instead.
Most modern large language models use ReLU variants rather than the classic sigmoid or tanh. GPT-2 and GPT-3 use GELU, while Llama and PaLM use SwiGLU, a gated variant that Shazeer reports lowers Transformer perplexity without offering a mechanism. Softmax also runs inside every attention layer, normalizing the attention weights.
A linear activation function passes the neuron's input through unchanged, so its output equals its input. It adds no non-linearity, which is why a network built only from linear activations collapses into a single linear layer. Its one common use is the output layer of a regression model, where the prediction is an unbounded number.
This content was generated with the assistance of AI. Our AI prompt chain workflow is carefully grounded and preferences .gov and .edu citations when available. All content is reviewed by a Telnyx employee to ensure accuracy, relevance, and a high standard of quality.