AI guardrails are run-time checks on what goes into and comes out of an AI model. How they work, the main types, examples, and guardrails for AI agents.

Updated October 2026
AI guardrails are checks that run around an AI model while it is in use. They inspect what goes into the model, such as the prompt and retrieved text, and what comes out, such as the response or a tool call. Anything that breaks the developer's policy is flagged, blocked, rewritten or escalated to a person. LLM guardrails are the same checks applied to applications built on large language models.
Large language models arrive with safety training built in, yet Zou and colleagues found that an automatically generated string of text, added to the end of a harmful request, got three public chatbots past that training.
Guardrails put the final decision about what reaches a user, a database or a phone line in the application, where the developer controls it.
This content was generated with the assistance of AI. Our AI prompt chain workflow is carefully grounded and preferences .gov and .edu citations when available. All content is reviewed by a Telnyx employee to ensure accuracy, relevance, and a high standard of quality.
An AI guardrail is a rule enforced outside the model. It has three parts: a written policy, a detector that checks each request or response against it, and an outcome, such as a block, when the detector fires.
The model cannot switch a guardrail off, because the guardrail is not part of the model. The same guardrail works with any underlying large language model.
Safety training sits inside the model: methods such as Constitutional AI change its weights so it declines harmful requests and explains why.
Prompt instructions differ from both: a system prompt asks the model to behave, while a guardrail checks whether it did.
The term also has a policy sense: in law and corporate governance, "AI guardrails" and "ethical guardrails" mean the rules for how AI may be built and used, not checks that software runs on each request.
AI systems need guardrails because a model's training does not reliably stop it from being manipulated, leaking data, stating false facts or taking unsafe actions.
The OWASP Top 10 for large language model applications, a ranking of the most serious security risks, puts prompt injection first and sensitive information disclosure second for 2025.
Prompt injection is input that changes the model's behavior in ways the developer did not intend.
A model can also fail with no attacker involved, by producing a hallucination: a fluent answer that is false. The US National Institute of Standards and Technology lists it, as confabulation, among 12 risks in its Generative AI Profile.
Safe AI responses come from a check matched to each risk: input checks against injection and data leakage, output checks against harmful or unsupported answers, and action checks on what an agent may do.
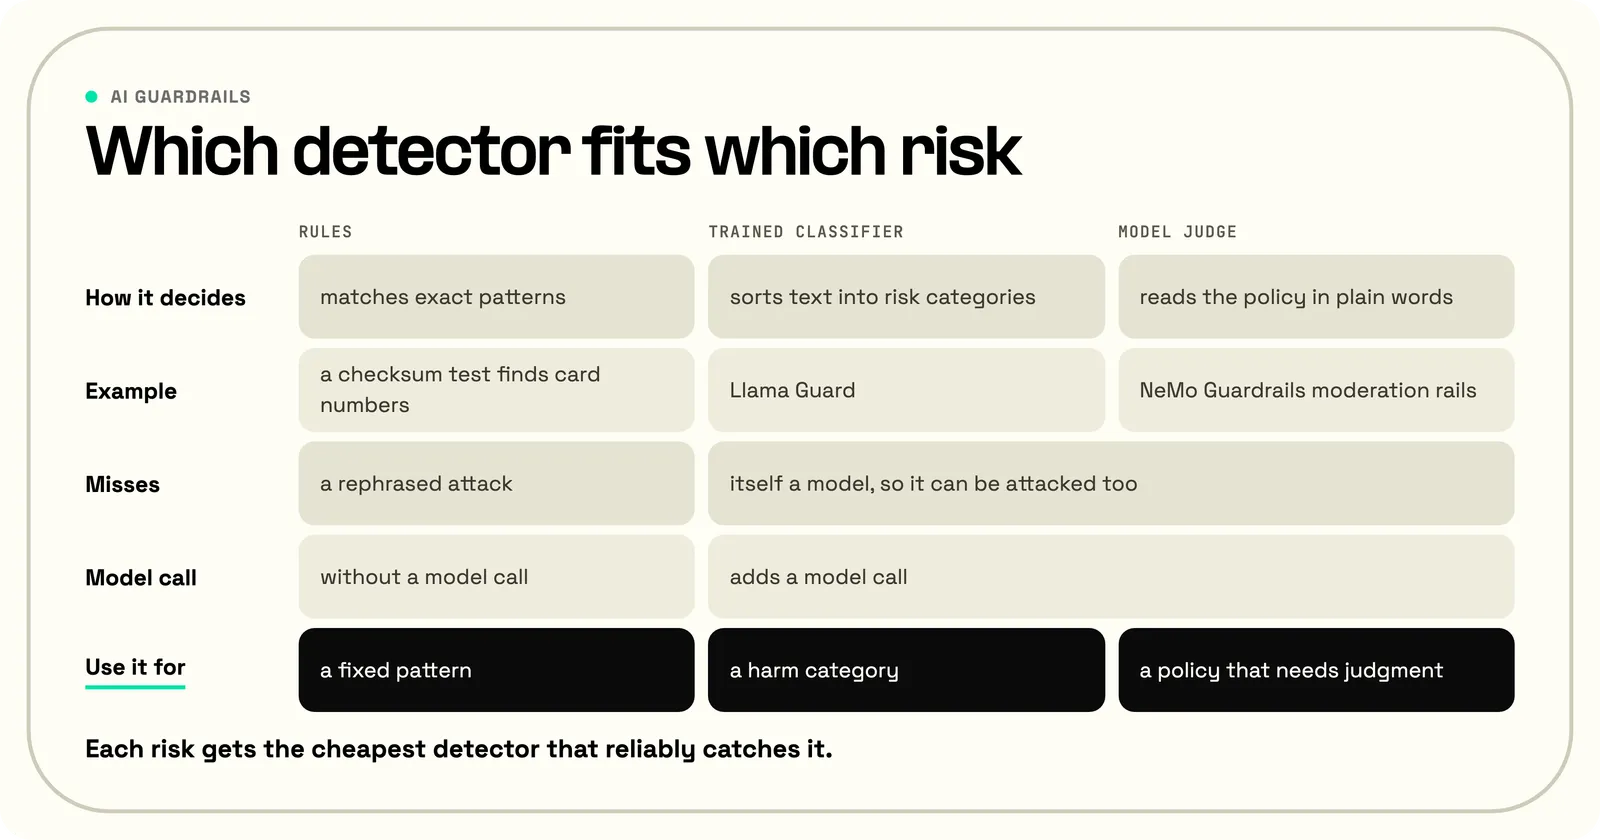
AI guardrails work by running a detector at fixed checkpoints in an AI application and acting on what it finds. An input check runs before the model, an output check runs after it, and in an agent an action check runs before any tool executes.
Each detector looks for a policy violation and returns one of five outcomes:
In a support chat, a customer pastes a card number into a refund question. A rule in the application's code masks the number before the model sees it: a rewrite.
The output check then confirms the answer promises nothing the refund policy forbids: an allow.
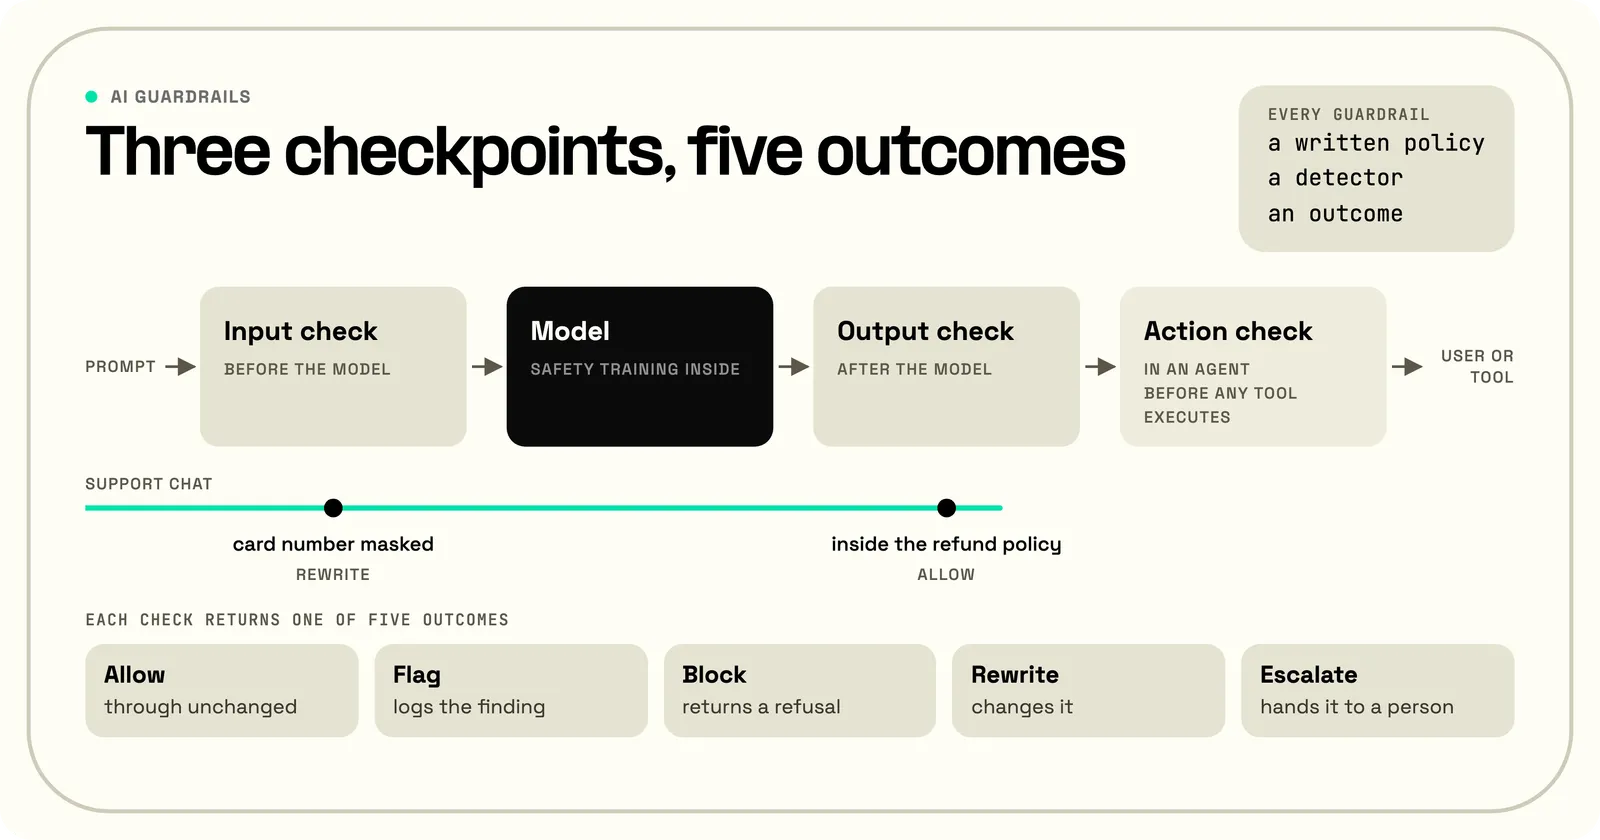
Behind each check is a detector of one of three kinds: rules, trained classifiers or model judges. Rules match exact patterns without a model call, such as a checksum test that finds card numbers or a list of banned phrases.
Trained classifiers sort text into risk categories. Llama Guard, for example, is a language model fine-tuned to label both prompts and responses against a safety taxonomy.
A model judge is a second language model given the policy in plain words and asked whether a prompt or response breaks it. It handles nuanced policies that no pattern or fixed category describes.
The moderation rails in NeMo Guardrails work this way: a separate model vets each user message before the main model sees it, and each response before the user does.
The four main types of AI guardrails are named for what they inspect: input, output, retrieval and action guardrails.
Input guardrails check what users and other systems send to the model. They catch jailbreak attempts and prompt injections, keep secrets and personal data from reaching the model provider, and turn away off-topic requests.
Output guardrails check what the model produces before anyone sees it. Content filters block hate speech and other harmful categories; other checks catch leaked personal data, broken formats and claims the business may not make.
Retrieval guardrails check the documents a model reads, in systems that ground answers in retrieved text.
Before the model runs, one check screens retrieved passages for hidden instructions. Afterwards, another tests whether the answer follows from them.
Action guardrails sit between an agent and its tools. They decide whether a proposed tool call is allowed, whether its arguments are valid, and whether a person must approve it first.
Other taxonomies sort the same checks by owner (data, model, application, infrastructure) or by purpose (security, privacy, safety, accuracy, compliance).
A common example of an AI guardrail is a refund limit on a support agent. The agent issues refunds up to a set amount on its own, and anything larger waits for a person to approve it.
Three other common guardrails, with the trigger and the outcome for each:
Guardrails for AI agents check actions as well as words, because an agent's output can call a tool that moves money, changes a record or ends a phone call.
OWASP calls the failure excessive agency and traces it to three causes: tools the agent does not need, permissions broader than the task, and high-impact actions taken without approval.
Two action guardrails answer those causes directly, and two more catch bad inputs and runaway loops:
On a phone call, an agent's tools act on the call itself. An agent built on a programmable Voice API can transfer, hang up or send keypad tones, so each of those tools needs its own permission check.
Agents also read content they did not write, which opens a second path for attacks. Greshake and colleagues showed that instructions planted in a web page or document can redirect an assistant that retrieves it.
The working rule is that retrieved content is data, never instructions. OWASP's prompt injection mitigations put it into practice: the application labels retrieved text as untrusted, keeps it apart from its own instructions and filters it.
AI guardrails can be bypassed. OWASP's own guidance says it is unclear whether any method fully prevents prompt injection.
A rephrased jailbreak, a new language or an encoding the detector has not seen can slip past it. The adversarial suffixes that Zou and colleagues generated even worked on models they were never trained against.
A classifier or model judge is itself a model, so it can be attacked too. Mangaokar and colleagues built an adversarial prefix that carried harmful responses past several guard models, even with no access to the guard model itself.
The model's own safety training is no backstop either: Qi and colleagues fine-tuned a commercial model on 10 harmful examples, at a cost of under $0.20, and it then followed nearly any harmful instruction.
The realistic goal is layers: input, output and action checks that fail differently, logs that show what each one caught, and a person on the path for the decisions that matter most.
Implementing AI guardrails starts with a written policy for each risk, then attaches a detector and an outcome to each policy at the stage where that risk enters or leaves the application.
Guardrails run in one of three places: as a library inside the application, as a separate model the team hosts and calls, or in a gateway between the application and its model provider.
A library such as NeMo Guardrails changes with the application's code. A hosted classifier such as Llama Guard adds a model call but keeps the data on the team's own servers.
A gateway such as Telnyx AI Gateway sets one policy on a group of API keys and applies it to every request those keys make.
Because it sees every prompt and response in transit, a gateway suits checks every application needs, such as blocking secrets and card numbers.
Checks that depend on the application's context, such as masking a value or keeping to a topic, sit in the application itself.
Every added check costs latency and compute. A strict one also turns away legitimate requests, which users experience as the product failing.
Guardrails in voice AI agents must finish inside the pause between a caller's question and the agent's reply, because a sentence the agent has spoken cannot be withheld.
A voice agent speaks the model's text as it arrives, so an output check that might block must hold the text until it finishes. The caller hears silence for as long as the check runs.
The guardrails in Telnyx AI Gateway show the trade-off. Buffered mode holds a streamed response until inspection completes, delaying its first words; passthrough mode sends text at once but can only flag findings after the stream ends.
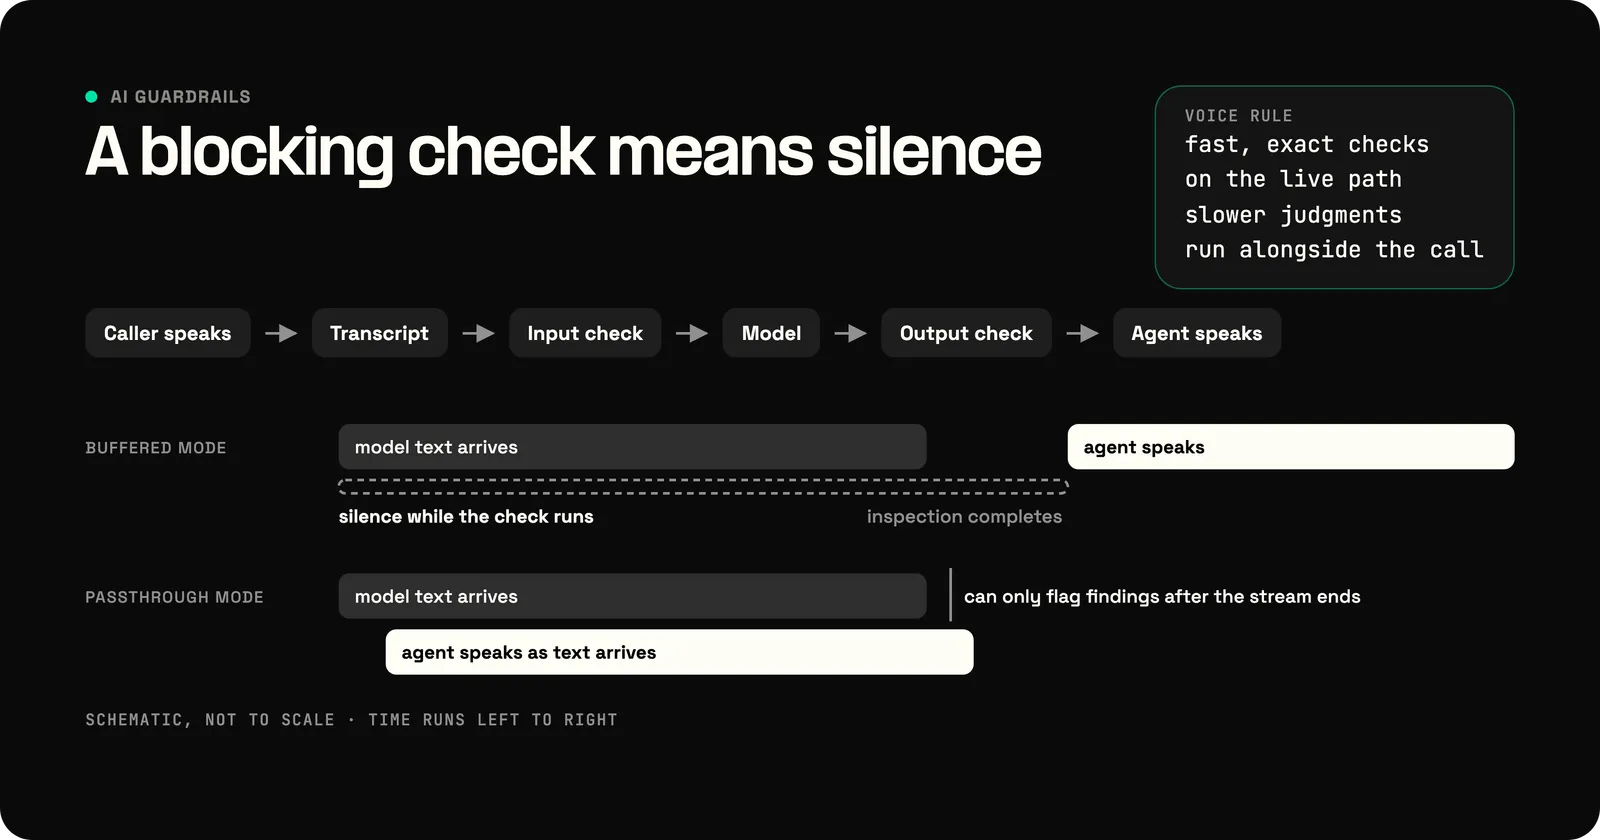
For voice, the working rule is to keep fast, exact checks on the live path. Slower judgments run alongside the call, as flags a person reviews later or as a signal that hands the caller to a human.
Spoken personal data is best stopped at the transcript, before it reaches a model provider. Callers read card numbers aloud, and the transcript carries them to the model.
In Telnyx's AI DLP test, AI Gateway's pattern checks blocked prompts carrying a cloud access key, a card number, an IBAN, a Social Security number, an email address and a phone number before any reached a provider.
The gateway documentation lists the limits of pattern checks. They miss names, addresses and formats outside the supported patterns.
Pattern checks also do not redact text, moderate content with a model, detect prompt injection or inspect audio. The application or a separate model has to cover those.
A required disclosure, such as a notice that the call is recorded, should never depend on the model.
In Telnyx AI Assistants, Conversation Workflows split a call into steps, and a speak node plays a fixed message word for word with no model turn. Each step can also limit the agent's tools.
A handoff to a person covers what the agent cannot resolve on its own. Telnyx's voice AI agents can transfer the call to a human when a rule fires, such as a caller asking for a manager.
Synthetic voice detection is an input check that only voice needs. A synthetic speech detector scores whether a caller's voice is machine-generated, and a high score can send the call to extra identity checks before the agent acts.
Consumer chatbots are trained to refuse harmful requests, and the companies behind them can add guardrails outside the model. Training alone is not enough: jailbreak prompts and generated attack strings have pushed public chatbots past it.
An application built on the same model through an API gets the model's training, not the chatbot's product rules. Its own guardrails, such as which topics it covers and what data it sends, are its developer's job.
A model run with no checks around it has no guardrails. Open-weight models can be run that way by anyone who downloads them.
The model's own safety training is a separate layer, and fine-tuning can wear it down. Qi and colleagues found that even fine-tuning on ordinary, benign data weakened a model's safety training.
Content moderation is one job AI guardrails do, not the whole of it. Moderation classifies text into harm categories such as hate speech or violence.
Guardrails also check for leaked data, prompt injection, unsupported claims and unsafe tool calls, none of which a moderation classifier is built to catch.
Alignment trains a model to behave well, so it changes the model itself. Steering, through prompts, examples and decoding settings, directs the model's output as it is generated; the steerability page covers how far that reaches.
Guardrails check the input and output at run time and enforce the result. A prompt that tells a model to avoid a topic is steering; a check that blocks the answer when it covers the topic anyway is a guardrail.
The best AI guardrails for an application are the ones that match its own risks and hold up on its own traffic. A tool that tops a general benchmark can still miss the attacks that matter to one business.
Four measures compare options fairly: the share of real attack prompts caught, the share of normal requests wrongly blocked, the latency each check adds, and what each check logs for review.