AI hardware is the chips, memory, and interconnects built for machine learning. The main types, why memory limits speed, and the power and cooling challenges.
Updated September 2026
The fastest AI chips spend much of their time waiting on memory rather than computing, especially when they serve large language models. Over the past 20 years, peak server compute grew about 3x every two years while memory bandwidth grew only 1.6x, according to the AI and Memory Wall study. That gap explains why AI hardware design now centers on moving data as much as on raw compute.
Quick answer: AI hardware is the processors, memory, and interconnects built to run machine learning workloads faster and more efficiently than a general-purpose CPU. The main types are GPUs, TPUs and other custom ASICs, NPUs in phones and laptops, and FPGAs. Each trades some flexibility for speed on the matrix math neural networks run, and each is limited by how fast it moves data, not only by how fast it computes.
AI hardware is computer hardware specialized for the arithmetic that machine learning models perform, above all the matrix multiplications inside neural networks. A central processing unit handles a few complex instructions quickly, in sequence. NVIDIA's CUDA programming guide describes the opposite balance in a GPU. More of its transistors go to data processing and fewer to caching and flow control, trading single-thread speed for far greater total throughput.
Neural networks reward that trade because their core operation is the same multiply-and-add, repeated billions of times. A working AI system needs three parts: processors that do the math, memory that holds a model's weights close to those processors, and interconnects that move data between chips. A shortfall in any one caps the other two.
The main types of AI hardware are GPUs, custom ASICs such as TPUs, NPUs, and FPGAs. All four are AI accelerators that take heavy math off the CPU.
| Type | Built for | Typical home | Trade-off |
|---|---|---|---|
| GPU (graphics processing unit) | Parallel math for training and inference | Data centers, workstations | Runs almost any model, but draws a lot of power |
| ASIC, such as a TPU | One workload, such as matrix multiplication | Cloud data centers | Efficient at its task, fixed once manufactured |
| NPU (neural processing unit) | Low-power inference on a device | Phones, laptops, edge devices | Uses little power, but fits smaller models |
| FPGA (field-programmable gate array) | Custom logic, rewired after manufacture | Networking, low-latency systems | Adaptable, but harder to program than a GPU |
| CPU (central processing unit) | Control, data preparation, light inference | Every system | Runs anything, but slowly on large matrix math |
A GPU runs nearly any model, so it handles both training and serving. An ASIC gives up that flexibility to do one job efficiently, and Google's TPU, built around a matrix multiply unit, is one example. An FPGA can be rewired after it ships. That gives a team custom hardware logic without manufacturing a chip, at the cost of harder programming.
Memory limits AI hardware because a processor can only compute as fast as data reaches it, and memory bandwidth has trailed compute for two decades. The effect is sharpest when a large language model generates text. Each new token requires another pass through the model's weights, so at small batch sizes the chip spends more time loading numbers from memory than multiplying them. The AI and Memory Wall authors show how memory bandwidth can become the dominant bottleneck for decoder models, the design GPT-style models use.
High-bandwidth memory (HBM) stacks layers of memory beside the processor on the same package, which shortens the path data travels and raises the bandwidth. When one chip cannot hold a model, interconnects join many: NVIDIA's GB200 NVL72 links 72 GPUs into one NVLink domain that NVIDIA says acts as a single GPU.
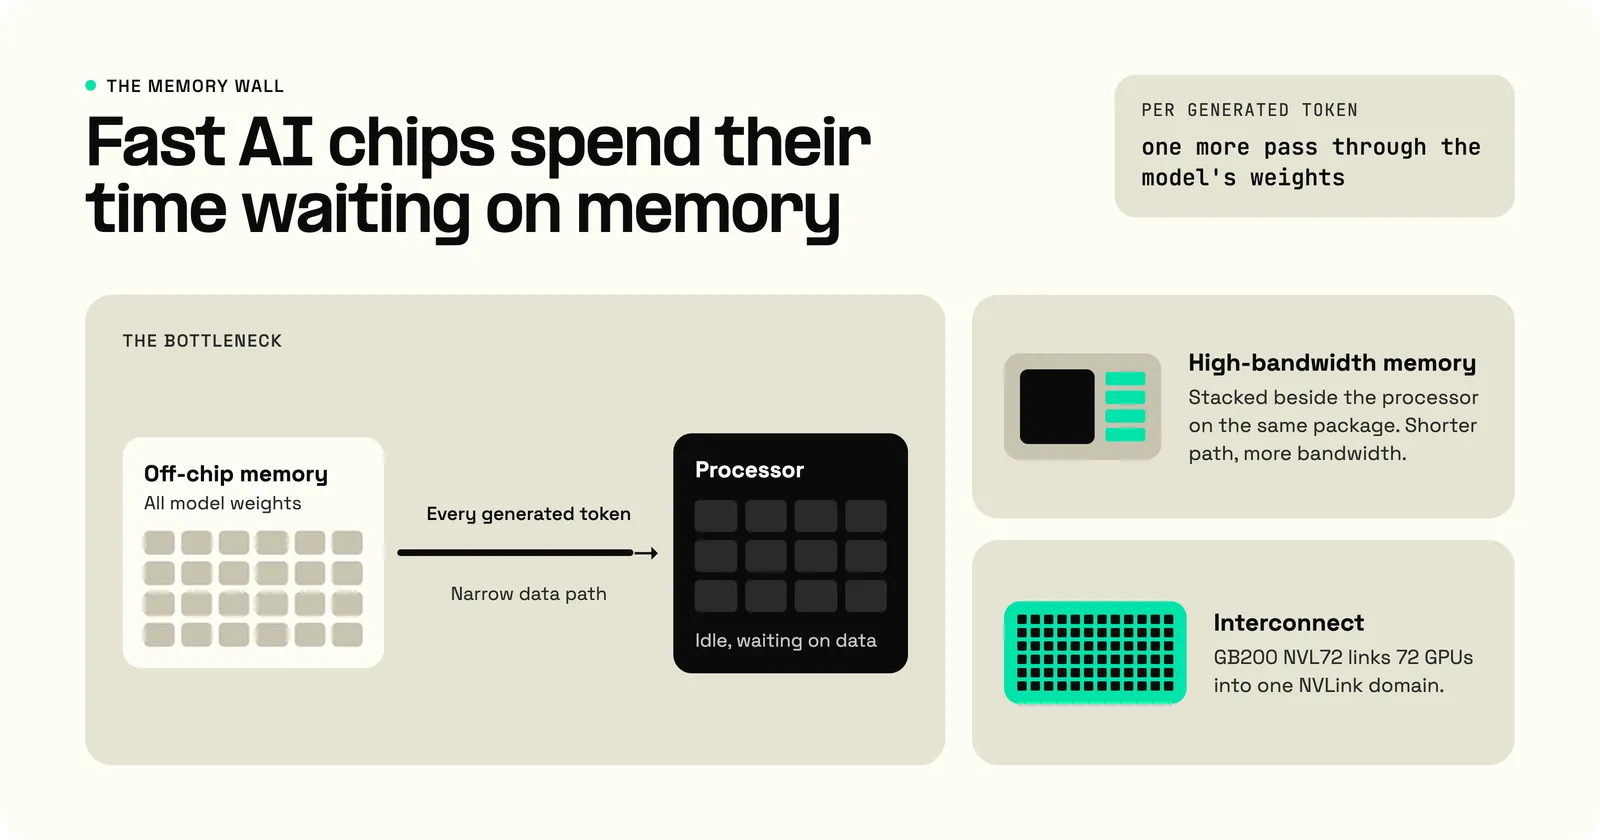
For a memory-bound workload, more compute sits idle.
Training hardware is built for throughput across huge datasets, while inference hardware is built for the latency and cost of each answer. Training runs as long jobs on large clusters that must keep every chip busy, a problem covered under AI scalability. Inference runs each time someone uses the model, so small savings per request add up.
Training and inference also differ in numeric precision. Training needs enough range to capture small gradient updates, so it usually runs in 16-bit or 32-bit formats. The mixed precision training method stores weights, activations, and gradients in 16-bit floating point and keeps a 32-bit master copy of the weights. That cuts memory use by nearly 2x.
Inference can go lower. In an integer quantization study, converting models to 8-bit integers kept accuracy within 1% of the floating-point baseline on every network tested, including BERT-large. Fewer bits per number mean fewer bytes to move. Integer math also runs faster on processors built for it, so quantization improves inference latency and throughput as well as memory use.
AI hardware runs in three places: cloud data centers, edge systems near where data is produced, and consumer devices. Data centers host training and the large models people reach through an app or API. Edge systems, such as a car or a factory camera, run inference locally, so decisions skip the round trip to the cloud.
In consumer devices, AI hardware usually takes the form of an NPU built into a phone or laptop. Many Windows AI features on Microsoft's Copilot+ PCs require an NPU that performs more than 40 trillion operations per second. Microsoft describes the chip as built for tasks such as real-time translation and image generation, run on the device without a round trip to a server.
Placement matters most when a person waits on the answer. Telnyx runs transcription, model inference, and speech synthesis for its voice AI agents on GPU clusters co-located with its telephony network, in the same data centers. A caller's audio reaches the models without leaving that network for a separate AI service.
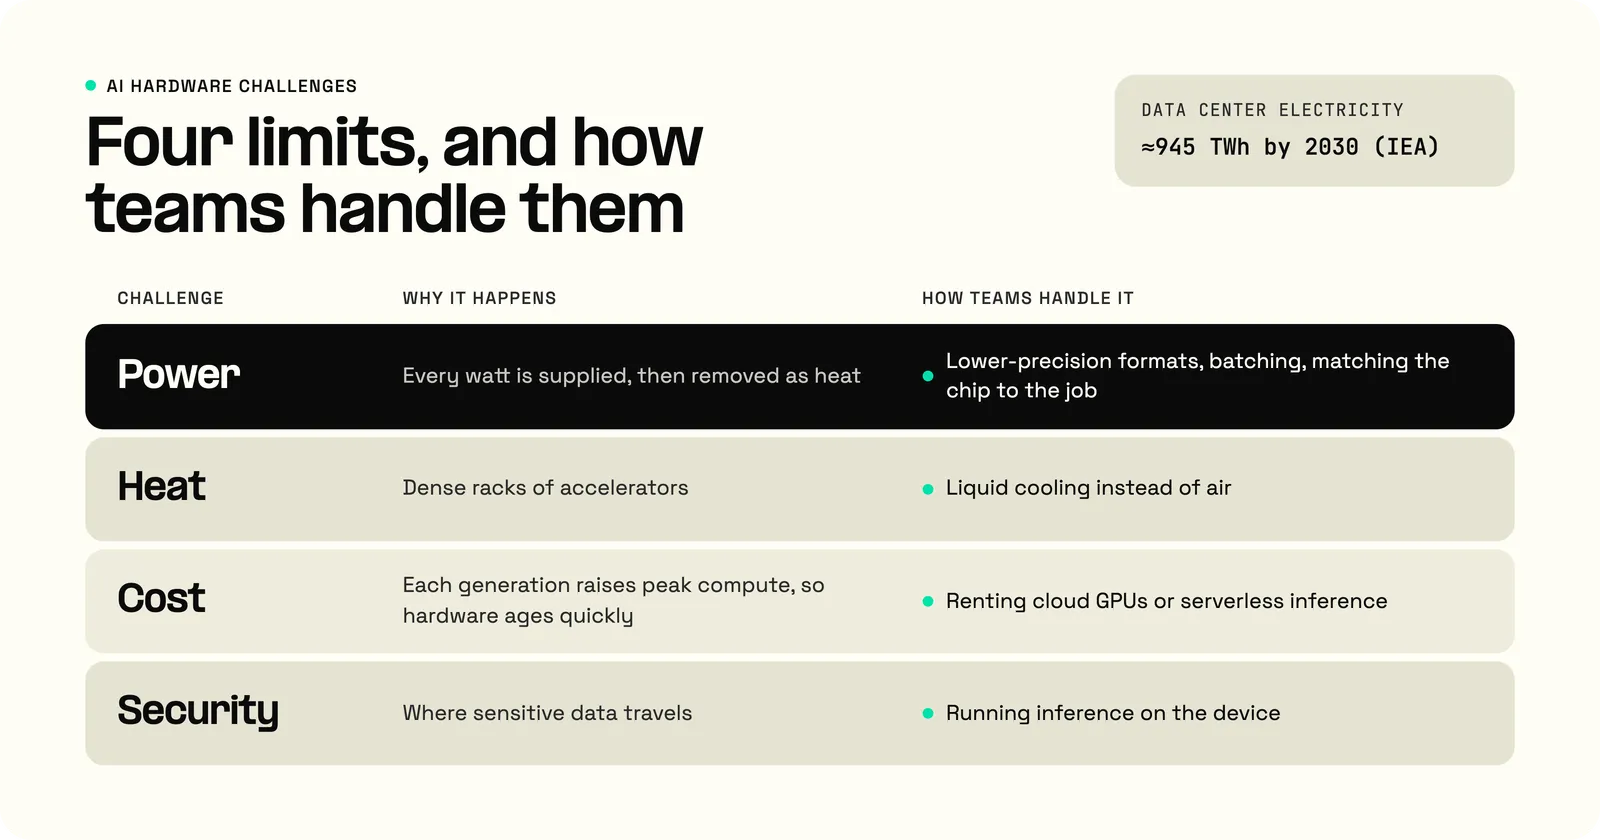
The main challenges of AI hardware are power, heat, cost, and security.
Power sets the ceiling for AI hardware, because every watt a chip draws has to be supplied and then removed as heat. The International Energy Agency projects that data center electricity use will more than double to around 945 TWh by 2030. That is slightly more than Japan's total electricity consumption today, and the IEA names AI as the most important driver.
Dense AI racks increasingly rely on liquid cooling instead of air: NVIDIA builds the GB200 NVL72, with 36 CPUs and 72 GPUs, as a liquid-cooled rack. Operators also apply AI to data center management, including cooling and energy use.
AI accelerators cost more than general-purpose servers, and each new generation raises peak compute, so hardware bought today ages quickly. Many teams rent cloud GPU capacity or use serverless inference instead of owning chips.
Most ethical questions in AI sit with models and training data, but hardware adds two of its own. The first is where sensitive data travels: on-device inference keeps a voice clip or photo on the device, while cloud inference sends it to a server that must be secured. The second is energy, which makes the IEA's projected growth an environmental question, not only a cost one. Bias, by contrast, comes from data and model design, and no chip removes it.
The latest developments in AI hardware target its two hardest limits, memory and power. Memory keeps moving closer to compute through high-bandwidth memory. Number formats keep shrinking for inference, from 32-bit floats toward 8-bit integers. Systems scale out as whole racks of chips wired together, and NPUs push more inference onto phones and laptops.
A quick test shows which limit a served model hits. If throughput keeps climbing as you batch more requests together, memory was the limit, and faster memory will help more than faster math.
The main hardware component for AI is an accelerator, commonly a GPU, that runs the parallel matrix math neural networks depend on. A CPU still coordinates the system and prepares data. Data centers also use TPUs and other custom chips, while phones and laptops use a built-in NPU.
A GPU is one kind of AI accelerator, but not the only kind. An AI accelerator is any chip that takes machine learning math off the CPU, which includes TPUs, NPUs, and FPGAs as well as GPUs. GPUs stay popular because they run nearly any model.
Examples of AI hardware include NVIDIA's data center GPUs, Google's TPUs, and the NPUs built into Copilot+ PCs. Those laptop NPUs perform more than 40 trillion operations per second.
You can run smaller AI models on a regular laptop, and laptops with an NPU run them more efficiently. The largest language models need far more memory than any laptop holds, which is why they run in data centers. Smaller or quantized versions can run locally, trading some capability for privacy and offline use.
Teams handle thermal and power challenges by cutting the energy each result costs and by removing heat more effectively. Lower-precision formats and batching reduce the work per request, and matching the chip to the job avoids running a data center GPU where an NPU would do. In dense racks, liquid cooling replaces air.
Yes, Telnyx runs its voice AI on hardware acceleration. Transcription, model inference, and speech synthesis run as GPU workloads on clusters co-located with the Telnyx telephony network. A call's audio does not cross the public internet to reach a separate AI service.
This content was generated with the assistance of AI. Our AI prompt chain workflow is carefully grounded and preferences .gov and .edu citations when available. All content is reviewed by a Telnyx employee to ensure accuracy, relevance, and a high standard of quality.