AI image style transfer redraws one image in the style of another. How neural style transfer works, fast and diffusion-based methods, uses, and copyright.

Updated September 2026
AI image style transfer is a technique that redraws the content of one image in the visual style of another. It keeps the layout and objects of a photo and renders them with the colors, textures, and brushwork of a painting or any other reference image. The original method uses a neural network, so it is also called neural style transfer, and the same task now runs in photo apps and in diffusion-based image editors that work differently.
The original method rests on a 2015 finding by Gatys and colleagues: a network trained only to recognize objects represents what an image shows and how it looks in ways that can be pulled apart. Reading the content from one image and the style from another, then searching for a picture that matches both, lets the network paint a photo of a river town as a Van Gogh.
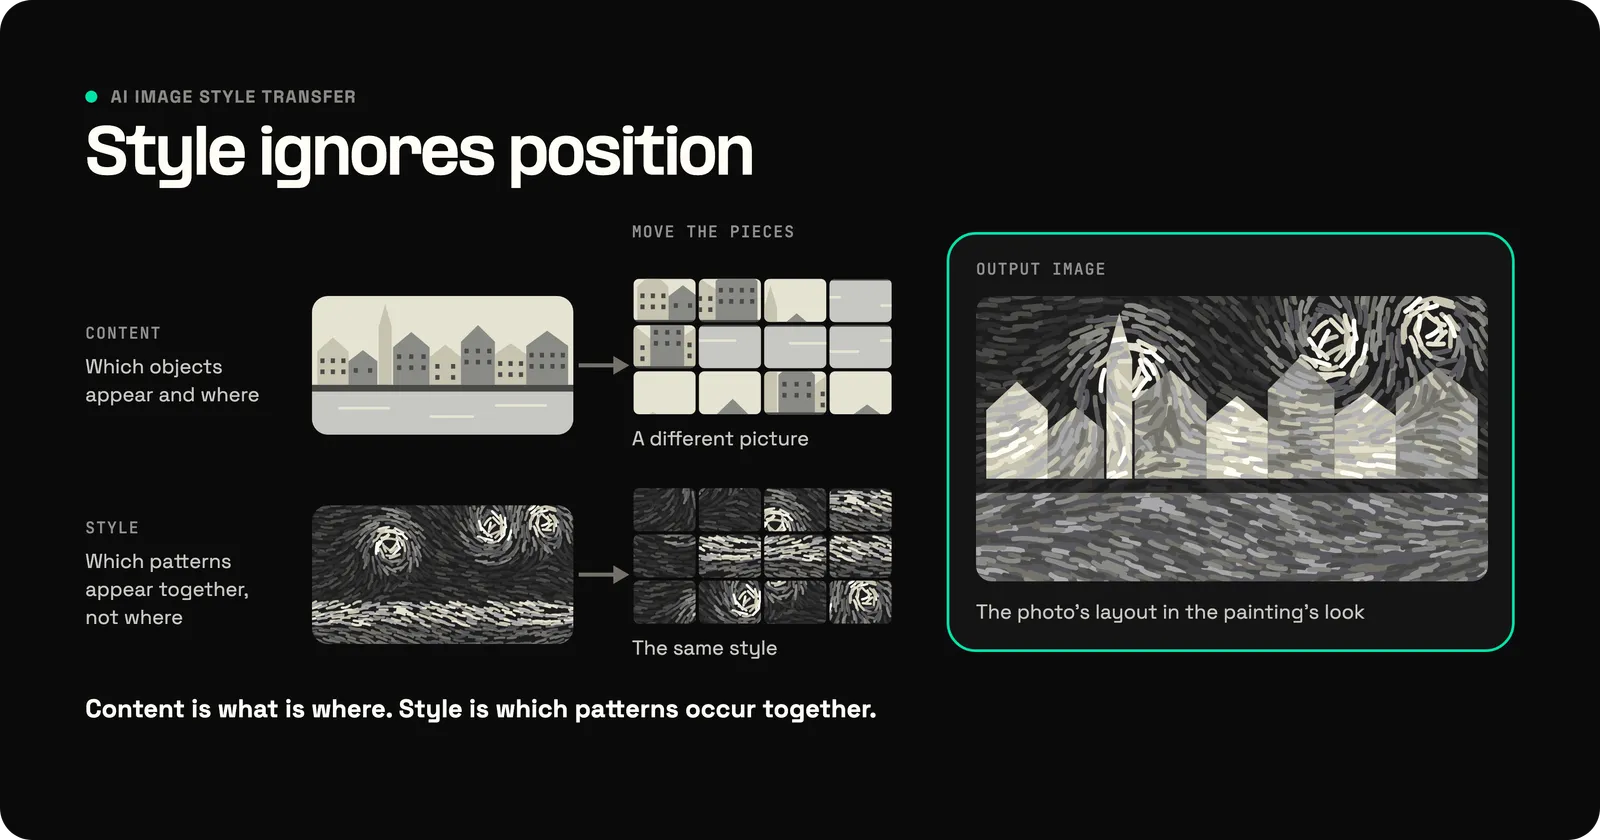
AI image style transfer splits an image into two things a network can measure: content, meaning which objects appear and where, and style, meaning the textures, colors, and strokes that repeat across the picture. The method needs a content image, a style source (a reference image or, for diffusion models, a text description), and a model, and it produces one output image that keeps the content and borrows the style.
Style, to a recognition network, is a set of statistics rather than a subject. It records which visual patterns tend to appear together, such as short curved strokes with deep blues, and ignores where they appear. That is why a style can be lifted from a painting of a night sky and laid over a photo of a street: the model carries over how the painting looks, not what it depicts.
AI image style transfer works in one of two families of methods, which together cover four main types. The older family measures content and style inside a trained recognition network and changes an output image until both measurements match. Neural style transfer does that by optimizing the pixels directly, and later networks learn to do it in one pass. The newer family partially noises the photo and lets a diffusion model redraw it under a style prompt.
Neural style transfer, the original method from Gatys, Ecker, and Bethge, uses a convolutional neural network trained for object recognition, the VGG network. Each layer of that network produces feature maps, grids of numbers that respond to edges, textures, and eventually whole object parts, which pooling layers shrink as the image moves deeper.
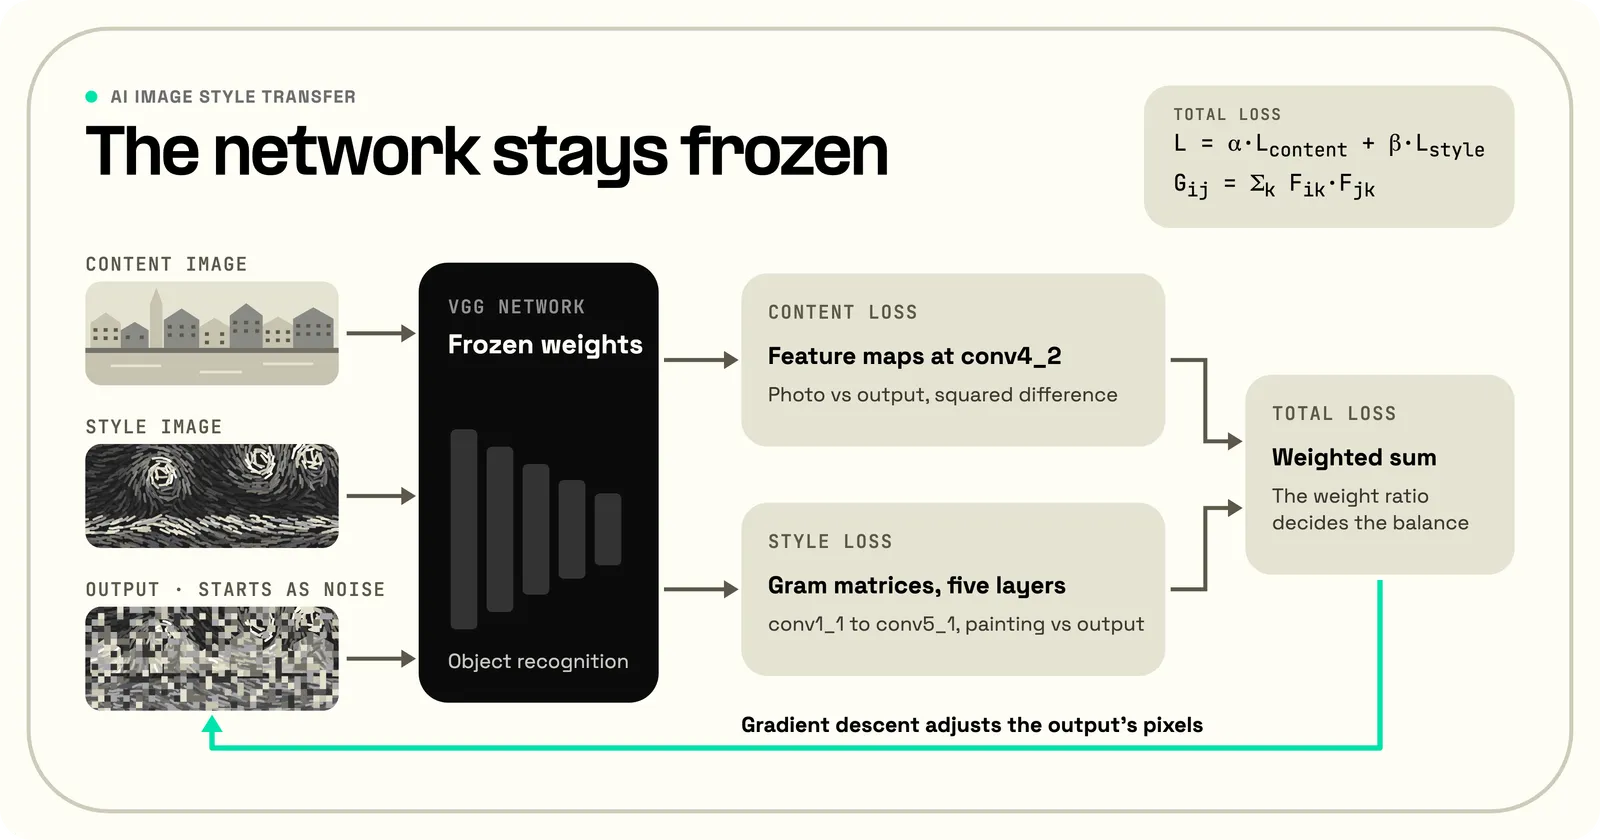
The content of the photo is its feature maps at one deep layer, which record what is where. The style of the painting is the correlations between feature maps at several layers, which record which patterns occur together. For the paper's figures, content was matched at one layer, conv4_2, and style at five, conv1_1 through conv5_1, with equal weight on each. Using several layers lets the style carry both fine brush texture from the early layers and larger repeating shapes from the deep ones. The output image starts as noise and is repeatedly adjusted by gradient descent until its content matches the photo and its style matches the painting.
What makes the method unusual is what it optimizes. Ordinary training changes a network's weights and leaves the data alone, while neural style transfer freezes the network and changes the image itself.
The two measurements become two losses. The content loss is the squared difference between the output's feature maps and the photo's feature maps at the chosen layer. The style loss uses a Gram matrix for each layer: every entry multiplies two feature maps together position by position and sums the result. The entry counts how strongly two patterns appear together across the whole image, regardless of position. The style loss is the squared difference between the output's Gram matrices and the painting's.
The total loss function is a weighted sum of the two, and the ratio of the weights decides the balance. A heavier style weight gives a more painterly result that drifts from the photo, and a heavier content weight keeps the photo recognizable with a lighter wash of style. Because the Gram matrix discards position, the style loss can reproduce a texture anywhere in the output, which is also why it copies brush texture well and composition not at all.
The original method had four clear weaknesses. It copied the painting's colors along with its texture, gave no control over which region got which style, turned photos into paintings even when a photo was the goal, and flickered on video. Later work addressed each one, with its own trade-offs. Gatys and colleagues showed how to keep the photo's own colors while taking only the painting's texture, and a follow-up added control over which regions get which style and at what scale. Luan and colleagues constrained the output to stay photorealistic in a method they called deep photo style transfer, which transfers lighting and time of day between photos without turning them into paintings. Ruder and colleagues extended the method to video by penalizing changes between frames, since styling each frame alone makes the texture flicker.
Optimizing the pixels takes many passes through the network for every image. Johnson and colleagues replaced that search with a feed-forward network trained once per style, using the same content and style measurements as its training loss, which they called perceptual loss. They report results similar to the optimization method at up to three orders of magnitude faster. On a GTX Titan X GPU, their network took 0.05 seconds for a 512 by 512 image, against 10.97 to 54.85 seconds for 100 to 500 iterations of optimization. That is a speedup of 205 to 1,026 times. The catch is one network per style.
Dumoulin and colleagues fit 32 styles into one network by giving each style its own normalization parameters. Normalization rescales each feature map to a chosen mean and spread, and much of a style turns out to live in those two numbers per map. Huang and Belongie removed the limit on styles altogether with adaptive instance normalization (AdaIN), which shifts the content image's features to take on the mean and variance of the style image's features. An encoder-decoder network then turns the adjusted features back into an image, for any style, in one pass. On a later Pascal Titan X GPU, the authors report 15 images per second at 512 by 512 pixels, or about 0.07 seconds each, not counting the one-time encoding of the style image. The two papers used different GPUs, so their timings are not a head-to-head comparison.
Diffusion-based style transfer uses an image generator instead of a recognition network. A diffusion model learns to turn noise into an image step by step, so it can restyle a photo by adding partial noise and denoising it toward a new look. SDEdit introduced that approach. The image-to-image mode of Stable Diffusion uses it, run in the model's compressed image space, which is the "latent" in latent diffusion. A denoising strength setting decides how much noise is added: a little keeps the photo's structure, a lot hands more of the picture to the model. The model behind it is large. Stable Diffusion pairs an 860 million parameter denoising network with a 123 million parameter text encoder, and its README calls for a GPU with at least 10 GB of memory.
Two add-ons give that process control. IP-Adapter lets a reference image steer the generator the way a text prompt would, with a weight that sets how strongly it counts. At full weight the adapter carries the reference's subject as well as its look, so style-only use means turning the weight down. ControlNet holds the structure in place by conditioning the generator on an edge map, a depth map, or a pose, so the style can change while the outline stays put. A text prompt such as "in the style of a watercolor" can also carry the style, without any reference image.
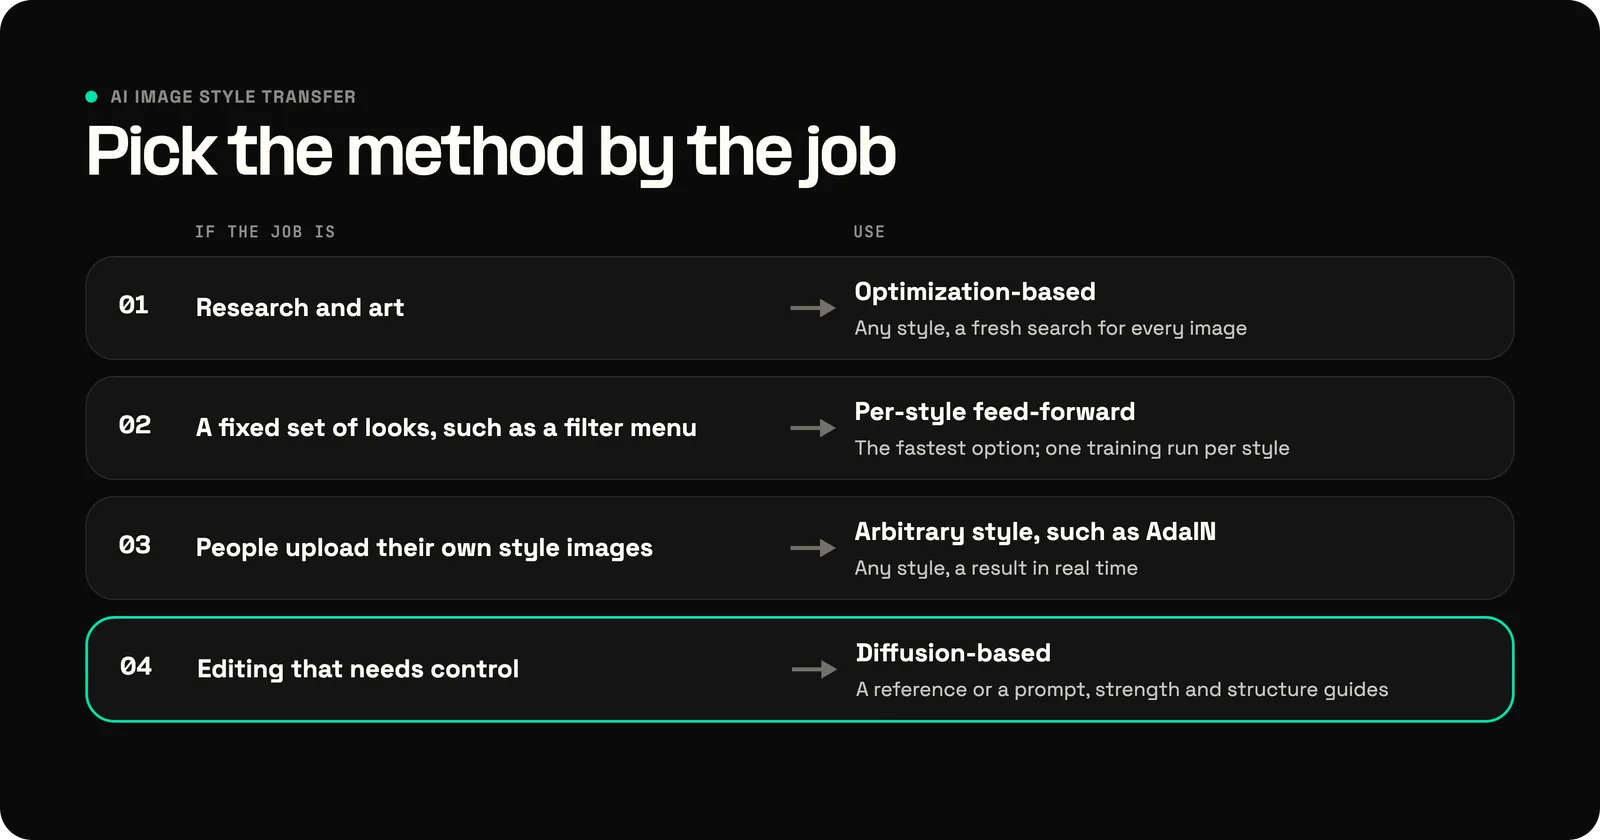
The main types of AI image style transfer are optimization-based, per-style feed-forward, arbitrary-style, and diffusion-based methods, and the choice between them comes down to speed, flexibility, and control. Optimization-based transfer needs no training beyond the pretrained recognition network and accepts any style, but it runs a fresh search for every image, which makes it a research and art tool rather than a product feature. A per-style network is the fastest option for a fixed set of looks, such as a filter menu, and costs one training run per style. An arbitrary-style method such as AdaIN suits a feature where people upload their own style images and expect a result in real time. A diffusion-based pipeline suits editing that needs control, since it accepts a reference image or a text prompt and exposes a strength setting and structure guides. It pays for that with many denoising steps per image and a much larger model.
A related family, image-to-image translation, learns a mapping between two whole collections of images rather than copying one reference. Despite the similar name, it is a different thing from Stable Diffusion's image-to-image mode, which edits one photo at a time. CycleGAN, for example, learned to turn photos into paintings in the style of Monet from unpaired sets of each. It trains two networks against each other, one generating paintings and one judging whether they look real, and adds a cycle-consistency loss: a photo turned into a painting and back should return the original photo. It transfers a collection's look, not a single picture's.
The styles themselves are open-ended. Any image with a consistent look can serve as the reference: oil and watercolor painting, pencil sketch, woodcut, anime and cartoon, pixel art, stained glass, or a photographer's color grade. Some styles transfer better than others. Styles defined by texture and color, such as Impressionist brushwork, carry over cleanly. Styles defined by shape and exaggeration, such as caricature, need a generative model, a GAN or a diffusion model, because texture statistics alone cannot bend a face.
The best-known example of AI image style transfer is the first one. In the original paper, Gatys and colleagues took a photograph of the riverfront in Tübingen, Germany, and rendered it in five painters' styles. The paintings were Turner's The Shipwreck of the Minotaur, Van Gogh's The Starry Night, Munch's The Scream, Picasso's Femme nue assise, and Kandinsky's Composition VII. The houses and the river stay where they are in every version; only the rendering changes.
Later papers each added an example that the original could not do. CycleGAN turned landscape photos into paintings in the manner of Monet, Van Gogh, Cézanne, and Japanese ukiyo-e prints, learning each look from a collection rather than one canvas. Deep photo style transfer moved the lighting of a dusk photo onto a daytime shot of a city, so the result still reads as a photograph. Diffusion-based editors now handle the everyday cases: a portrait as a watercolor, a product shot in an anime style, a sketch rendered as a finished illustration.
AI image style transfer is used to restyle photos and video, to make art, and to generate training data, and a related technique, voice cloning, applies the same idea to speech.
Photo and video editors use style transfer for one-tap looks: turning a portrait into a painting, matching a set of photos to one color grade, or giving a video a consistent illustrated style. Video needs the temporal methods above, since a style applied frame by frame flickers. The photorealistic variants handle the quieter jobs, such as moving the light of a sunset photo onto a midday shot of the same scene.
Artists use style transfer to explore a composition in many looks before committing to one, to render concept art in a studio's house style, or to turn a sketch into a finished-looking piece. The diffusion-based tools changed the workflow most, because a structure guide lets an artist keep their own drawing and change only its rendering. The artist still decides what the picture shows; the method changes how it looks.
Style transfer also generates training data for other models. Geirhos and colleagues found that image classifiers trained on ImageNet rely heavily on texture rather than shape, then retrained them on a stylized copy of ImageNet made with AdaIN. The stylized data pushed the models toward shape and made them more resistant to common image distortions. Restyling the same labeled images many ways teaches a model that the label does not depend on the texture.
Voice cloning applies the content and style split to speech: the words are the content, and the speaker's timbre and delivery are the style. Telnyx's Voice Design Lab creates a voice from a natural-language description or clones one from a short recording, then speaks any new text in it. Each voice gets an ID that works across AI Assistants, Call Control, and the text-to-speech API, so the same voice can speak for voice AI agents built on Telnyx. The mechanism is speech synthesis rather than an image method, but the split between what is said and how it sounds is the same one.
Voice Design Lab runs in the Telnyx portal, so trying it takes a Telnyx account: a written description returns three audio samples, and the one saved becomes a reusable voice.
Changing the style of an image with AI takes a content image, a style source, and one setting that decides how far the output may drift from the original. For someone restyling a photo with a diffusion-based editor, the process has five steps:
The older methods reduce to fewer choices. An optimization-based tool takes a content image, a style image, and a style weight, and a one-style filter takes only the photo.
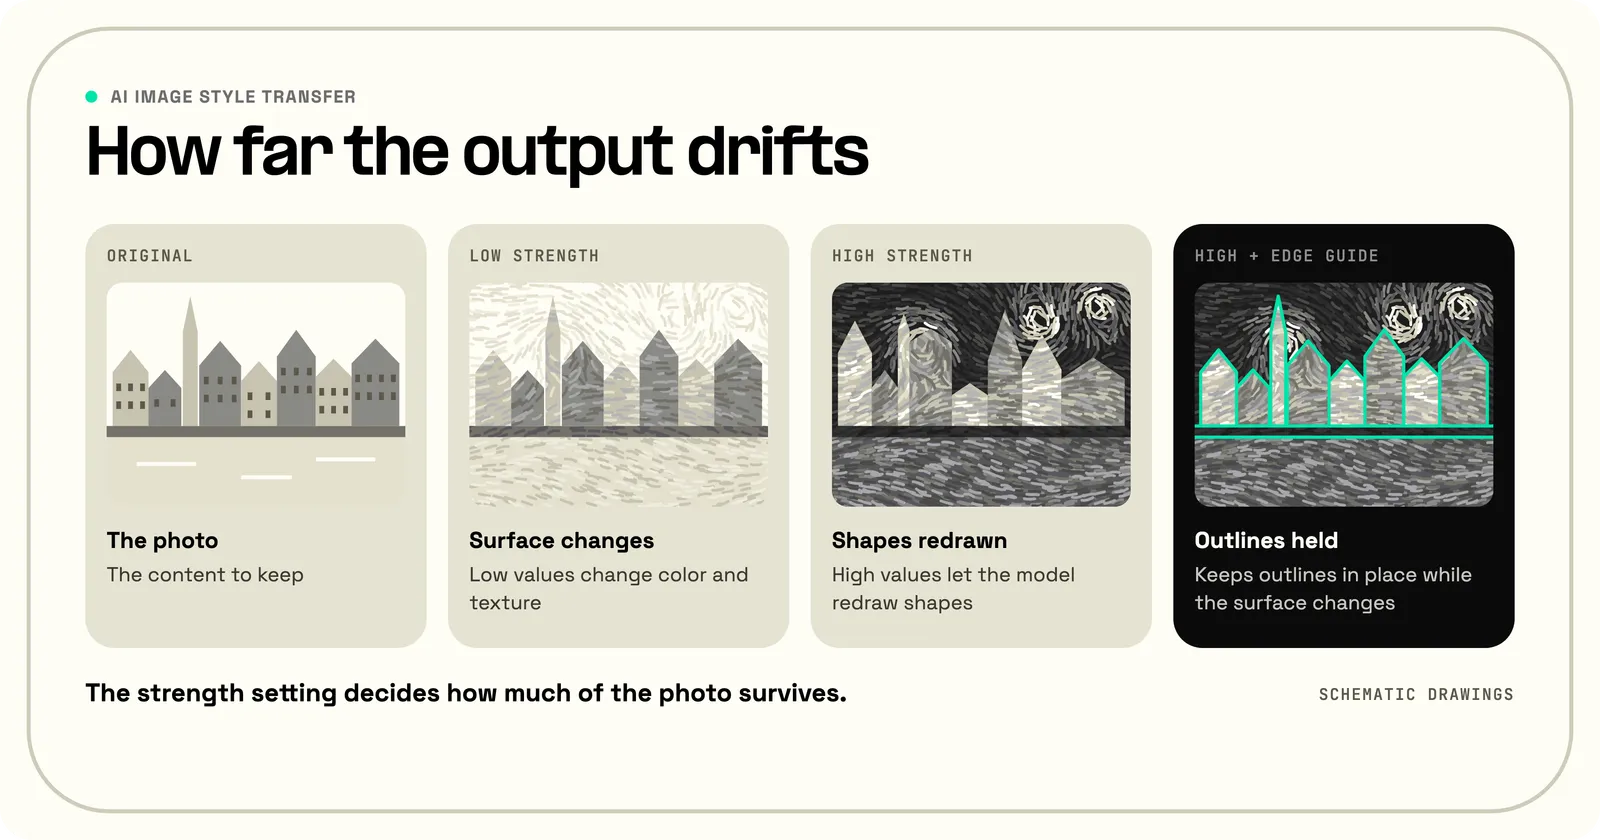
The main challenges of AI image style transfer are distortion, leakage, evaluation, cost, and ownership. Content distorts first where people look hardest: faces, hands, and text lose their structure as the style weight rises. With reference-image methods such as IP-Adapter, style can also leak content, carrying a painting's objects or composition into the output instead of only its technique, and a high adapter weight makes that more likely. The Gram-matrix methods have the opposite limit: they copy texture and discard composition. No agreed metric says whether an output looks like the style, so results are usually judged by eye, in side-by-side comparisons. And the fast methods still need a GPU to run at interactive speed. For a product, model licenses are part of the cost: the original Stable Diffusion weights use the CreativeML OpenRAIL-M license, which permits commercial use with use-based restrictions, and each later model and adapter carries its own terms.
Ownership is the open question. In the United States, the Copyright Office's January 2025 copyrightability report concluded that copyright does not extend to purely AI-generated material, or to material where a person had insufficient control over the expressive elements. It also found that prompts alone do not provide that control. The federal appeals court in Washington, D.C., upheld the human-authorship requirement in Thaler v. Perlmutter in March 2025. Leakage is also where the practical copyright risk sits: an output that carries over recognizable parts of a specific reference work can infringe it, whatever method made it. Whether training image models on copyrighted art is lawful is still unresolved: Andersen v. Stability AI, the artists' suit against image-model developers filed in January 2023, had not reached trial as of September 2026.
AI can change the style of an image while keeping what it shows. A style transfer model redraws the photo's layout and objects with the colors and textures of a reference image or a text description. Diffusion-based editors add a strength setting and structure guides, so the change can range from a color grade to a full repaint.
The best AI tool for style transfer depends on the job. A one-style filter is fastest for a fixed look. An arbitrary-style method such as AdaIN handles any reference image in real time. A diffusion-based pipeline, such as Stable Diffusion with IP-Adapter and ControlNet, gives the most control over how much of the original survives. Comparing tools on the same photo and the same reference is the only fair test.
Free AI style transfer is available through open-source models that run on a personal computer with a capable GPU. The original neural style transfer method, AdaIN, and Stable Diffusion with IP-Adapter and ControlNet all have public code and weights. Hosted apps often offer free tiers, with limits on resolution or the number of images.
Copying an art style with AI works best with a clear reference image in that style and a structure guide to protect the content. The reference goes to an image-prompt adapter or an arbitrary-style model, and the adapter's weight controls how strongly the reference takes over; too high a weight copies its subject too. Styles defined by texture and color copy most reliably; styles defined by exaggerated shapes need a diffusion-based method.
Copying an art style with AI is not illegal in itself in the United States, because copyright protects specific works, not a creator's style, as the Copyright Office's 2025 training report notes. The risk sits elsewhere: an output that reproduces recognizable parts of a particular work can infringe it, and a purely AI-generated output may not be protected by copyright at all. This is general information, not legal advice, and the law on training data is still unsettled.
Neural style transfer is the original 2015 method of AI style transfer, from Gatys, Ecker, and Bethge. It uses an object-recognition network to measure a photo's content and a painting's style, then adjusts a new image by gradient descent until it matches both. Later feed-forward methods made it fast while keeping its content and style measurements; diffusion-based methods replaced those measurements with a noise-strength setting and a style prompt.
Style transfer starts from an existing image and changes how it looks, while image generation creates a picture from a prompt or from noise. The line has blurred because diffusion models do both: the image-to-image mode is style transfer, and text-to-image is generation. The test is whether an input image's content is kept.
Style transfer's split between content and style has a direct parallel in speech: the words are the content and the speaker's voice is the style. Telnyx's Voice Design Lab builds a voice from a description or clones one from a recording, then speaks new text with it through the Telnyx Voice API. The voice keeps the speaker's sound; the content is whatever text the application sends.
This content was generated with the assistance of AI. Our AI prompt chain workflow is carefully grounded and preferences .gov and .edu citations when available. All content is reviewed by a Telnyx employee to ensure accuracy, relevance, and a high standard of quality.