A unit in a neural network is an artificial neuron that weights its inputs, adds a bias, and applies an activation. Unit types, hidden units, layer width.

Updated September 2026
A unit is the basic building block of a neural network, responsible for processing input data and generating an output. In the context of neural networks, a unit is often called a neuron or perceptron. Each unit takes multiple inputs, applies a set of weights, adds a bias, and passes the result through an activation function to produce an output, which becomes an input to the units in the next layer.
Units are grouped into layers: every unit in a layer reads the same inputs, and the layer's outputs together form the next layer's input. Chaining layers this way is how every neural network is built, from a classroom example to a large language model.
The smallest example network in Stanford's CS231n notes has 6 units, not counting its inputs, and 26 learnable parameters, the weights and biases that training sets. has 175 billion parameters in 96 layers, and its authors put the main width of each layer, its unit count, at 12,288.
This content was generated with the assistance of AI. Our AI prompt chain workflow is carefully grounded and preferences .gov and .edu citations when available. All content is reviewed by a Telnyx employee to ensure accuracy, relevance, and a high standard of quality.
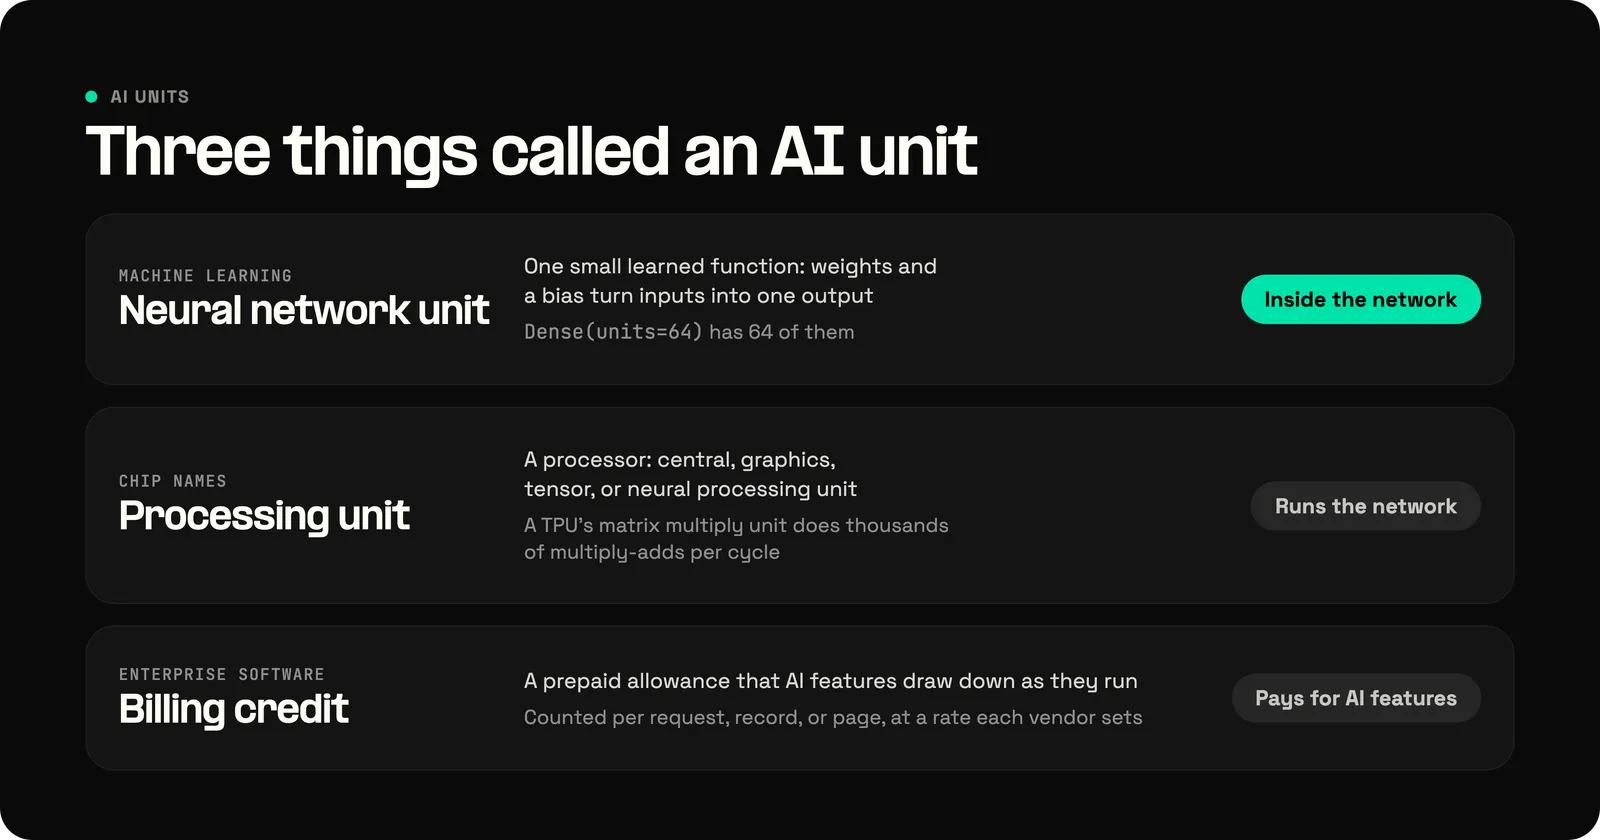
The phrase "AI units" also has meanings outside neural networks. Enterprise software vendors sell AI units as prepaid credits for their AI features, and chipmakers use "unit" for the processors that run neural networks. Neither is a neural network unit, though an AI chip is built to compute neural network units quickly.
In AI, a neural network unit is one small learned function: a set of weights and a bias that turn several input numbers into one output number. The weights and bias are the unit's parameters, the values that training adjusts, while the activation function is chosen by whoever designs the network.
The same unit goes by four interchangeable names: unit, neuron, node, and neural unit. Machine learning texts often prefer unit. The GPT-3 paper measures layer width in units, and CS231n notes that many people "prefer to refer to neurons as units" because they dislike the analogy to real brains. The same notes call the artificial neuron "a very coarse model of a biological neuron." Node is the name from network diagrams, which draw each unit as a node and each weight as a connection between two nodes.
Perceptron is the narrower term. In Frank Rosenblatt's 1958 perceptron, units fire on an all-or-nothing basis once their summed input reaches a threshold, the behavior Warren McCulloch and Walter Pitts had described for all-or-none neurons in 1943. Calling every unit a perceptron is common shorthand, kept alive in the name multilayer perceptron. Most modern units replace the on-off threshold with a graded activation function such as ReLU, which passes positive values unchanged and outputs zero for negative ones. A graded output gives training a slope to follow, which an on-off step does not.
A unit in a neural network works in three steps: it multiplies each input by a weight, adds the products and a bias, and passes the sum through an activation function.
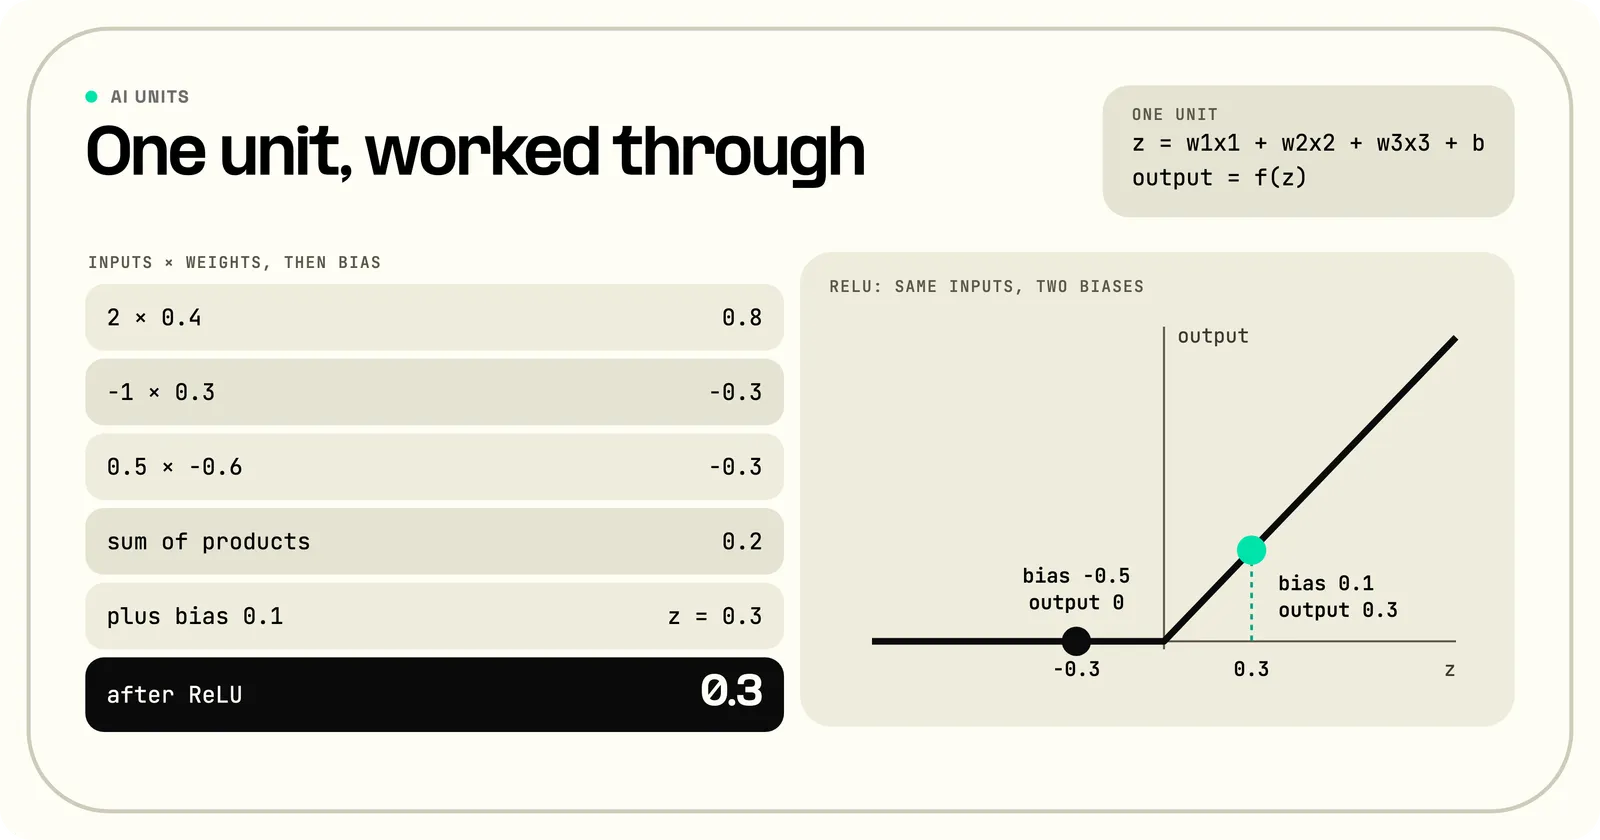
Written out, a unit with three inputs computes z = w1*x1 + w2*x2 + w3*x3 + b and then outputs f(z), where f is the activation function. The Deep Learning textbook by Goodfellow, Bengio, and Courville describes most hidden units exactly this way: an affine transformation, meaning a weighted sum plus a constant, followed by a nonlinear function. In the textbook's account, what separates one kind of hidden unit from another is mostly the choice of f; the other difference is how the unit connects to its inputs.
With f set to ReLU, a unit with inputs 2, -1, and 0.5, weights 0.4, 0.3, and -0.6, and a bias of 0.1 outputs 0.3. The weighted sum is 0.4(2) + 0.3(-1) + (-0.6)(0.5) = 0.8 - 0.3 - 0.3 = 0.2, and adding the bias gives z = 0.3. ReLU leaves a positive value unchanged, so the output stays 0.3.
The bias in that example sets how much weighted evidence the unit needs before it responds. Change the bias from 0.1 to -0.5 and z drops to -0.3, so the same inputs now produce an output of 0. The weights set how much each input matters and in which direction: a positive weight raises the weighted sum as its input grows, and a negative weight lowers it.
Weights and a bias alone would make every unit linear, and the activation function is what makes a stack of units more capable than a single one. A weighted sum of weighted sums is still one weighted sum, so any depth of purely linear units collapses into a single layer's worth of computation. The nonlinearity lets later units combine earlier ones into curves, thresholds, and interactions that no single weighted sum can express.
Later units sit in later layers, and a layer computes all of its units at once. A layer of d units outputs d numbers, one per unit, so a layer's width counts both its units and its outputs. Each unit's weights form one row of the layer's weight matrix, which is how PyTorch's nn.Linear stores a layer. One matrix multiplication plus a bias vector then gives every unit's weighted sum in a single step. Passing an input through every layer this way, first to last, is forward propagation.
The weights that forward propagation uses start out random and are learned in training. After each forward pass, the network's output is compared with the correct answer, and backpropagation works backward through the layers to calculate how much each weight contributed to the error. That contribution is the weight's gradient. An optimizer then adjusts every weight and bias against its gradient to shrink the error, and repeating the cycle over many examples is what training means.
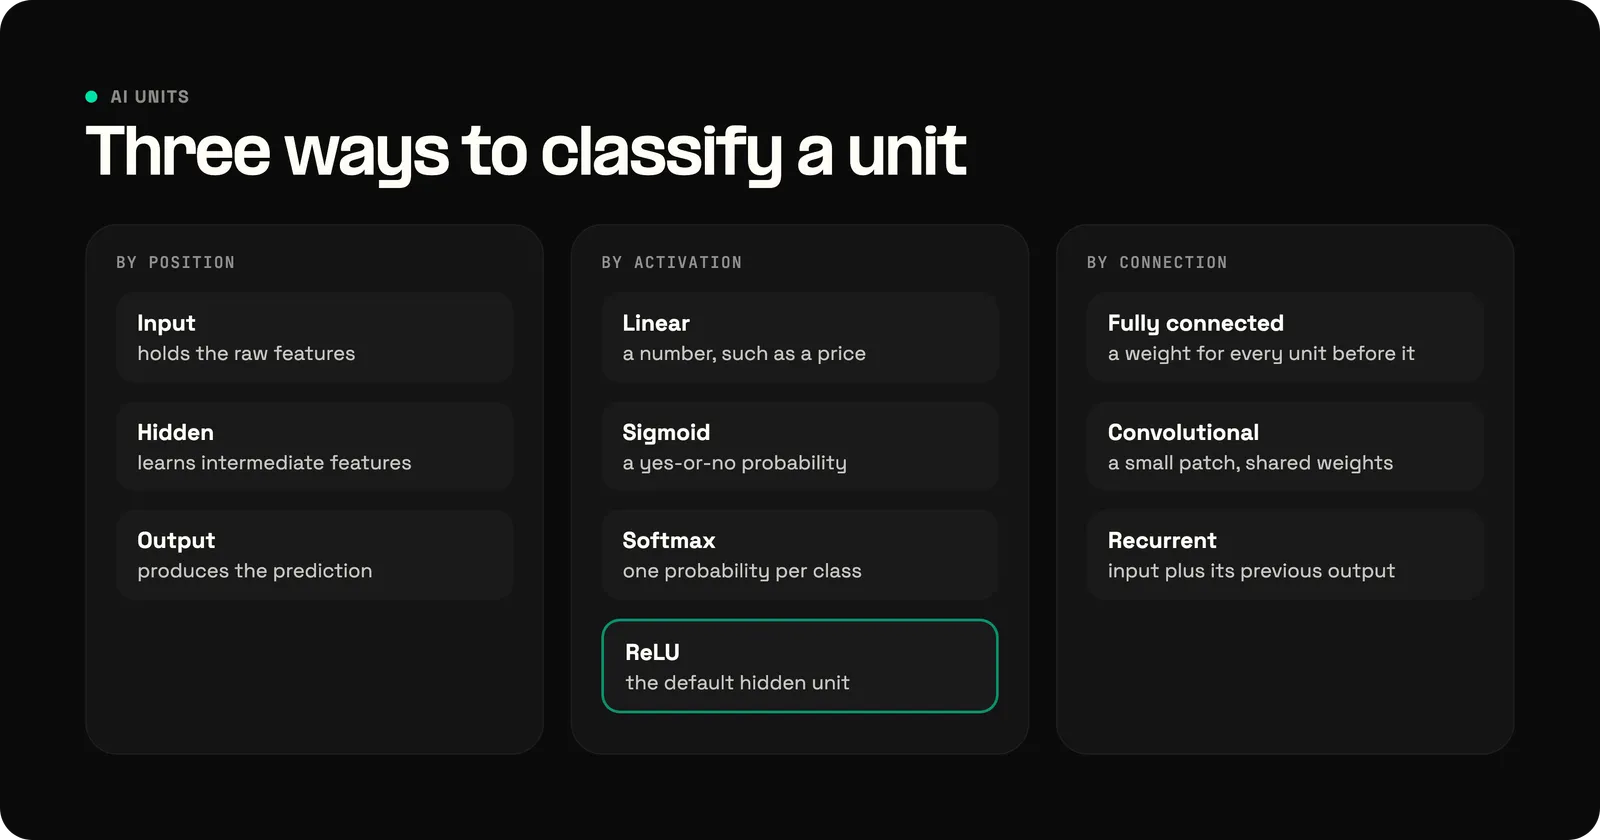
Units in AI are classified three ways: by where they sit in a network, by their activation function, and by how they connect to their inputs. Position gives input, hidden, and output units; activation gives linear, sigmoid, softmax, and ReLU units; and connection gives fully connected, convolutional, and recurrent units. The perceptron and the parts of a transformer layer are special cases built from the same pieces.
Input units hold the raw features, such as the pixels of an image or the samples of an audio clip. They compute nothing, so CS231n leaves them out when it counts a network's units. Hidden units sit between the input and output layers and learn the intermediate features the task needs. Output units produce the prediction, and the right activation for them depends on what the network predicts.
The Deep Learning textbook matches output units to the kind of answer. A linear unit, a weighted sum with no nonlinearity, outputs a number such as a price or a temperature. A sigmoid unit outputs a probability between 0 and 1 for a yes-or-no question. A layer of softmax units outputs one probability per class, normalized together so the probabilities sum to 1, which is why a 10-class classifier ends in 10 output units.
For hidden units, the same textbook calls rectified linear units (ReLU) "an excellent default choice of hidden unit." Most older networks used sigmoid or tanh hidden units; tanh is an S-shaped curve like the sigmoid, running from -1 to 1 instead of 0 to 1. The book now discourages them as hidden units in feedforward networks, where data flows one way from input to output. The reason is saturation: for large positive or negative inputs, their output flattens and the gradient shrinks toward zero.
ReLU is flat too, but only below zero: a unit with positive input keeps a slope of 1, while sigmoid and tanh flatten at both ends. A ReLU unit whose input stays negative gets no gradient and stops learning on those examples, which is why variants such as leaky ReLU keep a small slope, such as 0.01, below zero.
A fully connected unit, the kind in a dense layer, has a separate weight for every unit in the layer before it. Deep Learning describes a traditional layer as one where "every output unit interacts with every input unit."
A convolutional unit looks at only a small patch of its input, such as a few neighboring pixels. It shares its weights with every other unit in the same feature map, the grid of outputs that one set of weights produces. That shared set of weights is the kernel. The convolution is the operation that slides the kernel across the input and computes a weighted sum at each position. That lets the layer learn one small pattern detector instead of a separate set of weights for every position. Each of those position-by-position weighted sums is one convolutional unit.
Recurrent units have connections that form directed cycles, allowing them to maintain a memory of previous inputs. At each step of a sequence, a recurrent unit receives the current input along with the layer's output from the previous step. That feedback is how it carries context from one word or audio frame to the next. The memory made recurrent units a common choice for sequence modeling of text and audio.
Plain recurrent units struggle to hold information across long gaps, because the training signal decays as it flows back through many steps, as Hochreiter and Schmidhuber explained in 1997. Their fix was gating. A gate is a small unit whose sigmoid output, between 0 and 1, multiplies another value to decide how much of it passes.
The long short-term memory (LSTM) cell uses gates to control what enters its memory, what leaves it, and, since a 2000 extension, what it forgets. The gated recurrent unit, proposed by Cho and colleagues in 2014, does a similar job with just two gates, reset and update.
A transformer has no single "transformer unit." Each transformer layer has two parts. Attention heads let every position in a sequence weigh every other position, and the query, key, and value projections inside each head are layers of linear units. A feed-forward sublayer of ordinary units then transforms each position separately.
In the original Transformer base model, each position leaves every layer as the outputs of 512 units, and inside the feed-forward sublayer it widens to 2,048 units before being projected back down to 512. Many recent language models replace that sublayer's activation with a gated linear unit, which multiplies one weighted sum by a gate computed from a second weighted sum.
A perceptron unit is a weighted sum followed by a threshold, with an output of 1 or 0. Rosenblatt's perceptron was among the first models that could learn its weights from examples, according to Deep Learning.
A single layer of perceptrons can only separate classes with a straight line, or a flat boundary in more dimensions. That rules out XOR, the function that outputs 1 when exactly one of its two inputs is 1. Plot XOR's four input pairs on a grid, and the two that output 1, (0, 1) and (1, 0), sit on opposite corners. No single straight line can put both 1s on one side and both 0s on the other.
The XOR limit shaped the field's history. The Deep Learning textbook traces a backlash against early neural networks to critics of this flaw. Marvin Minsky and Seymour Papert's 1969 book Perceptrons analyzed the limits of single-layer networks on problems like parity, of which XOR is the two-input case.
One layer of hidden units removes the limit. The textbook's worked solution uses two hidden units: one outputs ReLU(x1 + x2), and the other outputs ReLU(x1 + x2 - 1), which stays 0 unless both inputs are 1. The output unit takes the first minus twice the second: 0 for (0, 0), 1 for (0, 1) and (1, 0), and 2 minus twice 1, which is 0, for (1, 1).
Hidden units are the units between a neural network's input and output layers. They are called hidden because the training data specifies only the inputs and the desired outputs, never what the units in between should compute, which is the reason Deep Learning gives for the name. A layer made of hidden units is a hidden layer.
Because nobody specifies their targets, training alone determines what hidden units detect. In their 1986 Nature paper on backpropagation, Rumelhart, Hinton, and Williams showed that hidden units come to represent the important features of a task as training adjusts their weights. No one labels those features; they emerge because they help the output units get the answer right.
Individual hidden units can often be read. In a PNAS study titled "Understanding the role of individual units in a deep neural network," Bau and colleagues found units in a scene classifier that respond to specific objects. Some respond to trees, although the network was never taught the concept of a tree. Removing the 20 units most important to one scene class, ski resorts, out of 512 in that layer, cut the classifier's accuracy on that class from 81.4% to 53.5%, close to the 50% of guessing.
Beyond what single units detect, their number sets what a network can represent. The universal approximation theorem, as the Deep Learning textbook states it, says one hidden layer with enough hidden units can approximate any continuous function on a bounded range of inputs to any accuracy. Later work extended the result to rectified linear units. The catch is "enough": a single hidden layer may need an impractically large number of units, and deeper networks can often do the same job with far fewer.
The task sets the number of units in the output layer, and you choose the number in each hidden layer by testing a few widths on validation data, examples held out from training. A classifier over several classes needs one softmax unit per class, a yes-or-no classifier needs a single sigmoid unit, and a regression model needs one linear unit per predicted value. Hidden-layer width is a hyperparameter, set before training rather than learned.
In code, the unit count is the layer's width argument. Keras calls it units and PyTorch calls it out_features. Both layers below have 64 units reading 784 inputs, the pixel count of a 28-by-28 image:
# TensorFlow Keras: 64 units; Keras infers the 784 inputs from the layer before it
tf.keras.layers.Dense(units=64)

# PyTorch: the same layer, sized by in_features and out_features
torch.nn.Linear(in_features=784, out_features=64)
A Keras Dense layer with no activation argument stays linear: TensorFlow's reference says that if you specify nothing, "no activation is applied." Stacked without activations, Dense layers collapse into one linear layer, so hidden Dense layers normally set one, such as activation="relu". The activation shapes each unit's output; it never changes how many units the layer has.
Recurrent layers use the same units argument. In a recurrent layer such as LSTM(units=128), each of the 128 units is one number in the hidden state, the vector the layer carries from one step of a sequence to the next. The cell's gates update all 128 at every step.
Convolutional layers are sized differently. Keras's Conv2D takes filters, which the Conv2D reference defines as the number of filters in the convolution, and each filter's kernel produces a feature map with one unit per position. A Conv2D layer with 32 filters of 3 by 3, run over a 28-by-28 image, produces 26-by-26 feature maps, so it has 32 × 676 = 21,632 units. On a one-channel image it has only 320 parameters: 32 kernels of 9 weights plus a bias each.
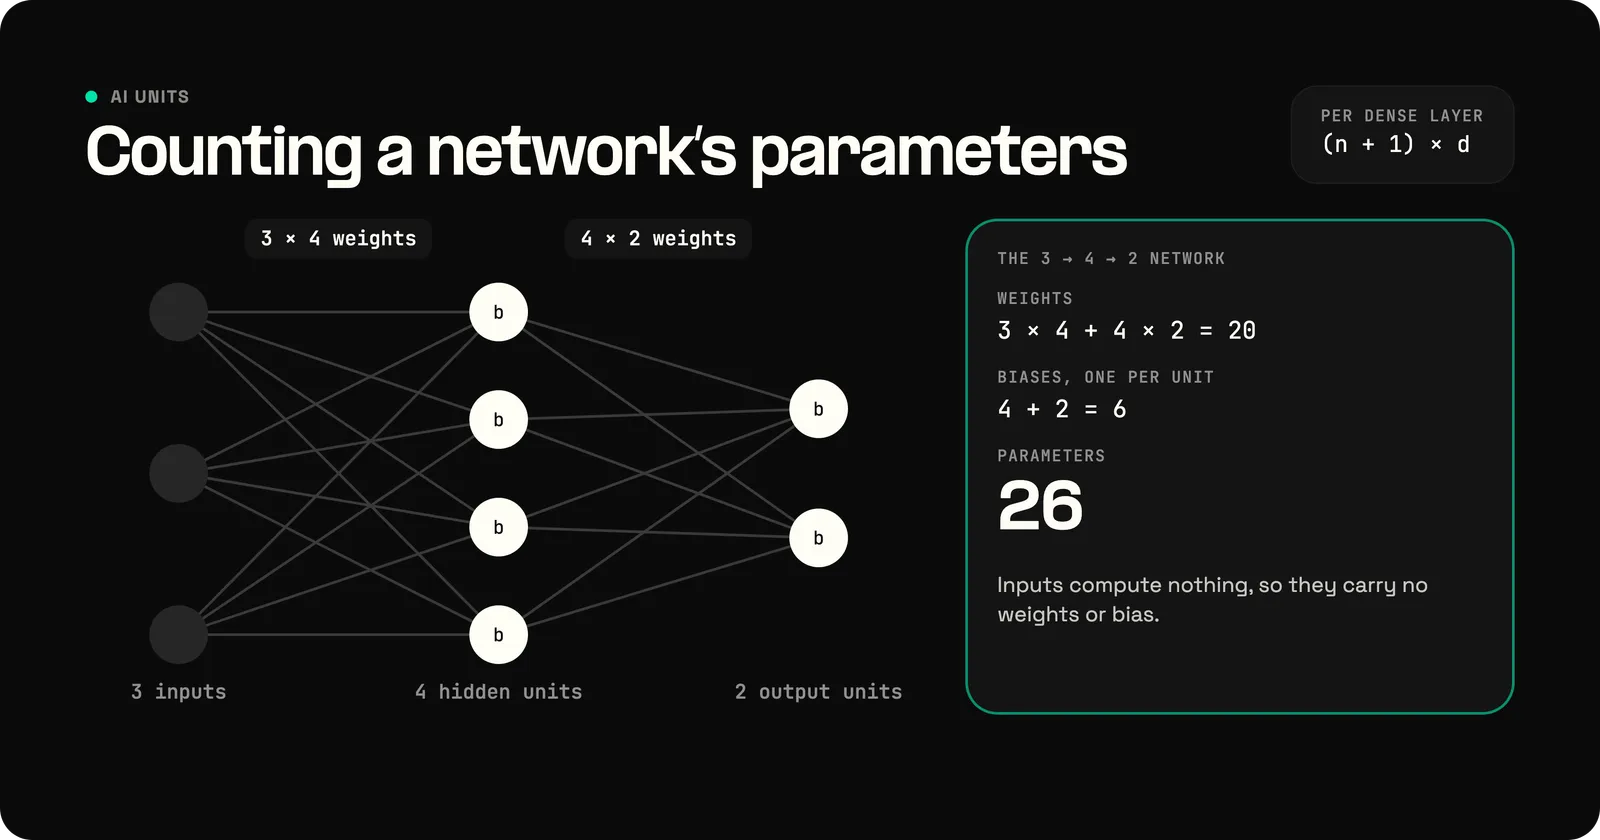
For a dense layer, the parameter count follows directly from the width. Each unit in a dense layer has one weight per input plus one bias, so a layer of d units reading n inputs has (n + 1) × d parameters. The 64-unit layer above holds (784 + 1) × 64 = 50,240. CS231n works the same count for a small network: 3 inputs, a hidden layer of 4 units, and 2 output units. That network has 3 × 4 + 4 × 2 = 20 weights plus 4 + 2 = 6 biases, 26 parameters in all.
Parameter count is where width turns into cost. Every unit's weights and bias have to sit in memory whenever the model runs inference, and they are the files a lab publishes when it releases an open-weight model. At 4 bytes per 32-bit number, the 64-unit layer's 50,240 parameters take about 200 KB. At 2 bytes per 16-bit number, GPT-3's 175 billion parameters take about 350 GB. They are spread across 96 layers, each of which widens from 12,288 units to 49,152 inside its feed-forward sublayer, the four-to-one ratio the paper states.
Choosing a hidden width is a trade between underfitting and overfitting. With too few units, the network underfits: it cannot capture the pattern even on its training data. With too many, it can overfit, memorizing the training set instead of learning the pattern. Statistics calls these high bias and high variance, a different sense of bias from a unit's b term, and the bias-variance tradeoff is the balance between them.
A value like 64 in a tutorial is a starting guess, not a derived number, and a simple loop turns it into a choice. Train at that width and check validation loss, the model's error on the held-out examples, then double the width while validation loss keeps falling. When training loss keeps dropping but validation loss stops improving, the network has started to memorize. At that point, hold the width and add regularization such as dropout, which randomly drops units, along with their connections, during training.
Holding the width instead of cutting it back follows CS231n's advice. Its reason is that small networks are harder to train well. Gradient descent, the optimizer that follows the gradients backpropagation computes, tends to settle on poor solutions with high loss in a small network and on better ones in a larger network. Regularization is the better tool against overfitting than removing units.
Besides the neural network unit, "AI units" names a prepaid billing credit in enterprise software and processor hardware built to run AI, and it loosely names a component of an AI system.
As a billing credit, an AI unit is a prepaid allowance that a software platform's AI features draw down as they run. Depending on the vendor, usage is counted per request, per record, or per page processed. Each vendor sets its own conversion, so an AI unit on one platform says nothing about an AI unit on another, and none of them measures anything inside a model.
As hardware, "unit" is the standard word for a processor: central, graphics, tensor, and neural processing units. The neural processing unit, or NPU, is a low-power chip that runs models on phones and laptops, one of several kinds of AI hardware built for neural networks. These chips compute neural network units; they are units only in the hardware sense. Most of a unit's work is multiplying and adding, and the matrix multiply unit at the core of a TPU exists to do thousands of those operations every clock cycle.
Loosely, writers also call a large component of an AI system a unit or an AI module, such as the perception or planning module of a self-driving car. An AI module in that sense is software built from many networks and rules, not a unit in the technical sense.
Which unit type carries the work in an application depends on its data and on the neural network architecture built for it. Images get convolutional units, text gets attention heads and feed-forward units, and audio gets recurrent or transformer layers.
In computer vision, convolutional units detect patterns in small patches of an image. A unit in the second layer sees a patch of the first layer's outputs, and each of those saw its own patch of the image. Each layer's units therefore cover a wider area of the image than the layer before, as Deep Learning illustrates. That wider view lets deep units respond to whole objects, like the trees in the Bau study.
Language models are built from transformer layers, in which attention heads move information between positions in a sequence and feed-forward units transform each position's representation.
Speech models need context across time, and both recurrent and transformer layers supply it. In the Tacotron 2 speech synthesizer, recurrent units carry context from step to step as a sequence-to-sequence network predicts audio features from text. The Whisper speech recognizer uses a transformer instead, with an encoder that reads the audio and a decoder that writes the text, so attention heads can relate every part of an utterance to every other part.
Whatever the architecture, its units still do what the perceptron's did in 1958: weigh their inputs, add a bias, and apply an activation to set the output.
An AI unit is a neural network unit in machine learning, a prepaid billing credit in enterprise software, or, in chip names, a processor built to run AI. In machine learning, a unit is an artificial neuron, the basic building block of a neural network. As a billing credit, an AI unit is prepaid usage that a platform's AI features consume as they run, priced and converted differently by each vendor.
The basic unit of a neural network is called a unit, a neuron, or a node, and the names are interchangeable. It is the network's basic computational unit: it receives inputs, weights them, adds a bias, and applies an activation function such as ReLU, sigmoid, or tanh. The perceptron is one specific early unit that uses an on-off threshold instead.
A perceptron is one specific kind of artificial neuron, although the word is often used loosely for any unit. The units in Rosenblatt's 1958 perceptron output all or nothing, 1 or 0, by comparing their summed input with a threshold. A neuron in a modern network uses a graded activation such as ReLU, so its output can take many values. That gives backpropagation a useful gradient to follow, which a hard threshold does not.
The three main parts of a neural network are the input layer, one or more hidden layers, and the output layer, each made of units. The input layer holds the raw features, the hidden layers learn intermediate features, and the output layer turns them into a prediction. The weights and biases on the connections between units are what training learns.
OpenAI's launch post does not give ChatGPT's layer count; it says only that ChatGPT was fine-tuned from a model in the GPT-3.5 series. The nearest published figures are GPT-3's: 96 layers with a main width of 12,288 units. Either way, ChatGPT is a neural network: a large language model built, like GPT-3, from layers of units.