Bayesian machine learning uses Bayes' theorem to treat model parameters as distributions, so predictions carry uncertainty. Concepts, methods, and models.

Updated September 2026
Most machine learning models give you a single answer without a confidence score. Bayesian machine learning is different: it treats what a model learns as a probability distribution, so every prediction carries a measure of confidence. It does this with one rule, Bayes' theorem, updating its beliefs as new data arrives.
Quick answer: Bayesian machine learning is an approach to machine learning that uses Bayes' theorem to update the probability of a model's parameters as new data arrives. Unlike frequentist methods, which treat parameters as fixed values estimated from data, Bayesian ML treats them as random variables with probability distributions, so its output is a distribution rather than a single point estimate. That distribution is what lets the model express uncertainty. It rests on three quantities: a prior, a likelihood, and a posterior.
Bayesian machine learning applies Bayes' theorem to learning. It starts with a prior belief about a model's parameters, updates that belief with observed data, and produces a posterior, the revised belief. Where a traditional model estimates one best value for each parameter, a Bayesian model keeps a whole distribution over possible values and narrows it as more data arrives.
That distinction is the heart of the approach. Frequentist methods treat parameters as fixed unknowns and estimate a single value, usually by maximum likelihood. Bayesian methods treat parameters as random variables with distributions, so the model does not just predict, it also reports how confident it is. That is why Bayesian methods are valued where uncertainty carries a cost, such as medical diagnosis, or where data is scarce and a single best guess would be overconfident.
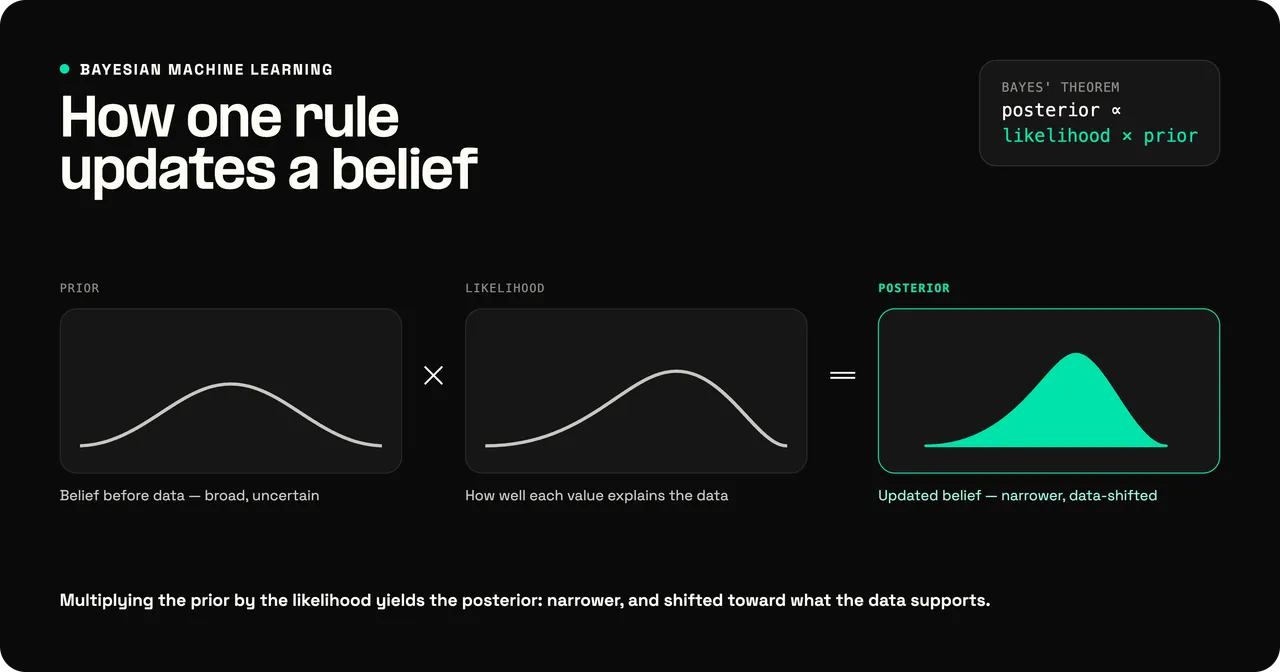
Bayesian machine learning runs on three quantities tied together by Bayes' theorem. The prior is what you believe about the parameters before seeing data. The likelihood is how probable the observed data is under a given set of parameters. The posterior is the updated belief after combining the two, and it is what the model actually uses.
Bayes' theorem is the rule that connects them: the posterior is proportional to the likelihood times the prior. In words, your updated belief is your starting belief adjusted by how well each possibility explains the data you saw. As more data arrives, the likelihood does more of the work and the choice of prior matters less, which is why Bayesian models can start from a rough prior and still converge on a good answer.
A simple example makes it concrete. To judge whether a coin is fair, you start with a prior, say a mild belief that it is, then flip it and record the results as the likelihood. Each flip updates the posterior: a long run of heads shifts it toward "biased," and the more flips you see, the sharper and more data-driven that belief becomes. The same loop scales from a coin to the millions of parameters in a real model.
The central challenge in Bayesian machine learning is computing the posterior, which is often too complex to solve exactly, so the methods differ mainly in how they handle it. The two anchors are a point estimate and a full distribution.
Maximum a posteriori (MAP) estimation takes the single most probable set of parameters under the posterior, the peak of the distribution. It is the Bayesian cousin of maximum likelihood, with the prior added, and it gives one answer rather than a distribution. Full Bayesian inference keeps the entire posterior and averages predictions over it, which captures uncertainty but is far more expensive.
In a few lucky cases the math works out cleanly: when the prior and likelihood are a matched, or conjugate, pair, the posterior has a closed form and needs no approximation. Most real models are not so tidy, so the posterior has to be approximated.
When it cannot be computed directly, two families of approximation do the work. Markov chain Monte Carlo (MCMC) draws samples from the posterior to approximate it, accurate but slow. Variational inference fits a simpler distribution to the posterior and is faster but approximate. The choice is the usual tradeoff between accuracy and compute.
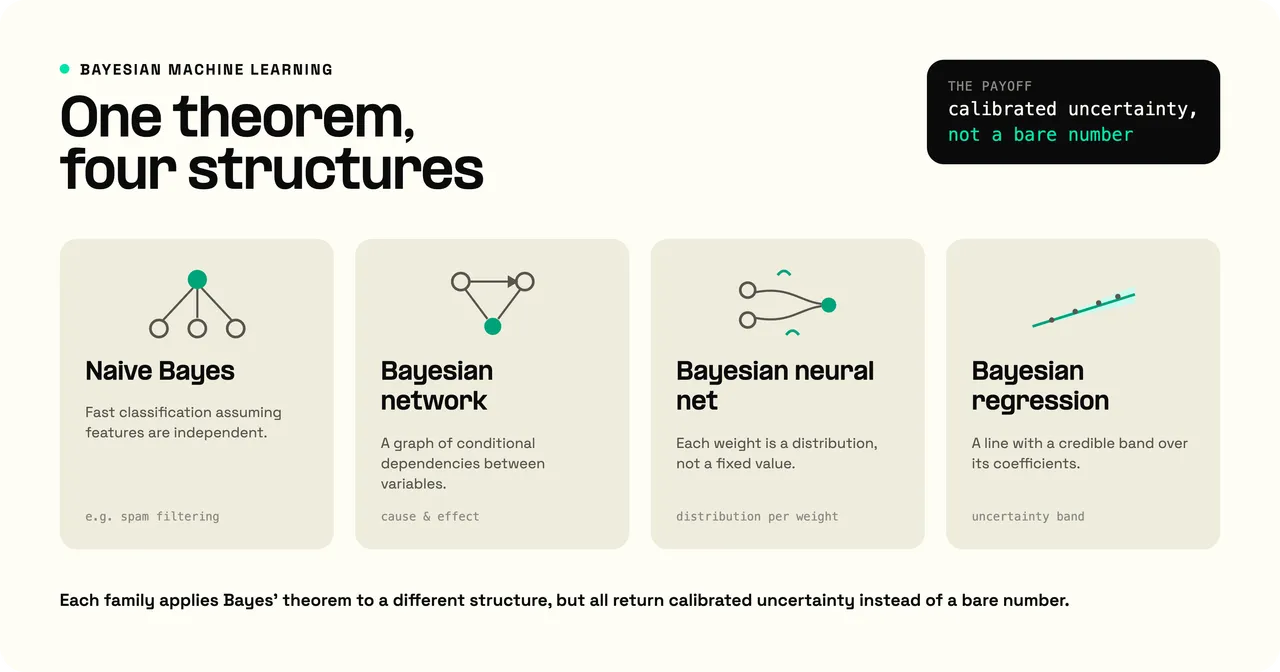
Several model families put these ideas to work, and they differ in how they represent the relationships between variables. Each applies Bayes' theorem to a different structure.
Naive Bayes is a simple, fast classification model that applies Bayes' theorem while assuming the input features are independent. The assumption is rarely true, but the model works surprisingly well for tasks like spam filtering. A Bayesian network is a graph whose nodes are variables and whose edges encode conditional dependencies, used to reason about cause and effect under uncertainty.
A Bayesian neural network replaces each fixed weight in a neural network with a probability distribution, so the network produces a range of outputs that reflects its uncertainty rather than one deterministic answer. Bayesian linear regression does the same for the coefficients of a linear model. In every case the payoff is the same: predictions that come with calibrated uncertainty instead of a bare number.
Bayesian machine learning is used wherever knowing the model's confidence matters as much as its prediction. Its clearest strength is uncertainty quantification: because the output is a distribution, the model can flag when it is unsure, which is valuable in medicine, finance, and autonomous systems where a confident wrong answer is dangerous. It also shines on small datasets, where a prior supplies structure that the data alone cannot.
The same machinery drives model selection and hyperparameter tuning. Bayesian optimization treats an unknown performance surface as something to learn probabilistically, and it finds good hyperparameters in fewer trials than a grid search. Bayesian ideas also appear in generative AI, where reasoning about distributions over data is the whole game.
Uncertainty also makes Bayesian methods a fit for active learning, where a model uses its own confidence to choose which examples are most worth labeling next. It suits A/B testing too, where a Bayesian approach estimates not just which variant is better but the probability that it is. Both turn the model's uncertainty into a decision rather than treating it as noise.
The main cost is exactly that: computing or approximating a posterior is expensive, and full Bayesian inference does not scale as easily as training a single point-estimate model. Choosing a prior also introduces a modeling decision that can sway results on small data. For many production systems the practical answer is a hybrid, using Bayesian methods where uncertainty is worth the compute and simpler estimates elsewhere.
ChatGPT is not Bayesian in the strict sense. The large language model behind it learns a single fixed set of weights through maximum likelihood and gradient descent, not a probability distribution over its parameters, so it is not a Bayesian model. There is active research on Bayesian deep learning that treats a network's weights as distributions, but mainstream LLMs are not built that way.
The difference is how each treats a model's parameters. Frequentist methods treat parameters as fixed unknowns and estimate a single best value from the data. Bayesian methods treat parameters as random variables with probability distributions, start from a prior, and update it into a posterior as data arrives, which is what lets a Bayesian model express uncertainty.
The main disadvantage is computational cost: the posterior is often intractable, and approximating it with methods like MCMC is slow and does not scale as easily as training a single point-estimate model. Bayesian methods also require choosing a prior, which adds a modeling decision that can influence results when data is limited.
They are related but not identical. "Bayes" refers to Bayes' theorem, the underlying rule of probability, named after Thomas Bayes. "Bayesian" describes any method, model, or interpretation built on that rule, such as Bayesian machine learning or Bayesian statistics.
Yes, in specific places. Bayesian inference underpins models like Naive Bayes classifiers and Bayesian networks, powers Bayesian optimization for tuning, and provides the uncertainty estimates used in safety-critical systems. Most large deep learning models are not fully Bayesian, but Bayesian methods remain a core tool where calibrated confidence is required.
This content was generated with the assistance of AI. Our AI prompt chain workflow is carefully grounded and preferences .gov and .edu citations when available. All content is reviewed by a Telnyx employee to ensure accuracy, relevance, and a high standard of quality.