Concatenative synthesis joins recorded units of sound into new speech or music. How unit selection works, its types, and how it compares with neural TTS.

Updated September 2026
Concatenative synthesis is a sound synthesis technique that divides recorded sounds into smaller units and reassembles them to form new sounds. Concatenative means joined end to end, and the method, also called concatenation synthesis, is unrelated to concatenative programming languages. Each unit comes from a database of recordings called a corpus. The system chooses the units that best match a target: a line of text in speech, or a sound or musical phrase in music.
Matching a target with real recordings made concatenative synthesis the most natural-sounding form of text-to-speech (TTS) for years. The Google team behind Tacotron 2 calls unit selection, the large-database form of the method, the state of the art "for many years." It also notes that Google used concatenative voices in production. Amazon Polly's standard voices still use concatenative synthesis. The method's limit comes from the same source: a concatenative system can only rearrange sounds that someone has already recorded.
Concatenative synthesis works in four steps: record a corpus and cut it into units, describe every unit, select the sequence of units that best matches the target, and join them with the seams smoothed. The full version of those steps is unit selection, which weighs many candidate recordings for every sound; simpler systems store one recording per unit and skip most of the search.
Unit size depends on the application. Speech units range from whole words and phrases down to diphones, the transition from one sound to the next, and to phonemes, the individual sounds of a language. Hunt and Black's 1996 system used phonemes, and Apple's 2017 Siri voices used half-phones, units half a phoneme long. Music systems use anything from a short window of signal to an instrument note or a whole phrase, according to Schwarz's survey of the field.
Each unit is then described in the same terms as the target, so the two can be compared. In Hunt and Black's system, those terms are the phoneme, its phonetic context, and its prosody: pitch, duration, and power (loudness). Music systems describe units with descriptors measured from the audio itself; in CataRT, they include pitch, loudness, and spectral centroid, a measure of brightness.
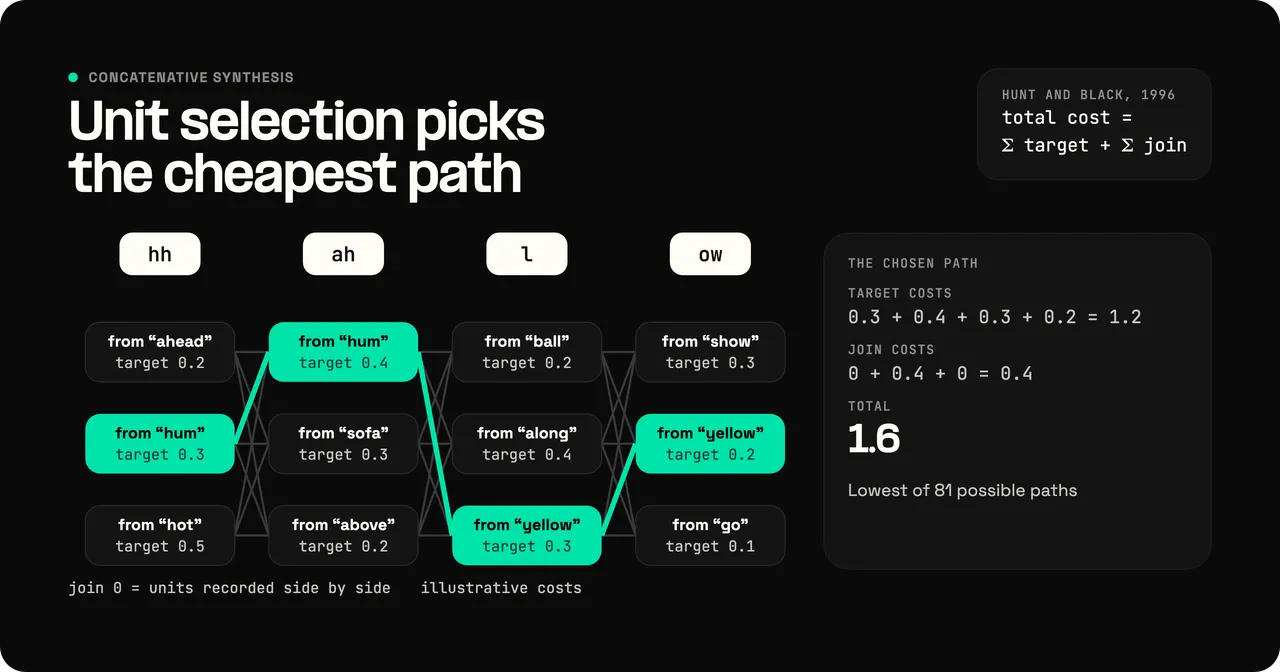
With every unit described, selection is where concatenative synthesis earns its quality. The system scores candidate units with two costs:
Hunt and Black add both costs along every possible sequence of units and pick the cheapest. They find it with a Viterbi search, a dynamic-programming method that finds the lowest-cost path without testing every combination. Two units that sat next to each other in the original recording join at zero cost, so the search favors runs of units that were recorded together.
Even Viterbi compares every candidate for one sound with every candidate for the next, and a large database holds many candidates per sound, so the search has to be pruned. On 1996 workstations, Hunt and Black kept only a beam of 10 to 20 candidates at each step. That ran near real time on a database of about 100,000 units, with little effect on quality.
Once the units are chosen, the last step joins them and fixes their prosody. PSOLA, pitch-synchronous overlap-add, does both: it concatenates the waveforms and modifies their pitch and timing by overlapping and adding short pieces aligned to the pitch periods of the voice. Every adjustment costs some naturalness. That is why Hunt and Black put prosody into the selection step: a unit that already has the right pitch and duration needs less processing. The better the selection, the less smoothing the output needs.
Concatenative speech synthesis, or concatenative TTS, is text-to-speech that selects and joins units of recorded human speech. It converts text into a target: the string of sounds to say, with a pitch and duration for each. Then it runs selection and smoothing against a corpus recorded by one speaker.
Building that target is the job of the front end, which works the same way in every kind of TTS. The system normalizes the text, expanding abbreviations and numbers into words, converts the words to phonemes, and predicts the prosody of each phrase, as Telnyx's TTS guide describes.
After the front end, concatenative TTS systems split into three types, which differ in how much speech they store and how much choice the search has: limited-domain synthesis, diphone synthesis, and unit selection synthesis.
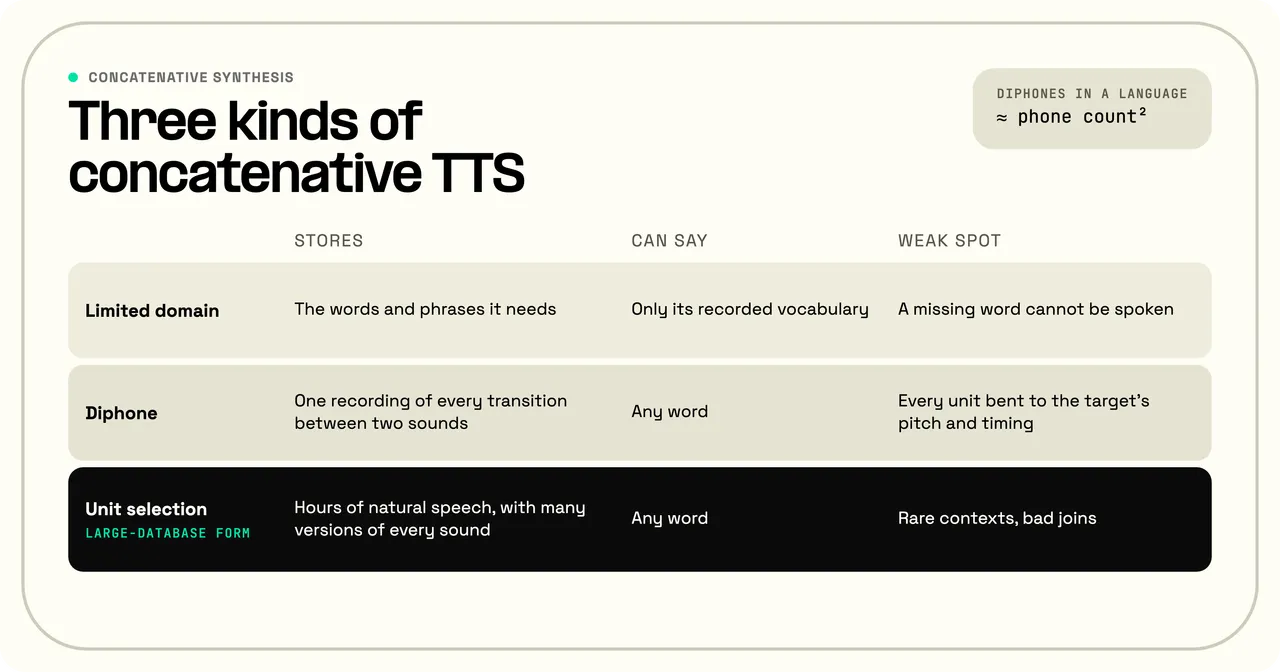
Limited-domain synthesis records the words and phrases an application needs and joins them. Inside that vocabulary, Black and Lenzo found, it reliably gives very high quality; outside it, it gives nothing. Their voice-building guide names telling the time and reading telephone numbers as typical uses, both small and closed vocabularies. A word missing from the recordings cannot be spoken.
Phone systems still build prompts this way. A bank line that plays a recorded "Your balance is" followed by recorded numbers joins whole-word units. On Telnyx's programmable Voice API, consecutive play-audio commands queue in order, so an application can chain recorded prompt files into one message.
Anything outside the recordings needs a fallback. Phone menus switch to text-to-speech for dynamic parts such as a caller's name, as Telnyx's guide to call menus describes. Black and Lenzo's own voice-building tools fall back to a diphone voice.
A diphone voice can say any word, because diphone synthesis stores one recording of every transition between two sounds in a language. Transitions matter because each sound changes shape with its neighbors, so a phoneme recorded in one word does not fit cleanly next to an arbitrary other one. A diphone keeps the change from one sound to the next as a speaker actually produced it. Stanford's Julius O. Smith put the problem plainly: "juxtaposing phonemes made for brittle speech." Recording every pair rests on a working assumption that each sound is shaped only by its immediate neighbors. Black and Lenzo's Festvox guide puts the number of diphones in a language at roughly the square of its phone count, less the pairs the language never uses.
With only one example of each diphone, the system has to bend every unit to the target's pitch and timing. PSOLA does the bending, and Moulines and Charpentier published it in 1990 for exactly this job: text-to-speech built from diphones. The result is compact, but Black and Lenzo use a diphone voice only as a fallback, one they say always sounds worse than unit selection.
Unit selection synthesis usually sounds better than diphone synthesis because it keeps many versions of every sound, recorded over hours of natural speech. The search can then pick the version that already fits, and like a diphone voice, a unit selection voice can say any word. Black and Campbell framed the shift in 1995. Most systems then stored one instance of each unit type, typically a diphone. Large databases of natural speech held many instances of each unit and raised a new problem: choosing between them. Hunt and Black's 1996 cost-and-search method became the answer, and Schwarz's survey calls it the standard path search in speech synthesis.
Hunt and Black's method also explains why unit selection can use units as small as a phoneme without the brittleness Smith describes. Each phoneme is recorded many times in different contexts, the target cost checks that context, and zero-cost joins favor units that were recorded side by side.
Recording more of each sound also means less bending. In Campbell and Black's chapter on prosody and unit selection, more recordings make it likelier that a unit already has the right prosody and needs little modification. Scale followed. Hunt and Black's test databases ran from 10 to 150 minutes, while Apple recorded 10 to 20 hours of speech for each Siri voice in iOS 10 and 11. Each voice was cut into roughly 1 to 2 million half-phone units.
Siri's voices from that period also show unit selection absorbing deep learning. Apple calls them hybrid: they use a statistical model to decide which units to select. A deep neural network predicts the acoustic features the target should have (spectrum, pitch, and duration) along with the concatenation cost, and the target cost compares each candidate with that prediction. A conventional Viterbi search then picks the path, as in Hunt and Black's system.
Outside Apple, Festival, the University of Edinburgh's open-source speech synthesis system, ships both approaches, so a developer can run a diphone voice and a unit selection voice side by side. Its project page lists diphone voices alongside two unit selection engines, Multisyn and Clunits, which groups the recordings of each sound into clusters by context before the search.
In music and sound design, concatenative synthesis borrows unit selection from speech to rebuild a target sound, such as a live instrument or a beatboxed rhythm, out of units cut from other recordings. Concatenative sound design goes by two other names, audio mosaicing and musaicing, after the image mosaics it resembles.
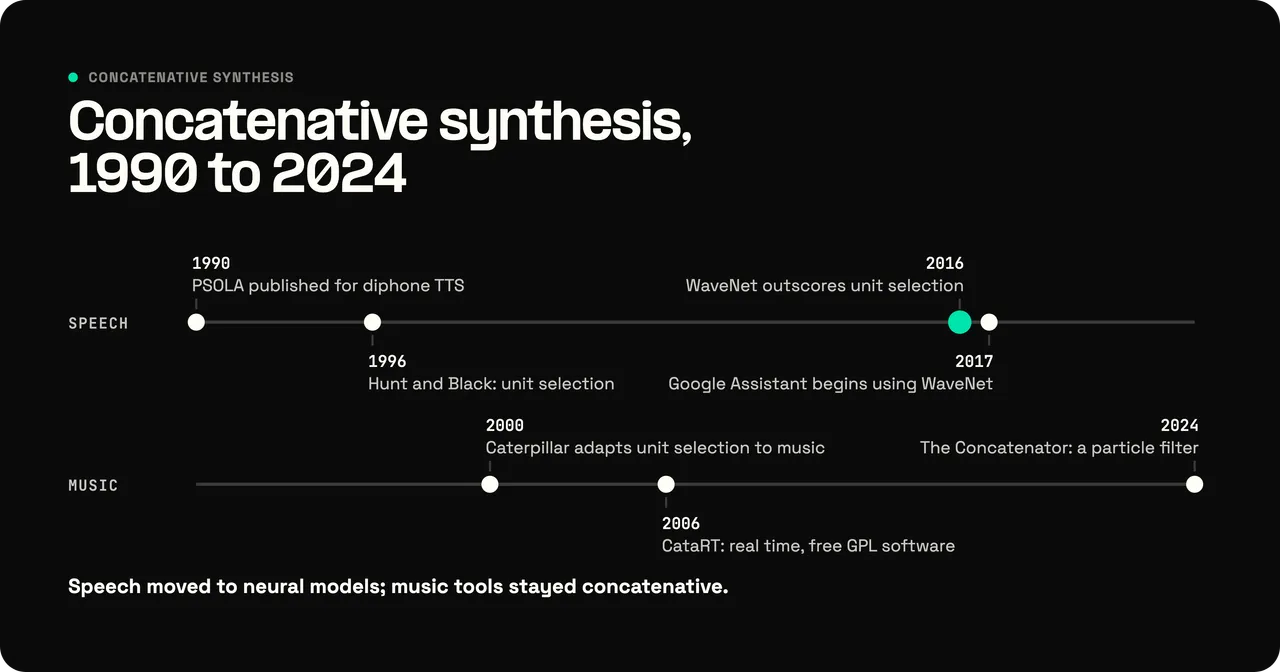
Diemo Schwarz adapted the speech method to music in 2000 with a system called Caterpillar, which kept its target cost, concatenation cost, and Viterbi search. His 2006 survey dates this as the first adaptation of speech unit selection to music. In 2001, Zils and Pachet introduced musical mosaicing. It turns properties a composer asks for, or the measured features of a target song, into rules that the chosen samples' descriptors must satisfy, then searches for a sequence that meets them. The system scaled to databases of more than 100,000 samples.
Where musical mosaicing reworked the speech method, singing synthesis took it almost unchanged. Yamaha's VOCALOID, as its developers described it in 2007, stores mostly diphones recorded from a real singer. It selects the ones a score needs and joins them, then converts their pitch and smooths their timbre around each junction.
Real-time tools changed the method's shape: a live performance reveals its target only as it is played, so a real-time system cannot find the globally best sequence the way offline speech synthesis can. Schwarz and colleagues spell out that trade-off in their 2006 paper on CataRT, free GPL software for Max/MSP, a visual programming environment for music. It lays a corpus out on a two-dimensional map of descriptors and plays the units nearest a point the performer moves.
The newest real-time approach treats selection as inference. In their 2024 paper The Concatenator, Tralie and Cantil use a particle filter, a method that keeps many running guesses about where in the corpus the best match lies and updates them as the audio arrives. Because it tracks a fixed number of guesses, the computing cost does not grow with the size of the corpus. On a 60-minute corpus, their method runs nearly 30 times faster than Let it Bee, a 2015 method that mixes pieces of the source recording until their spectrogram resembles the target's. Let it Bee is also the basis of the tool Rob Clouth used to build percussion from his own voice on a track of his 2020 album Zero Point. DataMind Audio, Cantil's company, built its Concatenator plugin on the paper's ideas.
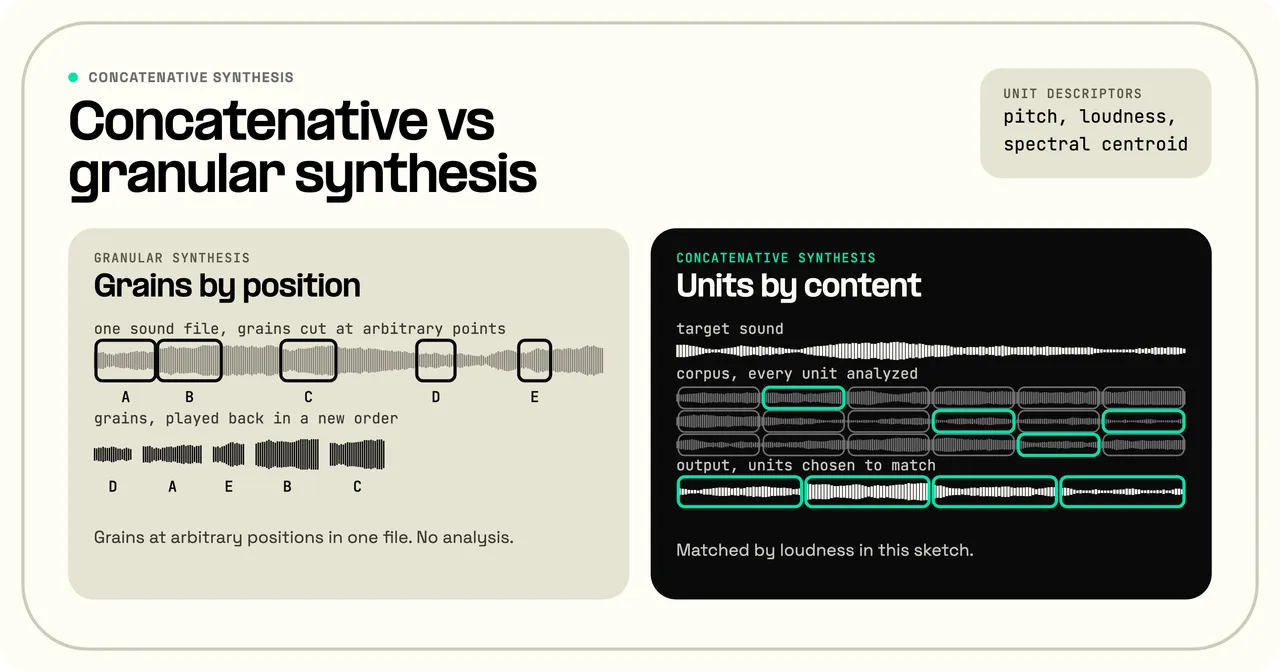
Concatenative synthesis differs from granular synthesis in how it picks each grain: by what the grain sounds like, not by where it sits in a file. Granular synthesis, in the CataRT paper's description, takes short snippets called grains out of one sound file at an arbitrary rate and plays them back, with their position and length controlled by hand. A mosaicing tool analyzes every unit first and selects by content, which is why the CataRT authors call their system a content-based extension of granular synthesis.
Choosing real recordings by how they sound gives concatenative synthesis its advantages: natural output, a faithful copy of the recorded voice, and modest computing needs. Its disadvantages are large storage, costly recording, little control over style, and audible glitches when a join goes wrong.
On the advantage side, Apple's Siri team wrote in its Interspeech paper that unit selection "typically produces more natural-sounding speech" than statistical parametric synthesis, which generates speech from a statistical model instead of recordings. The condition is a database with enough high-quality audio. Because every unit is a real recording, the output keeps the speaker's timbre and accent. Selection and joining are also cheap to run. Hunt and Black reached near real time on 1996 workstations, while WaveNet needed a 1,000-fold speedup before it could voice the Google Assistant in 2017, per DeepMind.
The disadvantages follow from storing recordings instead of a model:
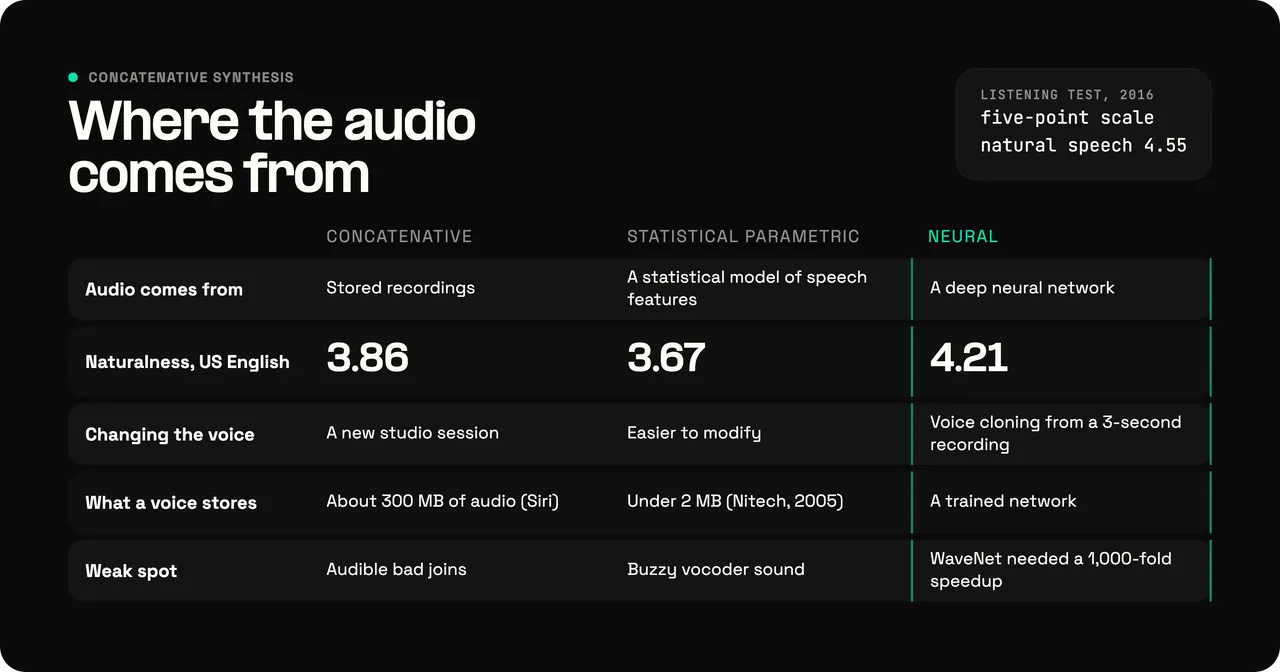
Concatenative, statistical parametric, and neural TTS differ in where the audio comes from. Concatenative TTS copies it from stored recordings, parametric TTS generates it from a statistical model of speech features, and neural TTS generates it with a deep neural network trained on recorded speech.
Parametric synthesis was the first challenger. Black, Zen, and Tokuda describe it as generating "the average of some set of similarly sounding speech segments." Hidden Markov models (HMMs) predict spectral and pitch parameters for each moment of speech, and a vocoder, a signal model of the voice, turns those parameters into a waveform. The vocoder drives a filter with a simple pulse or noise signal instead of real recorded speech, so the voices were easier to modify but tended to sound buzzy. The same authors wrote in 2007 that even parametric's supporters rated the best unit selection above the best parametric speech.
Neural TTS overtook both. In the 2016 WaveNet paper, listeners rated US English samples for naturalness on a five-point scale. A parametric system scored 3.67, a unit selection system 3.86, WaveNet 4.21, and natural speech 4.55. In US English, WaveNet halved the gap between the best older system and human speech. In Mandarin the two older methods swapped places: unit selection scored 3.47, below parametric at 3.79, and WaveNet reached 4.08. The paper does not say why.
Tacotron 2 widened the lead in December 2017, scoring 4.53 against 4.17 for Google's concatenative baseline and 4.58 for recorded speech, on that paper's own test set. By then Google had begun using WaveNet to generate Google Assistant voices in US English and Japanese, per DeepMind's October 2017 announcement.
Neural TTS has changed shape since. Early systems split the job between an acoustic model, which predicts a spectrogram, and a vocoder, which turns it into audio. Newer ones generate speech end to end, as Telnyx's guide to TTS architectures traces. None of them copies audio from stored fragments, which is the line that separates neural TTS from concatenative synthesis.
Concatenative synthesis is still used where a fixed vocabulary, low computing cost, or an exact recorded voice matters more than flexibility. Amazon Polly still offers a standard engine that Amazon says uses concatenative synthesis, next to its neural, generative, and long-form engines, all three built on deep learning. Phone systems splice recorded prompts, the limited-domain case. In music, current tools such as CataRT and the Concatenator plugin are concatenative by design. For speech, a concatenative voice fits fixed prompts, a voice that must match recordings already in use, or a tight budget per character. Open-ended speech is where neural voices earn their higher price.
Voice AI agents are a poor fit for concatenative synthesis. An agent speaks open-ended sentences that a language model writes during the call, and each needs prosody fitted to the conversation. Those are the conditions in which a unit database is most likely to run out of good matches. If you build voice AI agents, test the difference directly: render one agent reply with a concatenative voice and a neural voice, and listen to where the joins fall.
A talking clock is the classic example of concatenative synthesis: it joins recorded words such as "the time is," "four," and "fifteen" into a sentence nobody recorded whole. Black and Lenzo use it to walk through limited-domain synthesis. Larger examples are Siri's iOS 10 and 11 voices, built from 1 to 2 million half-phone units, and Yamaha's VOCALOID, which sings from diphones recorded by real singers.
The three types of speech synthesis, grouped by how the audio is produced, are concatenative, statistical parametric, and neural. Concatenative synthesis joins recordings, parametric synthesis generates speech from a model of acoustic features, and neural synthesis generates it with a deep neural network. Within concatenative synthesis, the three types are limited-domain synthesis, diphone synthesis, and unit selection synthesis.
Speech recognition converts spoken audio into text, and speech synthesis converts text into spoken audio. A recognition system uses an acoustic model to map sounds to phonetic units and words. Synthesis runs the other way: a concatenative system maps words to recorded sounds and joins them, while neural TTS predicts sound from text with a network trained on recorded speech. A voice application usually needs both: recognition to hear the caller and synthesis to answer.
Julius O. Smith's synthesis taxonomy sorts digital sound synthesis into four families. They are processed recordings, such as sampling and granular synthesis; spectral models, such as additive and subtractive synthesis; physical models, such as waveguides; and abstract algorithms, such as FM synthesis. Smith's 1991 taxonomy, written for computer music, does not list concatenative synthesis, but it belongs with the processed-recording methods, since it builds new sound out of recordings.
VOCALOID is concatenative synthesis applied to singing. Yamaha's engine, as its developers described it in 2007, reads a score, selects samples, mostly diphones, from a library recorded by a real singer, and concatenates them. It then converts each sample's pitch and smooths the timbre around each join, working in the frequency domain.
PSOLA, pitch-synchronous overlap-add, is a signal processing method that changes the prosody of recorded speech so concatenated units match the pitch and timing a sentence needs. Moulines and Charpentier published it in 1990 for diphone text-to-speech. The time-domain version, TD-PSOLA, is efficient enough for real-time synthesis, while the frequency-domain version, FD-PSOLA, allows more flexible changes to the spectrum.
You can compare concatenative and neural TTS on Telnyx by rendering the same text through two engines of one provider. Telnyx's TTS API supports AWS Polly with an engine setting of standard, neural, generative, or long-form, and Amazon states that Polly's standard voices use concatenative synthesis. The voice string names the engine, in the form aws.Polly.
This content was generated with the assistance of AI. Our AI prompt chain workflow is carefully grounded and preferences .gov and .edu citations when available. All content is reviewed by a Telnyx employee to ensure accuracy, relevance, and a high standard of quality.