Concept drift vs data drift in machine learning: data drift changes a model's inputs, concept drift changes what they mean. How to detect and fix each.

Updated September 2026
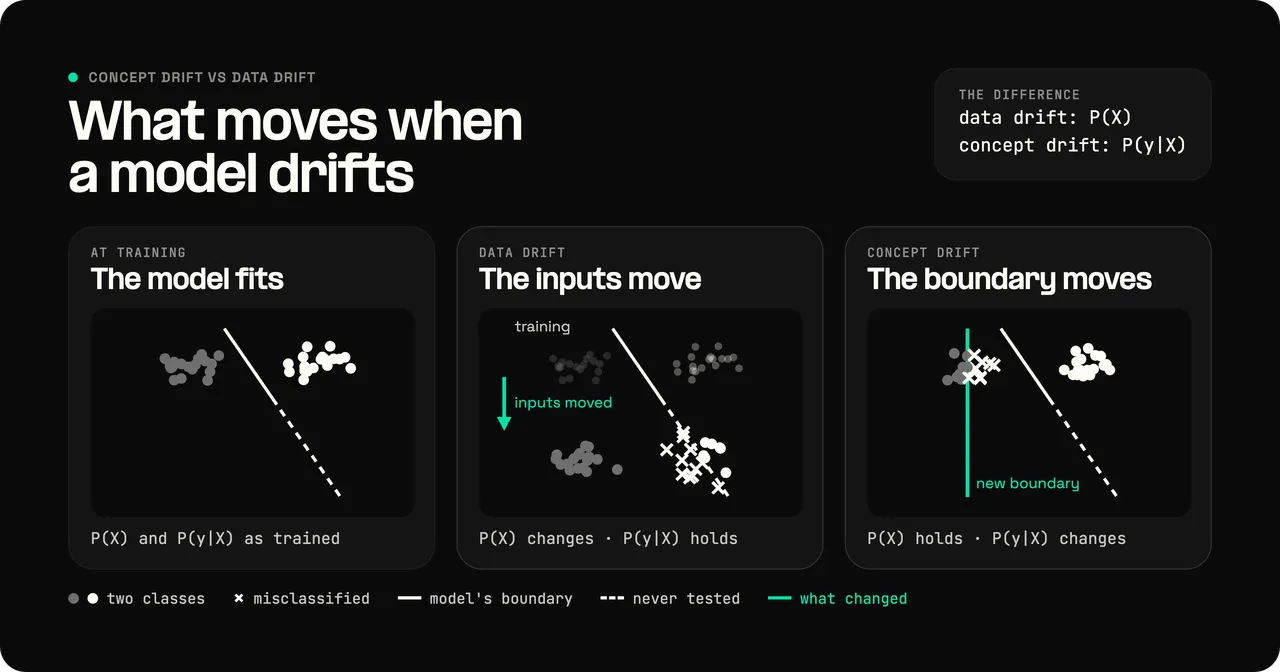
Data drift and concept drift are two of the main reasons a machine learning model loses accuracy after deployment. Data drift is a change in the distribution of the input data, written P(X), while the relationship between inputs and the target stays the same. Concept drift is a change in that relationship, P(y|X): the same inputs now call for a different output.
Neither data drift nor concept drift sets off an alarm. The model keeps running and returning answers, and nothing in its logs looks wrong, while the answers get less accurate. That is why Rabanser and colleagues describe machine learning systems as ones that "tend to fail silently." The two also surface in different places, data drift in the inputs and concept drift only in the outcomes, so each needs its own check.
This content was generated with the assistance of AI. Our AI prompt chain workflow is carefully grounded and preferences .gov and .edu citations when available. All content is reviewed by a Telnyx employee to ensure accuracy, relevance, and a high standard of quality.
Data drift means the inputs a model receives in production no longer look like the inputs it trained on. A speech recognition model trained on clean headset audio that starts receiving noisy speakerphone calls has data drift: the audio changed, but the words still map to the same transcript.
The statistical term for data drift is covariate shift. Lu and colleagues call it virtual drift, because the decision boundary, the real dividing line between one answer and another, does not move. Data drift degrades model accuracy anyway. A model only learns where that line runs in the regions its training data covered, so when inputs move into regions it rarely saw, the model guesses.
Data drift starts with anything that changes who or what feeds the model:
Concept drift means the correct output for a given input has changed. The inputs can look exactly like the training data while the right answer moves, usually because of something the model never sees, such as the economy or a fraud ring's playbook. Lu's review calls these hidden variables and names the result actual drift: a change in P(y|X) that moves the decision boundary itself.
Concept drift degrades model accuracy even when every input looks familiar.
Concept drift comes from changes in the world that alter what an input means:
Concept drift has four types: sudden, gradual, incremental, and recurring. Lu's review sorts them by how the new relationship between inputs and answers replaces the old one:
The key difference between data drift and concept drift is distribution versus relationship change. Data drift refers to changes in the distribution of the input data, but the relationship between the input features and the target variable remains the same. Concept drift refers to changes in the relationship between the input features and the target variable, even if the input distribution remains the same.
In probability terms, data drift changes P(X) and concept drift changes P(y|X), and the two often arrive together.
| Data drift | Concept drift | |
|---|---|---|
| What changes | The input distribution, P(X) | The input-output relationship, P(y given X) |
| Also called | Covariate shift, virtual drift | Actual drift, concept shift |
| Visible in the inputs | Yes | Not necessarily |
| Needs labels (true outcomes) to detect it | No | Usually |
| Typical triggers | New users, devices, seasons, pipeline changes | Economic shifts, adversaries, policy changes |
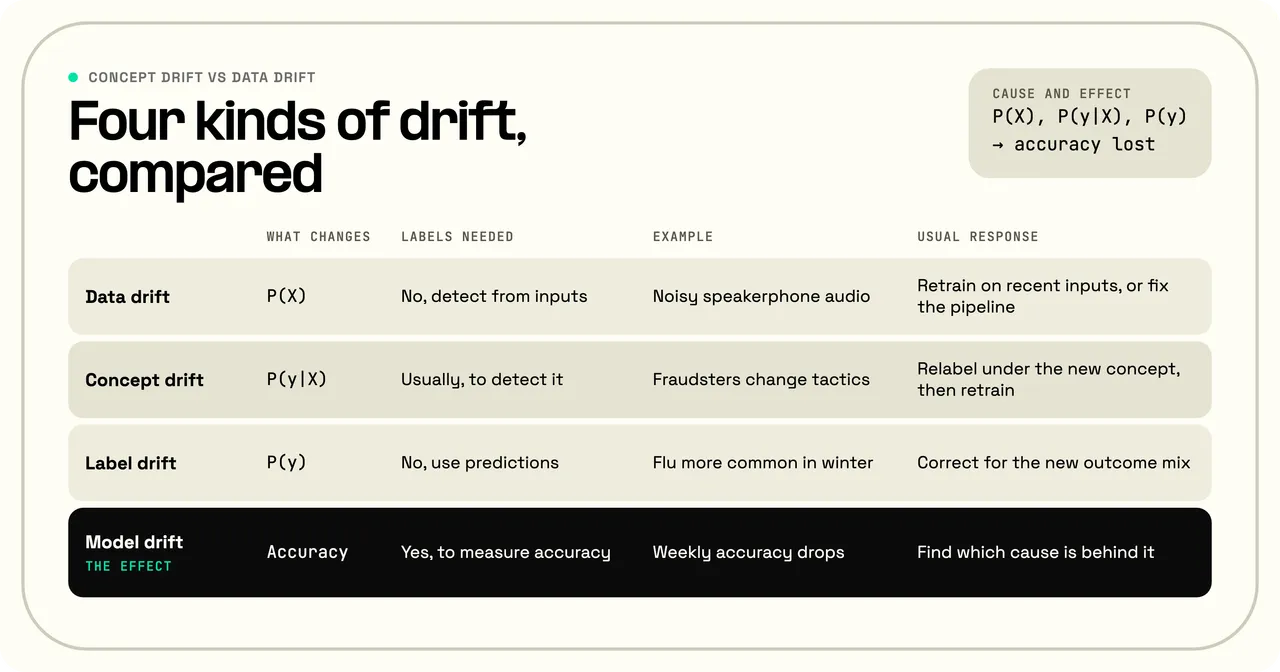
| Usual response | Retrain on recent inputs, or fix the pipeline | Relabel under the new concept, then retrain |
The cause does not reveal the type: economic changes such as a recession can shift who applies for loans (data drift) and who defaults (concept drift) at once. Concept drift usually costs more to fix, because labels collected under the old concept teach the old answer: it takes new labels, not just new inputs.
A common example of concept drift is fraud detection: once a model learns to flag a pattern, fraudsters shift to transactions that resemble approved ones, so the same features carry a different risk.
A common example of data drift, by contrast, is a medical imaging model moved to a new hospital. In the WILDS benchmark, a tumor classifier averaged 93.2% accuracy on tissue patches from the hospitals it trained on and 70.3% at a hospital it had never seen. Nearly one patch in three was misread. Tumor tissue still meant tumor; what changed was the slides, through differences in staining and image acquisition.
Some systems face both at once. Telnyx's guide to synthetic speech detection notes that new text-to-speech (TTS) models appear constantly, so a static detector starts drifting from day one. Each new voice generator changes both the audio a detector hears and the cues that mark a voice as synthetic.
In MLOps usage, model drift, also called model decay, is the decline in a model's performance in production. The difference between data drift, concept drift, and model drift is cause and effect: the first two are causes, and model drift is the accuracy lost. A third cause, label drift, changes how often each outcome occurs, such as flu becoming more common in winter while its symptoms stay the same.
Label drift can be corrected without new labels. Lipton and colleagues, who call it label shift, showed that the new outcome mix can be estimated from the model's own predictions and the model adjusted to match.
Detect data drift by running a two-sample statistical test on each input feature, comparing a recent window of production data with the training data. Detect concept drift by scoring the model's predictions against the real outcomes as they come in, and watching for accuracy to fall.
For a numeric feature, the standard choice is the two-sample Kolmogorov-Smirnov (KS) test, which compares the distributions of the two samples and reports how far apart they are. On thousands of rows it flags even tiny, harmless shifts as significant, so alert on how big the shift is.
For images and other inputs with thousands of dimensions, test the model's outputs instead of the raw inputs. In Rabanser and colleagues' image experiments, running the same tests on a classifier's output probabilities caught shift best, so the model you already run can double as its drift detector.
Input and output checks share a blind spot: under pure concept drift the inputs do not change, so neither do the model's outputs. The only signal left is accuracy, measured against the ground truth. Track accuracy or F1 score per time window. Error-rate detectors, the largest family in Lu's review, automate the watch: the Drift Detection Method (DDM), one of the most cited, raises a warning when the error rate rises significantly and signals drift if it keeps rising.
This Python sketch runs a simple version of both checks, a KS test on one feature and an accuracy threshold on weekly labeled traffic:
import numpy as np
from scipy.stats import ks_2samp

rng = np.random.default_rng(0)
train_x = rng.normal(50, 10, 5000)  # a feature at training time
prod_x = rng.normal(56, 10, 5000)   # the same feature in production

# Data drift: two-sample KS test on the inputs, no labels needed
result = ks_2samp(train_x, prod_x)
print(f"KS statistic {result.statistic:.3f}, p-value {result.pvalue:.1e}")

# Concept drift: weekly accuracy on labeled traffic (example values)
weekly_accuracy = [0.94, 0.93, 0.94, 0.88, 0.85]
baseline = weekly_accuracy[0]
drifted = [week for week, acc in enumerate(weekly_accuracy) if acc < baseline - 0.05]
print("Accuracy dropped in weeks:", drifted)
The two checks run on different clocks. A data drift check needs only the inputs, so it can run as soon as production data arrives. A concept drift check needs labels, the true outcome for each prediction, such as whether a flagged transaction really was fraud, and a fraud label may arrive only when a chargeback lands. Concept drift shows up only as fast as those labels come back, which is why it is slower to catch.
In an MLOps pipeline, both checks run on a schedule and alert when they fire. Telnyx's guide to model deployment makes that monitoring a step of the deployment process itself, with automated alerts that catch drift before it reaches users.
Lu's review groups the strategies for managing data drift and concept drift into three families: retrain on recent data, keep past models for patterns that return, and adapt the model as data arrives.
If data drift traces to a pipeline bug, fix the pipeline. Retraining on broken data teaches the model the bug.
Concept drift in a large language model is the growing gap between the world the model learned from and the world it answers questions about after its training cutoff. Lazaridou and colleagues found that language model performance "becomes increasingly worse with time" on text from beyond the training period, and that model size alone does not solve it. Grounding in AI narrows the gap at answer time by feeding a large language model current facts.
LLM applications also drift when the model itself changes. Chen, Zaharia, and Zou found that GPT-4's accuracy at identifying prime numbers fell from 84% in its March 2023 version to 51% in its June 2023 version. Pin model versions, and rerun your evaluations whenever a provider updates one.
Concept drift in machine learning refers to a change over time in the relationship between a model's input features and the target it predicts. A model trained on past data then gives outdated answers to inputs that look familiar.
Covariate shift is the research term for what practitioners usually call data drift: P(X) changes while P(y|X) stays fixed. Covariate shift differs from concept drift, which changes P(y|X) itself.
Data drift is a type of concept drift in much of the research literature, where many papers, Lu's review included, call any change in inputs or answers concept drift. In production monitoring, the two usually name separate problems: a change in the inputs, and a change in the right answer.
Retrain a model when a drift detector or a drop in labeled accuracy shows drift, with a fixed schedule as a backstop. A schedule alone can react weeks late to a sudden change.
Handle drift in a voice AI agent by analyzing conversations for new failure patterns and shipping fixes to a slice of calls first. With Telnyx Voice AI agents, AI Assistants run analysis on every conversation through Insights, split calls between versions by percentage for gradual rollouts, and roll back to the main version. New product names and caller accents are data drift; a new refund policy, which changes the right answer, is concept drift.