A counterfactual explanation shows the smallest change that would flip an AI decision. How they are computed, examples, tools, legal uses, and limits.
Updated September 2026
A counterfactual explanation is a statement of the smallest change to an input that would have changed an AI model's decision. It takes the form "if X had been different, the outcome would have been Y." For example, a declined loan applicant might learn that an income of $52,000 instead of $42,000 would have been approved.
In a 2017 paper, Wachter, Mittelstadt, and Russell argued that counterfactuals could explain automated decisions to the people they affect without disclosing the model's internals. Nobody has to follow the model's math. The counterfactual answers the question a declined applicant asks, which is what would have made the difference.
This content was generated with the assistance of AI. Our AI prompt chain workflow is carefully grounded and preferences .gov and .edu citations when available. All content is reviewed by a Telnyx employee to ensure accuracy, relevance, and a high standard of quality.
A counterfactual explanation contrasts two inputs: the factual, which the model actually saw, and the counterfactual, a nearby input the model would have used to decide differently. The difference between them is the explanation. It is local, because it explains one prediction rather than the whole model. It can also be model-agnostic, because finding one can take nothing more than sending inputs to the model and reading the outputs.
The running example on this page is one prediction from an illustrative loan model, a logistic regression that scores four features. They are annual income, debt-to-income ratio, years of credit history, and missed payments in the past two years. The model adds up evidence in log-odds of repayment, a scale it converts to a probability at the end. The log-odds start at −0.5 and move by +0.10 per $1,000 of income, −0.12 per point of debt-to-income, +0.25 per year of history, and −1.1 per missed payment. The model approves an application when the resulting probability of repayment is above 0.5.
One applicant earns $42,000, has a 38% debt-to-income ratio, 4 years of credit history, and one missed payment. That applicant scores 0.28, so the model declines. With an income of $52,000 and everything else unchanged, the same applicant scores 0.51 and is approved.
That contrast matches how people ask for explanations. In a survey of the social science of explanation, Tim Miller found that people rarely ask why an event happened in the abstract. They ask why it happened instead of something else, and they expect an answer that picks one or two causes. A counterfactual is contrastive and selective by construction: it names the alternative outcome and the few features that separate the applicant from it.
Counterfactual explanations are one family of explainable AI methods, and the word has two other meanings nearby. In causal inference, a counterfactual is the outcome a person would have had under a different treatment, a claim about the world. In psychology, counterfactual thinking is the everyday habit of imagining how events could have gone otherwise. A counterfactual explanation is narrower than both: a claim about what one model would output, which can be checked exactly.
A counterfactual explanation is found by search. An algorithm looks for the input closest to the original that the model scores on the other side of its decision threshold, then reports the features that changed. Methods differ in how they define "closest," which changes they allow, and whether they return one answer or several.
Wachter and colleagues framed the search as an optimization with two terms. The first measures how far the model's prediction for a candidate input is from the desired outcome. The second measures how far the candidate is from the original input. A weight on the first term is raised until the prediction reaches the target, so the search settles on the nearest input that gets the new decision. The whole objective is a loss function minimized over inputs, with the model left untouched.
The distance term they proposed adds up the change in each feature divided by that feature's median absolute deviation, a measure of how much the feature typically varies. Dividing by the spread puts dollars, percentage points, and years on one scale. Adding absolute values, rather than squares, favors changing few features at once.
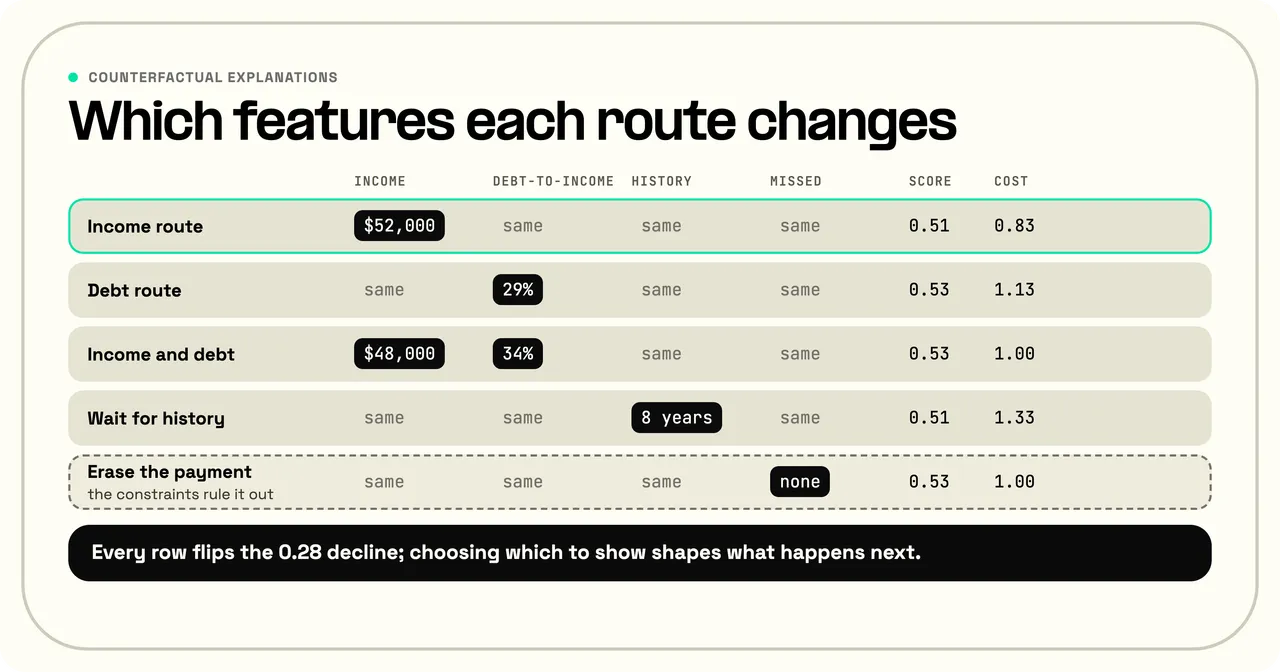
In the loan model's applicant pool, income typically varies by $12,000, the debt-to-income ratio by 8 points, credit history by 3 years, and missed payments by 1. Searching in steps of $1,000, one percentage point, and one year, the cheapest income route is $52,000, at a cost of 0.83. The cheapest debt route is a 29% ratio, at 1.13, because 30% leaves the score at exactly 0.50. Waiting until the credit history reaches 8 years costs 1.33. The search returns the income change.
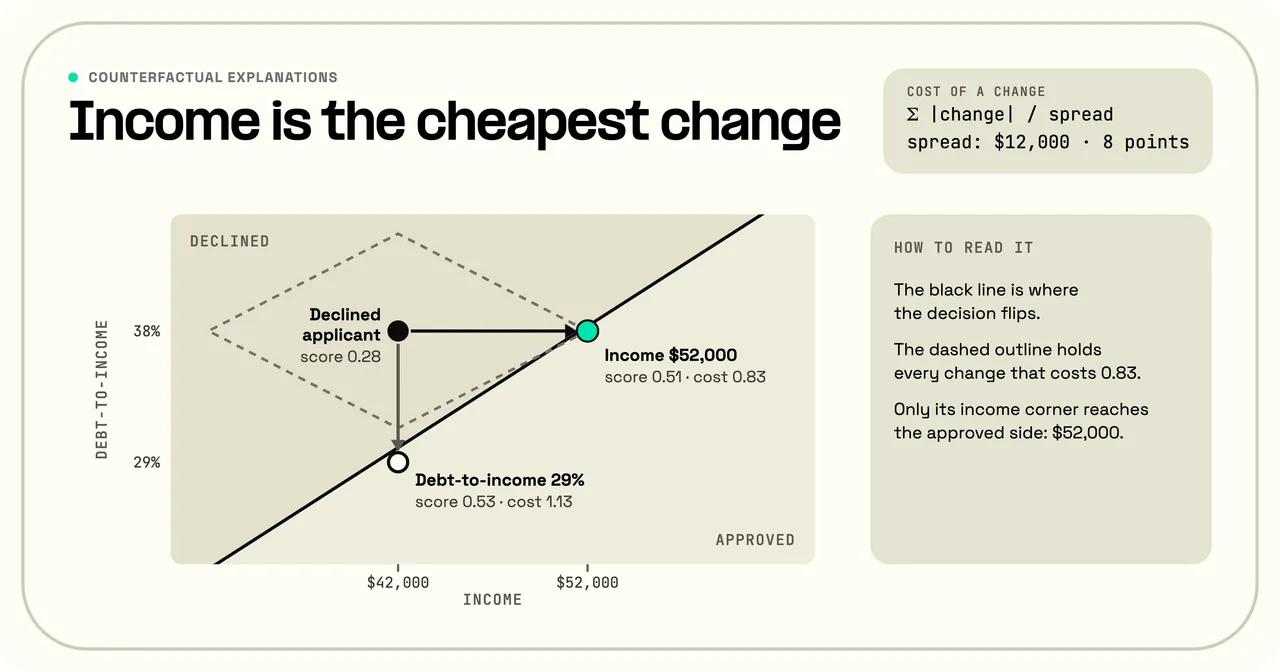
An unconstrained search will propose changes the person cannot make. In the loan model, the second-closest route after the income change comes from erasing the missed payment, which scores 0.53 at a distance of 1.00, ahead of the debt route at 1.13. But a payment already on the credit record cannot be unmissed. Practical methods therefore freeze features that cannot change, such as a past missed payment or the date an account was opened. They restrict others to one direction, since credit history only grows, and they cap how far any feature may move. Ustun, Spangher, and Liu call the result recourse: a change within the person's power that the model would reward.
A single counterfactual hides the other ways to reach the same decision, so later methods return a set. DiCE, from Mothilal, Sharma, and Tan, searches for several counterfactuals at once and rewards sets whose members differ from each other. The applicant then sees an income route and a debt route, not two versions of the same one. Dandl and colleagues trade off four goals at once: reaching the target prediction, staying close, changing few features, and staying plausible. They return the candidates that no other candidate beats on every goal at once.
The search strategy depends on what the model exposes. For models with gradients, such as neural networks and logistic regressions, the search follows those gradients with gradient descent, adjusting the candidate a step at a time. For tree ensembles and models behind an API, it uses random sampling or genetic search, which evolves a population of candidate inputs and only needs predictions. Either search can be pulled toward real data. The prototype approach of Van Looveren and Klaise steers candidates toward typical examples of the target class, which keeps the answer where the model's behavior was learned.
The main benefits of counterfactual explanations are transparency that a person can check, support for legal duties and fairness testing, and recourse: a concrete route to a different outcome.
Counterfactual explanations enhance the transparency of AI models by providing clear and concise reasons for their decisions. This transparency builds trust between users and the AI system, as it explains what changes are needed to achieve a desired outcome. Each counterfactual also marks a point on the model's decision boundary, the line in feature space where the decision changes. A set of them shows where that line runs near a given case. Unlike a description of a model's internals, which a reader has to take on faith, a counterfactual can be tested by rerunning the model.
Counterfactual explanations fit EU data protection law closely and US lending law indirectly. Under the EU's GDPR, Article 22 restricts decisions based solely on automated processing that have legal or similarly significant effects. Article 15 gives people a right to meaningful information about the logic involved. Wachter and colleagues set out three aims for explaining such a decision: helping the person understand it, giving grounds to contest it, and showing what would need to change. They argued that counterfactuals serve all three without explaining the system's internal logic.
The EU's Court of Justice read Article 15 in February 2025, in Dun & Bradstreet Austria, a case about an automated credit assessment. It ruled that the right of access covers "the procedure and principles actually applied." The Court added that a national court could find it sufficient to tell the person "the extent to which a variation in the personal data taken into account would have led to a different result." The Court named that as one form a sufficient explanation could take, and the form is a counterfactual.
Lending law in the United States asks for reasons rather than counterfactuals. A creditor that denies an application must send an adverse action notice with a statement of specific reasons that indicates the principal reasons for the denial. The duty comes from the Equal Credit Opportunity Act and Regulation B. In 2022 the Consumer Financial Protection Bureau said in a circular that the duty applies in full to decisions made with complex algorithms. It withdrew that circular in May 2025 along with dozens of other guidance documents, while the regulation's own wording, which makes no exception for complex models, stayed the same.
A counterfactual is not the notice itself, and the two answer different questions. Regulation B's principal reasons are closer to an attribution, which ranks what pushed the score down, while a counterfactual answers what would have changed the outcome. The regulation's official commentary says no factor that was a principal reason may be left off the notice, and the rule makes no exception for factors the applicant cannot change, such as a past missed payment. A counterfactual therefore can never rule a reason out. The natural pairing is attribution for the reasons on the notice, and counterfactuals for any guidance about what the applicant could change.
Fairness testing borrows the counterfactual question for a different purpose. Where a protected attribute is a model input, changing only that attribute and watching whether the decision flips shows directly whether the model responds to it, and a flip is a finding for bias mitigation work. In US consumer credit the attribute is usually absent, because Regulation B bars creditors from asking about an applicant's race, color, religion, national origin, or sex outside narrow exceptions. The same flip test then runs on suspected proxies for the attribute, such as a zip code, to see how much the score depends on them.
A counterfactual is phrased in the features a person already knows, such as income, debt, and payment history. Reading it takes no knowledge of statistics or model internals. It also points forward: the applicant learns what would change the outcome next time, not only why this one went badly. That value depends on the constraints on what can change, because a counterfactual that asks for an impossible change gives the person nothing to do.
A lender that says "with an income of $52,000 instead of $42,000, this application would have been approved" gives a counterfactual explanation. The same form works for any model that makes decisions about people or objects. In every domain the explanation has three parts: the decision, the changed input, and the new decision.
A resume-screening model that rejected a candidate can report that two more years of experience with a required skill would have advanced the application. A readmission-risk model that flagged a patient as high risk can show which measured values, at what levels, would have put the patient in the low-risk group. That tells a clinician what the model responds to, not what to treat.
For images, Goyal and colleagues find the regions of one image that, swapped in from an image of another class, change the classifier's answer. In their bird-species experiments, people trained with these explanations learned to tell the species apart better than people trained with examples alone.
Text counterfactuals change a few words and watch the label move. Replacing "not bad" with "bad" in a product review and seeing a sentiment classifier flip from positive to negative shows how the classifier reads negation. Polyjuice, from Wu and colleagues, generates such minimal edits automatically. The same test applies to large language models, including the ones behind voice AI agents. Changing one fact in a caller's request and comparing the agent's answers over several runs shows whether the agent uses that fact. One run is not enough, because a language model's sampling can change an answer on its own.
Network operators run the same kind of classifier at high volume. They score traffic flows for intrusion and phone calls for spam and fraud before the calls connect. An illustrative call-screening model might block a call because the originating number placed 120 calls in the past hour. Its counterfactual might say that fewer than 40 calls would have passed. A reviewer handling a complaint from a wrongly blocked caller, such as a pharmacy's reminder line, then sees the exact threshold that caught it.
The detection report described in this guide to detecting AI voices identifies the artifacts behind each verdict. That report is an attribution. A counterfactual adds the other half: which of those signals would have had to be absent for the call to pass. The answer matters most when the flag triggers an action. On a programmable Voice API, a flagged call can be hung up, transferred to a person, or logged, and a counterfactual stored with that log tells the reviewer what would have let the call through.
Counterfactual explanations say what would have had to change for a different decision. Attribution methods such as SHAP and LIME say how much each input contributed to the decision that was made. The two answer different questions about the same prediction, and they can point at different features.
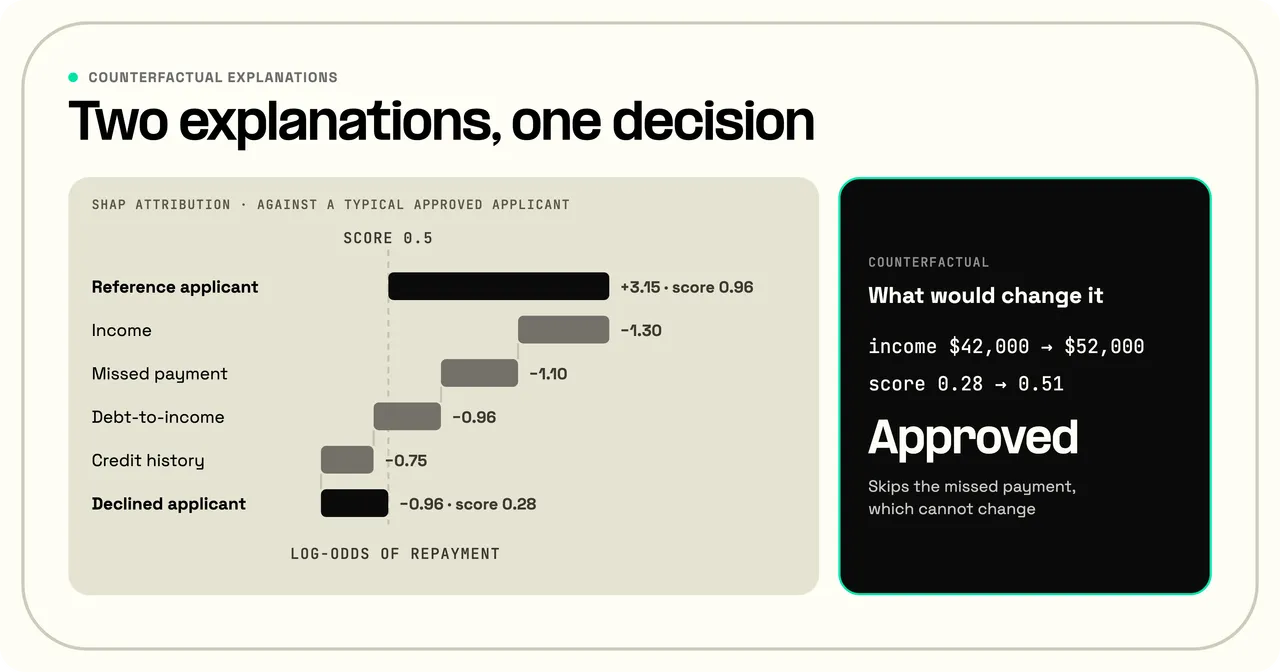
For the loan applicant, SHAP here measures the gap against a single reference. That reference is a typical approved applicant with a $55,000 income, a 30% debt-to-income ratio, 7 years of history, no missed payments, and a score of 0.96. For a logistic regression against one reference, each SHAP value is simply the feature's weight times its difference from the reference, so the split is exact. Against the usual baseline, the average over a background dataset, the values would differ.
The split is in log-odds: the applicant sits at −0.96 and the reference at +3.15. Income contributes −1.30, the missed payment −1.10, the debt-to-income ratio −0.96, and the shorter credit history −0.75. The four add up to the full −4.11 gap.
SHAP ranks the missed payment second, a feature the applicant cannot change; the counterfactual skips it and names the income change.
The ranking depends on the reference. Regulation B's commentary accepts, among other methods, comparing an applicant with applicants who scored at or slightly above the minimum passing score, or with all applicants. A stand-in for the first group is an applicant with $44,000, a 38% ratio, 4 years of history, and no missed payment, who scores 0.58. Against that reference, the missed payment contributes −1.10 and income −0.20, and the other two features contribute nothing. The missed payment becomes the top reason, so under that method it has to appear on the notice.
For a lender, that suggests a two-part check. The reasons on the notice should match the top attributions under the reference the lender's method names. Any guidance about what the applicant could change should match a counterfactual the constraints allow, such as the $52,000 income route, and never an impossible one.
Contrastive explanations are a close relative of counterfactuals. The contrastive explanations method of Dhurandhar and colleagues reports what must be present for a prediction and what must stay absent. In the paper's image examples, the absent part, the "pertinent negatives," is background pixels that have to stay blank for a handwritten digit to keep its label. In the loan model, an approved applicant's clean payment record works the same way: the approval holds partly because no missed payment is present.
Causal counterfactuals are a different object with the same name. In causal inference, a quantity such as E(Y^a), the average outcome if everyone had received treatment a, describes what would happen in the world. Estimating it from observational data requires assumptions about confounders, the factors that affect both the treatment and the outcome. A counterfactual explanation describes what the model would output, and it needs no assumptions because the model can be rerun. That exactness about the model says nothing about the world, which is where counterfactual explanations can mislead.
The main challenges of counterfactual explanations are that they ignore cause and effect between features and that the nearest one can be implausible. They can also be gamed or leak the model they explain, they get harder over sequences of decisions, and many different counterfactuals can explain the same decision, which makes large sets hard to read.
Counterfactual explanations treat features as independent dials, and real features are not independent. Debt-to-income is debt payments divided by income. An applicant who raises income to $52,000 while keeping the same debt also lowers the ratio to about 31%, and the model then scores 0.71, not 0.51. With the ratio allowed to follow income, $47,000 would have been enough.
The simplest fix inside a counterfactual library is to search over debt and income and compute the ratio from them in the model wrapper, so the two can never move separately. A lender that models the identity would report the $47,000 route; the $52,000 figure used elsewhere on this page is what a search that treats the features as independent returns.
Karimi, Schölkopf, and Valera put the gap plainly: a counterfactual explanation tells a person where they need to get to, but not how to get there. They propose computing recourse as the smallest set of interventions in a causal model of how the features affect each other.
A counterfactual can be valid for the model and still describe no real person. A search without data constraints might pair a $90,000 income with a single year of credit history. The model may rarely or never have seen that combination in training, so its score there is an extrapolation. Laugel and colleagues call these unjustified counterfactuals and show that post-hoc methods, which explain a model after it is trained, often produce them. Data-guided search reduces the problem. A second check flags the rest: measure each counterfactual's distance to the nearest real applicant, and reject any farther away than, for example, the 95th percentile of nearest-neighbor distances among real applicants.
A model can be built so that its counterfactuals mislead. Slack and colleagues train a model that looks fair when audited with standard counterfactual search, which reports similar recourse costs for two groups. A slight, deliberate change to the same applicant's input then reveals much cheaper recourse for one group, so the audit itself can be fooled. Counterfactuals also reveal the decision boundary, one point at a time. Aïvodji and colleagues show that an attacker who collects them can train a faithful copy of the model. A system that publishes counterfactuals publishes information about its model, which qualifies the promise that counterfactuals keep a proprietary model private.
Many decisions arrive as the last step of a sequence: a treatment plan, a multi-step application, a reinforcement learning agent's policy. A counterfactual there has to name which earlier choice would have changed the outcome. The number of possible alternatives grows with every step. Tsirtsis, De, and Gomez-Rodriguez search for the closest alternative sequence of actions that would have led to a better outcome, with a limit on how many steps may differ. In collections, for example, the counterfactual might name the payment-plan offer that, made a month earlier, would have kept an account current. The same limit on how many steps may differ keeps that answer short enough for a person to act on.
The Rashomon effect, named after the film in which witnesses give conflicting accounts of one event, describes a decision with several equally valid explanations. The declined applicant has at least four that the constraints allow: an income of $52,000, a debt-to-income ratio of 29%, an income of $48,000 together with a 34% ratio, or 8 years of credit history. A fifth, a record with no missed payment, flips the decision too, but the constraints rule it out. Choosing which one to show shapes what the applicant does next.
The effect also runs across models. Pawelczyk and colleagues show that equally accurate models can treat the same person differently, so a counterfactual computed on one model may not hold on another. Retraining can change the answer: the income that would have been enough last month may fall short after the next update.
More counterfactuals give a fuller picture and are harder to read. Miller's survey found that people select one or two causes from many, so an applicant shown ten routes to approval gets less guidance, not more. One common default is two to four diverse counterfactuals, each changing few features.
Implementing counterfactual explanations means choosing a generation method that fits the model and encoding which features may change and how. It also means testing every counterfactual before a person sees it. Python libraries cover the generation step for most tabular models.
DiCE is an open-source Python library that generates diverse counterfactuals for scikit-learn, TensorFlow, and PyTorch models. It offers both model-agnostic and gradient-based methods. Alibi Explain, a source-available library, includes counterfactual search in the style of Wachter and colleagues, the prototype-guided method, and the contrastive explanations method. It also has a reinforcement learning method that generates counterfactuals quickly once trained. CARLA, from Pawelczyk and colleagues, benchmarks recourse and counterfactual methods on common datasets and models, so methods can be compared on equal terms before one is chosen.
The model decides the method first. Differentiable models, such as neural networks and logistic regressions, support gradient-based search, which is fast. Tree ensembles and models behind an API usually rely on model-agnostic search, which needs more predictions. The data type decides the next choice. Tabular features can be changed one at a time, while images and text need generative methods so the counterfactual stays a realistic image or sentence. An explanation for the person affected calls for a diverse, constrained set. For a developer debugging the model, the single nearest counterfactual is often enough.
Each domain adds its own rules about which changes a counterfactual may suggest. In lending, a counterfactual should never suggest changing a characteristic the law protects, such as national origin. It should also be reconciled with the reasons the lender states in its notices: the reasons come from the attribution, and the counterfactual speaks only to what the applicant could change.
Reconciling an explanation with its notice later, in an audit or a complaint, means logging, with every decision, the inputs, the model version, the constraint set, and the counterfactual actually shown. Regulation B requires creditors to keep the application and the information used to evaluate it for 25 months after the notice for consumer credit. The model version, constraint set, and counterfactual shown are additions the regulation does not name.
Healthcare adds a different rule: a counterfactual about lab values explains the model, not the patient, and has to be presented so no one reads it as treatment advice. Every domain needs its list of immutable and one-directional features written down before the search runs.
A counterfactual method is judged on a handful of measurable properties. The review by Verma and colleagues, first posted in 2020 as "Counterfactual explanations for machine learning: A review," uses them as its rubric. Validity asks whether the counterfactual actually flips the decision. Proximity asks how far it is from the original, and sparsity how many features it changes. Plausibility asks whether it lies near real data, feasibility whether it respects the constraints, and diversity whether a set covers different routes. Stability asks whether similar people get similar counterfactuals and whether the answer survives retraining.
A counterfactual explanation tells a person what would have had to be different for an AI model to reach another decision. An example is "the loan would have been approved with an income of $52,000." It explains one decision by pointing to the nearest alternative input the model would have treated differently, without describing the model's inner workings.
Examples of counterfactuals in AI include a lender stating that a higher income would have led to approval. A resume screener can show that more experience with a required skill would have advanced a candidate. An image classifier can reveal which part of a photo would have to change for a different label, and a call-screening model can show which feature of a call would have let it through. Outside AI, "if I had left five minutes earlier, I would have caught the train" is a counterfactual.
Counterfactuals in machine learning are alternative inputs or outcomes used to explain or evaluate models. Counterfactual explanations change an input until a model's prediction changes. Causal machine learning uses the word in a second sense: the outcome a unit would have had under a different treatment, estimated from data. Counterfactual data augmentation, a third use, adds edited copies of training examples so a model learns not to depend on a feature such as a name or gender.
"Counterfactual explanations without opening the black box: Automated decisions and the GDPR" is a 2017 paper by Sandra Wachter, Brent Mittelstadt, and Chris Russell. The Harvard Journal of Law and Technology published it in 2018. It argues that counterfactuals can explain automated decisions to the people affected without disclosing how the model works. It also proposes the optimization that later methods build on: a prediction term plus a distance weighted by each feature's median absolute deviation.
The best tool for counterfactual explanations depends on the model and the audience. DiCE suits tabular models when a diverse set of counterfactuals is needed. Alibi Explain adds prototype-guided and fast learned methods, and CARLA is the benchmark for comparing methods on the same data. For a differentiable model, a gradient-based method is fastest; for a model behind an API, only model-agnostic methods apply.
A counterfactual is not a fallacy; it is a claim about what would have happened under different conditions. It becomes weak reasoning when nothing can check it, such as a confident claim about how history would have gone. A counterfactual explanation of an AI model is the checkable kind. The model can be run on the changed input, and the claimed outcome either appears or does not.
ChatGPT is not explainable AI in the technical sense. It is a large language model whose billions of parameters cannot be read as reasons, and the explanations it writes for its own answers are not guaranteed to reflect how it produced them. Turpin and colleagues found that models' step-by-step explanations can leave out a bias that changed the answer. Counterfactual tests are one of the few outside checks: changing one fact in the prompt and comparing answers over several runs shows whether the answer moves with it.
Explainability is hard for the most accurate AI models, because a deep network spreads each decision across millions or billions of learned parameters. Those parameters do not map onto human reasons. Simple models such as short decision trees are interpretable by design, but they often give up accuracy. Counterfactual explanations avoid part of the problem by explaining behavior rather than internals. They need only the model's inputs and outputs, though they describe one decision at a time, not the model as a whole.