An encoder-decoder model maps one sequence to another. How it works, examples like T5 and Whisper, and how it compares to encoder-only and decoder-only.
Updated September 2026
An encoder-decoder model splits a hard problem in two. One network reads the input and compresses it into a representation, and a second network reads that representation and writes the output. That split is why one architecture can translate English into French, turn speech into text, or shorten a long document into a summary.
Quick answer: An encoder-decoder model is a neural network architecture with two parts: an encoder that turns an input sequence into an internal representation, and a decoder that generates an output sequence from it. It fits tasks where the input and output differ in length or type, such as machine translation, summarization, and speech recognition. Introduced for machine translation in 2014 and rebuilt on attention in the 2017 Transformer, it is one of three main Transformer layouts, alongside encoder-only and decoder-only.
An encoder-decoder model is a machine learning architecture that maps one sequence to another in two stages. The encoder processes the full input and produces a representation that holds its meaning. The decoder takes that representation and produces the output one step at a time. The design is also called a sequence-to-sequence, or seq2seq, model.
This content was generated with the assistance of AI. Our AI prompt chain workflow is carefully grounded and preferences .gov and .edu citations when available. All content is reviewed by a Telnyx employee to ensure accuracy, relevance, and a high standard of quality.
This is the machine learning meaning, not the hardware one. A rotary encoder is a sensor that measures rotation, and a decoder in digital electronics is a logic circuit that maps input lines to outputs. Neither is related to the neural network here. An audio or video codec also uses the words encode and decode, but for compression, not for learning.
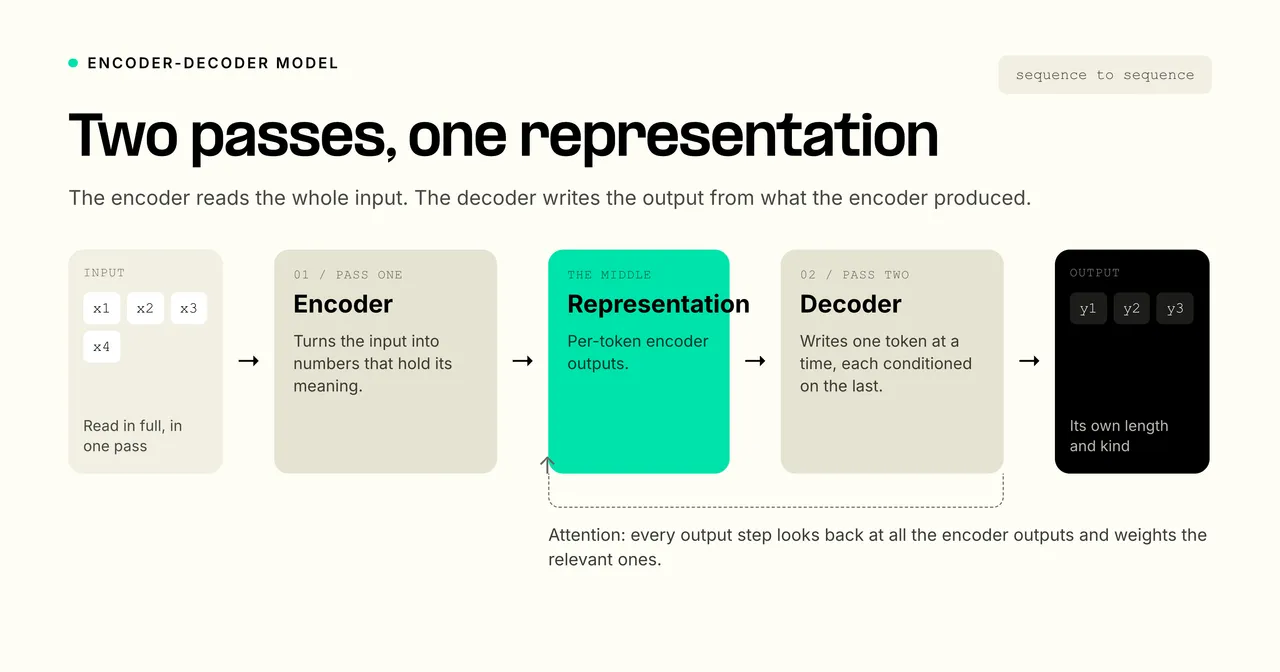
The encoder and the decoder are the two neural networks inside the architecture, each with a distinct job. The encoder reads the input and turns it into a set of numbers that captures its meaning in a form the model can work with. The decoder reads that representation and generates the output one token at a time, each new token conditioned on what it has already produced.
An encoder on its own is a reading model, built to understand an input, which is why encoder-only models suit classification and search. A decoder on its own is a writing model. It generates text left to right, which is why decoder-only models suit open-ended generation. An encoder-decoder pairs the two, so the output can depend on the whole input.
An encoder-decoder model works in two passes. The encoder consumes the entire input sequence and produces its representation. Then the decoder generates the output sequence from that representation, referring back to it at every step.
Translation makes the two passes concrete. The encoder reads the full English sentence and builds its representation. The decoder then emits the French sentence word by word, and because it can draw on the whole encoded input, a word near the end of the output can still depend on a word at the start of the input.
Early encoder-decoder models squeezed the whole input into a single fixed-length vector, which became a bottleneck on long inputs. Attention removed that limit. Instead of one summary vector, the decoder looks back at all of the encoder's per-token outputs and weights the ones most relevant to the token it generates. The 2017 Transformer built the entire architecture around attention and dropped the recurrent networks the original models relied on.
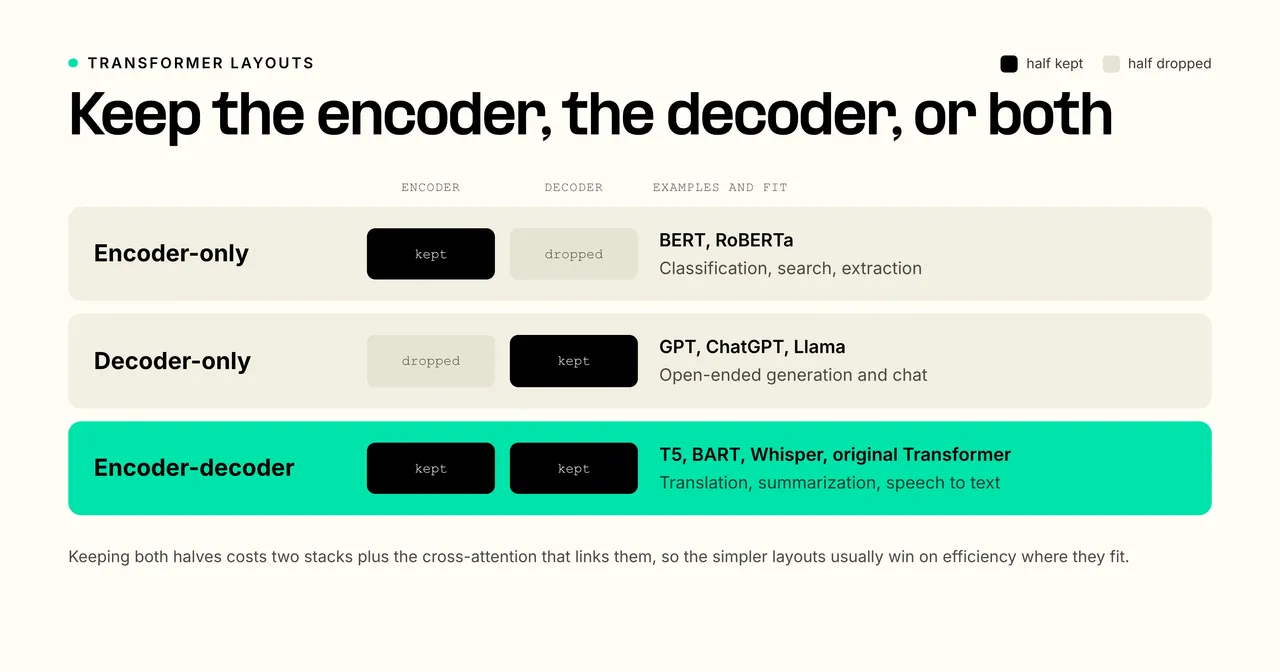
The three layouts differ in which halves they keep and what they do best. Encoder-only models keep the encoder and read the whole input at once, in both directions. Decoder-only models keep the decoder and generate left to right. Encoder-decoder models keep both, and are built for turning one sequence into a different one.
| Architecture | Reads and writes | Example models | Best at |
|---|---|---|---|
| Encoder-only | Reads the full input, both directions | BERT, RoBERTa | Understanding: classification, search, extraction |
| Decoder-only | Generates left to right | GPT, ChatGPT, Llama | Open-ended text generation and chat |
| Encoder-decoder | Encodes input, then generates output | T5, BART, Whisper, original Transformer | Translation, summarization, speech-to-text |
Most large language models today are decoder-only, including the GPT family behind ChatGPT, because next-token generation scales well and covers many tasks with one model. Encoder-decoder models still lead where the input and output are clearly separate, such as translation and speech recognition, because a dedicated encoder can read the full input before any output is written. The cost is size: an encoder-decoder runs two stacks plus the cross-attention that links them, so for tasks a decoder-only model already handles well, the simpler layout usually wins on efficiency.
Common encoder-decoder models include the original Transformer, T5, BART, and Whisper. The 2017 Transformer introduced the attention-based encoder-decoder for machine translation. T5 frames every task as text-to-text, so translation, summarization, and classification all run through one encoder-decoder. BART adds a denoising objective and suits summarization. Whisper applies the layout to speech: the encoder reads audio, the decoder writes text.
Before the Transformer, encoder-decoder models used recurrent networks. Cho and colleagues named the RNN encoder-decoder in 2014, and Sutskever and colleagues showed sequence-to-sequence learning the same year.
The layout also runs on images. Convolutional encoder-decoders swap the sequence networks for convolutional ones: the encoder downsamples an image into a compact feature map, and the decoder upsamples it back to full resolution. U-Net is the best-known case, built for biomedical image segmentation, where the output is a labeled map the same size as the input rather than a sentence.
Encoder-decoder models are used for tasks that turn one sequence into a different one. The common thread is a mismatch between input and output: when the two are the same kind and length, a simpler model often does the job.
Translation is the original case, and it is still where the layout is strongest. The encoder reads a sentence in one language and the decoder writes it in another, which is the shape production translation systems have used since neural machine translation replaced phrase-based systems. Summarization runs the same way, compressing a long document into a short one, and question answering follows the same read-then-write pattern.
Image captioning pairs a vision encoder with a text decoder. A convolutional network reads the image and produces a feature representation, and the decoder writes a sentence describing it. This is the clearest case of the two halves working on different modalities, because nothing about the input is a sequence of words.
Speech recognition reads audio and writes text, which is exactly what Whisper does with an audio encoder and a text decoder. Text to speech runs the same shape in reverse, reading text and producing audio frames. Attention matters more here than in translation, because an audio input is far longer than the text it maps to.
The main limit is cost. An encoder-decoder runs two stacks plus the cross-attention linking them, so it needs more compute and memory than a single-stack model of similar quality.
The original limit was the fixed-length vector. Early models squeezed the whole input into one vector, and translation quality fell as sentences grew longer. Attention removed that ceiling by letting the decoder read every encoder output, and the 2017 Transformer made attention the whole architecture.
Two limits remain. Decoding is sequential, because each output token depends on the one before it, so generation is harder to parallelize than encoding. And for tasks a decoder-only model already handles, the second stack buys little. Scale and instruction tuning let GPT-style models translate and summarize well enough that the general-purpose lane went to them.
No, BERT is an encoder-only model. It uses only the encoder half to read text in both directions, which suits understanding tasks like classification and search rather than generation. Encoder-decoder models such as T5 keep both halves.
ChatGPT is built on a decoder-only model. The GPT family uses only the decoder and generates text one token at a time, left to right. It has no separate encoder reading a fixed input, which is what sets it apart from an encoder-decoder model.
Most large language models are decoder-only, including the GPT and Llama families. A few use an encoder-decoder layout, such as T5. Encoder-only models like BERT are language models too, but they are used for understanding rather than generation.
The encoder reads an input and turns it into an internal representation. The decoder reads a representation and generates an output from it. The encoder understands, the decoder writes, and an encoder-decoder model chains the two.
Decoding is how the decoder picks each output token, and three strategies cover most use. Greedy decoding takes the highest-probability token at every step. Beam search keeps several candidate sequences alive and picks the best complete one, which usually reads better on translation. Sampling draws from the probability distribution instead of taking the top token, which suits open-ended generation where variety matters.
Not exactly. The original Transformer is an encoder-decoder, but the Transformer design also powers encoder-only models like BERT and decoder-only models like GPT. Encoder-decoder describes the layout; Transformer describes the underlying mechanism, attention.