Explainable AI (XAI) shows why a model made a decision: how it works, its benefits, SHAP and LIME, the laws that require it, and whether ChatGPT is explainable.

Updated September 2026
Explainable AI (XAI) is the set of methods that let a person see why a machine learning model produced a particular output. An explanation shows which inputs pushed the result up or down and by how much, or which rule the model followed. It covers models that are interpretable by design, such as rule lists and small decision trees, and techniques such as SHAP and LIME that explain a complex model after it has been trained.
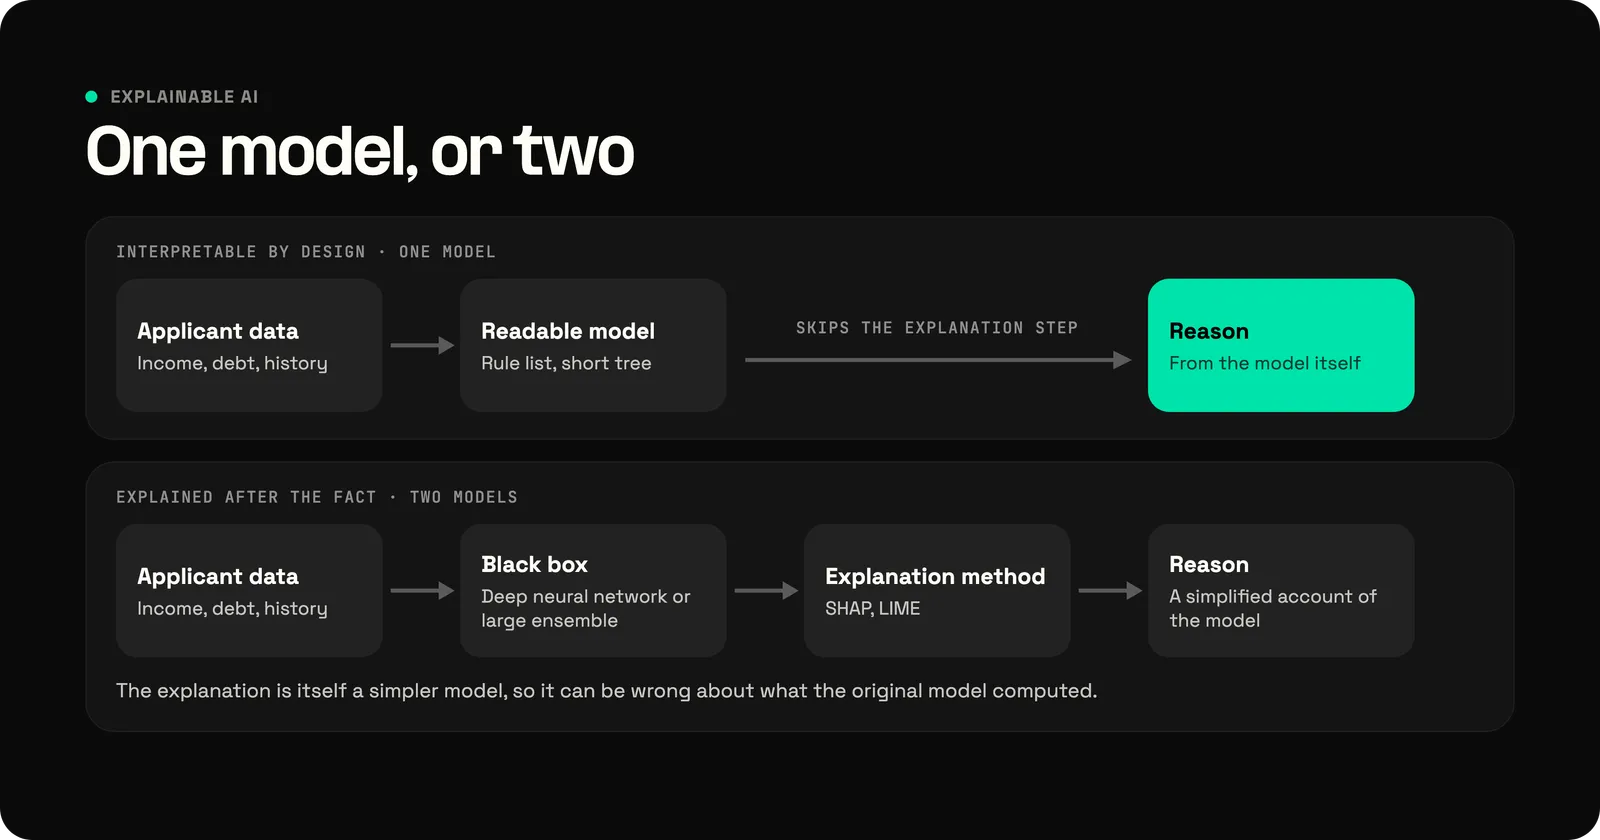
Explaining a model after training is the harder route, because the explanation is a simplified account of the model, not the model itself. A deep neural network or a large ensemble can score a loan application accurately and still offer no reason a person can read, which is why such systems get called black boxes. Explainable AI is the work of getting a usable reason out of a black box, or of choosing a model that never needed one.
Explainable AI is the part of machine learning concerned with reasons: an explainable system can say what drove a given output in terms the person relying on it understands. DARPA funded a four-year research program on the topic. It defines explainable AI as systems that "can explain their rationale to a human user, characterize their strengths and weaknesses, and convey an understanding of how they will behave in the future," according to . DARPA announced the program in 2016 and launched it in May 2017 under the name XAI, the same abbreviation the field uses. The abbreviation is unrelated to xAI, the company behind the Grok models; the FAQ below covers the name clash.
This content was generated with the assistance of AI. Our AI prompt chain workflow is carefully grounded and preferences .gov and .edu citations when available. All content is reviewed by a Telnyx employee to ensure accuracy, relevance, and a high standard of quality.
Explainability and interpretability overlap, and researchers use them loosely. Doshi-Velez and Kim define interpretability as "the ability to explain or to present in understandable terms to a human." Christoph Molnar's Interpretable Machine Learning notes that the field cannot agree on the difference. He adopts a common split: interpretability maps what a model does into an understandable form, and explainability adds the context a person needs to use it. This page uses a simpler working split: an interpretable model is one a person can read directly, and an explanation is usually an account of one prediction.
A definition says what an explanation is; NIST's four principles of AI explainability say what a good one needs. A system should give a reason for each output (explanation) and make that reason understandable to its audience (meaningful). The reason should match how the output was actually produced (explanation accuracy), and the system should operate only under the conditions it was designed for (knowledge limits). NIST treats explanation accuracy as separate from decision accuracy: a model can be right for the wrong reason, and an explanation can describe a reason the model never used.
Explainable AI works in one of two ways: build a model whose logic a person can read, or run an explanation method on a model that cannot be read. Molnar calls these interpretability by design and post-hoc interpretability.
Interpretable-by-design models are simple enough to show their reasoning. A linear model's weights say how much each input moves the output. A small decision tree or a rule list, "a sequence of IF-THEN rules" in the words of Yang and colleagues, can be followed step by step. That is why rule-based AI is easy to audit: the rule that fired is the reason.
Post-hoc methods explain a model after it has been trained, and they come in two kinds. Model-agnostic methods treat the model as a closed box and study how its output changes as the inputs change, so they work on any model. Model-specific methods look inside, for example at a neural network's gradients or at individual neural network units, some of which respond to recognizable concepts such as trees. Either kind can be local, explaining one prediction, or global, describing how inputs affect predictions on average.
One credit application shows a local explanation in action. The model is an illustrative credit model that scores applicants from 0 to 100 and approves at 50 or more. The applicant in question earns $48,000, has a 42% debt-to-income ratio, 5 years of credit history, and one recent missed payment, and scores 24, so the model declines.
A SHAP-style explanation answers why with an attribution: a list of how much each input contributed to the gap between this score and a comparison point called the baseline. Here the baseline is a typical applicant, with a $60,000 income, a 30% debt-to-income ratio, 8 years of history, and no missed payments, who scores 60. The method uses Shapley values, a game-theory rule for dividing a joint result among contributors (covered under Methods), computed exactly here. The debt-to-income ratio accounts for -15 points, the missed payment for -9, the short credit history for -6, and the lower income for -6. The four contributions add up to exactly -36, the gap between 60 and 24, which makes the explanation checkable.
Six of the 36 points come from a combination: the model adds an extra penalty when a high debt-to-income ratio and a missed payment occur together. The Shapley calculation splits that 6 evenly, 3 to each. If all 6 went to debt-to-income instead, the missed payment would tie with two other inputs for second place, so the rule for splitting a shared penalty changes the order of the reasons.
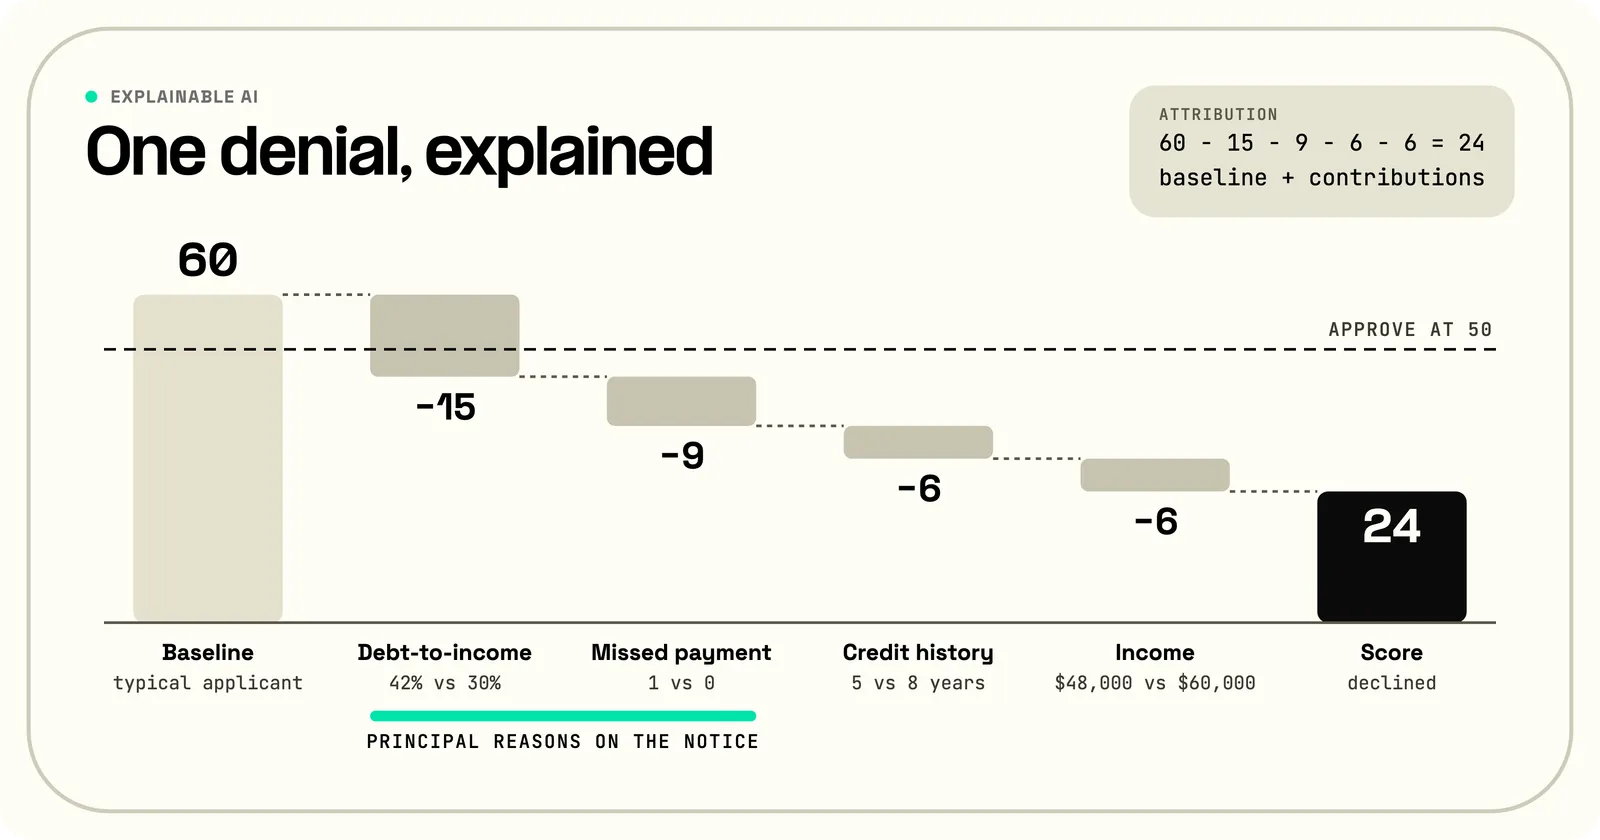
The largest negative contributions are the natural candidates for the reasons on a denial notice, starting with debt-to-income and the missed payment. US credit law asks for the principal reasons, not the numbers behind them. Under Regulation B, the reasons for a denial "must be specific and indicate the principal reason(s)," and a statement that the applicant "failed to achieve a qualifying score" is not enough.
Regulation B's sample notice lists reasons such as "Excessive obligations in relation to income" and "Delinquent past or present credit obligations with others," which match the two largest contributions here. Its official commentary says the regulation does not require any one method for selecting reasons, and that more than four is "not likely to be helpful to the applicant." An attribution like this one is one way to find them.
The main benefits of explainable AI are appropriate trust, faster debugging, bias that can be found before it does harm, and decisions that people can check and contest. DARPA's program aimed to help users "understand, appropriately trust, and effectively manage" AI systems. The word appropriately matters: an explanation should make a person trust a good model and doubt a bad one.
Debugging is where explainable AI benefits show up first. In the paper that introduced LIME, Ribeiro and colleagues deliberately trained a bad image classifier to tell wolves from huskies, using 20 photos chosen so that every wolf photo had snow in the background. The model then labeled any photo with snow a wolf and any photo without snow a husky. On a test set of 10 photos it got 8 right. LIME's explanations showed what it was actually looking at: the snow, not the animal. Before seeing the explanations, 10 of the 27 graduate students in the study trusted the model; after seeing them, 3 did.
The same inspection helps find bias. Attributions across many decisions show which inputs carry the most weight. Checked against data on protected characteristics, they show whether a heavily weighted input, such as a postal code, acts as a stand-in for one. An input that does is a candidate to remove or replace, which is where bias mitigation starts.
An explanation also gives the person affected by a decision something to act on. Wachter and colleagues list three purposes for explaining an automated decision. It should help the person understand why the decision was reached, give grounds to contest it, and show what would need to change for a different result.
Explainable AI in decision-making turns a model's output into something a reviewer can check. A reviewer who can see why a model flagged a case can overrule it when the reason is wrong and trust it when the reason holds. That makes an explanation a working check on the model.
Explainable AI is important because some decisions legally require a reason, and three sets of rules come up most often: US credit law, the EU's GDPR, and the EU AI Act. The first governs lending in the US; the other two apply to decisions about people in the EU.
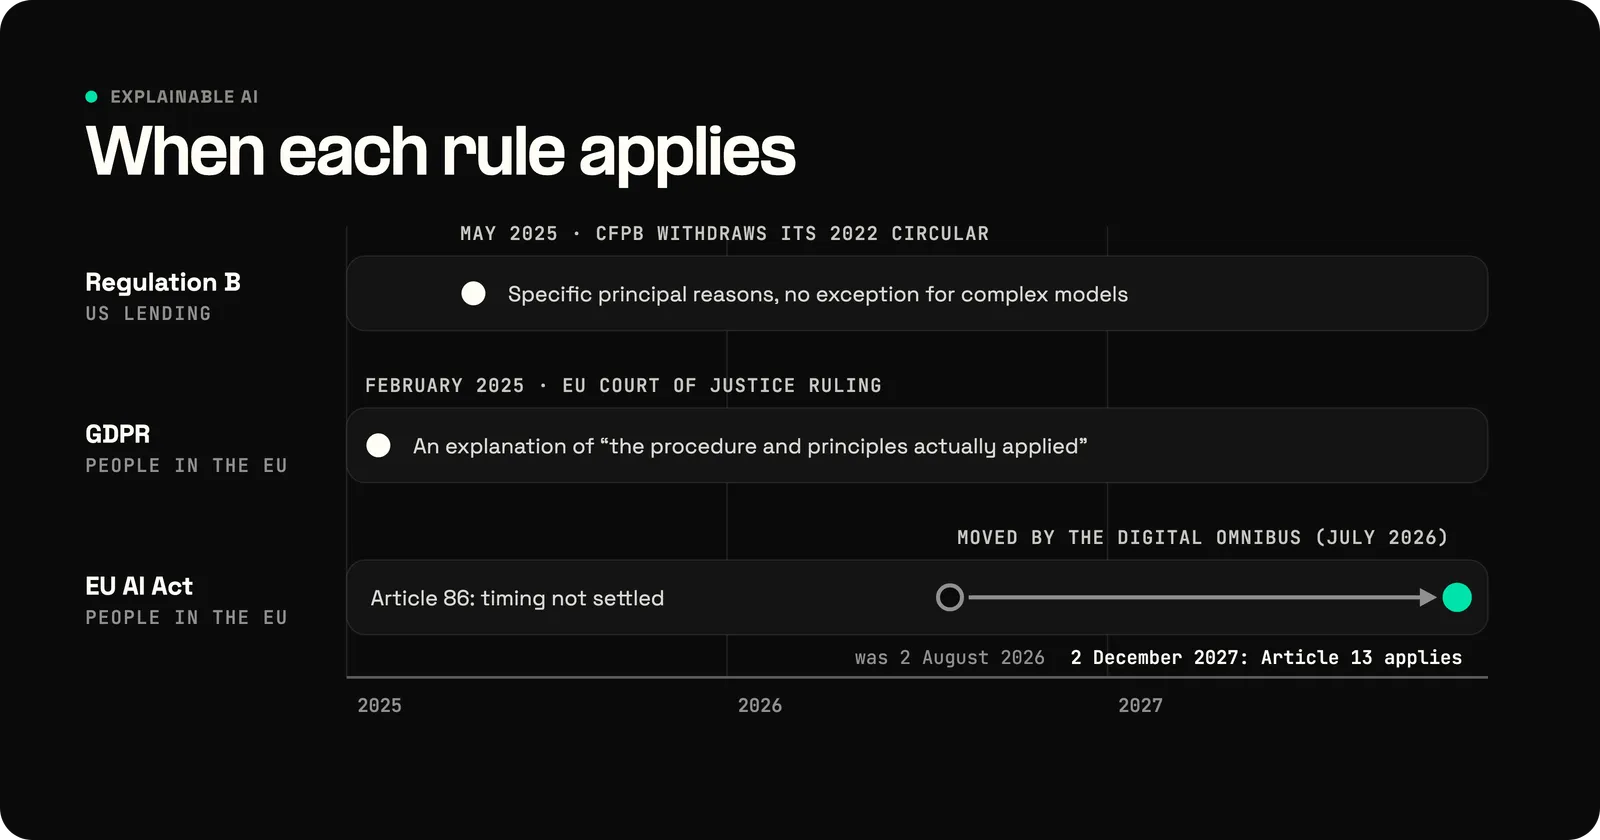
In the US, the Equal Credit Opportunity Act and its implementing rule, Regulation B, require a lender that denies credit to give the applicant specific principal reasons. A 2022 CFPB circular applied that rule to complex algorithms: creditors using them "must still provide a notice that discloses the specific principal reasons," and a model too opaque to understand is no excuse. The CFPB withdrew the circular in May 2025. That removed the agency's guidance, not the rule: Regulation B has no exception for complex models.
The GDPR's text says less about explanation than its reputation suggests, and a 2025 court ruling filled the gap for credit scoring. Article 22 gives people the right not to be subject to a decision "based solely on automated processing" that has legal or similarly significant effects. Where such decisions are allowed, people keep the right to human intervention, to express their view, and to contest the decision. Article 15 adds a right to "meaningful information about the logic involved." The word explanation appears only in Recital 71, part of the regulation's preamble, which is not legally binding, a point Wachter and colleagues make at length.
The EU Court of Justice read Article 15 more broadly in February 2025, in a case about an automated credit assessment. It ruled that the article lets the person require the company to explain "the procedure and principles actually applied" to reach a result "such as a credit profile," in a concise and intelligible form. Handing over "a complex mathematical formula, such as an algorithm," does not meet that bar. For a credit decision made solely by a model, the GDPR gives the person a right to an explanation they can follow.
The EU AI Act addresses explanation directly. Article 13 requires high-risk AI systems to be "sufficiently transparent to enable deployers to interpret a system's output and use it appropriately." Article 86 gives people affected by decisions from high-risk systems in the Act's Annex III a right to "clear and meaningful explanations" of the AI system's role and "the main elements of the decision taken."
Annex III includes systems that evaluate creditworthiness or set credit scores. The high-risk requirements, Article 13 among them, were due to apply from 2 August 2026. A July 2026 amendment, the Digital Omnibus on AI, moved them to 2 December 2027 for Annex III systems. The amendment does not mention Article 86, so when that right takes effect for credit decisions is not settled by the text alone.
Explainability matters beyond the law wherever the stakes are high. Black-box models already make decisions in healthcare, criminal justice, and other high-stakes domains, as Cynthia Rudin notes, and there the question is not only whether a model can be explained but whether its explanation can be trusted.
Common examples of explainable AI are credit decisions that list the reasons for a denial, image classifiers that highlight the region behind a result, and fraud alerts that show which signals triggered them. Rule-based systems are another example, because their deciding rule can be read directly.
Credit is the standard case, because the law asks for reasons and inputs such as debt-to-income map onto the reasons on Regulation B's sample notice, as the credit example above shows. Image models use heatmaps. Grad-CAM produces "a coarse localization map highlighting important regions in the image," so a reviewer can see whether a medical image classifier looked at the finding or at something beside it.
Fraud screening is another of the common explainable AI use cases. In fraud decisioning, an explanation tells a reviewer why a case was flagged. Dhurandhar and colleagues tested the contrastive explanation method, described below, on millions of invoices from a large corporation. For one invoice rated high risk, the explanation named what was present: unusually high spend with the vendor, a risky commodity code, and a vendor with only a PO box. It also named what was absent: the vendor was not registered with the company and had no Dun & Bradstreet number.
Rule-based and knowledge-based systems are explainable by construction: in knowledge reasoning, a conclusion can be traced back through the rules and facts that produced it.
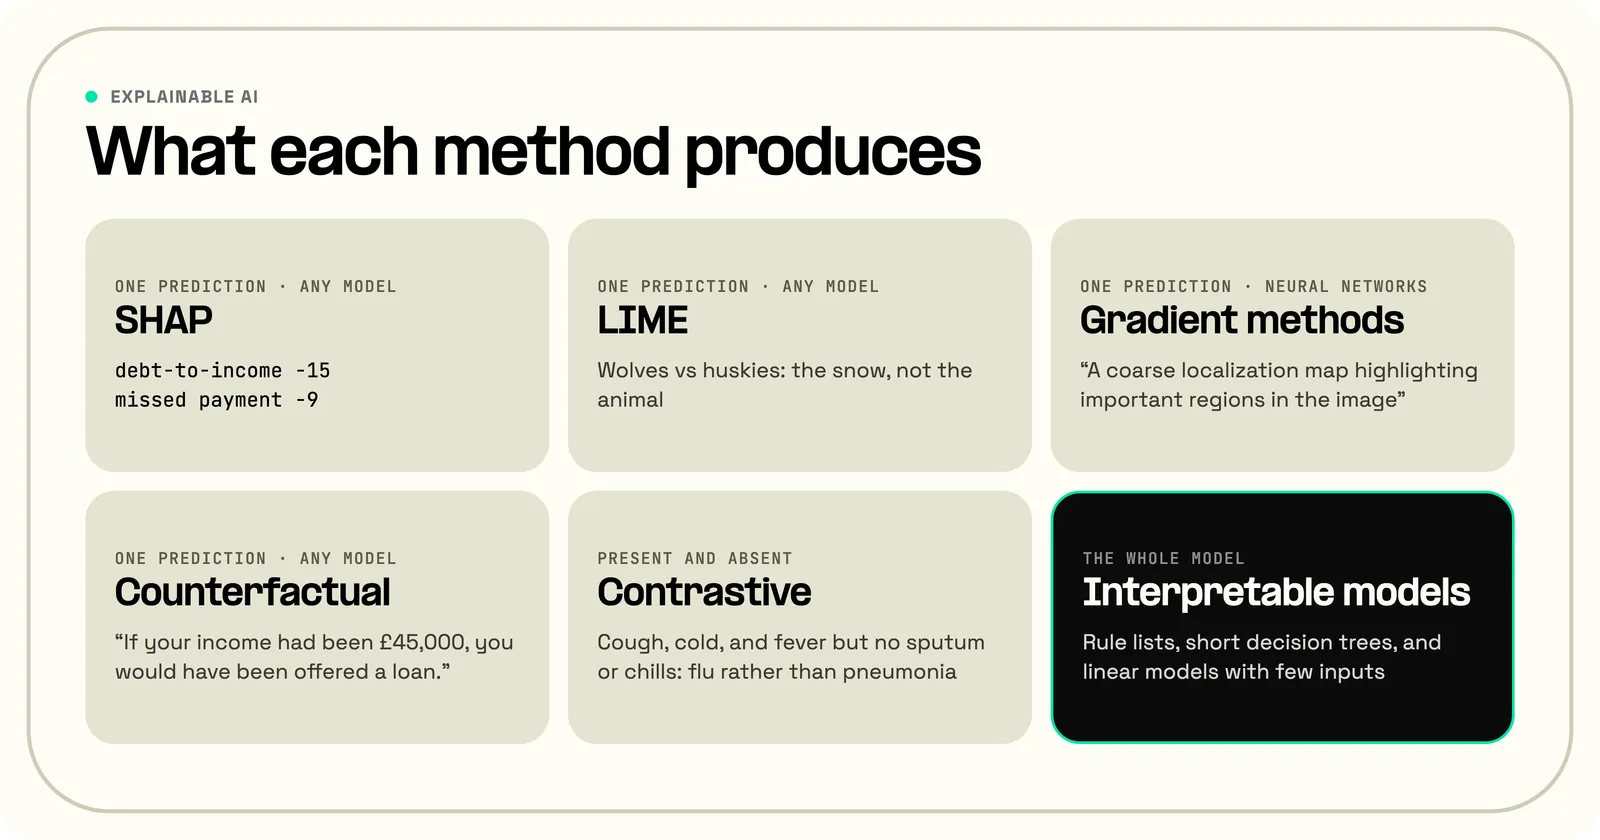
The main methods of explainable AI are SHAP and LIME, which explain individual predictions of any model, and counterfactual explanations, which say what would have to change. Neural networks add gradient-based attributions, and some models are interpretable by design.
SHAP assigns each input a share of one prediction, measured against a baseline. Lundberg and Lee built it on Shapley values from cooperative game theory, a way of dividing a payout fairly among players that Lloyd Shapley published in 1953. In SHAP, the players are the inputs and the payout is the gap between this prediction and a baseline, commonly the model's average prediction over a reference dataset; the credit example uses a single typical applicant. Computing the values means scoring altered copies of the input with some inputs swapped for baseline values. For most models, the Kernel SHAP method estimates the values from a sample of those copies.
The SHAP paper names three properties. Under local accuracy, the contributions plus the baseline add up to the prediction. Under missingness, an input the explanation leaves out gets zero credit. Under consistency, if a model comes to rely more on an input, that input's share does not shrink. The authors show that methods not based on Shapley values break local accuracy, consistency, or both.
A SHAP value is measured in the model's output units and can be negative. In the credit example, debt-to-income moved the score down by 15 points. A model that outputs a probability can report on a less intuitive scale. For a gradient-boosted classifier such as XGBoost, the shap library reports values in log-odds by default, which have to be converted before they read as changes in probability. Exact values also work at real scale for tree models, which Lundberg and colleagues call "the most popular non-linear predictive models used in practice today." Their algorithm computes exact SHAP values for tree ensembles, including gradient-boosted trees, without trying every combination of inputs, and the shap library implements it.
The baseline changes the answer. Against the typical applicant, debt-to-income is the top reason. A borderline applicant scores exactly 50, with a $56,000 income, a 38% debt-to-income ratio, 8 years of history, and no missed payments. Against that baseline, the missed payment becomes the top reason at -11, followed by credit history at -6, debt-to-income at -5, and income at -4. Those add up to -26, the gap between 50 and 24. Regulation B's commentary gives two example methods for selecting reasons: one compares the applicant with applicants who scored at or just above the passing score, the other with all applicants. A SHAP baseline plays the same role, and choosing one is part of the method.
LIME explains one prediction by fitting a simple model around it. Ribeiro and colleagues describe it as "learning an interpretable model locally around the prediction." LIME makes many slightly changed copies of the input, records how the black-box model scores each one, and fits a small linear model to those scores. The small model's weights are the explanation. LIME does not carry SHAP's guarantees of local accuracy and consistency, and its answer depends on the sampled copies and how they are weighted.
A counterfactual explanation states the smallest change that would have flipped the result. Wachter and colleagues give an example: "You were denied a loan because your annual income was £30,000. If your income had been £45,000, you would have been offered a loan." A counterfactual does not require explaining the model's internal logic, which makes it practical to give to the person affected.
Contrastive explanations are close relatives: both kinds say what would have to differ. The contrastive explanation method (CEM) of Dhurandhar and colleagues explains a result by what is present and what is absent. A pertinent positive is a factor whose presence supports the result; a pertinent negative is a factor whose absence is necessary for it. Their example is a patient with cough, cold, and fever but no sputum or chills, who is most likely diagnosed with flu rather than pneumonia. The three symptoms present are the pertinent positives, but they fit both illnesses. The absence of sputum and chills is the pertinent negative that rules out pneumonia.
Neural networks allow model-specific methods that use gradients. A gradient measures how much the output changes when an input is nudged slightly, and it is the same quantity used in training. Integrated Gradients accumulates gradients along a path from a baseline input to the real input. Its attributions add up to the difference between the two outputs, the same bookkeeping SHAP guarantees. Grad-CAM turns the gradients flowing into a convolutional network's final convolutional layer into an image heatmap.
Interpretable models skip the explanation step. Rule lists, short decision trees, and linear models with few inputs can be read directly. Yang and colleagues report that their Bayesian rule lists achieve "better accuracy and sparsity than decision trees" for many practical problems. Open-source toolkits cover both routes: InterpretML trains interpretable "glassbox" models and explains black-box ones, and Captum provides attribution methods for PyTorch models.
The biggest limit of explainable AI is faithfulness: an explanation of a black-box model is itself a simpler model, so it can be wrong about what the original model computed. Rudin makes the case in a paper whose title is its argument, "Stop explaining black box machine learning models for high stakes decisions and use interpretable models instead." Post-hoc explanations, she writes, "are not faithful to what the original model computes," and they cannot be, because a completely faithful explanation would equal the original model.
Exact and faithful are different properties. SHAP's arithmetic can be exact, as in the credit example, where the four numbers add up to the score. The numbers are still a summary: on their own they do not show that 6 points of the penalty exist only when a high debt-to-income ratio and a missed payment occur together. Regulation B's commentary requires that stated reasons "accurately describe the factors actually considered or scored," so faithfulness is a compliance question as well as a technical one.
Rudin also challenges the idea that interpretability costs accuracy. "It is a myth that there is necessarily a trade-off between accuracy and interpretability," she writes. On structured data with meaningful features, she reports, there is often no significant difference in performance between complex classifiers and much simpler ones. Her recommendation for high-stakes decisions is to design models that are inherently interpretable, rather than explaining a black box after the fact.
Credit scoring is her own example. In the 2018 FICO Explainable ML Challenge, entrants were told to build a black box and explain it afterward, yet Rudin reports "no performance difference between interpretable models and explainable models for the FICO data." In her usage, explainable means a black box explained after the fact.
Post-hoc explanations can also mislead in quieter ways. An attribution describes how the model used an input, not whether that input causes the outcome in the world. A postal code can drive a credit score without causing anyone to default; telling the two apart takes causal inference.
Explanations built from altered inputs can be gamed on purpose. NIST warns that an explanation short of full accuracy can be exploited by adversaries who make a model behave differently on those altered inputs, hiding the system's biases. Slack and colleagues showed how, on data sets that included German credit records. They wrapped a deliberately biased classifier so that it behaved innocently on the altered inputs LIME and Kernel SHAP generate, and both methods produced explanations that hid the bias. In a lending audit, that would mean a biased model whose explanations look clean.
In credit, the practical challenges of explainable AI in decision-making add up to a sequence for a lender. Train an interpretable model first and compare it with the complex one; if the gap is small, the interpretable model supplies its own reasons. If the complex model clearly wins, explain it after the fact with a baseline chosen to match one of Regulation B's example methods, and check for combined penalties before ranking the reasons. The last step is translation, because the attribution chart a data scientist needs is not the sentence a declined applicant needs: each top contribution maps to a reason statement that describes the factor actually scored.
ChatGPT is not explainable AI in the XAI sense. It is a large language model, and the reasoning it writes out for an answer is generated text, not a readout of how the model computed that answer.
Turpin and colleagues tested this with chain-of-thought prompting, where a model explains its steps before answering. In one test, they reordered the answer options in a prompt's examples so the right answer was always "(A)". The pattern swayed the models' answers, but the models "systematically fail to mention" it in their explanations. When nudged toward wrong answers, the models "frequently generate CoT explanations rationalizing those answers," and the authors conclude that such explanations "can systematically misrepresent the true reason for a model's prediction." The models they tested were GPT-3.5 and Claude 1.0, but the finding is about the method. It is why a fluent explanation from a chatbot is not evidence of how the answer was produced.
Grounding and open weights help in narrower ways. Grounding ties an answer to retrieved sources, so a person can check the claim even without seeing the computation. Open weights, meaning the model's trained parameters are published, give access to the model, which any explanation of its internals needs. A team can run the model itself, probe it, and apply the gradient methods above, which a model reachable only through a vendor's API does not allow. As the Telnyx guide to open-source LLMs notes, open models allow external audits that proprietary ones do not. A cited source can be checked; a confident paragraph can only be believed.
Explainable AI is still an active field, and some of the rules that require it have not taken effect yet. Regulation B still requires specific reasons for credit denials. The GDPR, as the EU Court of Justice read it in 2025, gives people a right to an intelligible explanation of automated credit decisions. The EU AI Act's requirements for high-risk systems, such as Article 13's transparency duty, apply to credit scoring and other Annex III systems from 2 December 2027. DARPA's program has finished, but open-source libraries such as shap, InterpretML, and Captum implement the methods, and explaining large language models is an open research problem.
Generative AI and explainable AI answer different questions. Generative AI is a kind of model that produces new content, such as text, images, or audio. Explainable AI is a set of methods for showing why any model, generative or not, produced a given output. A generative model can be the subject of explainable AI, and its self-written explanations are not a substitute for it.
Interpretability describes how well a person can understand a model itself, while explainability describes how well a specific output can be accounted for. Doshi-Velez and Kim define interpretability as "the ability to explain or to present in understandable terms to a human." Molnar notes that researchers do not agree on a firm line between the two terms. A short decision tree is interpretable; a SHAP chart for one loan decision is an explanation.
The four principles of explainable AI, from NIST's 2021 report, are explanation, meaningful, explanation accuracy, and knowledge limits. A system should give a reason for each output and make the reason understandable to the person receiving it. The reason should reflect how the output was really produced, and the system should operate only in the conditions it was designed for and when it is confident enough in its output.
XAI and xAI are different things that share a name. XAI stands for explainable AI, the field on this page. xAI is the AI company behind the Grok models. Telnyx offers xAI's five Grok voices on Voice AI Assistants, and Grok voices and transcription through its TTS and STT APIs.