Extensibility means adding capabilities without rebuilding the core. What it means in software, and how AI models and agents are extended with tools and MCP.

Updated October 2026
Extensibility is the ability of a system to take on new capabilities without being rebuilt. In software, new features attach without changes to the core. In AI, extensibility means adding tasks, knowledge or actions to a model or an AI agent, by adapting its weights or by connecting documents and tools, without retraining it from scratch.
An extensible system exposes extension points, such as plugin interfaces, APIs, hooks and event callbacks, where new behavior can attach without editing the code that already works.
D. L. Parnas argued in 1979 for designing software "for ease of extension and contraction", so a program can gain or drop features without a rewrite.
Extensions attach through a published interface, such as a plugin API. A stable interface keeps them compatible: an extension written today keeps working after the core is updated.
In anatomy, extensibility means a muscle's ability to stretch. That sense is unrelated to software and AI.
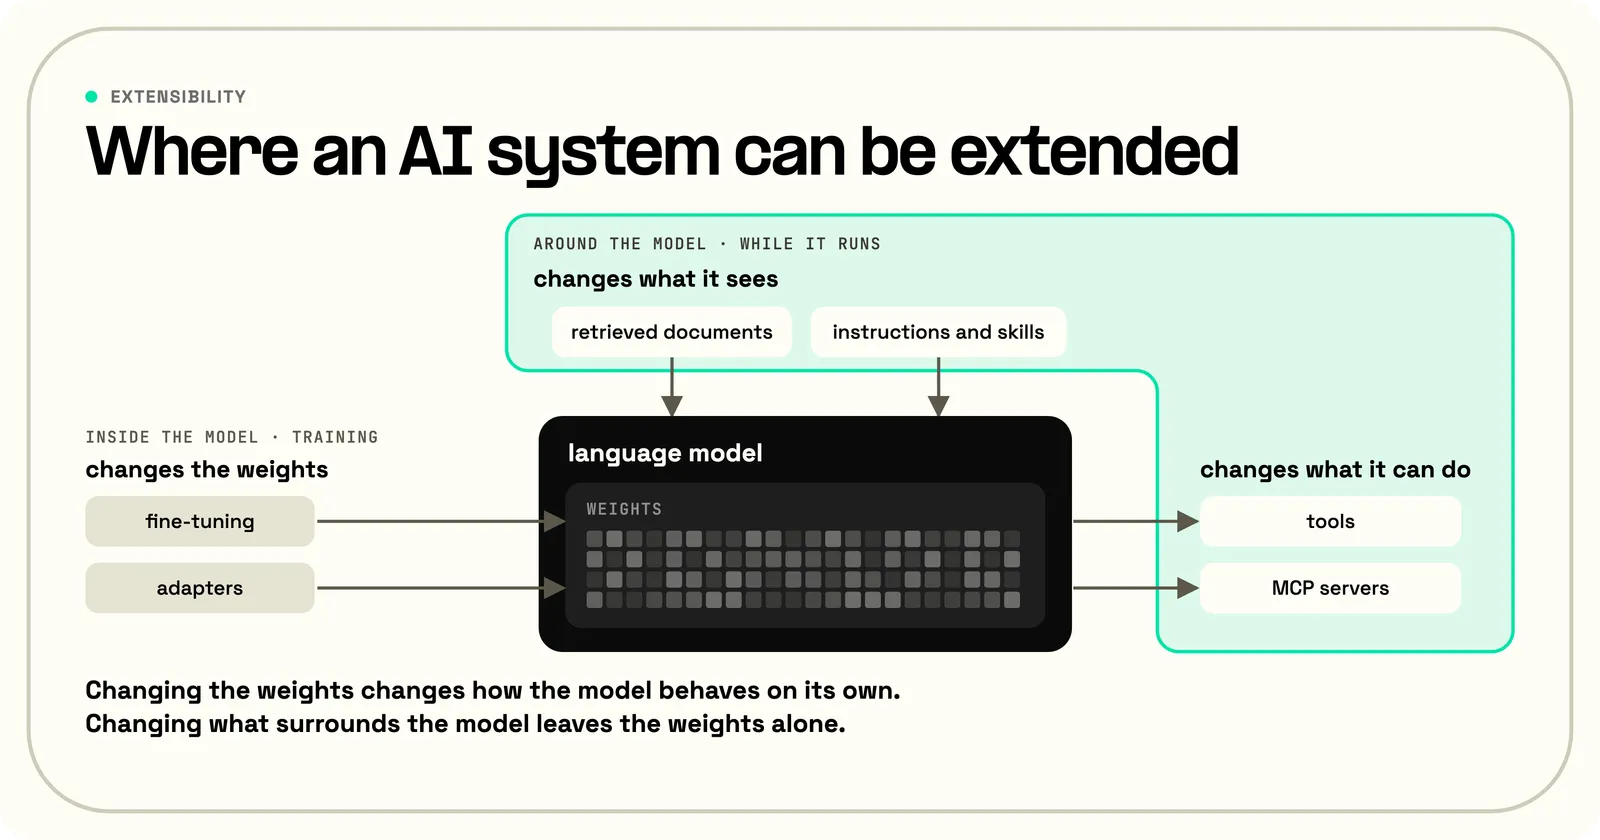
Extensibility in AI works in two places: inside the model, by changing its weights, and around the model, by changing what it can read and what it can do while it runs.
Changing the weights, through fine-tuning, adapters or further training, changes how the model behaves on its own and takes data and compute.
Code Llama was built this way. Its authors started from Llama 2, a general language model, and trained it further on 500 billion to 1 trillion tokens, mostly code.
Changing what surrounds the model leaves the weights alone: retrieved documents and instructions change what it sees, and tools change what it can do, from the next request onward.
Each kind of capability has a natural home, shown here for a support assistant at an online store:
Lewis and colleagues updated their retrieval model's knowledge by swapping its document index. They asked it about 82 world leaders who changed between 2016 and 2018.
With the 2016 index, it answered 70% of questions about 2016 leaders correctly. After a swap to the 2018 index, it answered 68% about 2018 leaders correctly. With the wrong year's index, it scored 12% or lower.
A model that stores knowledge only in its weights needs further training to change what it knows.
An AI model is extended by adapting what it already learned, instead of training a new model for every task.
Transfer learning reuses what a model learned on one task for another. Yosinski and colleagues found that features learned on one image dataset carry over to others.
Fine-tuning continues training a pretrained model on a smaller dataset for the new task. It costs far less than training from scratch, because the model starts with general features it already has.
Full fine-tuning still produces a complete new copy of the model for each task. Adapters avoid that: a small trainable module per task, with the pretrained model frozen.
Houlsby and colleagues describe the result as "a compact and extensible model", where new tasks are added without revisiting old ones.
On the GLUE language benchmark, those adapters came within 0.4% of full fine-tuning while adding 3.6% of the parameters per task.
LoRA freezes the weights and trains small low-rank matrices inside each layer. Against full fine-tuning of GPT-3 175B, its authors report 10,000 times fewer trainable parameters, a third of the GPU memory, and no added delay at inference.
Adapters and LoRA need access to the model's weights. On a hosted model, the open routes are the provider's own fine-tuning service, where one exists, or extensions around the model.
Multi-task learning is the up-front alternative to adding tasks later: one model trains on several related tasks at once, with shared layers.
Caruana showed in 1997 that what one task teaches the shared layers can improve generalization on the others.
Training a model on a new task can overwrite what the model learned for old ones, a failure called catastrophic forgetting. Kirkpatrick and colleagues reduced it by slowing learning on the weights most important to earlier tasks.
An AI agent is extended by giving its language model new things to call or read: tools for actions, retrieval for knowledge, and standard connectors such as the Model Context Protocol (MCP).
With function calling, a developer describes a tool to the model by name, purpose and parameters.
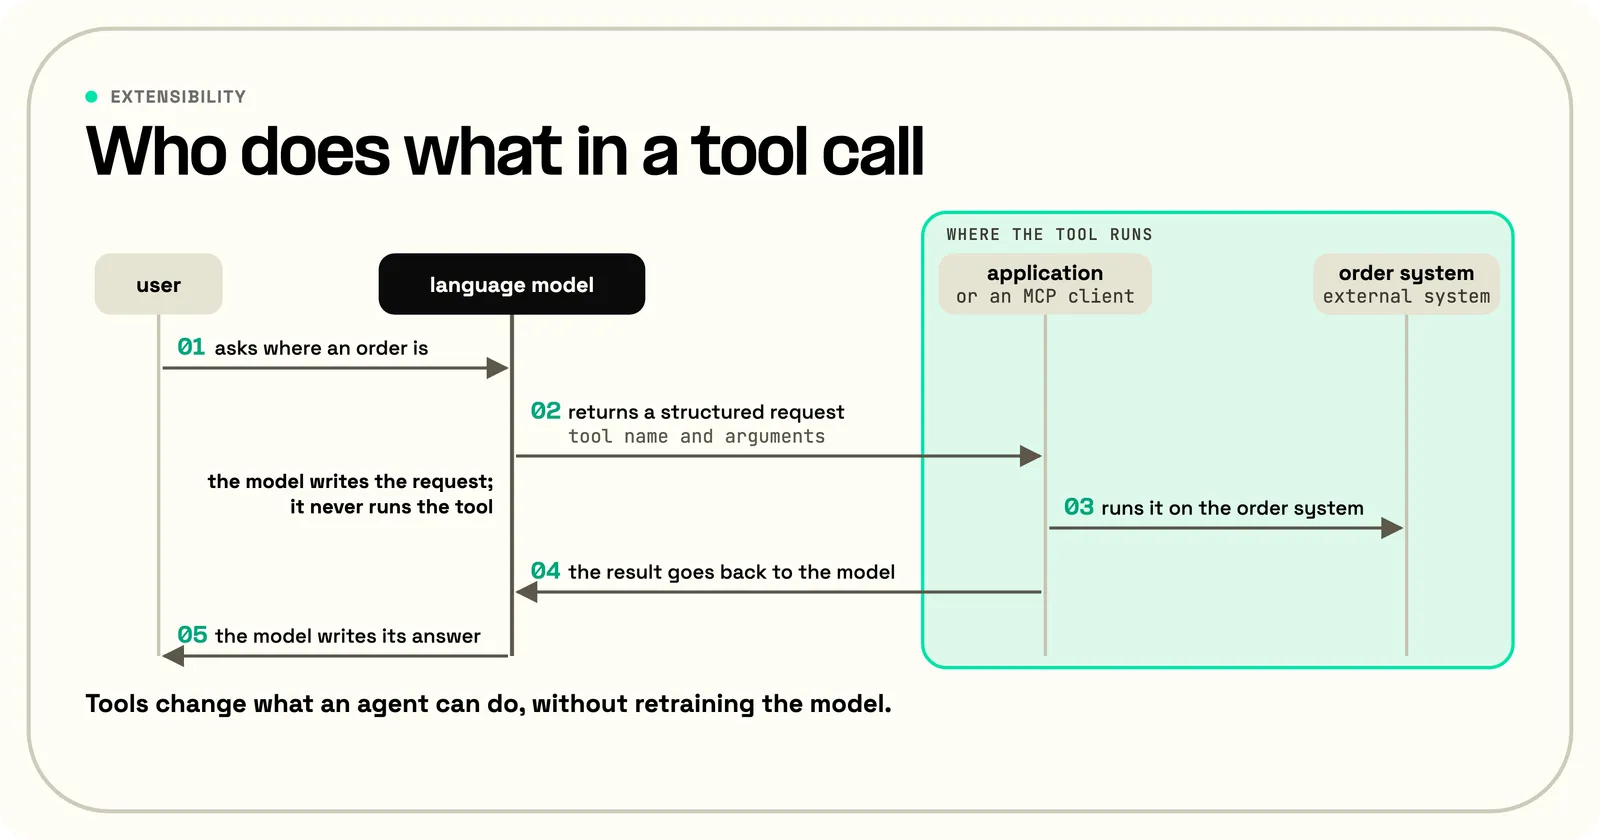
The model never runs the tool itself: it returns a structured request, a tool name plus arguments, and the application executes it. The result goes back to the model.
Current models can call a new tool without retraining; calling it correctly is a separate question. Telnyx Inference documents tool support on every model in its API.
ReAct prompted a model to interleave reasoning with tool calls, with only one or two examples on its two decision-making benchmarks.
Toolformer and Gorilla studied training tool use into a model. The Gorilla authors fine-tuned a model just for writing API calls, because general models often produced wrong arguments or used an API the wrong way.
Retrieval extends what an agent knows without retraining it. In retrieval-augmented generation, the system searches an index at question time and the model writes its answer from the passages it finds.
Retrieval fails when the index goes stale, when the search returns the wrong passage, or when a passage carries planted instructions the model will read. Write access to the index needs the same care as write access to code.
Skills and plugins package instructions, examples and tools for one job, and load only when a task needs them.
Telnyx's agent skills for AI coding assistants teach an assistant to use each Telnyx SDK.
Skills are text the model follows, so they can carry planted instructions. Telnyx's prompt injection scanner flags risky instructions in agent instruction files such as AGENTS.md before an agent relies on them.
The Model Context Protocol is an open standard for connecting AI applications to external systems, which Anthropic open-sourced in November 2024.
An MCP server offers tools, data and prompt templates over JSON-RPC 2.0, so any MCP-capable application can connect to it without custom integration code.
The specification credits the Language Server Protocol, which did the same for code editors.
To the model, an MCP tool is an ordinary function: the MCP client asks the server for its tool list and passes those definitions to the model.
The choice between a built-in tool and an MCP server turns on who maintains the tool, how many applications share it, and whether the team controls the server.
A support assistant that files a ticket mid-call is an example of extensibility in AI. Telnyx voice AI agents connect to Salesforce, Zendesk, ServiceNow and similar systems through built-in integrations.
A coding assistant connected to the Telnyx Local MCP Server can buy phone numbers and set them up for an AI assistant from a chat prompt.
Outside AI, a browser extension is the everyday example: an ad blocker or a password manager adds a feature through the browser's extension interface without changing the browser.
Extensible AI gains speed and reuse, since a new tool or retrieval source works from the next request, at the cost of a larger attack surface and more ways to fail.
Fine-tuning carries two risks. A model trained on a new task can lose an old one, and the training data stays in the weights.
Carlini and colleagues extracted hundreds of verbatim training sequences from GPT-2, including names, phone numbers and email addresses.
Their attack recovered pretraining data; the same risk applies in principle to customer records used for fine-tuning.
Retrieval and tools open the door to indirect prompt injection: instructions planted in data the model reads. LLM-integrated applications "blur the line between data and instructions", as Greshake and colleagues put it.
They showed that planted text can steer the model and "control how and if other APIs are called". Anything a tool or a search returns is untrusted input.
Third-party MCP servers and skills add the same risk one step earlier: the model reads their tool descriptions and instructions as text.
The MCP specification tells clients to treat descriptions of tool behavior as untrusted unless the server is trusted.
A server earns that trust when the team runs it or has vetted who does, when it authenticates its clients, and when its tool definitions are reviewed again after every change.
Servers that declare the capability send a notification when their tool list changes, which gives that review a trigger.
Tools also turn wrong answers into wrong actions: a tool that can delete records will delete the wrong one if the model asks.
The MCP specification says there "SHOULD always be a human in the loop with the ability to deny tool invocations."
Two more controls follow from the same logic: make tools read-only unless they must write, and log every call with its arguments.
In AI guardrails, checks on a tool's inputs can stop a bad call before it runs, and checks on its outputs can stop a bad result before the model reads it.
Each tool call also adds a round trip and sends part of the conversation to another system. Latency and data exposure grow with every extension.
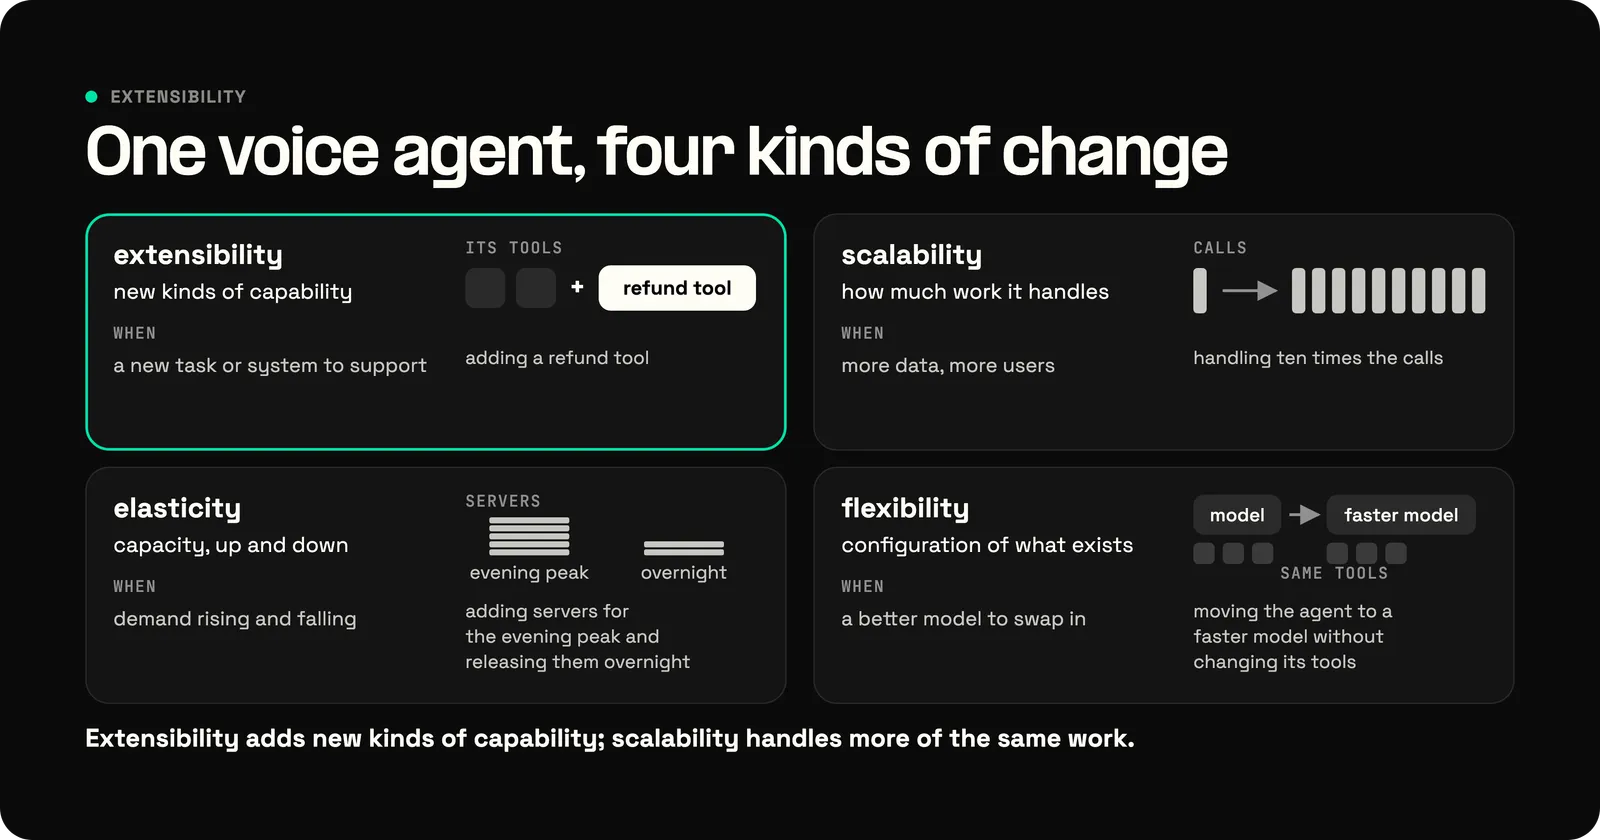
Extensibility is about adding new kinds of capability; scalability is about handling more of the same work, such as more data, more users or a larger model, without losing performance.
Elasticity is capacity that grows and shrinks with demand. NIST's cloud definition describes it as capacity provisioned and released, in some cases automatically, to match demand.
Flexibility is how easily an existing system can be reconfigured, such as swapping one model for another behind the same interface.
For a voice agent, adding a refund tool is extensibility and handling ten times the calls is scalability.
Adding servers for the evening peak and releasing them overnight is elasticity. Moving the agent to a faster model without changing its tools is flexibility.
A voice agent is extended through its tools. On a phone call, each tool has a cost the caller hears: a slow lookup is silence.
Slow lookups should run asynchronously. A standard webhook tool blocks the conversation until it returns; an async tool lets the assistant keep talking and add the result when it is ready.
Each tool should get the narrowest permission its job needs. That permission lives in the credential the tool uses. New tools belong on a test assistant first, especially tools that create, update or delete records.
On a call, the human confirmation is spoken: the agent reads back a change, such as a refund amount, and acts only after the caller agrees.
Telnyx AI Assistants take these kinds of tools, defined once in a Tools Library and shared across assistants:
Built-in integrations connect assistants to CRM, ticketing and IT systems. An assistant can also attach MCP servers, whose tools join the ones above.
Transfer and hangup tools use call control, the commands the Telnyx Voice API exposes for answering, transferring and ending calls.
Code is extensible when new behavior can be added through interfaces it already exposes, without editing the existing code. An extensible program is designed in advance for features its authors have not written yet.
Muscle extensibility is a muscle's ability to stretch beyond its resting length. It shares a word with software and AI extensibility and nothing else.
An AI extension is an add-on that brings AI features into another application, such as a browser or a code editor. Extending an AI system is the reverse direction: adding capabilities to the AI itself.
In software, extensibility and extendability are used as synonyms. Extensible is the established technical term in software design and AI.
Expandability and extendability are the closest synonyms. Scalability is a different property: it means handling more of the same work.
This content was generated with the assistance of AI. Our AI prompt chain workflow is carefully grounded and preferences .gov and .edu citations when available. All content is reviewed by a Telnyx employee to ensure accuracy, relevance, and a high standard of quality.