Few-shot learning trains models to learn new classes from a handful of examples. How N-way K-shot episodes, prototypical networks, and MAML work, and limits.
Updated October 2026
Few-shot learning is a machine learning approach in which a model learns to recognize a new class or perform a new task from only a few labeled examples, often one to five per class. Instead of learning each task from scratch, the model draws on prior knowledge from practice on many related tasks or from a large pretrained model, so a handful of examples is enough to generalize.
That prior knowledge carries most of the load, because a few examples are not enough to train a model the usual way. A model fitted to five examples can classify all five perfectly and still be wrong on most new inputs. Yaqing Wang and colleagues name this as the core problem of few-shot learning: the training error a model minimizes on so little data is an unreliable guide to how it will do on new data. Every few-shot method is a way of supplying the knowledge those few examples cannot.
This content was generated with the assistance of AI. Our AI prompt chain workflow is carefully grounded and preferences .gov and .edu citations when available. All content is reviewed by a Telnyx employee to ensure accuracy, relevance, and a high standard of quality.
The term now covers two related ideas. Few-shot learning in the training sense, the subject of this page, adapts a model to new classes. Few-shot prompting puts a few examples into a language model's prompt and changes no weights at all; a later section compares the two.
Few-shot learning is usually framed as an N-way K-shot task: the model must sort new examples into N classes it has never trained on, given K labeled examples of each. Those labeled examples are the support set, and the new examples to classify are the query set. A 5-way 1-shot task gives one labeled image each of five unseen classes, and asks which of the five a new image belongs to.
Vinyals and colleagues built the experiments of their 2016 matching networks paper around N-way k-shot tasks, and introduced miniImageNet, a benchmark of 60,000 color images in 100 classes, with 600 examples each. Another common benchmark, Omniglot, has 1,623 handwritten characters from 50 alphabets. Both have many classes, which is what a few-shot benchmark needs: thousands of different small tasks can be sampled from them, with the few labeled examples drawn fresh for each task.
The contrast is with standard supervised learning. Fei-Fei, Fergus, and Perona opened their 2006 paper on one-shot learning by noting that learning visual models of object categories notoriously requires hundreds or thousands of training examples. Their Bayesian method learned categories from one or a handful of images by starting from knowledge of previously learned categories, the same idea later few-shot methods build on.
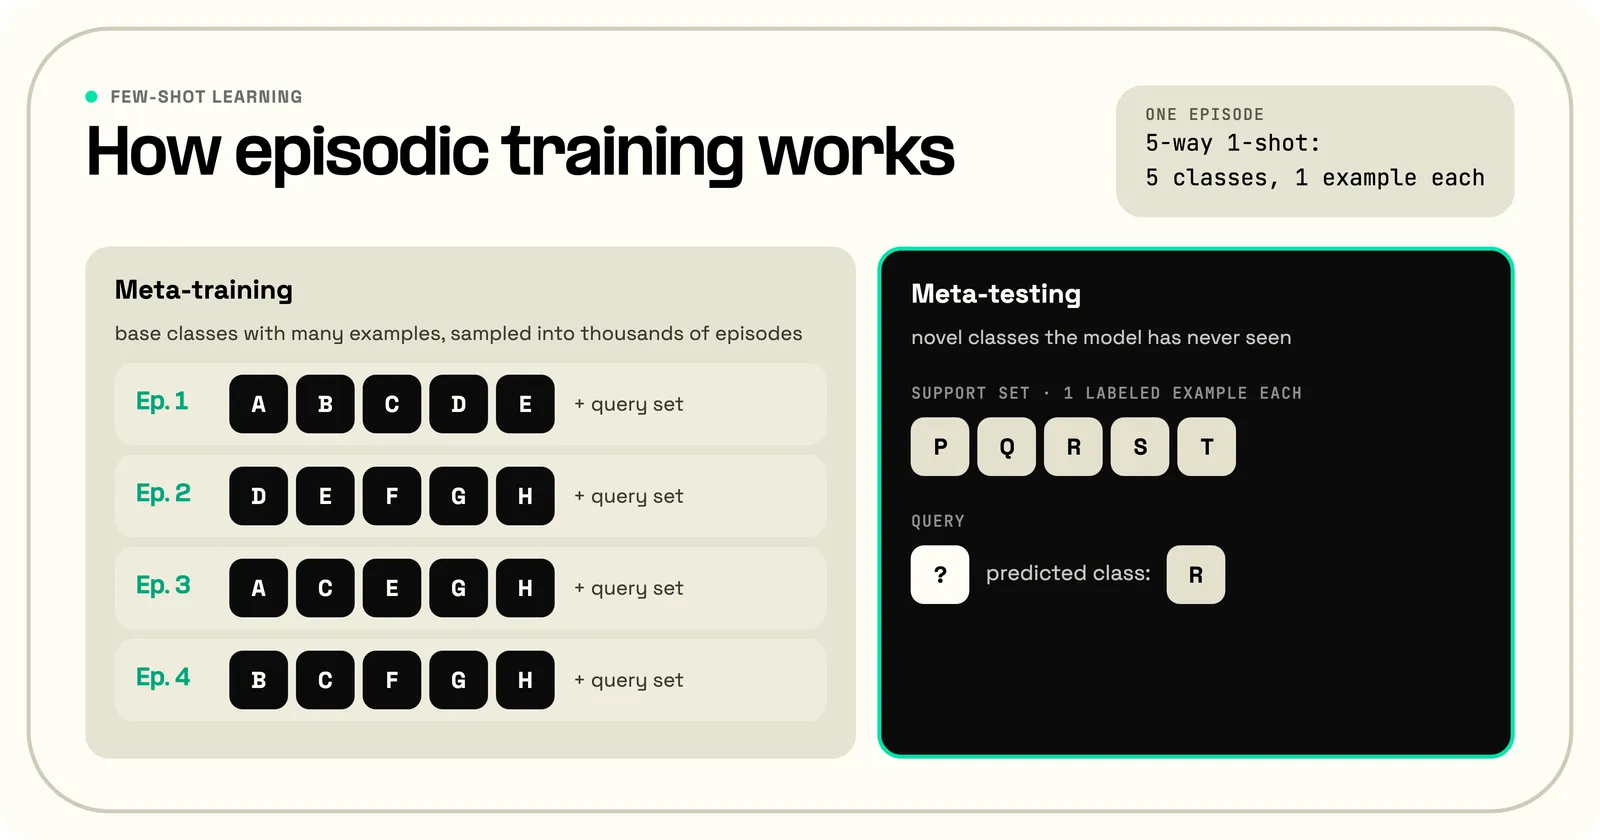
Few-shot learning methods built on meta-learning, or learning to learn, work by episodic training. The model practices on many small tasks drawn from classes with plenty of data, so that it gets good at learning new classes quickly.
Each training batch, called an episode, mimics the few-shot task by sampling a few classes and a few examples of each, as Snell and colleagues describe it. Their reasoning is that training under test conditions improves generalization. Later work found that models trained without episodes can match episodic methods.
Training and testing use different classes:
The model never learns the novel classes in the usual sense. It learns how to use a support set, and that skill is what carries over. Episodic training is one route, and on this page meta-learning means that route. The other route is pretraining a model on a large dataset and then fine-tuning it, covered below.
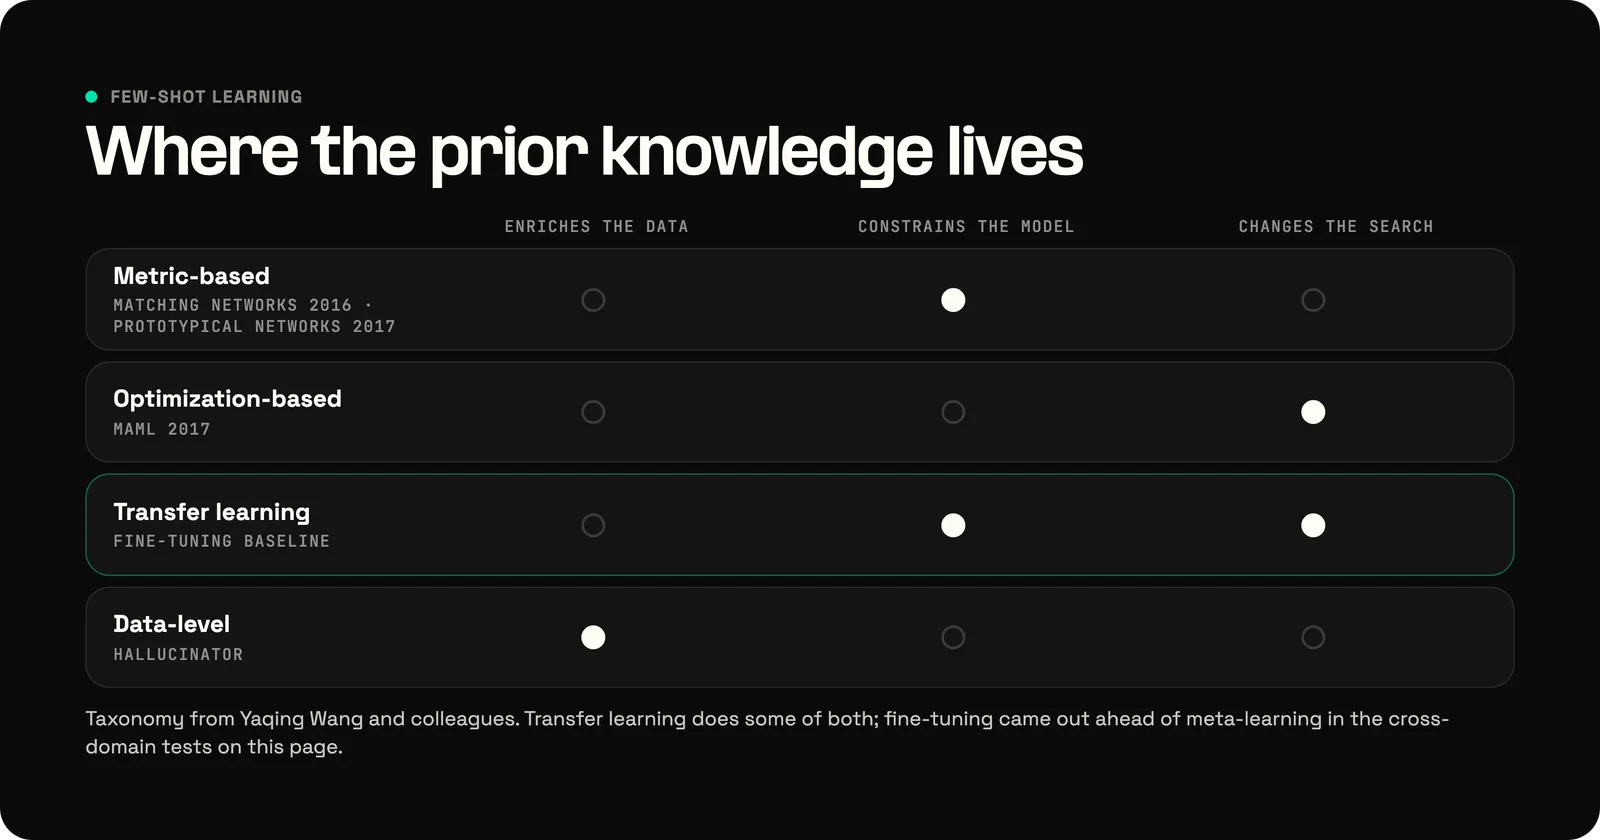
Few-shot learning methods differ in where they put the prior knowledge. Yaqing Wang and colleagues sort them by whether that knowledge enriches the data, constrains the model, or changes how the model searches for a solution. The four families below map onto that split: metric-based methods constrain the model, optimization-based methods change the search, transfer learning does some of both, and data-level methods enrich the data.
Metric-based methods learn an embedding, a mapping from inputs to vectors, in which examples of the same class sit close together, then classify a query by its distance to the support set. Matching networks map a small labeled support set and an unlabeled example to its label without any fine-tuning on the new classes.
Prototypical networks simplify the idea. Snell and colleagues take each class's prototype to be the mean of its support examples in the learned embedding space, and assign a query to the class with the nearest prototype. Their analysis showed that simple design decisions could beat more complicated architectures. The choice of distance mattered most: Euclidean distance greatly outperformed the more common cosine similarity. The embedding itself is a neural network, a convolutional one in the original image experiments, trained end to end by gradient descent across the episodes.
Optimization-based methods learn a starting point from which a few gradient steps solve a new task. Model-agnostic meta-learning (MAML), from Finn, Abbeel, and Levine in 2017, trains a model's initial parameters for fast adaptation. A small number of gradient steps on a small amount of data from a new task then produces good performance on it. In the authors' words, the method trains the model to be easy to fine-tune. Because it only assumes training by gradient descent, MAML applies to classification, regression, and reinforcement learning alike.
Transfer learning methods pretrain an ordinary classifier on the base classes, then fine-tune a small part of it, often only the final layer, on the novel classes' few examples. Chen and colleagues found that such a baseline was competitive with state-of-the-art meta-learning methods on the miniImageNet and CUB benchmarks. Deeper feature networks shrank the differences between methods, and on a cross-domain test the fine-tuning baseline compared favorably against the specialized algorithms.
Data-level methods use prior knowledge to create more training examples, for instance by altering the few labeled examples or by generating new ones. Yu-Xiong Wang and colleagues trained a "hallucinator" jointly with a meta-learner to produce extra examples of each new class. It raised classification accuracy by up to 6 points when only one example was available.
Large pretrained models give few-shot learning a stronger starting point than training on the base classes alone. Hu and colleagues showed in 2022 that a simple three-stage pipeline performs well. A transformer is pretrained on external unlabeled data, meta-trained on the base classes, and then fine-tuned on the novel task's few labeled examples. It did well on standard benchmarks, including CDFSL, the cross-domain benchmark of Guo and colleagues described under the limits below.
Models pretrained on image and text pairs go further. CLIP, from Radford and colleagues in 2021, classifies images into categories named in plain language without any training examples, and is often competitive with a fully supervised baseline. Its authors also found that zero-shot CLIP matches the average performance of a 4-shot linear classifier trained on the same features. One or two labeled examples per class can therefore do worse than naming the class well.
Taken together, that evidence suggests an order to try things in. It is a judgment, not a tested result. The first thing to try is a strong pretrained model with a simple classifier, such as zero-shot labels or nearest prototype over its embeddings. Fine-tuning part of the model comes next if the new classes look unlike its training data. That is the case where Chen and colleagues, and Guo and colleagues on the cross-domain benchmark covered below, found fine-tuning ahead of meta-learning.
Defect detection often does not fit the class framing at all, because a defect is anything that departs from normal. Anomaly detection treats it that way. WinCLIP, from Jeong and colleagues in 2023, extends CLIP to zero-shot and few-normal-shot anomaly classification and segmentation for industrial quality inspection, working from as few as one normal image.
Zero-shot, one-shot, and few-shot learning differ by how many labeled examples of a new class the model gets: none, one, or a few. One-shot learning is few-shot learning with K = 1, and most few-shot methods handle it by the same mechanism. The 2006 work by Fei-Fei and colleagues is an early example: their method learned a visual category from a single image by updating a prior built from previously learned categories.
Zero-shot learning has no labeled examples of the new class at all, so the model needs another description of it, such as a list of attributes or a text label. Snell and colleagues showed that prototypical networks extend to this setting: a prototype computed from a class's attribute description takes the place of the mean of support examples, and the method reached state-of-the-art results at the time on the CUB birds dataset. Vision-language models such as CLIP replace attributes with plain-language class names, and offer a newer route to zero-shot image classification.
| Setting | Labeled examples per new class | What the model uses instead |
|---|---|---|
| Zero-shot | 0 | A description of the class, such as attributes or text |
| One-shot | 1 | One example, plus prior knowledge from other classes |
| Few-shot | A few, commonly 5 | A small support set, plus prior knowledge |
Few-shot learning is used where new classes keep appearing with few labeled examples, such as rare objects in photographs, crop diseases, satellite scenes, skin lesions, and chest X-rays. Classification, which assigns a whole image to a class, is the setting most methods on this page were built for. Detection must also locate each object in the image, and has its own few-shot methods.
Xin Wang and colleagues studied few-shot object detection on PASCAL VOC, COCO, and LVIS. Fine-tuning only the last layer of an existing detector, on a small balanced set of base and rare classes, outperformed meta-learning methods by roughly 2 to 20 points on the benchmarks of the time.
Specialized imagery is a second area of published work. The benchmark built by Guo and colleagues tests few-shot methods on crop disease images, satellite images, dermatology images, and radiology images, areas where collecting labeled data is slow and costly.
Other domains use few-shot learning too:
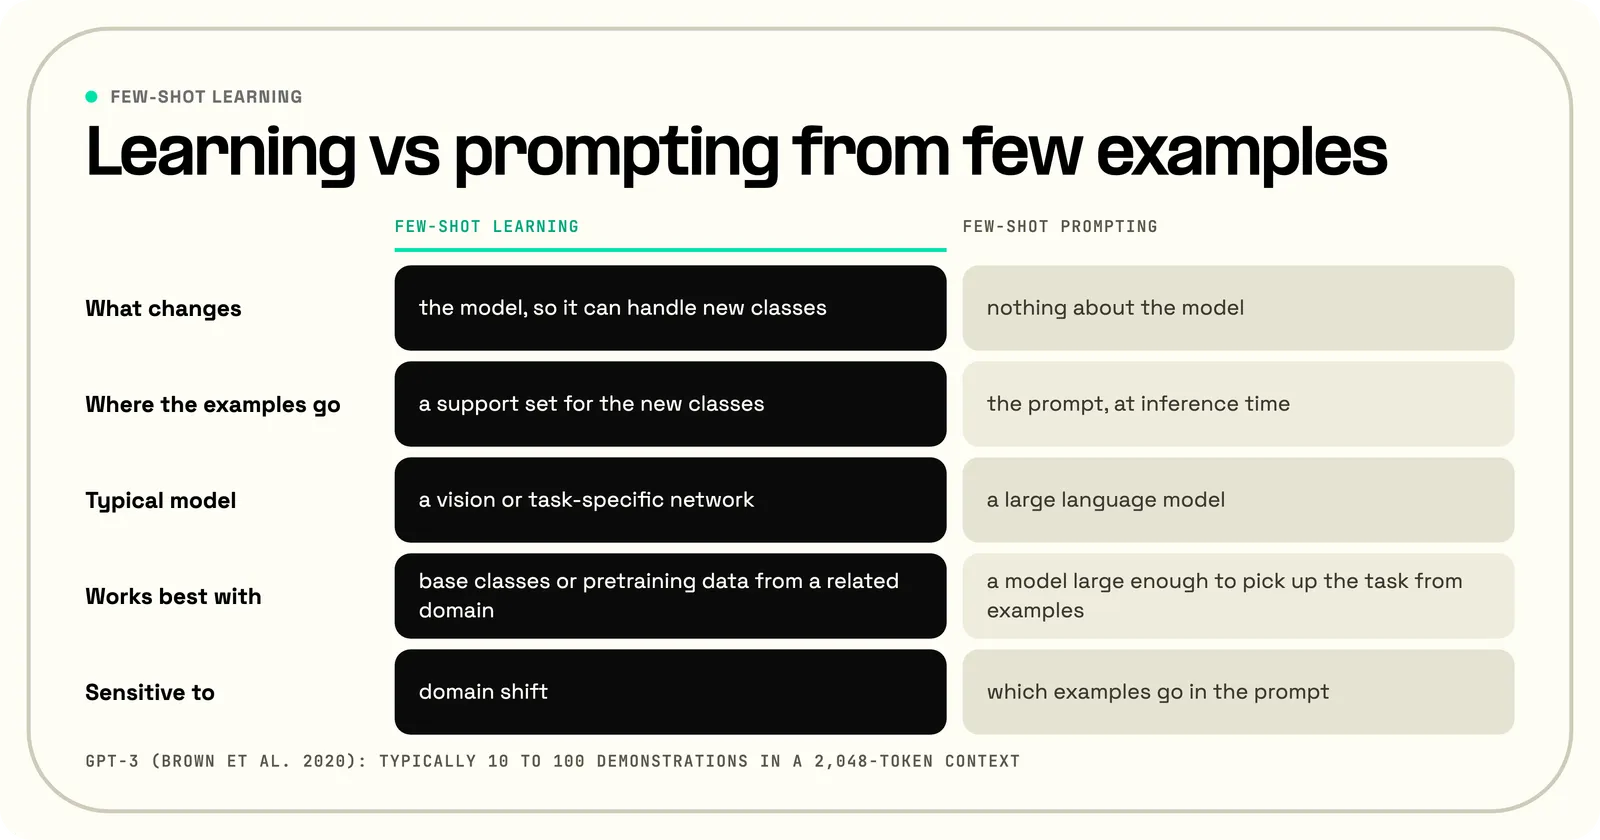
Few-shot learning changes a model so it can handle new classes, while few-shot prompting gives a large language model a few examples in its prompt and changes nothing about the model. Brown and colleagues defined the prompting setting with GPT-3 in 2020: the model receives a few demonstrations of the task at inference time, and no weight updates are allowed. They allowed as many demonstrations as fit in GPT-3's 2,048-token context window, typically 10 to 100, and called this in-context learning. Newer language models have longer context windows, so that number is no longer a fixed limit.
The two approaches fail in different ways. Few-shot learning works best with base classes or pretraining data from a related domain, and degrades under domain shift. Few-shot prompting needs a model large enough to pick up the task from examples, and its results depend on which examples go in the prompt:
A team picks between them by what it can change. With a language model behind an API, prompting is the cheapest option and needs no training data pipeline, though some providers also offer hosted fine-tuning. With its own model and a set of related labeled classes, few-shot learning gives a model that adapts without long prompts. One-shot prompting is the single-example case of the prompting approach.
Few-shot learning works best when the new classes resemble the classes the model trained on, and it degrades when they do not. Guo and colleagues measured this domain shift: on their benchmark of images unlike natural photographs, every meta-learning method they tested underperformed simple fine-tuning, which led by 12.8% in average accuracy across their tests. In some cases meta-learning did worse than a network with random weights.
The absolute numbers matter more than the gap. On chest X-rays, in a 5-way 5-shot task where guessing scores 20%, prototypical networks reached 24.05% and fine-tuning all layers 25.97%. On crop disease images, closer to natural photographs, fine-tuning reached 89.25%. Under a large domain shift, every method can fail.
Overfitting to the support set is the second limit. With so few examples, a model can fit noise in them, which is the unreliable-training-error problem Yaqing Wang and colleagues describe. A common remedy is to update fewer parameters. In few-shot object detection, Xin Wang and colleagues froze the detector and fine-tuned only its last layer on a small balanced set of base and novel classes.
Benchmarks themselves are a third limit. Results depend heavily on which few examples were drawn. The few-shot object detection study found accuracy varied so much between samples that published comparisons were unreliable. Its authors revised the protocol to average over several sampled groups of training examples. A team evaluating a few-shot method on its own data can follow the same practice: run several random draws of the support set and report the spread, not a single score.
A few-shot example is one of the few labeled examples a model gets for a new class or task. In few-shot learning, the few-shot examples form the support set, for example five labeled images per class. In few-shot prompting, they are input and output pairs written into a language model's prompt.
Zero-shot learning recognizes a new class with no labeled examples of it, using a description such as attributes or a text label instead. Few-shot learning gets a small number of labeled examples, often one to five per class. Both rely on prior knowledge learned from other classes.
One-shot learning is few-shot learning with exactly one labeled example per new class. A one-shot model compares new inputs against that single example, often in a learned embedding space. Fei-Fei, Fergus, and Perona showed in 2006 that a visual category could be learned from one image this way, using knowledge from previously learned categories.
Few-shot learning in text classification sorts text into categories from a few labeled examples per category. Training methods such as prototypical networks can do it over text embeddings. Few-shot prompting can also do it: a large language model reads a few labeled examples in its prompt and labels new text without any training.
Few-shot prompting fits when the task is in text, a capable language model is available, and there is no time or data to train. Training a few-shot model fits when the data is not text, such as images or sensor signals. It also fits when the model must run without a large language model, or when related labeled classes are available to learn from.
Few-shot learning is not the same as fine-tuning, though it can use fine-tuning. Fine-tuning means continuing to train a pretrained model on new data. Few-shot learning is the goal of handling a new class from a few examples, and fine-tuning the last layer is one way to reach it; metric-based methods reach it without any fine-tuning.