


A gated linear unit (GLU) gates one linear projection with another. Learn the GLU formula, its SwiGLU and GEGLU variants, and which LLMs use them.

Updated August 2026
A gated linear unit is a small change to how a neural network layer works, and a consequential one: most modern large language models now use one in place of the plain activation function in their feed-forward layers. The reason is empirical. When researchers swapped the usual ReLU or GELU for a gated linear unit, the models trained better.
Quick answer: A gated linear unit (GLU) is a neural network component that controls how much information passes between layers. It makes two linear projections of the input and uses one, squashed to a 0-to-1 range, as a gate on the other, written GLU(a, b) = a ⊗ σ(b). A GLU is not a pointwise activation like ReLU; it is a gating mechanism, and its variants SwiGLU and GEGLU sit in the feed-forward layers of most modern large language models.
A gated linear unit (GLU) is a gating mechanism, a small structure a network uses to decide, element by element, how much information to let through to the next layer. Instead of treating every value the same way, it learns a set of gates and applies them selectively, so the layer can emphasize the signal that matters and damp the rest.
In a machine learning context, GLU stands for gated linear unit. It is not glucose, the amino acid glutamate, or the GLUE language benchmark, which share the letters but are unrelated. The mechanism was introduced for language modeling in 2016, and today its variants are a standard building block inside large language models.
This content was generated with the assistance of AI. Our AI prompt chain workflow is carefully grounded and preferences .gov and .edu citations when available. All content is reviewed by a Telnyx employee to ensure accuracy, relevance, and a high standard of quality.
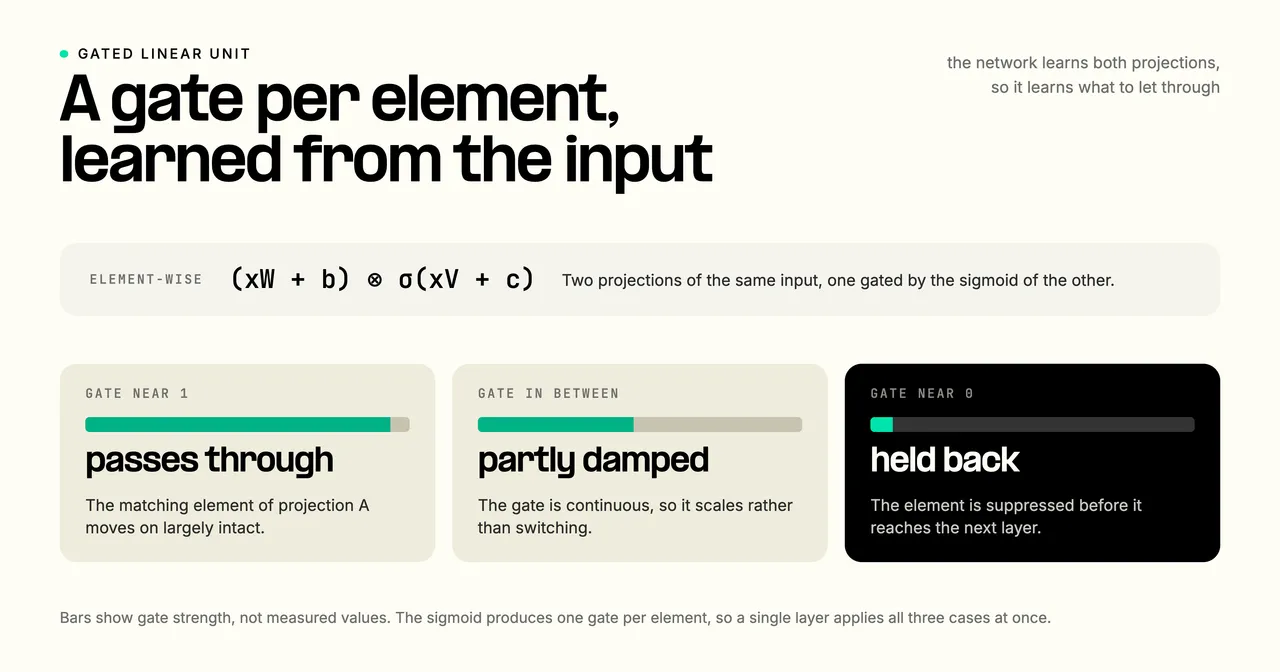
The GLU formula is GLU(a, b) = a ⊗ σ(b), where a and b are two linear projections of the input, σ is the sigmoid function, and ⊗ is element-wise multiplication. Written with weights, a layer computes (xW + b) ⊗ σ(xV + c): two projections of the same input x, one gated by the sigmoid of the other.
The sigmoid turns the second projection into values between 0 and 1, one per element. Multiplying element-wise, those values act as gates. Near 1, the matching element of the first projection passes through; near 0, it is held back. The network learns both projections, so it learns what to let through and what to suppress.
That structure gives GLU a property plain activations lack: a linear path for the signal. Because the first projection is never squashed, gradients flow back through it more freely during backpropagation, which helps training in deep networks.
The gate is the same idea used in a recurrent network and its LSTM cells: a learned, per-element control over what information moves on. Applied during a forward pass, it lets each layer keep the parts of the signal that matter and damp the rest, rather than pushing everything through one fixed function. The original design used convolutions rather than plain linear layers, but the gating idea is the same.
GLU is often listed among activation functions, but it is more precisely a gating mechanism, and the distinction matters. A standard activation like ReLU is pointwise: it takes one number and returns one number. A GLU takes a vector, makes two projections of it, and combines them, so it carries learnable weights of its own.
The practical difference is where it sits in the network. A pointwise activation is applied after a linear layer, on the values that layer produced. A GLU replaces that structure with its own two-projection gate. This is why swapping a plain activation for a GLU variant changes the shape of a feed-forward layer, not just the function applied inside it.
The comparison people usually reach for is GLU against ReLU. A ReLU keeps a value or zeroes it based only on that value's sign, the same rule everywhere. A GLU decides how much of each value to keep based on a second, learned projection of the whole input, so the gating adapts to context rather than following one fixed threshold. That flexibility is the reason GLU variants have displaced plain activations in many recent models.
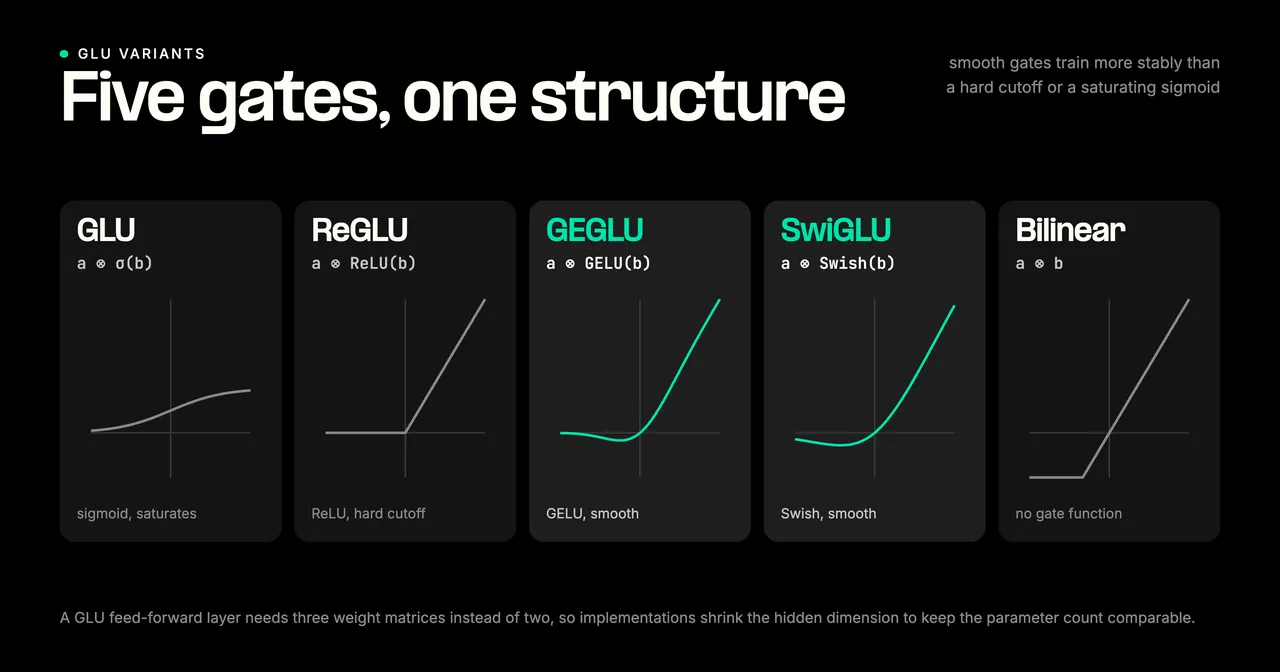
GLU variants keep the same gating structure but replace the sigmoid gate with a different function. Noam Shazeer's 2020 paper GLU Variants Improve Transformer tested several and found that some beat the usual ReLU and GELU activations in a Transformer's feed-forward sublayers.
| Variant | Gate function | Formula |
|---|---|---|
| GLU | Sigmoid | a ⊗ σ(b) |
| ReGLU | ReLU | a ⊗ ReLU(b) |
| GEGLU | GELU | a ⊗ GELU(b) |
| SwiGLU | Swish (SiLU) | a ⊗ Swish(b) |
| Bilinear | None (linear) | a ⊗ b |
SwiGLU and GEGLU are the two most widely adopted. Both use a smooth gate: Swish and GELU are smooth, non-monotonic functions, which tends to train more stably than the hard cutoff of a ReLU gate or the saturation of a sigmoid. The gains are empirical. Shazeer found the variants by testing them, not by deriving them from theory, which is common for activation-function choices.
Most recent large language models use a GLU variant in their feed-forward layers instead of a plain activation. LLaMA and PaLM use SwiGLU, and Gemma uses GeGLU. The pattern spread after Shazeer's 2020 result and is now close to a default in new transformer architectures.
There is a cost to account for. A GLU-based feed-forward layer needs three weight matrices instead of the usual two, one extra for the second projection. To keep the parameter count comparable, implementations shrink the hidden dimension, typically by about a third, so the added gate does not make the model larger.
One common mix-up is worth clearing up: GPT-3 does not use a GLU variant. Its feed-forward layers use GELU, a pointwise activation, not a gated one. The near-identical names GELU and GEGLU make the two easy to confuse, but a GEGLU layer is a gated structure while a GELU is a single function applied to one value.
GLU stands for gated linear unit, a gating mechanism used in neural networks to control how much information passes between layers. In a machine learning or deep learning context it is not glucose, the amino acid glutamate, or the GLUE benchmark, which share the letters but are unrelated concepts.
GLU and GELU are different despite the near-identical names. GELU, the Gaussian Error Linear Unit, is a pointwise activation function that acts on one value at a time. GLU, the gated linear unit, is a gating mechanism that combines two projections of the input. They can even work together: GEGLU is a GLU variant that uses GELU as its gate function.
PyTorch ships GLU directly as torch.nn.GLU. It takes one tensor, splits it in half along a chosen dimension, and returns the first half multiplied by the sigmoid of the second. To build a variant such as SwiGLU, you create the two projections yourself and replace the sigmoid with the variant's gate function, since PyTorch's built-in module uses the original sigmoid gate.
