A gated recurrent unit (GRU) is a recurrent network cell with two gates. Learn how it works, the update and reset gates, and how a GRU compares to an LSTM.

Updated August 2026
A gated recurrent unit is a streamlined answer to a long-standing problem: plain recurrent networks lose track of what happened early in a sequence. Reading a long sentence, the network's memory of the first words fades before it reaches the last, the vanishing gradient problem. The GRU fixes this with two small gates that decide what to keep and what to drop, and it does the job with less machinery than the LSTM that came before it.
Quick answer: A gated recurrent unit (GRU) is a type of recurrent neural network cell that processes sequences one step at a time while carrying a memory of what it has seen. It uses two gates, an update gate and a reset gate, to control what information to keep and what to discard, which lets it learn long-range patterns that plain recurrent networks lose. A GRU is a simpler alternative to the LSTM, with two gates instead of three and no separate memory cell.
A gated recurrent unit (GRU) is a recurrent neural network cell that handles sequential data by keeping a running summary of the sequence in a hidden state and updating it at each step through gates. Kyunghyun Cho and colleagues introduced it in 2014 as a lighter alternative to the LSTM.
In a machine learning context, GRU stands for gated recurrent unit. It is not the Russian intelligence agency or the character from Despicable Me, which share the letters. The GRU is a building block for models that work on ordered data: text, audio, and time series.
A GRU works by using two gates to decide, at every time step, how much of its memory to keep and how much to replace. The update gate controls how much of the new information enters the hidden state, and the reset gate controls how much of the past is used to form that new information. Each gate is a small learned layer squashed to a value between 0 and 1, the same gating idea a gated linear unit uses in feed-forward layers, applied here to a sequence over time.
The cell runs four calculations per step. Using h for the hidden state, x for the input, σ for sigmoid, and ⊙ for element-wise multiplication:
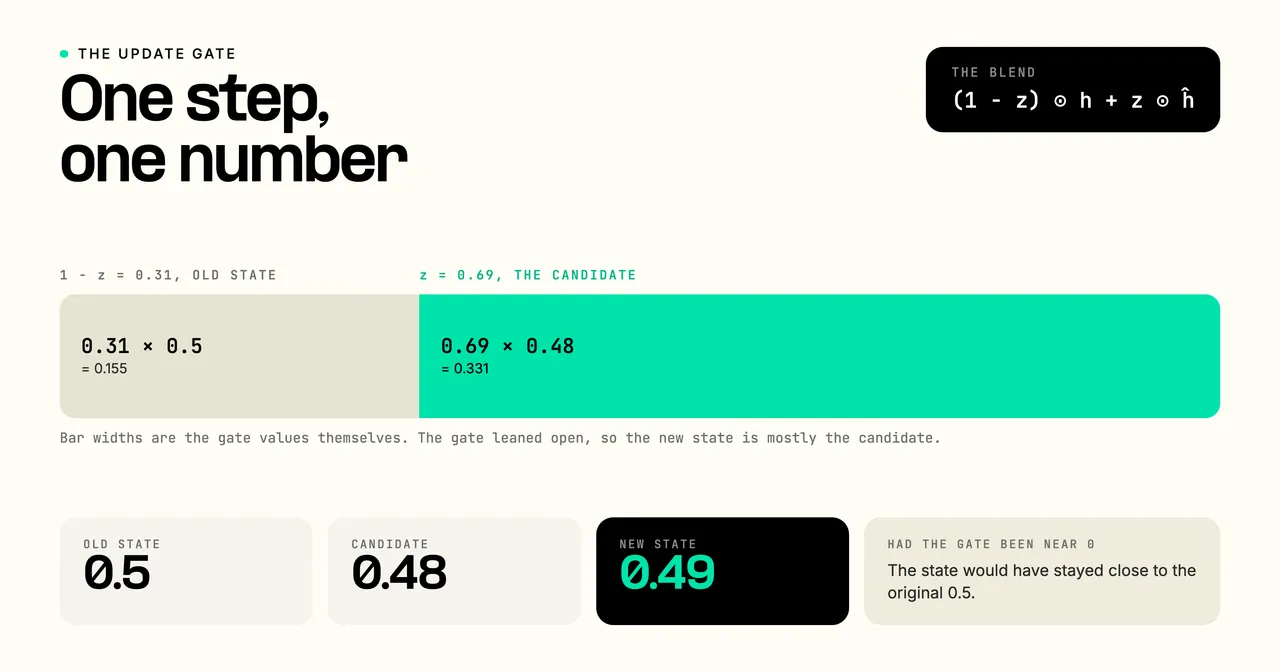
z_t = σ(W_z · [h_{t-1}, x_t])r_t = σ(W_r · [h_{t-1}, x_t])ĥ_t = tanh(W · [r_t ⊙ h_{t-1}, x_t])h_t = (1 - z_t) ⊙ h_{t-1} + z_t ⊙ ĥ_tThe last line is the heart of it. When the update gate z_t is near 0, the cell keeps its old state almost unchanged; when it is near 1, it swaps in the fresh candidate. The reset gate decides how much of the past feeds that candidate, so near 0 it lets the cell start a new thought and forget what came before.
A single-value step makes the blend concrete. Say the old state is h = 0.5, the update gate opens to z = 0.69, and the candidate works out to 0.48. The new state is (1 - 0.69) × 0.5 + 0.69 × 0.48 = 0.49, mostly the candidate because the gate leaned open. Had the gate been near 0, the state would have stayed close to the original 0.5. A real GRU runs this same blend for every element of the hidden state at once.
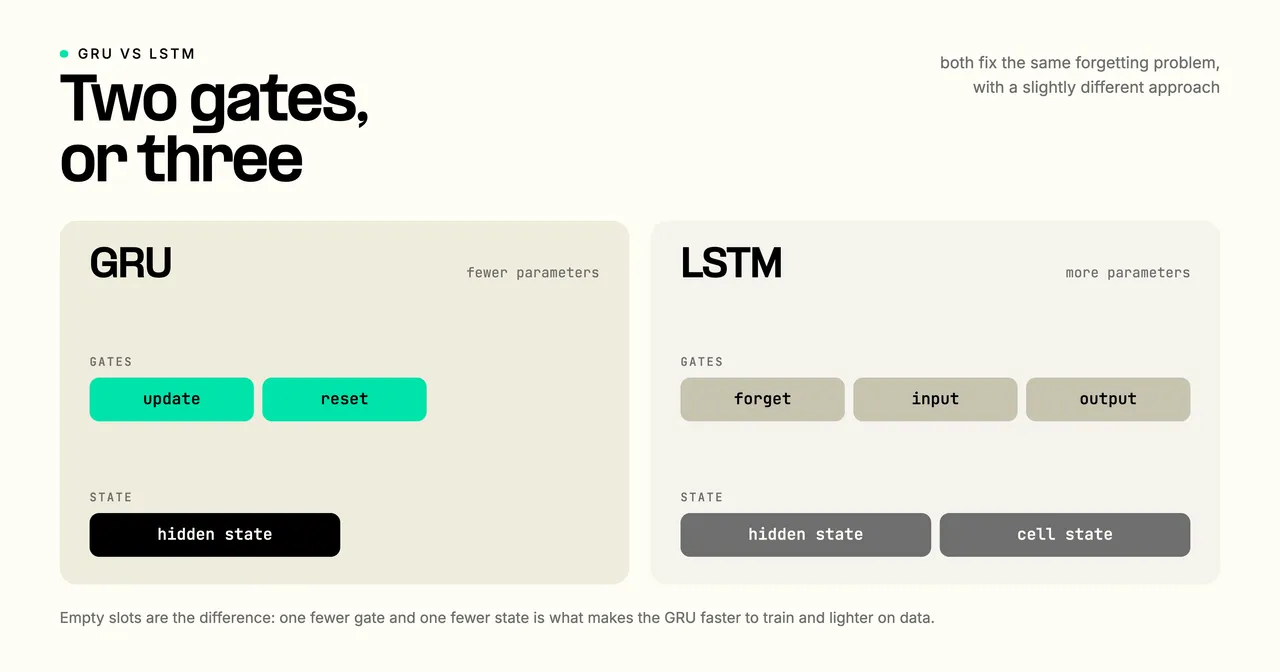
The main difference is that a GRU is simpler: it uses two gates and one state, while an LSTM uses three gates and two. Both were built to fix the same forgetting problem in recurrent networks, and both do it with gates, but with a slightly different approach.
| GRU | LSTM | |
|---|---|---|
| Gates | 2 (update, reset) | 3 (forget, input, output) |
| State | Hidden state only | Hidden state and a separate cell state |
| Parameters | Fewer | More |
| Speed | Faster to train | Slower to train |
| Long dependencies | Strong | Sometimes stronger on very long sequences |
The practical read is a trade. A GRU trains faster and needs less data because it has fewer parameters, which often makes it the better first choice. An LSTM's extra gate and separate memory cell can hold information over longer stretches, so it can win on tasks with very long dependencies. Neither is universally better; the right pick depends on the sequence and the data budget.
The parameter gap is concrete. An LSTM carries four sets of weights per layer, its three gates plus the candidate state, while a GRU carries three. For the same hidden size, that makes a GRU about a quarter smaller, which is what makes it quicker to train and lighter on data.
As a rule of thumb, reach for a GRU first on shorter sequences and smaller datasets: a sentiment classifier over product reviews, or a demand forecast over a short window. Reach for an LSTM when information from far back in a long sequence has to survive to the end, such as modeling a long document or a series with long seasonal cycles. When you are unsure, the cheaper option is a reasonable default, then compare.
The evidence supports that pragmatism. A 2014 comparison by Chung and colleagues found GRUs and LSTMs performed comparably across several sequence tasks, with neither a clear winner, so the smaller and faster GRU is often the sensible starting point.
A GRU eases the vanishing gradient problem by giving the hidden state a near-direct path from one step to the next. In a plain recurrent network, the signal from early steps is multiplied by small numbers again and again during backpropagation through time, so it shrinks toward zero and the network fails to learn long-range links.
The GRU's update rule, h_t = (1 - z_t) ⊙ h_{t-1} + z_t ⊙ ĥ_t, changes that. When the update gate stays near 0, the old state passes forward almost untouched, and so does its gradient. The gate lets the cell hold a memory across many steps without the repeated shrinking, which is the same reason the LSTM works. It reduces the problem rather than removing it; very long sequences can still strain a GRU.
GRUs are used for tasks built on ordered data, where each step depends on what came before. The gating that preserves memory across a sequence is what makes them fit these jobs:
For very long sequences, the transformer has largely replaced recurrent cells like the GRU in state-of-the-art systems, because it processes a whole sequence in parallel rather than step by step. GRUs remain a strong, efficient choice for smaller models and shorter sequences.
GRU stands for gated recurrent unit, a recurrent neural network cell used for sequential data. In a deep learning context it does not refer to the Russian intelligence agency, the São Paulo airport code, or the Despicable Me character, which share the abbreviation but are unrelated.
A GRU has two gates: the update gate and the reset gate. The update gate decides how much of the previous hidden state to keep versus replace, and the reset gate decides how much of the past to use when forming the new candidate state. This is one fewer gate than an LSTM, which uses three.
PyTorch provides a GRU directly as torch.nn.GRU. You give it an input size and a hidden size, and it runs the full sequence through the update and reset gates for you. Note that PyTorch labels the update gate in the opposite direction from the equations above, so check the documentation when comparing its formulas to a textbook.
This content was generated with the assistance of AI. Our AI prompt chain workflow is carefully grounded and preferences .gov and .edu citations when available. All content is reviewed by a Telnyx employee to ensure accuracy, relevance, and a high standard of quality.


