Gradient boosting builds a model from many small trees, each fixing the errors of the last. How GBMs work, XGBoost vs random forest, and Python code.
Updated October 2026
Gradient boosting is a machine learning technique that builds a prediction model one step at a time. Each step adds a small model, usually a decision tree, trained to correct the errors left by the steps before it. The finished model adds up the predictions of every step. In machine learning, GBM stands for gradient boosting machine, a model trained this way.
Each tree in a GBM is too simple to predict well on its own, yet a few hundred of them added in sequence make one of the most accurate models for tables of data.
In a 2022 benchmark of 45 tabular datasets, with every model tuned, tree-based models such as XGBoost still beat deep neural networks on tables of about 10,000 rows.
This content was generated with the assistance of AI. Our AI prompt chain workflow is carefully grounded and preferences .gov and .edu citations when available. All content is reviewed by a Telnyx employee to ensure accuracy, relevance, and a high standard of quality.
Gradient boosting is a form of boosting, the family of methods that train simple models in sequence. Each new model concentrates on what the combined model still gets wrong.
In gradient boosting, each new model learns the negative gradient of a loss function: the direction the predictions should move to lower the error. Jerome Friedman of Stanford introduced the method in 2001 in Greedy function approximation.
The loss is a choice, so the same algorithm covers regression with squared or absolute error and classification with log loss.
Gradient boosting starts from one constant prediction, then repeats a single step: fit a small tree to the current errors, and add a fraction of that tree's prediction to the model.
For regression with squared error, each round runs like this:
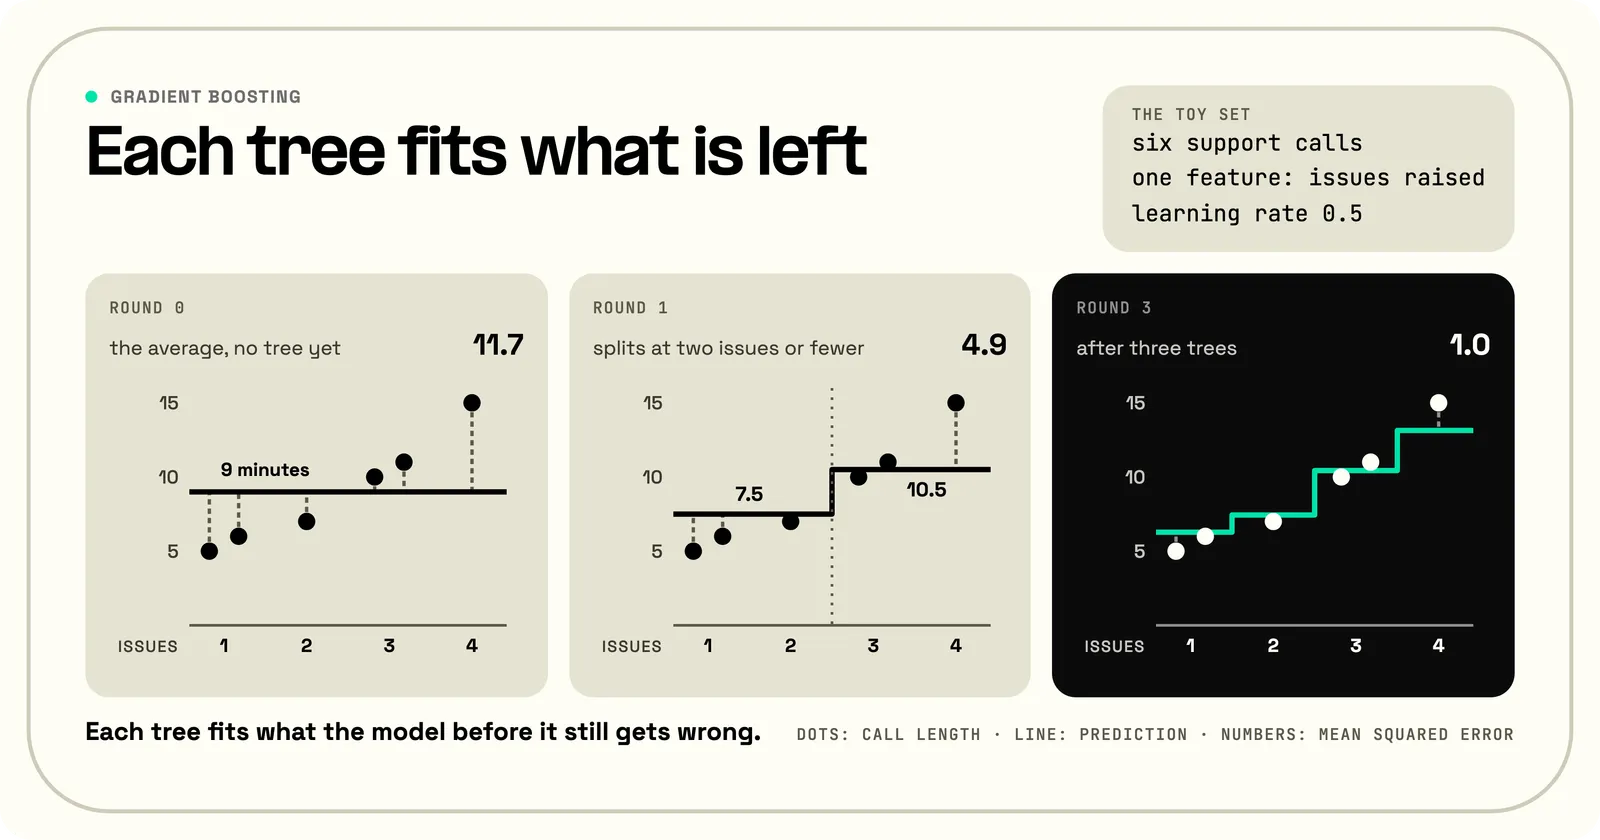
In a toy set of six support calls, the one feature is how many issues each caller raised: 1, 1, 2, 3, 3 and 4. The target is each call's length in minutes: 5, 6, 7, 10, 11 and 15.
The starting prediction is the average, 9 minutes, for every call. The residuals run from -4 to +6 minutes. The mean squared error, the average of the squared residuals, is 11.7.
A decision tree divides rows on one feature at a time and predicts one constant value for each group it ends with, called a leaf. Each tree in this example makes a single split.
The first tree splits the calls at two issues or fewer, the split that most reduces the squared error of the residuals. It predicts a residual of -3 minutes for those three calls and +3 for the other three.
A learning rate of 0.5 adds half of each value, a larger step than the usual 0.1, chosen here to keep each round visible.
Calls with one or two issues now get 7.5 minutes, calls with three or four get 10.5. The error falls to 4.9. The second tree splits at three issues or fewer and the third at one, cutting the error to 1.9, then 1.0.
After 50 trees the model predicts 5.5, 5.5, 7, 10.5, 10.5 and 15 minutes. Calls with the same number of issues get the same prediction, because no tree can split rows that share every feature value.
At inference time, a trained GBM runs a new row through every tree and adds the starting average to the sum of the trees' scaled outputs.
Gradient boosted decision trees (GBDT), also called gradient tree boosting, are gradient boosting with small decision trees as the models it adds. XGBoost, LightGBM, CatBoost and scikit-learn all implement this form.
Boosting keeps each tree shallow, so each one underfits on its own. The sequence of trees does the learning.
Tree depth sets which feature interactions a GBM can learn. A path through a tree three levels deep tests at most three features, such as a customer's plan, the time of day and the number of issues.
A tree with a single split, called a stump, can only learn each feature's effect on its own. scikit-learn's GradientBoostingRegressor defaults to trees three levels deep; its histogram-based estimators cap each tree at 31 leaves instead.
Gradient boosting runs the same loop for regression and classification with a different loss function, which decides what each new tree learns.
For regression with squared error, the negative gradient of the loss is the residual itself: the gap between the true value and the prediction. That is why each tree in the six-call example could fit the residuals directly.
Absolute error and Huber loss, which squares small errors and takes the absolute value of large ones, give outliers less pull on the model. Friedman's paper covers both.
For classification, a GBM adds its trees on the log-odds scale, the logarithm of p / (1 - p), where 0 means even odds. A sigmoid function turns the sum into a probability between 0 and 1.
The loss is log loss, which grows as the predicted probability of the true label falls. Each new tree fits the gap between the true label, 0 or 1, and the current predicted probability.
That gap is on the probability scale, while the model adds on the log-odds scale. So before a tree is added, each leaf's value is reset to the log-odds step that most lowers the loss for its rows, the line search in Friedman's algorithm.
With more than two classes, each round adds one tree per class.
A GBM overfits when it keeps adding trees after its loss on held-out data stops falling. Tracking that loss shows where to stop.
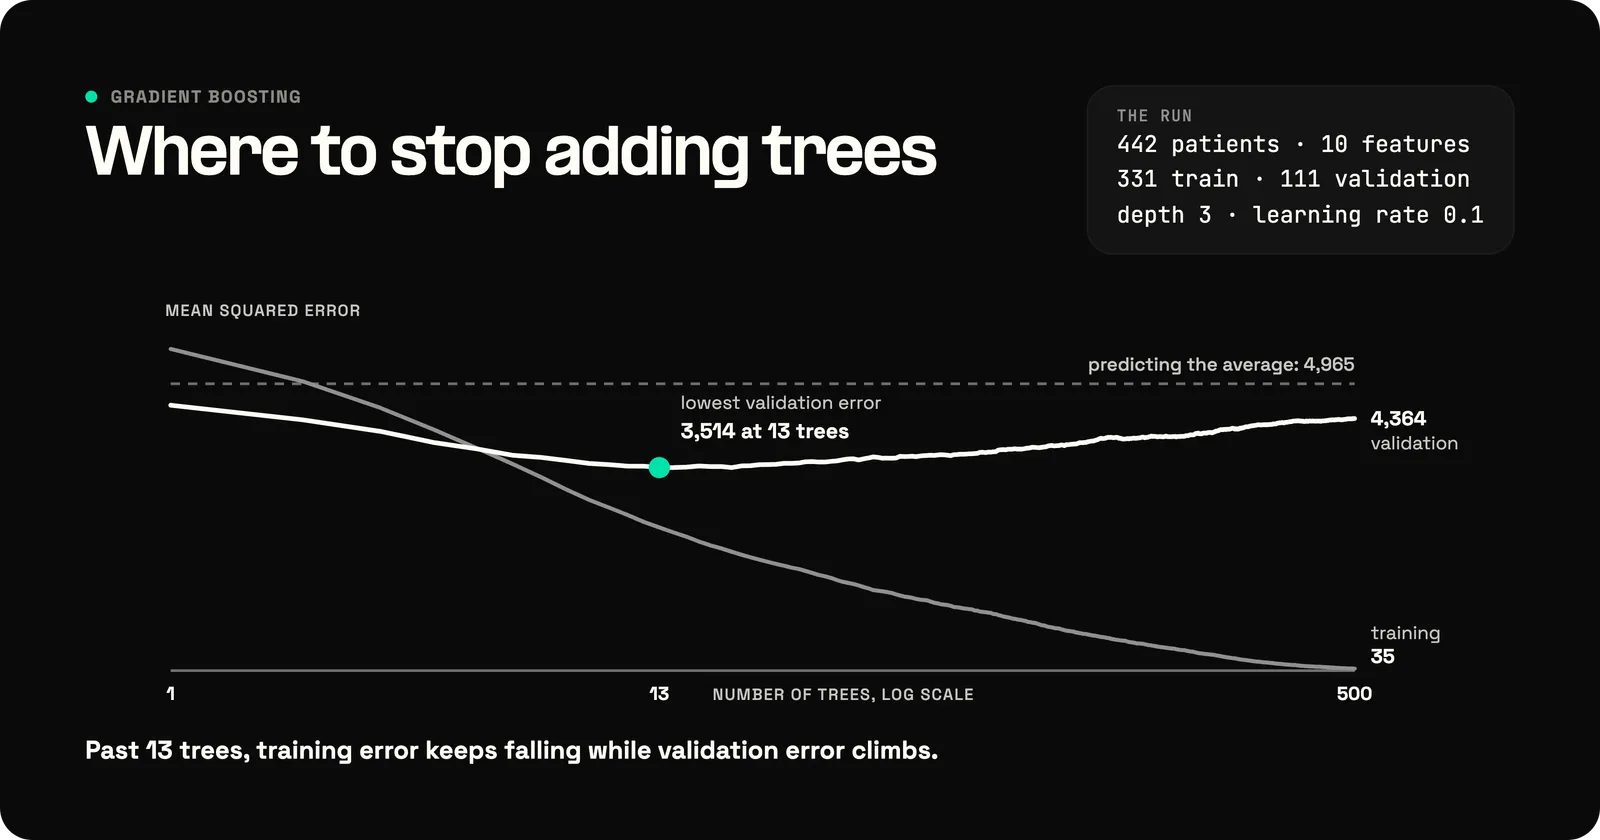
On scikit-learn's diabetes dataset (442 patients, 10 features), a GradientBoostingRegressor with depth-3 trees and a learning rate of 0.1 trained on 331 rows and was scored on the other 111 (a random split, seed 0).
Validation error was lowest at 13 trees, a mean squared error of 3,514, against 4,965 for predicting the average. The same 111 rows chose that count, so 3,514 flatters the model.
By 500 trees, training error had fallen to 35 while validation error had climbed to 4,364, 24% above its low.
The extra trees had fit noise in the 331 training rows. Early stopping ends training once the validation loss has gone a set number of rounds without improving.
scikit-learn's HistGradientBoostingClassifier trains a gradient boosted model in a few lines, with early stopping ending training once the held-out loss stops improving.
The example trains it on the breast cancer dataset that ships with scikit-learn (569 tumors, 30 features) and holds out 20% of the rows for testing:
The model stopped after 55 trees, 10 rounds after its best one. It classified 111 of the 114 test rows (97.4%) correctly. Four settings control it:
learning_rate scales each tree's contribution. scikit-learn's guide recommends 0.1 or lower, with max_iter set high enough that early stopping, not the cap, ends training.max_iter caps the number of trees.max_leaf_nodes (or max_depth) sets the size of each tree, which sets how many features can interact.early_stopping holds out 10% of the training rows and stops after n_iter_no_change rounds without improvement.Early stopping takes care of the tree count, which leaves the learning rate and tree size for hyperparameter tuning.
The older GradientBoostingClassifier has a subsample setting that trains each tree on a random fraction of the rows, typically half. Friedman called this stochastic gradient boosting.
Combined with a small learning rate, subsampling can further increase accuracy, according to scikit-learn's guide.
HistGradientBoostingClassifier bins each feature into at most 255 values before training and handles missing values and categorical features natively.
scikit-learn says the histogram version can be orders of magnitude faster than the older class above tens of thousands of rows.
XGBoost, LightGBM and CatBoost are open-source libraries that implement gradient boosted decision trees. They run the same algorithm and differ in how they find splits, sample rows and handle categories.
| Library | Paper | What it adds to gradient boosting |
|---|---|---|
| XGBoost | Chen and Guestrin, 2016 | A regularized objective, second-order gradient statistics, a learned default branch for missing values, and a system design that scales past billions of rows |
| LightGBM | Ke et al., 2017 | Histogram-based splits, sampling that keeps the rows with large gradients, bundling of features that are rarely nonzero together, and leaf-wise growth |
| CatBoost | Prokhorenkova et al., 2018 | Ordered boosting, which computes each row's residual with a model that never saw that row, and an ordered encoding of categorical features; both stop the label leaking into the model's own inputs. Symmetric trees use one split per level |
The LightGBM paper reports training up to more than 20 times faster than conventional GBDT at almost the same accuracy. LightGBM targets data with many rows and many features. CatBoost targets data where many features are categorical.
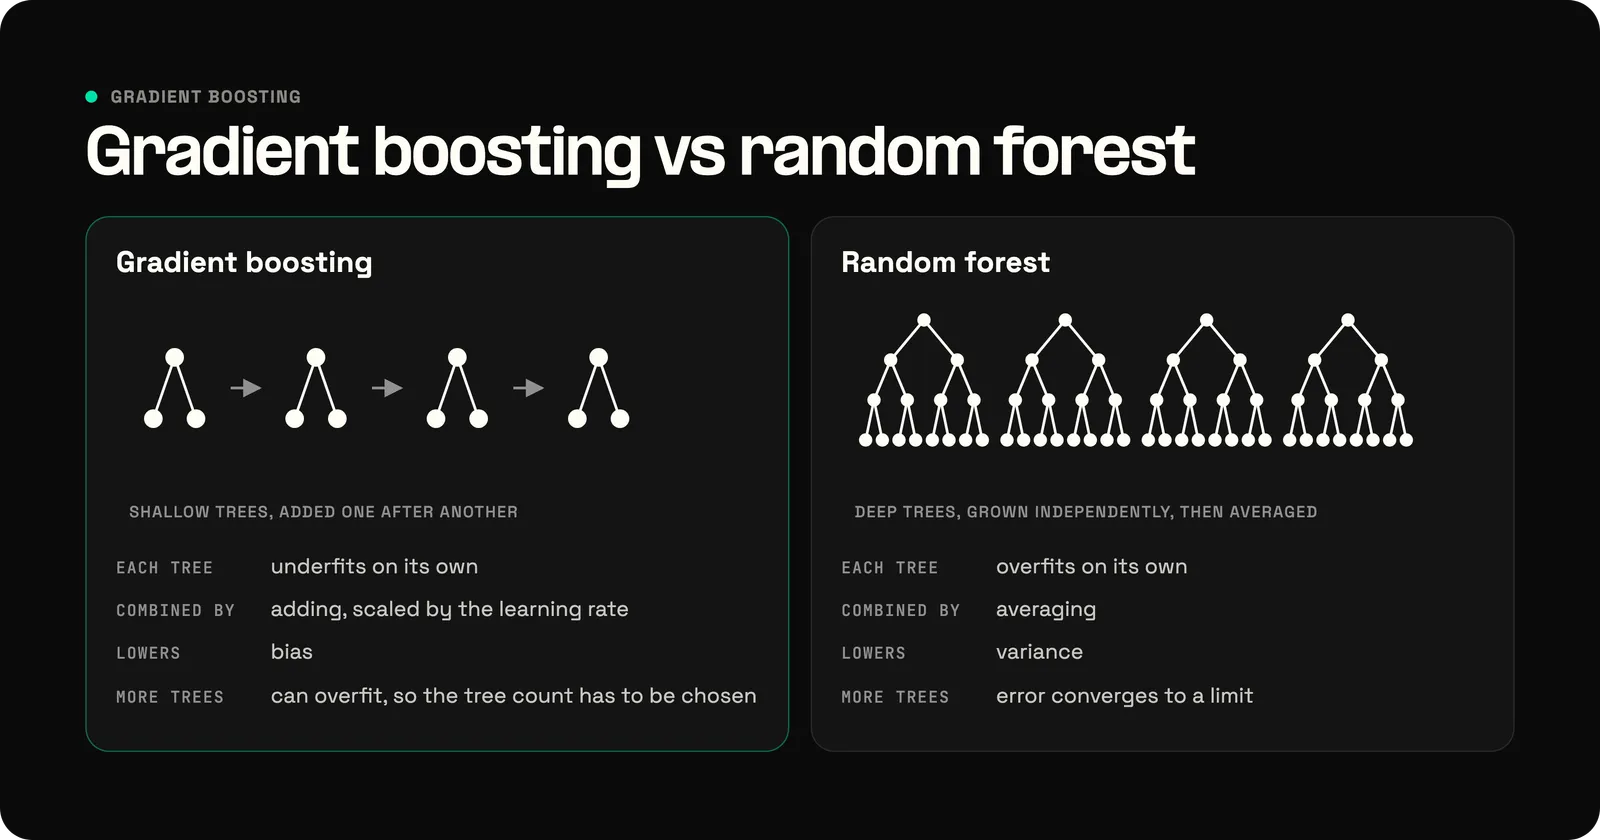
Gradient boosting adds shallow trees one after another, while a random forest grows deep trees independently and averages them.
In Leo Breiman's random forest, each tree trains on a sample of the rows drawn with replacement and picks from a random subset of features at every split. The trees grow deep and are not pruned.
A random forest averages deep trees that each overfit, which lowers variance. Gradient boosting adds shallow trees that each underfit, which lowers bias.
Adding trees to a random forest does not make it overfit: Breiman showed that its error converges to a limit as the forest grows. Adding trees to a GBM can, as the diabetes run showed, so the tree count has to be chosen.
Random forest trees can train in parallel because no tree depends on another. Boosting's shallow trees are faster to fit and predict than a forest's deep ones, according to scikit-learn's guide.
In the 2022 benchmark, the best tabular models were tree ensembles of both kinds, bagged random forests and boosted trees. scikit-learn's guide advises trying both on the problem at hand.
The main advantages of gradient boosting are accuracy on tabular data, little data preparation and interpretability. Its main limits are sequential training, overfitting, no extrapolation and weak results on raw text and images.
The advantages:
The limitations:
That limit sets the division of labor in a voice AI agent: the language model handles the conversation, while fields extracted from each finished call become a GBM's training rows.
The Telnyx Voice API hangup event records when a call started, why it ended and its audio quality. AI Insights extracts fields such as a 1-to-5 sentiment score from conversations with Telnyx voice AI agents.
In machine learning, GBM stands for gradient boosting machine: a model built by gradient boosting, usually from decision trees. The name comes from Friedman's 2001 paper.
In medicine, GBM means glioblastoma, a type of brain tumor.
Gradient descent improves a model by adjusting its parameters step by step, while gradient boosting improves it by adding a new model at each step.
Friedman framed boosting as gradient descent in function space: each step adds a whole function, a tree, instead of nudging a parameter.
AdaBoost, from Yoav Freund and Robert Schapire, raises the weight of every training example the previous models misclassified. Gradient boosting instead fits each new model to the negative gradient of a chosen loss.
AdaBoost is a special case: gradient boosting with exponential loss recovers the AdaBoost algorithm, as scikit-learn's documentation notes.
XGBoost is a library that implements gradient boosting, so it runs the same algorithm. Its additions, such as a regularized objective, change how the trees are built, not what the model is.
The learning rate scales each tree's contribution before it is added to the model. At 0.1, each tree moves the predictions a tenth of the way toward what it learned.
Smaller steps need more trees and tend to give better test error, according to scikit-learn's guide.
A weak learner is a model that predicts only a little better than chance, such as a decision stump with one split. Boosting combines many weak learners, trained in sequence, into one accurate model.