Ground truth is the verified reference data a model is trained and measured against. What it is, how labels are created, and its role in evaluation.
Updated September 2026
A machine learning model can be no more accurate than the answers it learns from, and those answers are its ground truth. Get them wrong, and the model learns the wrong thing, confidently. The term is precise in machine learning, and unrelated to GroundTruth, the location-advertising company that shares the name.
Quick answer: Ground truth is the correct, verified data used to train and evaluate a machine learning model, the labels, values, or measurements a model's predictions are compared against. It is usually created by human annotation and serves as the reference for both training and testing. Synonyms include gold standard and reference data. It is a different idea from AI grounding, which keeps a model's output tied to real sources rather than serving as its reference answers.
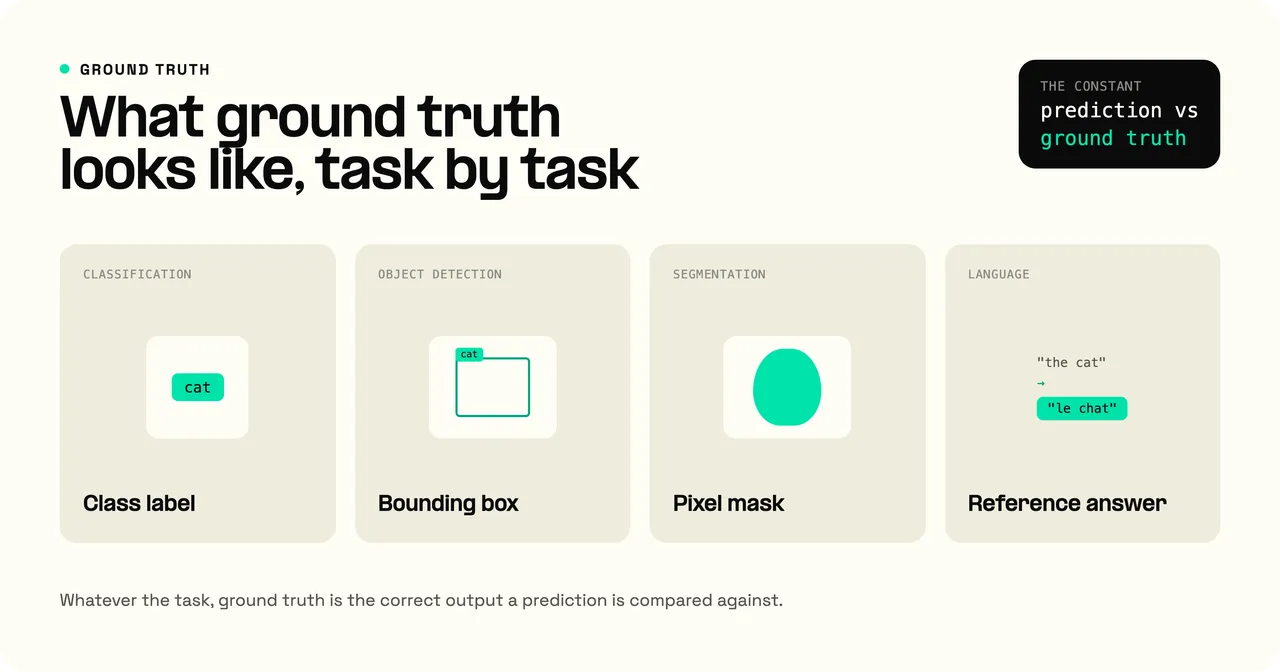
Every example in a labeled dataset carries a known-correct answer, and that answer is its ground truth: the output a model is supposed to produce for it. An image of a cat carries the ground-truth label "cat"; a support ticket carries the ground-truth category "billing"; an English sentence carries its ground-truth translation in French. Pairing data with its ground truth is what makes supervised learning possible, and models that learn without it, such as unsupervised methods, are a separate branch of the field.
This content was generated with the assistance of AI. Our AI prompt chain workflow is carefully grounded and preferences .gov and .edu citations when available. All content is reviewed by a Telnyx employee to ensure accuracy, relevance, and a high standard of quality.
Ground truth is a reference, not an absolute. It is the best available record of the correct answer, usually set by people or instruments, so it can carry its own errors, and treating it as flawless is a common mistake. What makes it the "truth" is not that it is perfect, but that it is the agreed standard a model is measured against.
In machine learning, ground truth is the reference a model is both trained on and tested against. During training, the model makes a prediction, a loss function measures how far that prediction is from the ground truth, and the model adjusts to close the gap. During testing, predictions are compared to ground truth the model has never seen, which is how you learn whether it generalizes or just memorized.
Because a model can memorize its ground truth, teams split their labeled data: the model trains on one portion and is scored on a held-out portion it never saw. Strong numbers on the training data mean little on their own. The held-out ground truth is what shows whether the model learned the pattern or only the answers.
This is why ground truth quality sets a ceiling on model quality. If the labels are wrong, inconsistent, or biased, the model faithfully learns those flaws, a pattern often summarized as garbage in, garbage out. In classification the ground truth is the correct class; in a large language model evaluation it is the reference answer a response is checked against; in every case it is the standard the model is held to.
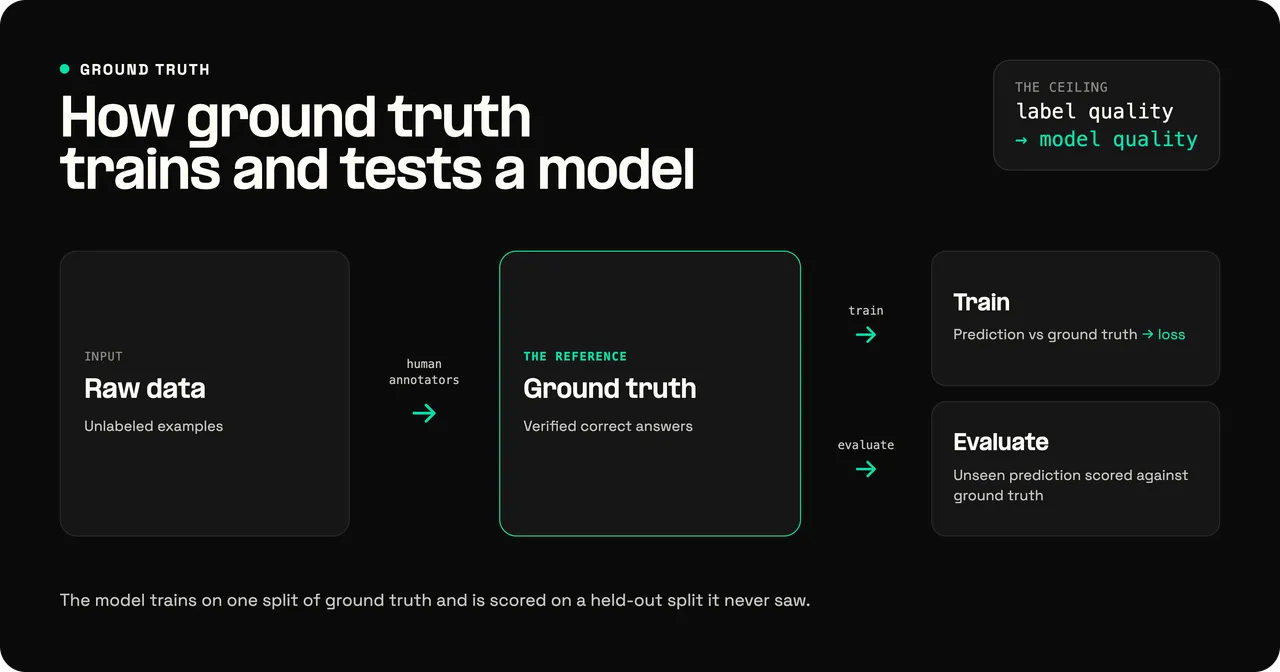
Ground truth data is the collection of examples paired with their verified correct answers, the dataset a model learns from. Each example holds an input, such as an image or a sentence, and its ground-truth output, such as a label or a value, and the quality of that pairing is what the model ultimately inherits.
Most ground truth is produced by data labeling, where human annotators mark up raw data by hand: drawing boxes around objects, tagging sentiment, or transcribing audio. Because human judgment varies, teams use multiple annotators, clear guidelines, and agreement checks to keep labels consistent, then improve the set over time as errors surface. Some ground truth instead comes from direct measurement or trusted records, which needs no manual labeling but is only as reliable as its source.
Even careful labeling carries noise. Annotators disagree on ambiguous cases, guidelines get read differently, and some judgments are simply subjective, so a fraction of any ground-truth set is wrong or contested. Teams track this with inter-annotator agreement and treat low agreement as a sign to clarify the task, not to push ahead. Ground truth can also inherit the bias of whoever created it, which the model then reproduces, so who labels the data, and how, is a modeling decision rather than a clerical one.
In computer vision, ground truth is the human-marked answer a model's visual predictions are compared against, and its form depends on the task. For image classification it is a single label for the whole image. For object detection it is a set of bounding boxes, each with a class. For segmentation it is a pixel-level mask that marks exactly which pixels belong to which object.
Getting that ground truth right is painstaking, because a bounding box drawn a few pixels off or a mask with ragged edges teaches the model a slightly wrong idea of where objects begin and end. This is why annotation guidelines and review matter as much in vision as the model architecture does. Vision ground truth is also costly: a single segmentation mask can take minutes of careful work, and a usable dataset needs thousands, so labeling budget often decides what a vision project can attempt.
Ground truth is what turns model evaluation from opinion into measurement. To score a model you run it on data it has not seen and compare each prediction to the ground truth. Metrics like accuracy, precision, recall, and the F1 score are all ways of summarizing how often the predictions and the ground truth agree.
It also underpins how teams catch failures. A hallucination is a confident model output with no support in ground truth, and you can only flag one if you have a trusted reference to check against. Without ground truth there is no objective way to say a model is right or wrong; there is only the model's own confidence, which is exactly what cannot be trusted on its own.
Shared benchmarks work the same way at industry scale. A public dataset like ImageNet is agreed-upon ground truth that lets different models be compared on the same answers, which is how the field tracks progress. The risk is that once everyone optimizes against one fixed set of answers, a model can start fitting the benchmark rather than the task it stands for.
The term comes from remote sensing and cartography, where ground truth meant data collected on location, on the actual ground, to verify what a satellite or aerial image appeared to show. Machine learning kept the meaning: ground truth is reality confirmed by a trusted source, used to check a model's output.
Ground truthing is the act of collecting or verifying ground truth, checking that the labels or measurements really match reality. In its original field it meant visiting a site to confirm remote observations; in machine learning it means validating that a dataset's labels are correct before a model is trained or judged against them.
Common synonyms are gold standard, gold labels, and reference data. Each names the same idea: a trusted set of correct answers a model is measured against. The exact word varies by field, but the role is identical.
A labeled set of photos tagged "cat" or "dog" is ground truth for image classification. A collection of sentences paired with human translations is ground truth for machine translation, and a set of questions with verified answers is ground truth for evaluating a language model. In each case the dataset pairs inputs with their known-correct outputs.
No, the two are different. Ground truth is the reference data a model is trained and evaluated against. Grounding is a technique that connects a model's output to external facts at the time it responds, to reduce hallucination. One is the yardstick; the other is a method for staying closer to it.