What is multimodal AI? Models, examples, and multimodal NLP
Multimodal AI processes text, images, audio, and video in one model. How multimodal models work, the main types, real examples, and where multimodal NLP fits.

Editor: Andy Muns
Updated October 2026
Multimodal AI is artificial intelligence that processes or generates more than one type of data, such as text, images, audio and video, within a single model or system. A multimodal model can answer a typed question about a photo, describe a chart in words, or hold a spoken conversation. Multimodal NLP is the language side of the field: models that read or write text together with images, speech or video.
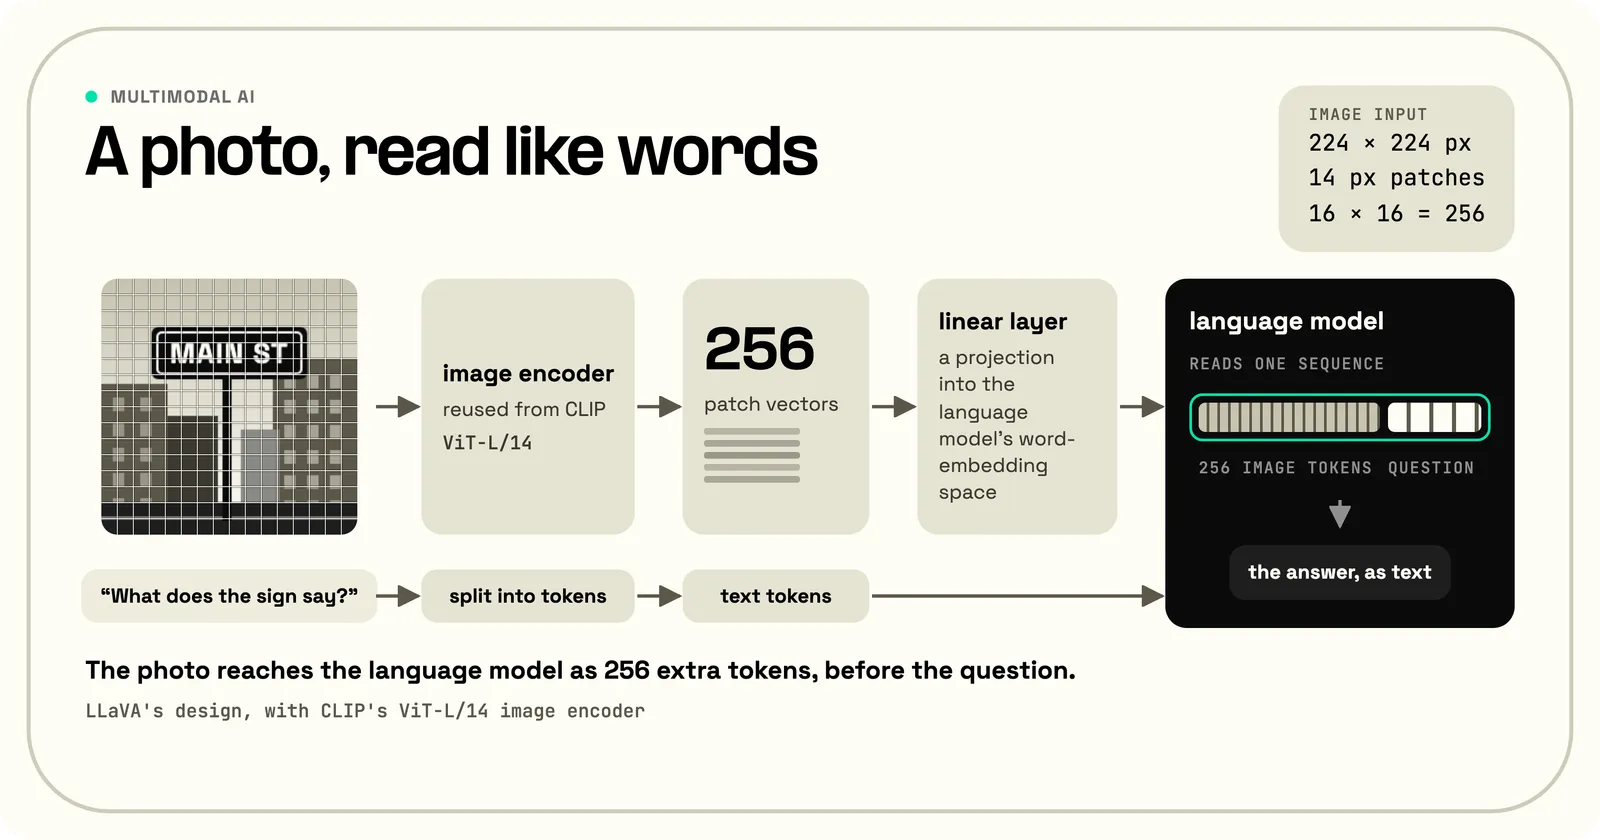
In many of today's multimodal models, a language model does the reading. A vision encoder turns a photo into a few hundred vectors, which the language model reads like extra words.
What is multimodal AI?
Multimodal AI combines two or more modalities, the kinds of data a model can take in or produce: text, images, audio, video, or sensor readings such as depth and motion.
Baltrušaitis and colleagues define multimodal machine learning as building models that process and relate information from multiple modalities. "Relate" is the important word: the model connects what it sees to what it reads or hears.
A unimodal model handles one modality. A text-only language model reads and writes text, and an image classifier looks at pictures and outputs a label.
A multimodal model combines several modalities, usually by mapping them into one shared representation.
In education, "multimodal learning" means teaching through several senses at once. That is a theory of how people learn.
How does multimodal AI work?
Multimodal AI works in up to three steps: encoders turn each kind of input into vectors, alignment puts those vectors in a shared space, and fusion combines them so one model can reason over all of them.
An encoder is a network that turns raw input into vectors, lists of numbers that a model can compare. Text is split into tokens before it is encoded.
Audio is usually turned into a spectrogram first, a picture of how its frequencies change over time.
Images go through a convolutional network or a vision transformer, which cuts the picture into square patches and treats each patch like a word.
CLIP, a model trained to match images with captions, uses a vision transformer called ViT-L/14: L for large, 14 for the patch size in pixels. It cuts a 224 by 224 pixel image into a 16 by 16 grid of 256 patches, each encoded as one vector.
Alignment trains the vectors so that a photo and a sentence about it land close together. CLIP trained its two encoders this way on 400 million image and caption pairs, predicting which caption goes with which image.
CLIP stops at alignment: it compares an image's vector with a caption's instead of fusing them.
LLaVA reuses CLIP's image encoder and adds one linear layer, a projection into the language model's word-embedding space. The 256 patch vectors reach the language model as 256 extra tokens, in the same sequence as the question.
Fusion combines the modalities inside one model. Late fusion encodes each modality separately and combines the results afterwards. Early fusion turns every modality into tokens of one sequence for a single network trained on all of them.
The Chameleon authors class LLaVA and Flamingo as late fusion, since each encodes the image separately. Flamingo joins the two with cross-attention layers, which let the language model look up image features as it writes each word.
Training usually runs in two stages. First the model learns from paired data, such as images with captions; in LLaVA, only the projection layer trains in this stage.
Then the model is instruction-tuned on examples of requests about images, so it answers a question instead of only describing the picture.
What is multimodal NLP?
Multimodal NLP is natural language processing that uses another modality alongside text, such as answering a question about an image or writing a caption for a video.
The field grew around five tasks: visual question answering, image captioning, multimodal sentiment analysis, multimodal machine translation, and speech tasks.
Visual question answering asks a model to answer a free-form question about an image in words. The VQA dataset defined the task in 2015, with about 250,000 images and 760,000 questions.
Image captioning generates a sentence that describes a picture. In 2015, Karpathy and Fei-Fei and Vinyals and colleagues both paired a convolutional network for the image with a recurrent network for the sentence.
Multimodal sentiment analysis reads the words, the voice and the face together. The MOSI dataset labeled opinion videos for sentiment intensity, with visual and audio features.
On phone calls, call sentiment analysis typically scores only the transcript, so a flat "great, thanks" scores the same as a warm one.
Multimodal machine translation translates a caption with its image as extra context. Multi30K added German translations to English image descriptions for this task.
Speech tasks pair audio with text. Speech recognition turns audio into a transcript, and text-to-speech turns text into audio. Whisper learned recognition from 680,000 hours of audio paired with transcripts.
Each task once had its own model. Large multimodal models now handle most of them with one set of weights. Shown a handful of examples in its prompt, a single Flamingo model set new few-shot results on question answering and captioning.
Types of multimodal models
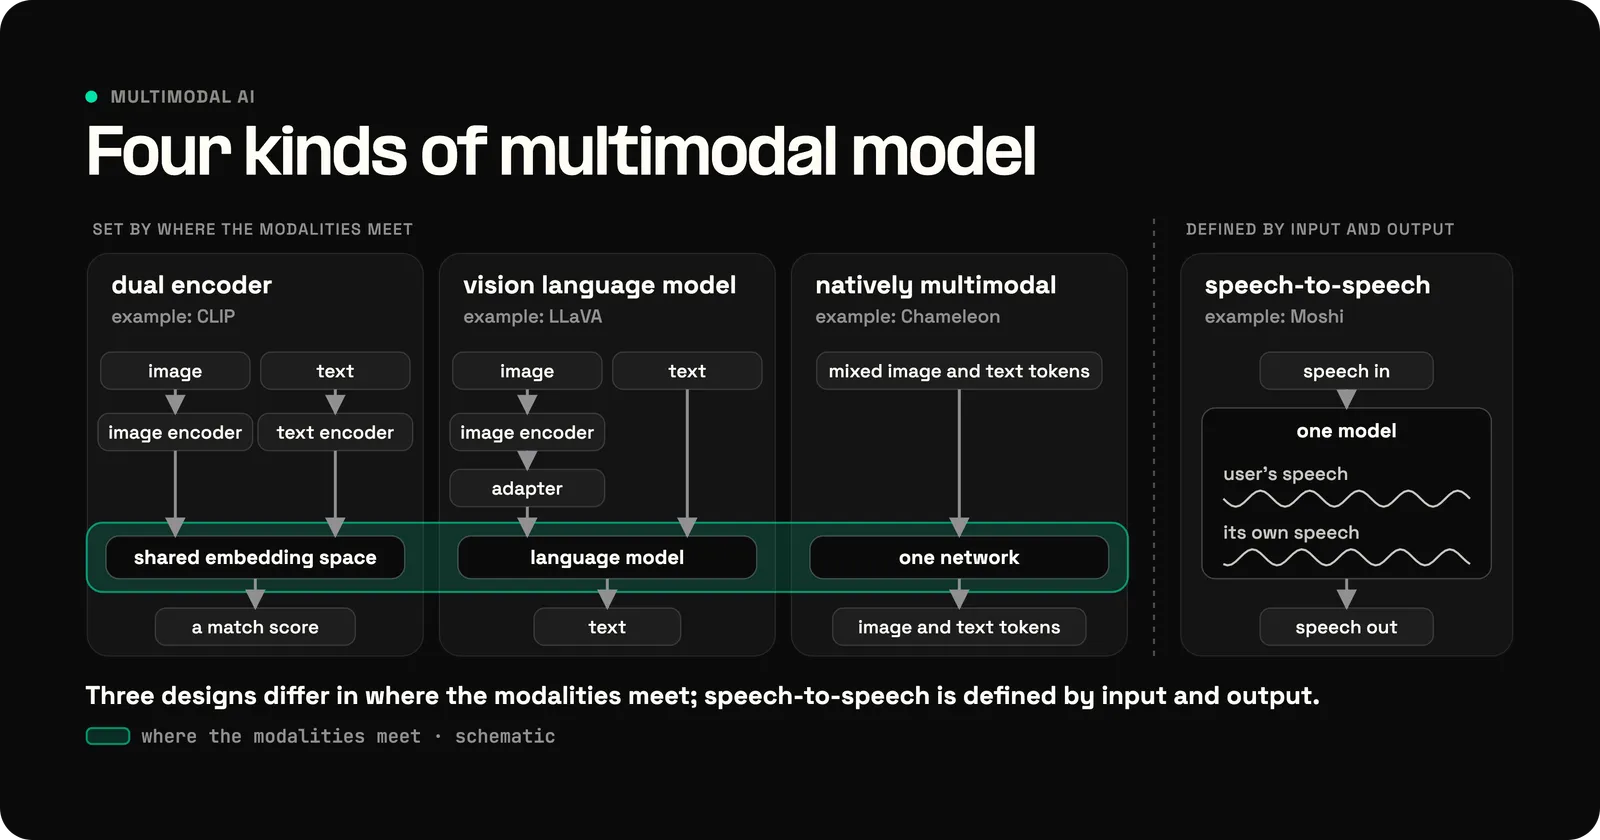
Multimodal models come in three main designs, set by where the modalities meet: a shared embedding space, an adapter into a language model, or one network trained on every modality from the start.
Speech-to-speech models are a fourth group, defined by input and output rather than design.
Dual encoders and multimodal embeddings
A dual encoder trains one encoder per modality so that matching items land close together in a shared space. CLIP works this way: its image and text encoders place a photo near its caption, so a text query can find images.
The same shared space classifies images with no labeled training data: CLIP compares a photo with the category names. CLIP matched the original ResNet-50 on ImageNet without any of the 1.28 million labeled images that model learned from.
ImageBind extended the shared space to six modalities: images, text, audio, depth, thermal and motion data.
Vision language models (VLMs)
A vision language model (VLM) reads images and text and answers in text. The adapter design connects a pretrained image encoder to a pretrained language model through a small adapter, so the language model can read images.
VLMs are also called large multimodal models (LMMs) or multimodal LLMs (MLLMs). Natively multimodal models do the same job with one network.
LLaVA's adapter is its single linear layer; Flamingo's is its cross-attention layers.
BLIP-2 trained a small Querying Transformer between a frozen image encoder and a frozen language model. It beat the 80-billion-parameter Flamingo by 8.7% on zero-shot visual question answering, with 54 times fewer trainable parameters.
An adapter saves training, because the image encoder and the language model arrive already trained. The language model then sees only what the image encoder passes on.
Natively multimodal models
A natively multimodal model is trained on several modalities from the start, in one network, instead of attaching an encoder to a finished language model.
Chameleon turns images into discrete tokens and trains one model on mixed sequences of image and text tokens. That early-fusion design lets it read and generate both, in any order.
The GPT-4o system card describes GPT-4o as trained end to end across text, vision and audio, with every input and output processed by the same neural network.
The Gemini report calls its models natively multimodal, trained jointly across text, image, audio and video.
Speech-to-speech models
A speech-to-speech model takes speech in and produces speech out in one model, instead of passing text between separate speech recognition, language and speech synthesis models. GPT-4o is one.
Moshi starts from a text language model and adds speech. It models the user's speech and its own as parallel audio streams, so it can handle interruptions. Its authors report 160 ms of latency in theory and 200 ms in practice.
Examples and applications of multimodal AI
Document question answering is a clear example of multimodal AI: a model reads a scanned invoice, form or report and answers questions about it in text. The DocVQA dataset set 50,000 such questions on more than 12,000 document images.
Accessibility tools pair a photo with a spoken question. VizWiz collected more than 31,000 questions from blind people who took a picture with a phone and recorded a question about it.
Medical AI combines clinical text with images. Med-PaLM M, a research model, interprets clinical language, medical images and genomic data with the same set of weights. Its tasks include writing radiology reports.
Retail and social apps search by image. In a three-month live test, recommendations from Pinterest's visual search raised repins (a user saving a recommended image) by 2% in its Related Pins feature.
Robots turn camera input and instructions into actions. PaLM-E feeds images, robot state estimates and text into one language model, which plans sequences of manipulation steps.
Customer service adds photos to calls. Telnyx voice AI agents can read a product photo or an error screenshot that a caller sends by MMS during the call.
Challenges of multimodal AI
The main challenges of multimodal AI are scarce paired data, objects the model invents, the token cost of images and video, and instructions hidden in media.
Paired data is the first limit. Image and caption pairs are plentiful on the web.
Pairs for other combinations are scarce. ImageBind's authors call collecting paired data for every combination of modalities infeasible, so their method needs only pairs with images.
Vision language models describe objects that are not in the image, a failure called object hallucination. Li and colleagues found it severe across the models they tested.
The objects most likely to be invented were ones that appear often in training instructions, or that usually appear beside what is in the picture.
Li and colleagues also found that the wording of the test question changed hallucination scores, so they built the POPE benchmark to measure hallucination more stably.
Images are expensive in tokens. In LLaVA's setup each image takes 256 positions in the language model's context before the question starts.
Video multiplies that by every frame the model reads. One minute sampled at one frame per second is 60 frames, or 15,360 positions, before any text.
Images and audio can carry hidden instructions. Bagdasaryan and colleagues blended an adversarial pattern into an image or a sound clip. When a user asked an unmodified model about it, the model output the attacker's text.
One mitigation is the check AI guardrails apply to typed input: treat text read from an image or audio clip as untrusted, and require a confirmation before any tool call that depends on it.
Multimodal AI vs generative AI vs LLMs
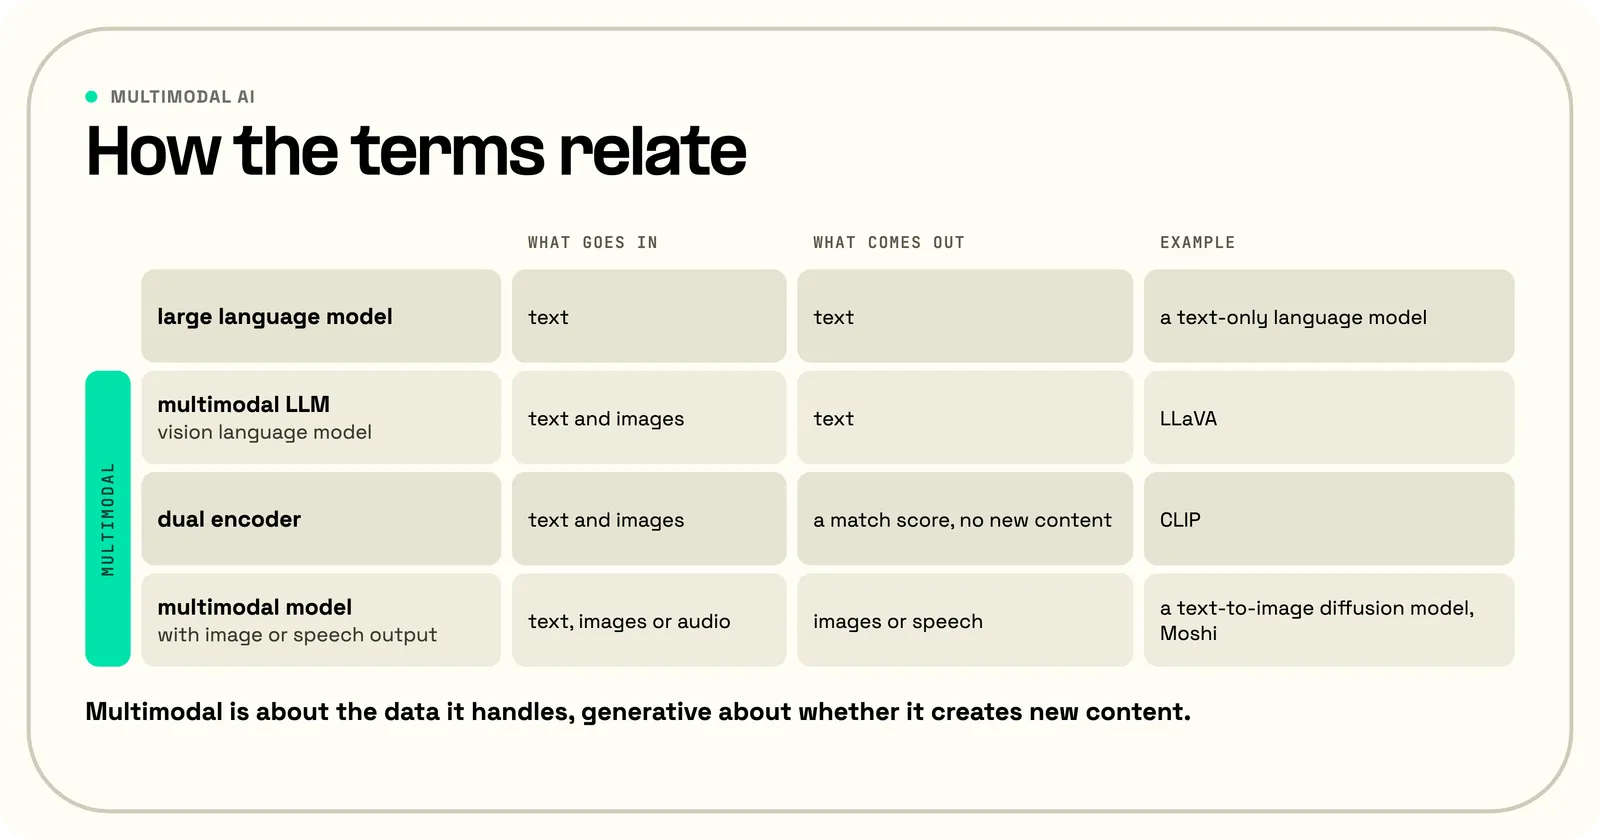
Multimodal AI, generative AI and large language models describe different properties of a model. Multimodal is about the data it handles, generative about whether it creates new content, and an LLM is a model trained mainly on text.
Generative AI covers any model that produces new content, whether text, images or audio. A large language model is generative and, in its original form, text-only.
A multimodal large language model is an LLM that also accepts images, audio or video as input. Vision language models are the common case. Some also produce images or speech.
Multimodal does not imply generative. CLIP handles images and text but generates nothing: it scores how well an image and a caption match.
Multimodal generative AI is the overlap: models that handle more than one kind of data and create new content. A VLM writing an answer about a photo counts.
Text-to-image generators are the familiar case with output that is not text: a text encoder reads the prompt and a diffusion model draws the image.
Multimodal AI in voice agents
A voice agent is multimodal by design: it takes in speech, reasons in language, and answers in speech. It can be built as a cascade of separate models or around one speech-to-speech model.
A cascaded agent passes text between three models. Speech recognition turns the caller's audio into text, a language model writes the reply, and text-to-speech speaks it.
Every model in a cascaded pipeline can be swapped and the transcript can be read, but each handoff adds delay to every turn.
A speech-to-speech model hears and answers in one model. It drops two text handoffs and keeps the tone that a transcript loses, but any transcript it produces is a side output, not a record of what it heard.
When callers read out numbers or the agent must log exactly what was said, a cascade keeps a transcript to check. When per-stage timings show the handoffs taking most of the wait, a speech-to-speech model is worth testing.
In a cascade, a photo joins the conversation through the language model. That model can be a vision language model, so the photo sits in the same context as the caller's words.
With a speech-to-speech model, the photo goes to the model itself if it accepts images, or to a separate vision model whose description comes back as text.
Telnyx AI Assistants support both designs. Two speech-to-speech models are available: GPT Live, used with the developer's own provider API key, and PersonaPlex 7B, in beta, hosted by Telnyx and English only.
On a phone call, a caller can send a photo by MMS for the assistant's language model to read, so that model must be vision-capable. A website visitor can share a photo in the chat widget.
An app can also send camera or screen-share snapshots to a vision tool, in beta. The assistant looks at the latest snapshot when a question needs it and ignores any older than 10 seconds by default.
Developers who build their own pipeline can stream a call's raw audio over WebSockets with media streaming on the Telnyx Voice API and run either design on it.
Frequently asked questions
Is ChatGPT a multimodal AI?
Yes, the chatbot is multimodal: it accepts images and spoken conversation as well as text.
The GPT-4o system card describes the model behind its voice mode as one network trained end to end on text, vision and audio, which replied to audio in 320 milliseconds on average.
Which multimodal AI model is best?
No single multimodal model is best for every task. The right one depends on the modalities it must handle, how fast it must answer, and where it must run.
The reliable test is how candidates do on a sample of the real inputs, such as the actual documents or call audio.
What is multimodal text analysis?
Multimodal text analysis has two meanings. In linguistics and education, it is the study of texts that combine several modes, such as the words, images and layout of a web page or a comic.
In NLP, it means analyzing text together with the images or audio around it, such as a social media post and its photo.
Is multimodal learning the same as multimodal AI?
No, the two terms come from different fields. In education, multimodal learning is a teaching approach that presents material through several senses, such as pictures, sound and hands-on activity.
In machine learning, multimodal learning means training a model on more than one modality, which is how multimodal AI models are built.
What are multimodal embeddings?
Multimodal embeddings are vectors that place items from different modalities in one shared space, so an image and a sentence describing it end up close together.
Dual encoders such as CLIP and ImageBind produce them for cross-modal search, such as finding product photos from a typed description.
Sources
- Baltrušaitis, T., Ahuja, C., and Morency, L.-P. (2019). Multimodal machine learning: a survey and taxonomy. IEEE Transactions on Pattern Analysis and Machine Intelligence.
- Dosovitskiy, A., et al. (2021). An image is worth 16x16 words: transformers for image recognition at scale. ICLR 2021.
- Radford, A., et al. (2021). Learning transferable visual models from natural language supervision. ICML 2021.
- Liu, H., Li, C., Wu, Q., and Lee, Y. J. (2023). Visual instruction tuning. NeurIPS 2023.
- Alayrac, J.-B., et al. (2022). Flamingo: a visual language model for few-shot learning. NeurIPS 2022.
- Agrawal, A., Lu, J., Antol, S., et al. (2015). VQA: visual question answering. ICCV 2015.
- Karpathy, A., and Fei-Fei, L. (2015). Deep visual-semantic alignments for generating image descriptions. CVPR 2015.
- Vinyals, O., Toshev, A., Bengio, S., and Erhan, D. (2015). Show and tell: a neural image caption generator. CVPR 2015.
- Zadeh, A., Zellers, R., Pincus, E., and Morency, L.-P. (2016). MOSI: multimodal corpus of sentiment intensity and subjectivity analysis in online opinion videos. IEEE Intelligent Systems.
- Elliott, D., Frank, S., Sima'an, K., and Specia, L. (2016). Multi30K: multilingual English-German image descriptions. Workshop on Vision and Language 2016.
- Radford, A., et al. (2023). Robust speech recognition via large-scale weak supervision. ICML 2023.
- Girdhar, R., et al. (2023). ImageBind: one embedding space to bind them all. CVPR 2023.
- Li, J., Li, D., Savarese, S., and Hoi, S. (2023). BLIP-2: bootstrapping language-image pre-training with frozen image encoders and large language models. ICML 2023.
- Chameleon Team (2024). Chameleon: mixed-modal early-fusion foundation models.
- GPT-4o System Card (2024). arXiv:2410.21276.
- Gemini Team (2023). Gemini: a family of highly capable multimodal models.
- Défossez, A., et al. (2024). Moshi: a speech-text foundation model for real-time dialogue.
- Mathew, M., Karatzas, D., and Jawahar, C. V. (2021). DocVQA: a dataset for VQA on document images. WACV 2021.
- Gurari, D., et al. (2018). VizWiz grand challenge: answering visual questions from blind people. CVPR 2018.
- Tu, T., et al. (2023). Towards generalist biomedical AI.
- Jing, Y., et al. (2015). Visual search at Pinterest. KDD 2015.
- Driess, D., et al. (2023). PaLM-E: an embodied multimodal language model. ICML 2023.
- Li, Y., et al. (2023). Evaluating object hallucination in large vision-language models. EMNLP 2023.
- Bagdasaryan, E., Hsieh, T.-Y., Nassi, B., and Shmatikov, V. (2023). Abusing images and sounds for indirect instruction injection in multi-modal LLMs.
- Telnyx. Speech-to-speech models, Vision, MMS integration during voice calls, and Media streaming. Telnyx developer documentation.
Share on Social
Sign up for emails of our latest articles and news
This content was generated with the assistance of AI. Our AI prompt chain workflow is carefully grounded and preferences .gov and .edu citations when available. All content is reviewed by a Telnyx employee to ensure accuracy, relevance, and a high standard of quality.


