A TPU is Google's AI accelerator built around the matrix multiply unit (MXU), a systolic array. How the architecture works and how the generations evolved.

Updated September 2026
A TPU is a chip Google designed to do one thing extremely well: multiply matrices. Neural networks are mostly matrix multiplication, so a processor built around that single operation runs them faster and more efficiently than a general-purpose chip. The part that does the multiplying is the MXU, the matrix multiply unit, and it is where a TPU's speed comes from.
Quick answer: A TPU (Tensor Processing Unit) is a custom AI accelerator chip Google built to speed up neural network training and inference. Its core is the MXU (matrix multiply unit), a systolic array that runs thousands of multiply-accumulate operations per cycle. TPUs are available through Google Cloud and support TensorFlow, JAX, and PyTorch. The MXU here is the hardware unit inside a TPU, not the unrelated "MxU" subscription at getmxu.com.
A TPU is a custom chip, an application-specific integrated circuit (ASIC), that Google built specifically for machine learning. A CPU runs almost any program, and a GPU accelerates the parallel math behind graphics and deep learning. A TPU is narrower than both: it is designed around the matrix operations that dominate neural networks, which is what lets it reach high throughput per watt on that one job.
Google began using TPUs in its data centers in 2015 and announced them in 2016, then opened them to outside developers through Google Cloud in 2018. They run models written in TensorFlow, JAX, and PyTorch, the frameworks Google supports on the hardware.
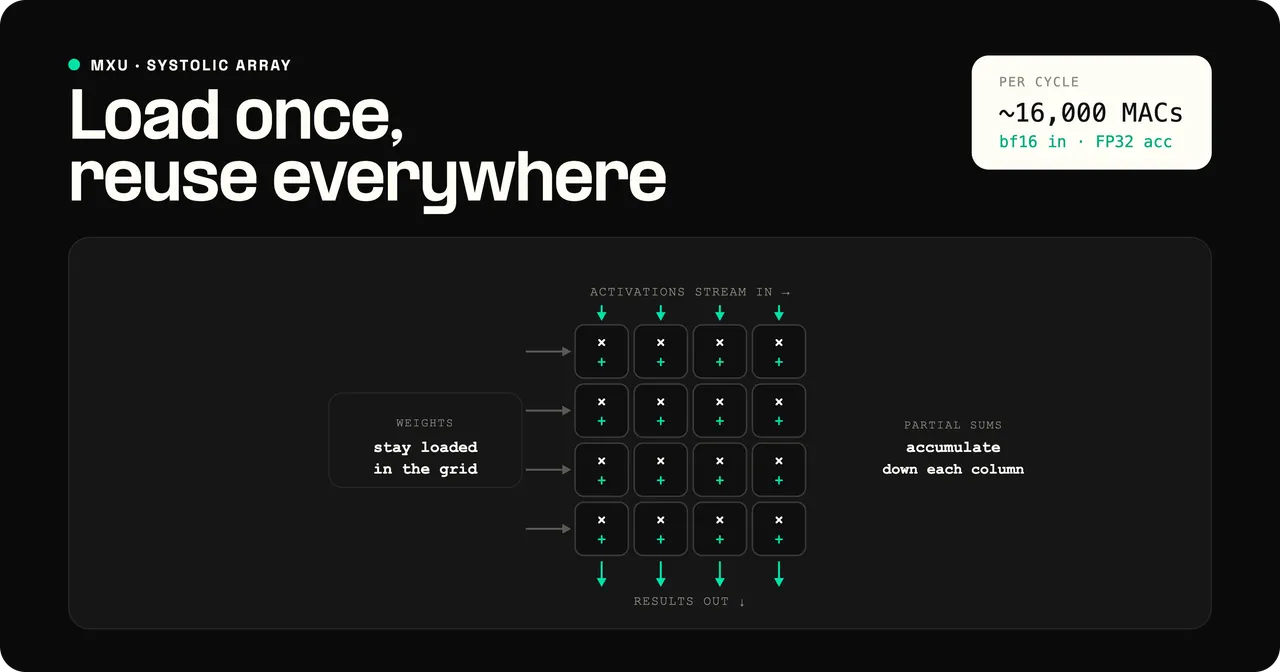
The MXU, or matrix multiply unit, is the part of a TPU that performs matrix multiplication, and it is the engine behind the chip's speed. It is a systolic array: a grid of multiply-accumulate cells wired so that data flows through them in step, so the chip reuses each value across many calculations instead of fetching it from memory again and again.
That reuse is the whole trick. In a systolic array the weights stay loaded in the grid while activations stream through, and each cell multiplies, adds, and passes the result to its neighbor. One Google Cloud MXU runs about 16,000 multiply-accumulate operations per cycle, taking bfloat16 inputs and accumulating the results in higher-precision FP32. Doing thousands of multiplications per cycle without repeated memory reads is why a TPU can outrun a general-purpose chip on the matrix math a neural network needs.
A neural network layer produces its output by multiplying a matrix of weights by its inputs, and a large model repeats that billions of times, so matrix multiplication is most of the work. A multiply-accumulate, the MXU's basic step, is one piece of that: multiply two numbers and add the result to a running total. Packing tens of thousands of these cells into one grid lets the MXU finish a full matrix multiplication in a fraction of the cycles a general-purpose core would take.
A TPU is built around one or more TensorCores, and each TensorCore combines an MXU with a vector unit and a scalar unit. The MXU carries the matrix multiplication, and the other two units handle everything around it.
The vector unit runs the general element-wise math, such as applying activation functions and computing softmax over the MXU's output. The scalar unit handles control flow, memory addresses, and the housekeeping that keeps data moving to the MXU on time. Splitting the work this way keeps the systolic array busy: the MXU does the heavy multiplication while the vector and scalar units feed it and clean up after it.
Feeding the array fast enough matters as much as the array itself. Modern TPUs pair the MXU with high-bandwidth memory on the same package, so weights and activations reach the systolic array without stalling it. A fast unit starved of data sits idle, which is why each TPU generation has raised memory bandwidth alongside raw compute.
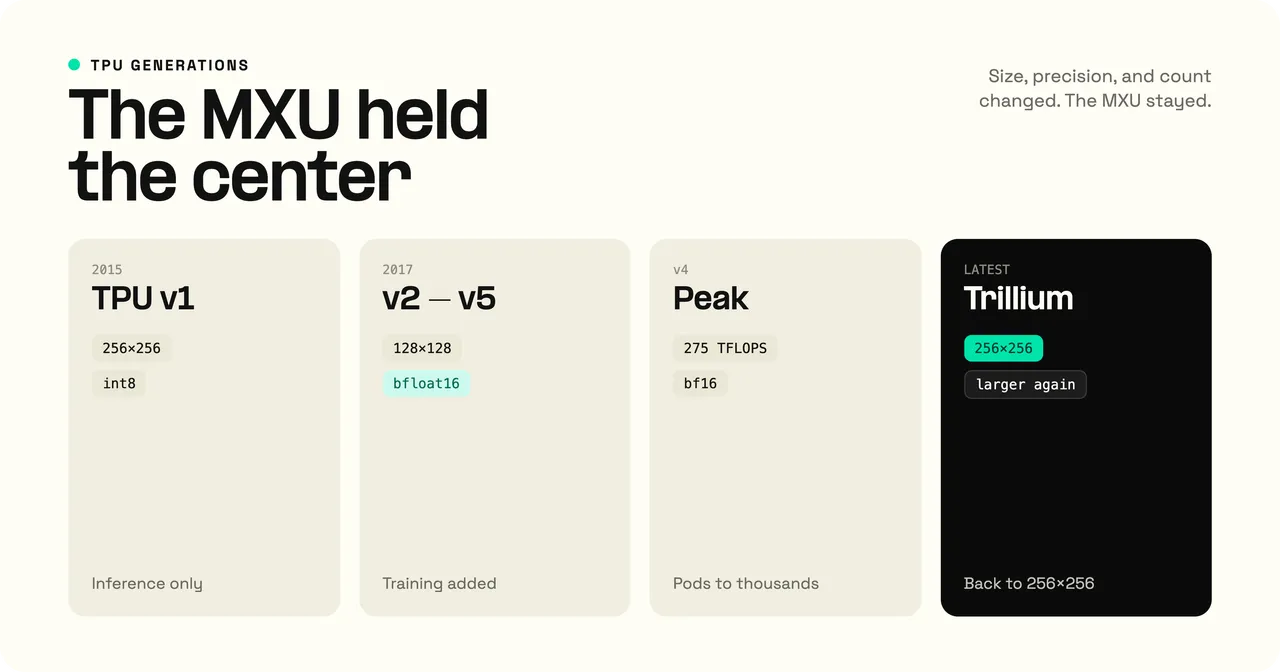
Google has shipped several TPU generations since 2015, and each one raised throughput, memory bandwidth, and the size of the pods the chips form. The first TPU (2015) was inference-only and did its matrix math in 8-bit integers on a 256x256 MXU. The second generation (2017) added training and switched to the bfloat16 format, and generations from the second through the fifth use a 128x128 MXU, often several per TensorCore.
The move from 8-bit integers to bfloat16 mattered because training needs a wider numeric range than inference, so the format change is what let the second generation train models rather than only run them. Peak throughput climbed with each step, reaching 275 teraFLOPS in bfloat16 on the fourth generation, and pods grew from around a thousand chips to several thousand wired together by a dedicated interconnect. The most recent generation, Trillium, returned to a larger 256x256 MXU. Across all of them the MXU stayed the center of the design; what changed was its size, its numeric precision, and how many worked together.
TPUs are used to train and run large neural networks where the workload is dominated by matrix multiplication. That covers most modern deep learning: large language models, image and speech models, recommendation systems, and other networks large enough that a single accelerator is not enough.
TPUs handle both stages of a model's life: the compute-heavy training runs, and the lower-latency inference that serves predictions once a model ships. Google also builds a much smaller Edge TPU for running trained models on devices, away from the data-center pods.
At that scale TPUs are wired into pods, groups of chips connected by a high-speed interconnect so they act as one machine, which is how Google trains frontier models and serves them inside its data centers. For a team, the appeal is throughput per dollar on matrix-heavy training and inference, provided the model runs in a supported framework and on Google Cloud.
TPU stands for Tensor Processing Unit. The name comes from the tensor, the multi-dimensional array of numbers that neural networks operate on, and the chip is built to multiply those tensors quickly.
A GPU is a flexible parallel processor that suits graphics, scientific computing, and a wide range of AI models, while a TPU is narrower and tuned for the matrix multiplication at the heart of neural networks. Which one wins depends on the model and the stack. The TPU vs GPU comparison covers the tradeoffs for training and inference in detail.
Google designs the TPU and has built every generation since 2015. It is Google's own accelerator, not an industry-wide standard, so other vendors ship their own AI chips rather than TPUs. Google keeps TPUs in its data centers and offers them as a cloud service instead of selling the data-center chips outright.
You cannot buy a data-center TPU to install yourself; Google offers them through Google Cloud, where you rent access by the hour. The exception is the Edge TPU, a small version sold as hardware for running models on devices at the edge.
A TPU's strength is also its limit: because it is specialized for matrix math, it is less flexible than a GPU for workloads that fall outside that pattern. It also ties you to Google Cloud and to the frameworks Google supports, so a model built for other hardware may need changes to run well on one.
A TPU pod is a group of TPU chips linked by a dedicated high-speed interconnect so they act as one large accelerator. Pods have grown from about a thousand chips in early generations to several thousand, which is what lets Google train models too large for any single chip to hold.
ChatGPT runs on GPUs, not TPUs. OpenAI trains and serves its models on NVIDIA GPUs through Microsoft Azure, so the TPU, which is specific to Google's own infrastructure, is not part of that stack.
This content was generated with the assistance of AI. Our AI prompt chain workflow is carefully grounded and preferences .gov and .edu citations when available. All content is reviewed by a Telnyx employee to ensure accuracy, relevance, and a high standard of quality.