Semi-structured data organizes itself with tags or keys instead of a fixed table schema. What it is, examples like JSON, XML, and CSV, and how it is stored.

Updated October 2026
Semi-structured data is data that organizes itself with metadata, such as tags or keys, instead of fitting a fixed table schema. It combines features of structured data, which sits in rows and columns defined in advance, and unstructured data, such as free text and images, which has no built-in organization. JSON, XML, and email are common examples: each record labels its own fields, so two records can differ in shape.
That freedom to differ makes semi-structured data easy to produce and harder to use. An application can add a field without changing any database schema, but every program that reads the data has to find the structure record by record.
Semi-structured data is self-describing: the labels that say what each value means are stored in the record, next to the values. A relational database works the other way. A table declares its columns and their types once, and every row must fit them before it is written, an approach called schema-on-write.
Semi-structured data reverses the order of schema and data. A JSON document carries its own field names, and the program that reads it decides how to interpret them, an approach called schema-on-read. The same document can be read by a program that needs every field and by one that needs only two.
That gives one test for whether data is semi-structured: the labels travel inside each record, and the system that stores the records accepts records of differing shape. JSON and XML are formats that usually hold semi-structured data. A producer's documented format, or a consumer that validates what it receives, does not change that. Data in the same formats becomes structured when the store itself declares a schema and rejects records that break it.
Semi-structured data got its name in the 1990s, when database researchers wanted to query sources such as the web that could not be held to a schema. In a 1997 tutorial, Peter Buneman described semi-structured data as data in which the information normally associated with a schema is contained within the data.
Buneman modeled semi-structured data as a tree or graph whose edges carry labels; in his example of a movie database, the labels are names such as movie and title. A JSON object maps onto that model directly: each key is a labeled edge, and each nested object is a subtree. Arrays fit too, since Buneman notes that they can be represented by labeling edges with integers.
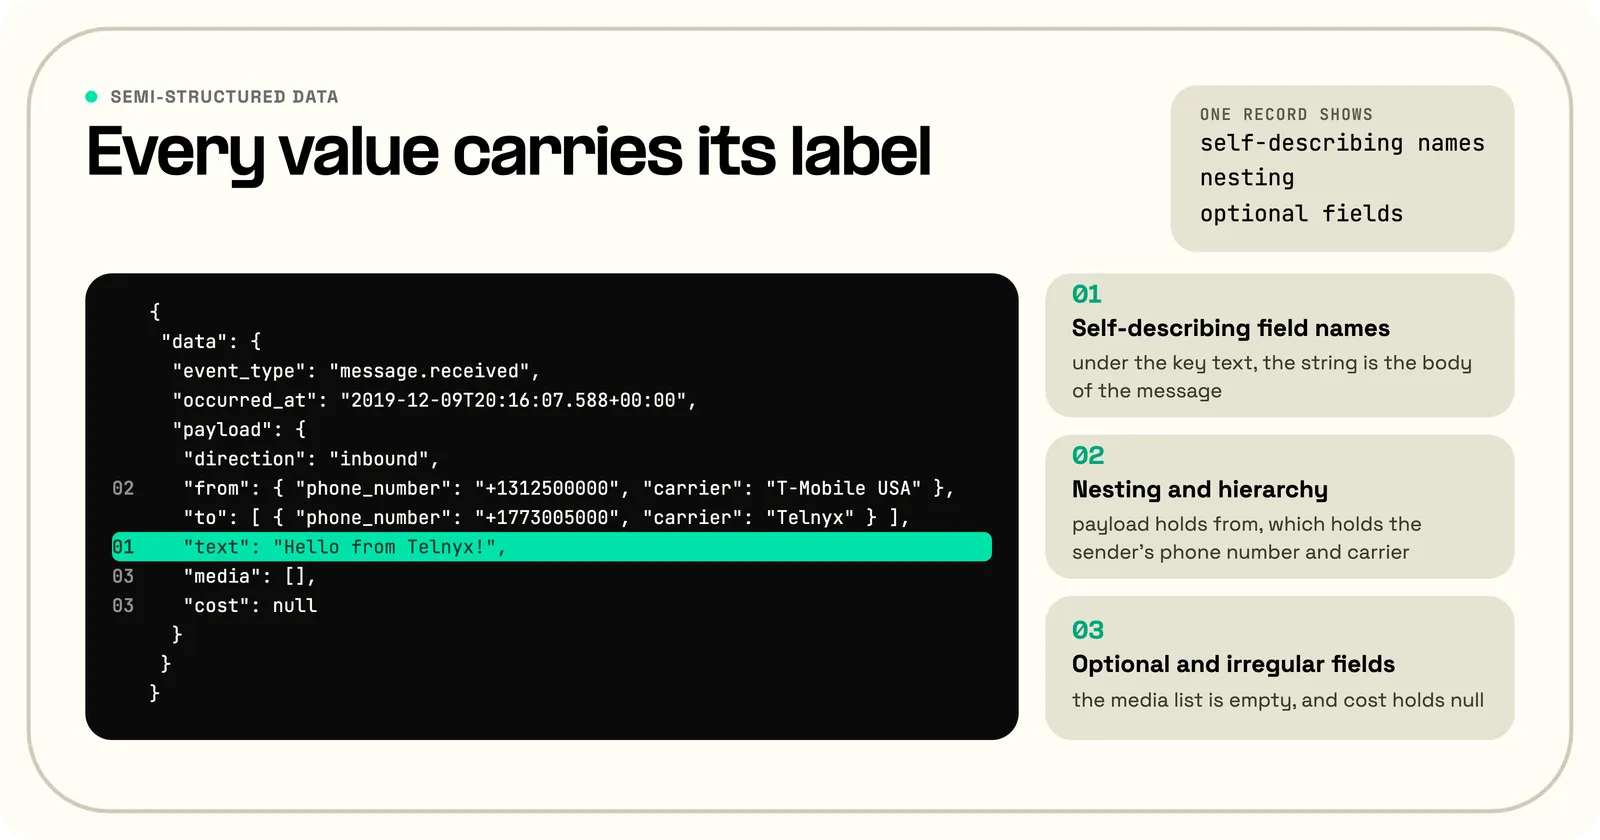
The characteristics of semi-structured data all follow from records that describe themselves: field names stored with the values, nesting, optional fields, a schema that can change, and values of mixed types. A text message delivered to an application as a Telnyx webhook event shows the first three; the other two need more than one record. A webhook is an HTTP request that one system sends to a URL another system registered, carrying an event. This copy is abridged from the example in Telnyx's webhook documentation:
{
  "data": {
    "event_type": "message.received",
    "occurred_at": "2019-12-09T20:16:07.588+00:00",
    "payload": {
      "direction": "inbound",
      "from": { "phone_number": "+1312500000", "carrier": "T-Mobile USA" },
      "to": [ { "phone_number": "+1773005000", "carrier": "Telnyx" } ],
      "text": "Hello from Telnyx!",
      "media": [],
      "cost": null
    }
  }
}Every value in a semi-structured record arrives with its label. The string "Hello from Telnyx!" means nothing alone; under the key text, inside an event whose event_type is message.received, it is the body of an inbound text message.
Semi-structured records nest. The payload object holds a from object, which holds the sender's phone number and carrier, so the record is a tree rather than a flat row. A relational design would split the same message across several tables and join them back together by key.
Fields in semi-structured data can be present, empty, null, or absent from one record to the next, and a program that queries the data has to treat each case separately. The media list is empty for this plain text message, and cost holds null, a value that says the field exists but has nothing in it. An absent key says nothing at all, so a query that looks for it finds no field rather than a null.
A store that holds semi-structured data accepts a record whose shape differs from the last one. Optional fields are variation between records produced at the same time; a flexible schema is the producer changing the shape over time. A sender can add a field to its events without a migration, the planned change a relational database needs before a new column can exist. A reader that does not use the new field can skip it.
In semi-structured data the same field can hold different types from one record to the next when the store declares no type for it. A product catalog's price can be a number in one record and the string "on request" in the next. A JSON store accepts both, where a typed column would reject the string. JSON also has no date type, so the event's occurred_at timestamp travels as a string that every reader has to parse.
Common examples of semi-structured data are JSON documents, XML files, HTML pages, email messages, and log files. Each marks up its content with names or tags that a program can read without understanding the content itself.
JSON (JavaScript Object Notation) stores data as objects of named fields, lists, and values, nested inside one another. RFC 8259, the standard that defines JSON, allows seven kinds of value: an object, an array, a number, a string, true, false, and null. Web APIs and webhooks, such as the Telnyx event above, commonly exchange JSON.
XML (Extensible Markup Language) wraps each value in named start and end tags, such as <carrier>T-Mobile USA</carrier>, and nests elements inside elements. The W3C XML specification defines the syntax, and a schema that fixes which elements a document must contain is optional, which keeps plain XML semi-structured. Telnyx's TeXML writes call flows as XML, with call instructions given as elements called verbs and nouns, such as <Dial> and <Number>.
HTML is semi-structured in the same way as XML. Tags mark the role of each piece of text, such as a heading, a list item, or a table cell, while the text inside them is free prose. A program can collect every heading on a page without understanding a word of it.
An email message is semi-structured: the headers are labeled fields, such as From, To, Date, and Subject, defined by the Internet Message Format, and the body below them is unstructured text.
Log files are semi-structured when each line labels its fields, as JSON lines or key=value pairs do. A plain-text log line, such as a timestamp, a severity level, and a message, works like an email instead: a fixed head identified by position, followed by a free-text tail.
CSV (comma-separated values) is grouped with structured data. RFC 4180, which documents the common CSV format, expects each line to hold one record with the same number of fields. The file's column order therefore works like a table's columns: one layout, set once, that every row follows. Fields are identified by position rather than by a label in each record, which fails the test for semi-structured data.
What a CSV layout leaves out is types. The header row is optional and no data types are declared, so a program cannot tell whether 02134 is a number or a ZIP code that must keep its leading zero. Loading CSV into a database therefore means declaring the column types at load time.
Semi-structured data comes from two kinds of sources: systems that exchange records with each other, and people whose writing passes through a format or template that adds labels. Machine-generated sources include web API responses, webhooks, application and server logs, IoT sensor readings, and configuration files. One system writes each record for another system to read, and most label every field, because the reader is a program that needs the names.
Human-generated sources include email, web pages, and business documents such as invoices and order forms. A person writes the content, and the format or template supplies the labels around it: the email headers, the HTML tags, the "Invoice number" printed beside the number.
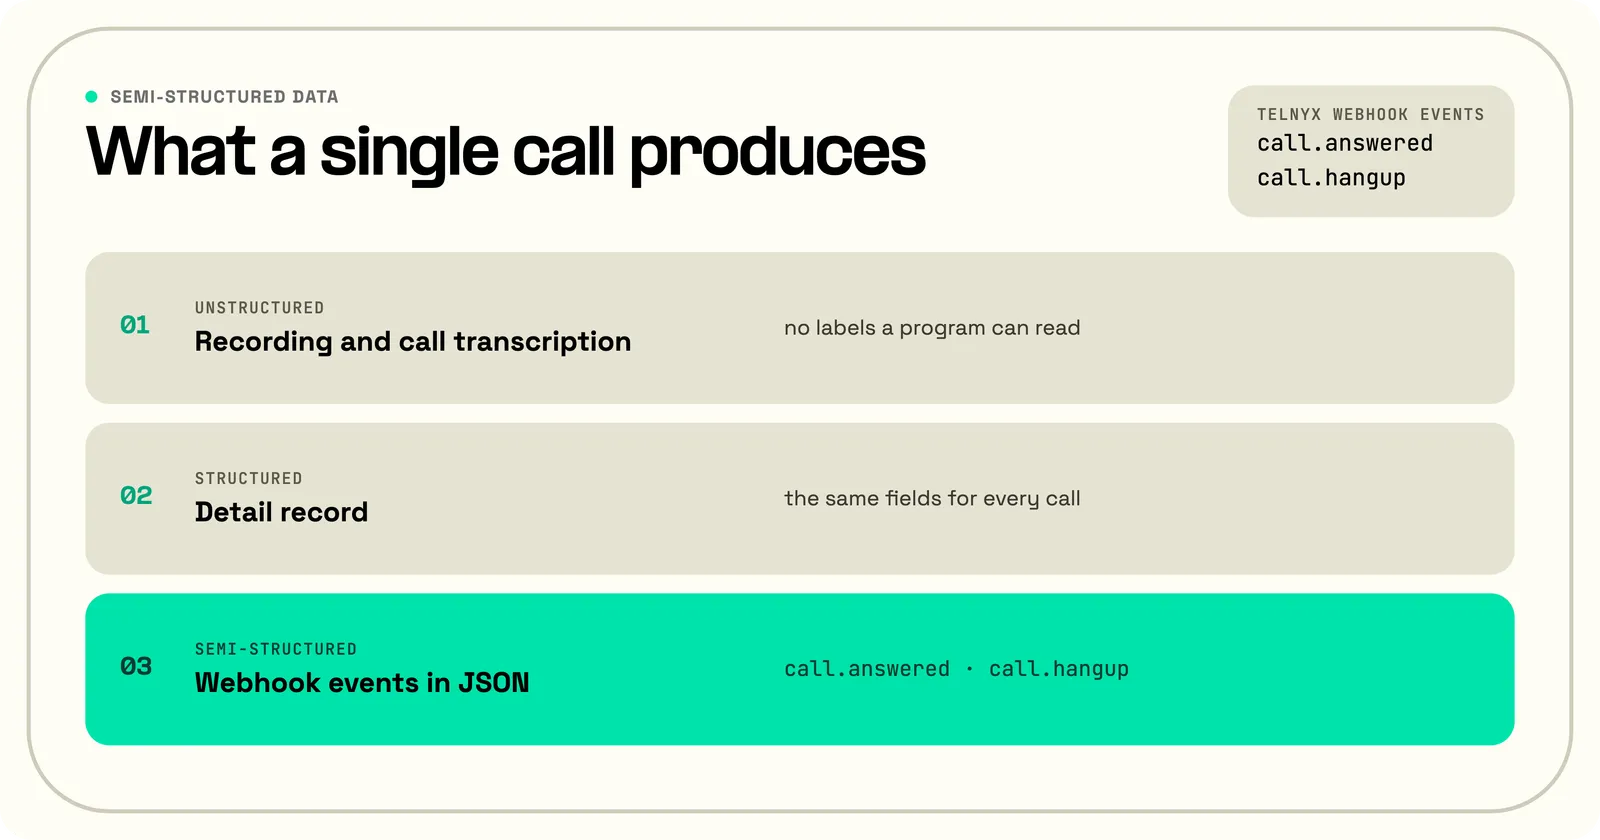
A single phone call produces structured, semi-structured, and unstructured data at once. The recording, and the call transcription made from it, are unstructured. The call's detail record, the per-call record kept for billing and reporting, is structured, with the same fields for every call. The events Telnyx sends to the application's webhook as the call progresses, such as call.answered and call.hangup, are semi-structured JSON, like the message event above.
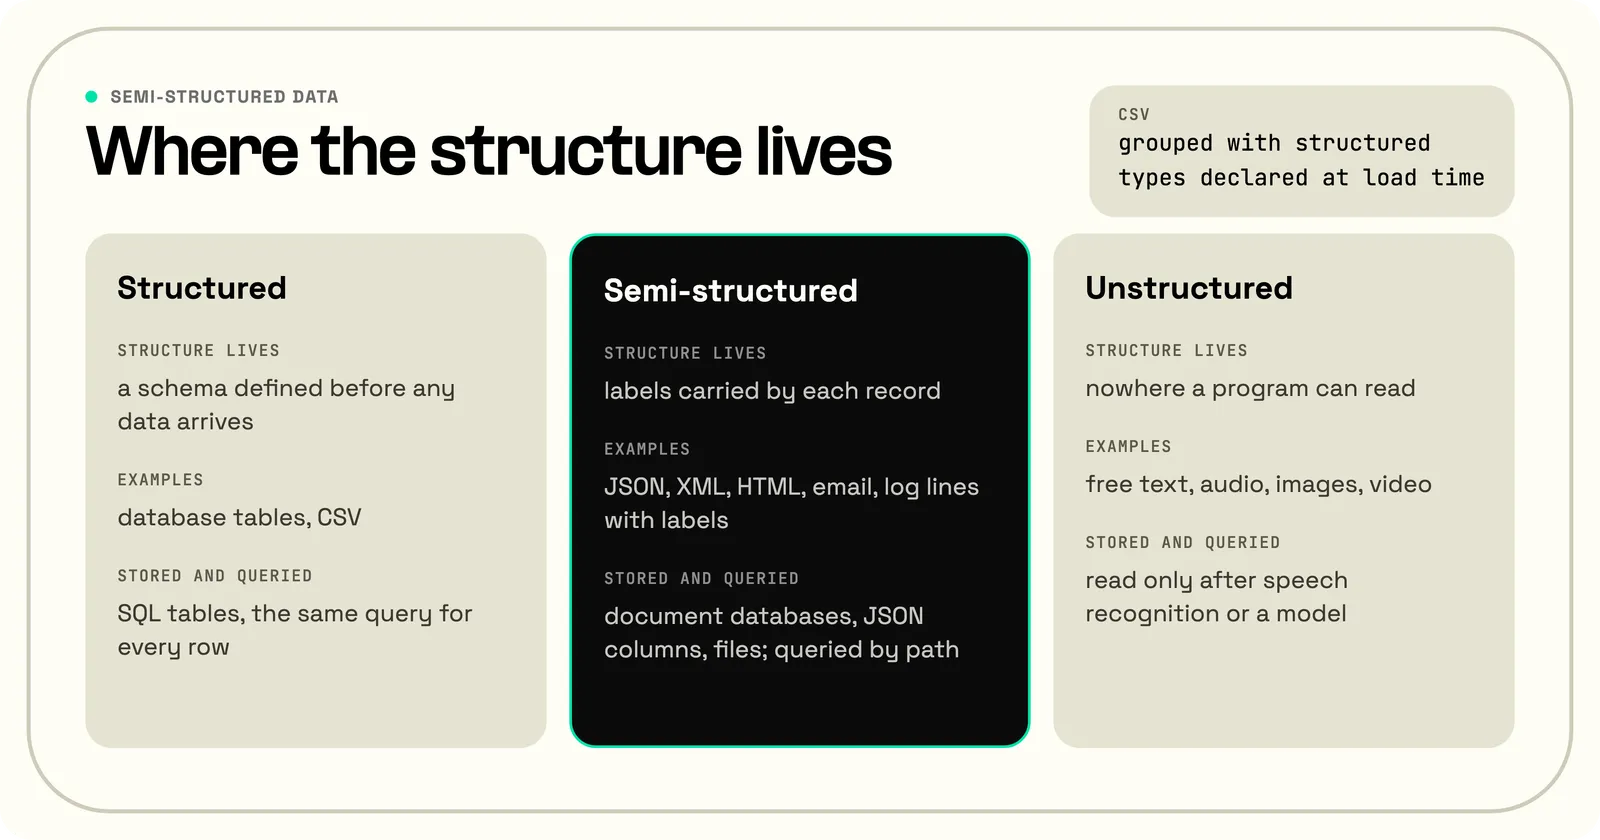
Structured, semi-structured, and unstructured data differ in where the structure lives: in a schema defined before any data arrives, in labels carried by each record, or nowhere a program can read. Structured data fits a schema written in advance, such as a database table with named, typed columns. Every row has the same fields, so the database can check each value on the way in and SQL can query every row the same way.
Semi-structured data carries its labels with it, so records can add, omit, or nest fields. It lives in document databases, in JSON columns inside relational databases, and in files, and programs query it by the path to a field rather than by a fixed column.
Unstructured data, such as free text, audio, images, and video, has no labels a program can read without first interpreting the content. A recording becomes searchable only after speech recognition turns it into text, and that text becomes queryable fields only after a parser or a model extracts them.
The main advantages of semi-structured data are flexibility, easy exchange between systems, a format people can read, and nesting that keeps related values together. Flexibility comes first: a record holds exactly the fields it needs. A product catalog can store a shirt with a size and a laptop with a processor in the same collection of records. Neither needs empty columns for every attribute of every product.
Semi-structured data is also easy to exchange: two systems that trade JSON or XML agree on a contract of field names and types that neither side's database has to enforce. RFC 8259 describes JSON as language-independent, so a sender written in one programming language can feed a reader written in another.
Text formats such as JSON and XML are readable by people too. An engineer can open a webhook payload or a log line and see what happened without special tools. A store may keep the same data in a binary form, such as MongoDB's BSON, that trades readability for speed.
Nesting, the hierarchy described under the characteristics above, keeps related values together, so a program reads a whole message, with its sender and recipients, in one step.
The challenges of semi-structured data come from its flexibility: nothing guarantees what a record contains, so programs must validate what arrives and handle fields that are missing, nested, or typed differently. Validation is the first defense. JSON Schema, a declarative language for defining the structure and constraints of JSON data, lets a team state which fields a record must have and what type each holds. Incoming records are then checked against that schema.
Validation at the consumer keeps the data semi-structured, because the labels still travel with each record and the store still accepts other shapes. A schema can also check a required core of fields and leave the rest open.
Schema drift is the quieter risk: it is the flexible schema as a consumer experiences it. An added field is usually safe, but when a producer renames a field or changes its type, every consumer that relied on the old shape can break. With no store schema to reject the change, it can ship unnoticed.
Semi-structured data also costs more effort to query and analyze. Nested and irregular records do not fit the rows and columns that most analytics tools expect, so teams often flatten them into tables before analysis. Text formats also repeat every field name in every record, which takes more space than a table that names each column once.
Semi-structured data is stored as whole records or as values inside relational tables, and it is queried by the path from the top of a record down to a field. That path is the sequence of labeled edges in Buneman's model: in the webhook event above, it runs through data, payload, and from to carrier.
JSONPath writes that path as $.data.payload.from.carrier, and XPath does the same job for XML. MongoDB, a document database, writes it in dot notation as "data.payload.from.carrier".
Document databases keep each record whole. MongoDB stores records as BSON, a binary form of JSON with more data types. Its data modeling documentation notes that documents in a single collection do not need to have the same set of fields.
Relational databases added semi-structured column types alongside their fixed columns. PostgreSQL's JSON types come in two forms. The json type stores the original text, and jsonb stores a decomposed binary form that is slightly slower to write but much faster to process, because it needs no reparsing. A table that stores each webhook event in a jsonb column, with a GIN index, PostgreSQL's generalized inverted index over the keys and values inside each document, looks like this:
CREATE TABLE events (id bigserial PRIMARY KEY, body jsonb);
CREATE INDEX events_body_idx ON events USING GIN (body);

SELECT body #>> '{data,payload,from,carrier}' AS carrier
FROM events
WHERE body @> '{"data": {"event_type": "message.received"}}';
The #>> operator returns the value at a path as text, and @> finds the events that contain a given fragment, a test the GIN index speeds up. PostgreSQL also accepts the $.data.payload.from.carrier form through its SQL/JSON path functions, such as jsonb_path_query.
Files kept on disk or in object storage, a service that stores whole files by name, can be queried in place by engines that apply the schema at read time. DuckDB, for example, reads a JSON file named in a query, as in SELECT * FROM 'events.json';. It turns top-level keys into columns and nested objects into struct columns that dot notation can reach.
Automation tools read the labels in semi-structured data to find values without understanding a whole document, and AI models add labels when they turn unstructured text into named fields. Robotic process automation (RPA), software that repeats the clicks and keystrokes of a desk task, relies on reading those labels where they exist as text. UiPath's document types guide classes invoices, receipts, and bank statements as semi-structured. They follow no fixed form, but their format is common enough, and their data sits mainly in key-value pairs, such as a label and the amount beside it.
Document-processing tools use semi-structured for a page layout: labels printed on the page, in positions that vary. That is a layout category, not the data test on this page. A scanned invoice is an image until optical character recognition (OCR) turns it into text, and the text becomes semi-structured data once extraction pairs each label with its value.
Where RPA reads labels, large language models add them: they read unstructured text and write labeled fields, usually as JSON. Telnyx's structured insights, for example, have a model read a conversation and return JSON in a schema the user defines. The fields can hold values such as a sentiment or an issue category. Because every insight follows the same schema, the output behaves like structured data: the transcript stays unstructured, and the insight becomes a record a dashboard can count. Keyphrase extraction, which pulls the main terms out of free text, adds labels of a different kind. The result is a list of topics stored as a field on the document's record, which makes the document searchable by topic.
The same labels help a model read. A model given a JSON record sees the field names along with the values, which tell it what each value means.
CSV is grouped with structured data: every line follows the same column order, and fields are identified by position rather than by labels in each record. The file declares no types, so whoever loads it supplies them.
JSON is a format, and the data in it is usually semi-structured. Each JSON document carries its own field names, and nothing makes two documents share them unless a schema such as JSON Schema is enforced. The JSON standard calls JSON a format for representing structured data, meaning data with internal organization, not data that fits a schema declared in advance.
XML is a format, and the data in it is usually semi-structured: tags name each element and elements nest, but a document needs no schema to be well-formed XML. With an XML Schema enforced by the system that stores the documents, the same data behaves much like structured data.
Structured data follows a schema defined before the data is written, such as the typed columns of a database table, so every record has the same fields. Semi-structured data carries its field names inside each record, so records can add, omit, or nest fields without a schema change.
Semi-structured data is told apart from the other two kinds by its metadata: it combines features of structured and unstructured data, using tags or keys to organize content. Data organized only in rows and columns defined in advance is structured, and data with no built-in organization, such as images and free text, is unstructured. Its main advantage is that it can handle varied data formats and records of varied shape.
RPA bots can use semi-structured data when its labels, such as "Invoice number" or "Total due", exist as text and stay stable enough to search for. The layout can change from one document to the next as long as the labels hold. They cannot when a document is still an image that has not been through OCR, or when the labels vary too much to anchor on. Unstructured documents, such as contracts, lack those markers, so automating them usually needs a model that reads the text first.
A semi-relational database has schema-defined tables but a data model that is not purely relational; the term describes a database design, not semi-structured data. Google used it for Spanner, whose paper calls the data model "not purely relational." Every Spanner table must have primary-key columns that name each row, the way a key-value store names its entries. Standard SQL tables do not have to declare a key.
This content was generated with the assistance of AI. Our AI prompt chain workflow is carefully grounded and preferences .gov and .edu citations when available. All content is reviewed by a Telnyx employee to ensure accuracy, relevance, and a high standard of quality.