Sequence modeling is machine learning for data where order matters, such as text, speech, and time series. Types, how it works, and applications.
Updated September 2026
The order of data often carries the meaning. Reorder the words in a sentence and it can say the opposite; shuffle a day's stock prices and the trend vanishes. Sequence modeling is the branch of machine learning built for data like that: a model reads its input in order and carries what it has seen forward, so each prediction depends on the context before it.
Quick answer: Sequence modeling is a machine learning technique for analyzing, predicting, or generating data where the order of elements matters, such as text, speech, and time series. Unlike models that treat each input independently, a sequence model processes data in order and maintains a hidden state, a memory of previous inputs, that it uses to predict what comes next. Common sequence models include recurrent neural networks (RNNs), LSTMs, GRUs, and Transformers. It is a concept, not a product, and is unrelated to tools branded "Sequence AI."
Sequence modeling predicts the next element in a sequence from the elements before it, using the order and dependencies in the data. Unlike a model that treats each input independently, a sequence model is built to handle variable-length sequences and to capture how earlier elements shape later ones.
It does this by maintaining a state, or memory, across inputs. As the model reads each element it updates that state, so information from the start of a sequence can still influence a prediction at the end. That memory is what separates sequence modeling from ordinary classification or regression, where each input stands alone. The same idea covers three jobs: reading a sequence to understand it, predicting the next step, and generating a new sequence one element at a time.
A sequence model works by processing data one element at a time while keeping a running summary of everything it has read. It takes the current input and its own previous state, combines them, and produces both an output and an updated state that it passes to the next step. That loop is how order enters the model: the state at any point reflects the whole sequence up to it.
Before any of this, the raw sequence is turned into numbers. Words, audio frames, or time steps are converted into vectors, often through an embedding layer, so the model can do math on them. The model then reads those vectors in order and learns, during training, which patterns in the past predict what comes next.
Training uses ordered examples where the correct next element is known. The model predicts, a loss function measures how far the prediction is from the true next element, and the weights adjust to close the gap across millions of sequences. The hard part is long-range memory: a detail early in a long sequence has to survive many update steps to affect a late prediction, and the earliest sequence models struggled to carry it that far.
Generation runs the same loop with the model's own output looped back in. It predicts one element, feeds that prediction in as the next input, and repeats, which is how a language model writes a sentence one token at a time. This is called autoregressive generation, and it is why the same architecture can both read a sequence and produce a new one.
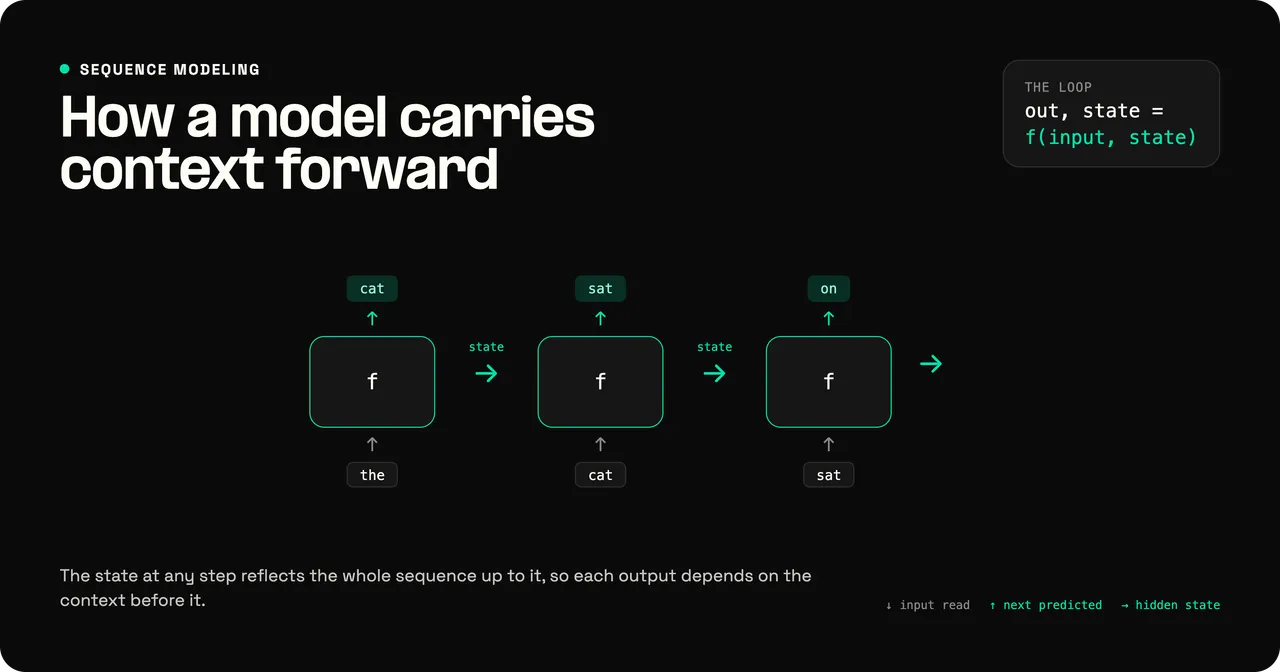
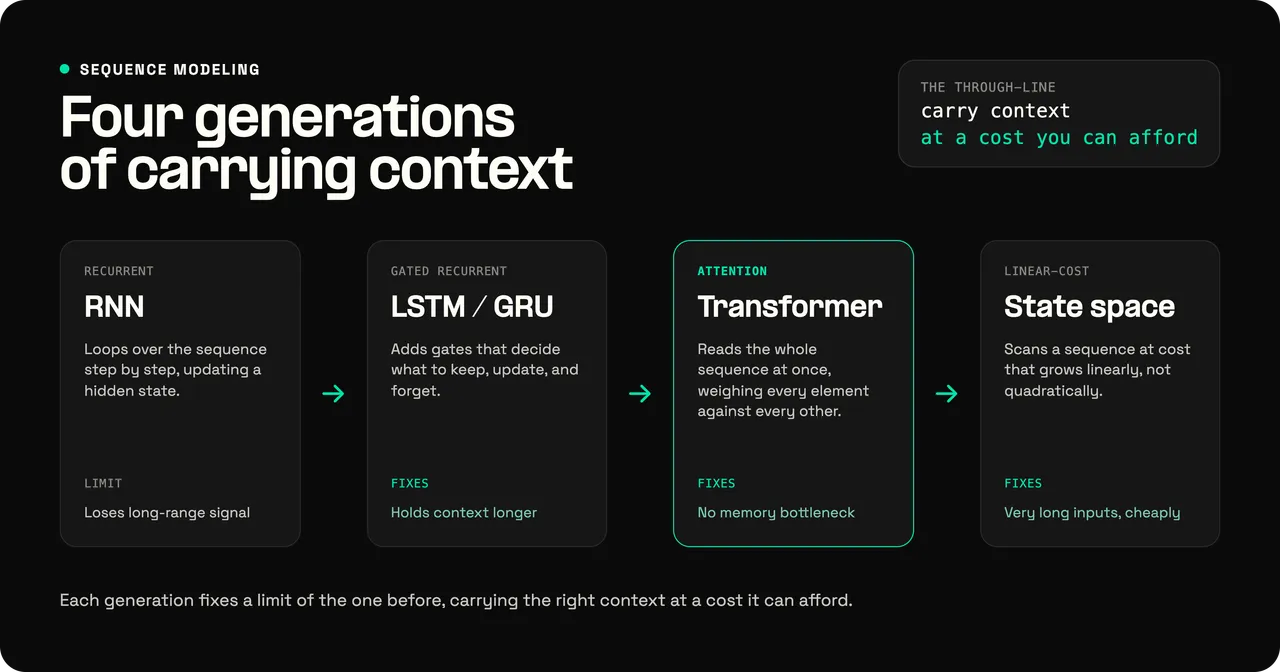
The main sequence models are recurrent neural networks, their gated variants LSTM and GRU, and Transformers, and they differ mainly in how they carry information across a sequence. Each generation was built to fix the memory limits of the one before it.
A recurrent neural network (RNN) is the original design: it loops over the sequence, updating a hidden state at each step. It works well on short sequences but struggles on long ones, because the signal from early elements fades as it passes through many steps, a problem known as the vanishing gradient.
Long short-term memory (LSTM) networks and gated recurrent units add gates, small learned controls that decide what to keep, update, and forget at each step. Those gates let the model hold onto important information across much longer spans, which is why LSTMs and GRUs replaced plain RNNs for most sequence tasks. A GRU is a simpler, faster variant of the LSTM with fewer gates.
Transformers took a different route: instead of stepping through the sequence, they use attention to look at all elements at once and weigh how much each one matters to every other. This removes the long-range memory bottleneck and processes the sequence in parallel rather than step by step. Transformers now power most large language models and have become the default for large-scale sequence work.
Two refinements cut across these models. Bidirectional models read a sequence both forward and backward, which helps when the whole input is available at once, as in classification, though not when a model must generate left to right. Attention is the idea that made the Transformer leap: rather than passing information hand to hand through the sequence, a model weighs distant elements directly. It first appeared as an add-on to RNNs before the Transformer built the entire architecture around it.
Transformers replaced RNNs for most large-scale tasks for two reasons: they handle long-range dependencies better, and they train far faster. An RNN must process a sequence in order, one step after another, so it cannot be parallelized across the sequence; a Transformer reads the whole sequence at once, which uses modern hardware far more efficiently. Attention also gives every element a direct path to every other, so a Transformer does not lose early context the way a deep chain of recurrent steps can.
A common point of confusion: ChatGPT is not an RNN. The GPT family is built on the Transformer, which is why it handles long context that recurrent models could not. RNNs, LSTMs, and GRUs are still used where sequences are short or compute is tight, but the frontier moved to attention.
One important pattern built on these models is sequence-to-sequence, or seq2seq, which maps an input sequence to a different output sequence, as in translating a sentence from English to French. Seq2seq uses an encoder to read the input and a decoder to generate the output; the encoder-decoder model covers that architecture in depth.
The core challenge in sequence modeling is long-range memory. Recurrent models lose early signal over many steps. Attention gives Transformers a direct path to distant elements, but its cost grows with the square of the sequence length, so very long inputs become expensive to process. Variable-length sequences add another wrinkle: the same model must handle a three-word query and a three-page document, and the amount of context it needs shifts from one input to the next.
Recent work targets the long-sequence problem directly. State space models such as S4 and Mamba process a sequence with cost that grows linearly rather than quadratically, which makes very long inputs practical. They have become an active alternative to attention for tasks like long-document and genomic modeling. The through-line across every generation, from RNNs to Transformers to state space models, stays the same: carry the right context across the sequence at a cost you can afford.
Sequence modeling underpins most tasks where data arrives in order. In natural language processing it drives translation, summarization, sentiment classification, and the large language models behind modern chat assistants, all of which treat text as a sequence of tokens.
Speech is sequential too. Speech recognition reads a sequence of audio frames and produces text, and neural text-to-speech runs the reverse, turning a sequence of words into audio. Both depend on a model that can track context across time rather than judging each frame alone.
Beyond language, sequence models forecast time series such as stock prices, energy demand, and sensor readings, where the goal is to predict future values from past ones. The same models drive demand forecasting and anomaly detection, flagging a reading that breaks the pattern the sequence had established. They also run in computational biology, where DNA and protein chains are sequences whose order determines function, and in any domain where events unfold over time. The common thread is that the order of the data carries information a non-sequential model would throw away.
Common examples are recurrent neural networks (RNNs), long short-term memory (LSTM) networks, gated recurrent units (GRUs), and Transformers. RNNs, LSTMs, and GRUs process a sequence step by step while carrying a hidden state; Transformers use attention to read the whole sequence at once. The Transformer is the basis of most modern large language models.
Yes, an LSTM is a sequence model. It is a type of recurrent neural network that adds gates to control what information it keeps and forgets at each step, which lets it hold context across longer sequences than a plain RNN. GRUs are a simpler variant of the same idea.
No, ChatGPT is not an RNN. It is built on the Transformer architecture, which uses attention instead of recurrence to model sequences. That is what lets it handle long stretches of context that recurrent models like RNNs and LSTMs struggle with.
Not usually. Convolutional neural networks (CNNs) are built for grid-like data such as images, where they detect local patterns. A one-dimensional CNN can process a sequence and is sometimes used for text or audio, but it captures mainly local context, so RNNs, LSTMs, and Transformers remain the standard choice when long-range order matters.
Transformers replaced RNNs for most large-scale tasks because they capture long-range dependencies better and train much faster. An RNN processes a sequence one step at a time, so it cannot be parallelized across the sequence, while a Transformer reads the whole sequence at once and gives every element a direct connection to every other through attention.
Sequence-to-sequence, or seq2seq, describes a model that maps one sequence to another, such as translating a sentence or summarizing a document. It uses an encoder to read the input sequence and a decoder to generate the output sequence, and it is the shape behind machine translation and many other language tasks.
This content was generated with the assistance of AI. Our AI prompt chain workflow is carefully grounded and preferences .gov and .edu citations when available. All content is reviewed by a Telnyx employee to ensure accuracy, relevance, and a high standard of quality.