AI speech enhancement uses neural networks to remove noise and reverberation from speech. How it works, the main methods, how it is measured, and its limits.

Updated October 2026
AI speech enhancement is the use of neural networks to make speech clearer by removing background noise, room reverberation, and other distortion from a recording or a live call. A model trained on pairs of noisy and clean speech learns to tell the voice apart from everything else. It then keeps the voice and turns down the rest, in audio it has never heard before.
Keeping the voice is the hard part. Every enhancement model guesses which parts of a sound belong to speech, and a wrong guess leaves behind sounds that were never in the recording. Speech recognizers are sensitive to those leftovers. Iwamoto and colleagues note that enhancement on a single microphone often gives a recognizer little benefit or makes it worse, and their experiments traced most of the damage to those artificial sounds. The same cleanup can help a caller and hurt the voice agent listening to that caller.
Speech enhancement is the signal-processing task of recovering one talker's speech from audio that noise, reverberation, echo, or the transmission path has degraded. AI speech enhancement is its neural network branch. The four kinds of damage behave differently:
Removing those degradations serves two goals that do not always move together. Quality is how clean and natural the speech sounds. Intelligibility is how many words a listener understands. In a listening study by Hu and Loizou, none of eight classical noise reduction algorithms significantly improved how many words normal-hearing listeners identified, except in a single noise condition. The algorithms that had ranked best for quality in earlier studies were not the ones that best preserved intelligibility.
A deep neural network changed that result, at least when the noise matched its training. In 2013, Healy and colleagues trained a network to estimate masks on one set of sentences and tested it on sentences it had not seen, mixed with the same two noise recordings, speech-shaped noise and babble. Intelligibility rose in every condition they tested. The gains were largest for listeners with hearing loss, several of whom went from scores near zero to above 70%.
Both studies tested single-channel algorithms, which work from one microphone's signal, and everything on this page concerns single-channel enhancement too. Phones, laptops, and conference devices with several microphones can also use the direction each sound arrives from, a technique called beamforming.
Every method on this page processes the audio signal. That separates speech enhancement from speech coaching, which scores how clearly a person talks, and from speech therapy, which trains a person to articulate. A soundbar's speech enhancement setting uses the term in this signal-processing sense, for the dialogue in a TV mix.
A speech enhancer takes speech audio in and returns the same words with less background noise and reverberation, and some enhancers also rebuild sound a damaged recording lost. Speech enhancers run in three places, and the place decides how much time and computing power the model gets. Open-source models such as RNNoise and DeepFilterNet, which run in real time on an ordinary CPU, can serve in any of them:
Speech enhancers, those two models included, also differ in what they output. Mask-based and filter-based models, including RNNoise and DeepFilterNet, reshape the sound already in the input instead of generating new speech. They still distort it: gains that jump between neighboring bands and frames leave behind isolated tones called musical noise, an artifact Iwamoto and colleagues link to masking and spectral subtraction. Generative models synthesize clean speech from what they recognize in the input. That lets them restore a muffled or clipped recording, and it also lets them produce sounds that were never recorded.
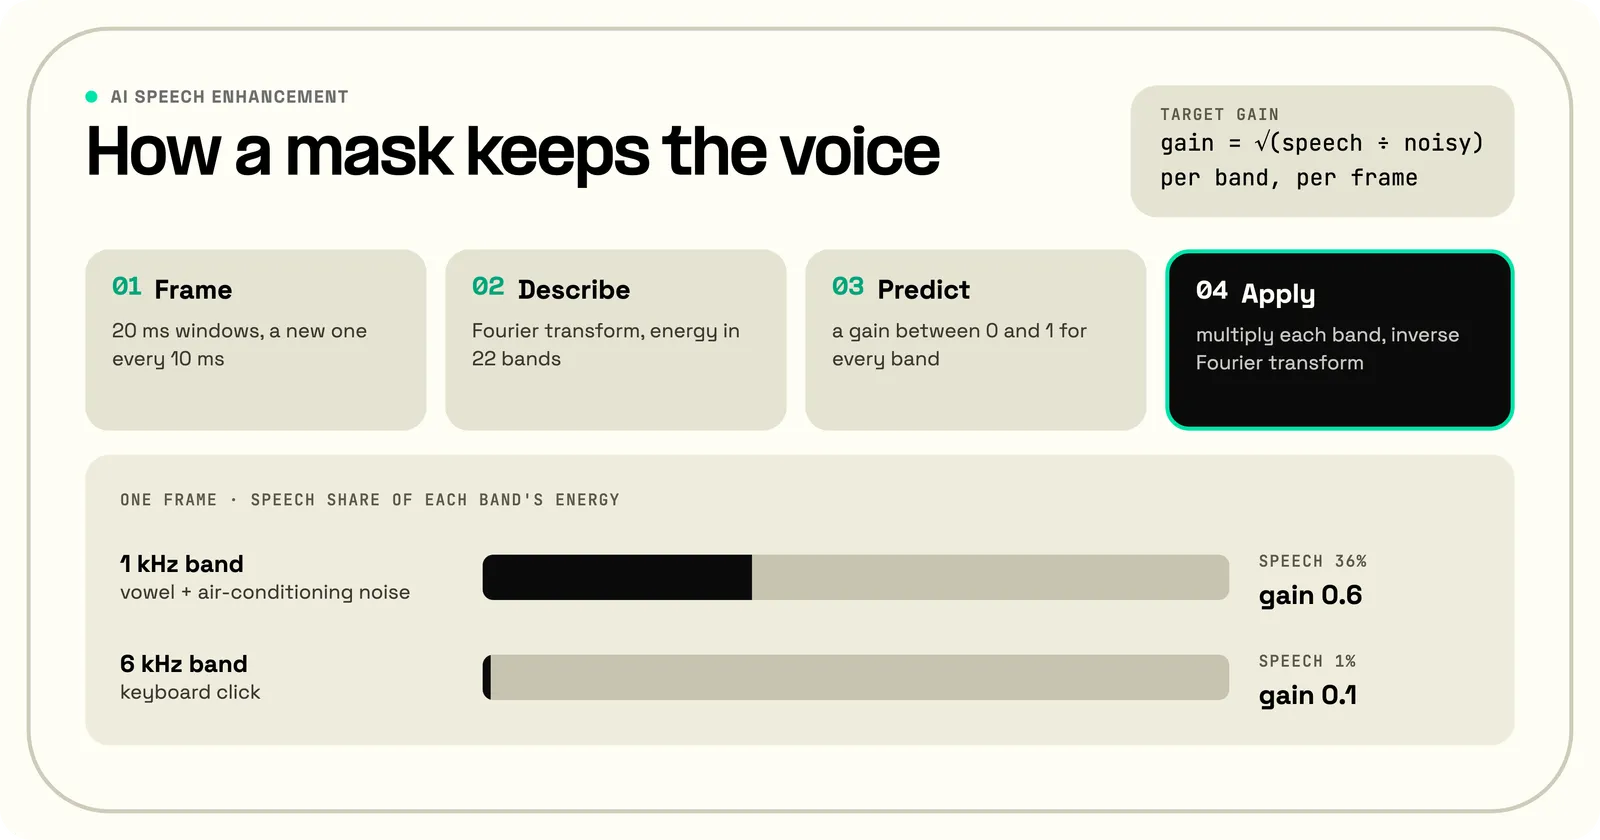
A common design for AI speech enhancement works on a spectrogram, a picture of how much energy each frequency carries at each moment. A neural network estimates what share of that energy belongs to speech, the model keeps that share and turns the rest down, and the result is converted back to audio. This mask-based design is the one RNNoise and DeepFilterNet use, and the steps below follow it. Waveform and generative models, covered in the next section, skip or replace some of these steps.
The network learns those gains from training examples built by mixing clean speech with recorded noise at many levels, so the right answer for every band is known. In RNNoise the target gain for a band is the square root of the clean speech energy divided by the noisy energy. Valin describes those gains as the square root of the ideal ratio mask, a common training target that measures how much of each region's energy is speech.
Mixing makes training data cheap, because any clean recording can be paired with any noise. Valin turned 6 hours of speech and 4 hours of noise into 140 hours of training audio this way. The Deep Noise Suppression Challenge later released a large open corpus of clean speech and noise for the same purpose.
The gain formula is easiest to see on one frame. A talker's vowel overlaps air-conditioning noise, and speech carries 36% of the energy in the band around 1 kHz. The target gain is the square root of 0.36, or 0.6. In the same frame a keyboard click fills the band around 6 kHz, where speech carries 1% of the energy, so the gain is 0.1. Each gain scales a band's amplitude, and energy goes with the square of amplitude, so gains of 0.6 and 0.1 leave 36% and 1% of the two bands' energy, the share that was speech.
A gain changes how loud each band is but not its phase, the timing information the Fourier transform also carries, so a simple mask reuses the noisy phase. Complex masks and the deep filtering in DeepFilterNet also adjust the phase, and the DeepFilterNet authors note that complex masks are usually preferred over real-valued ones for that reason.
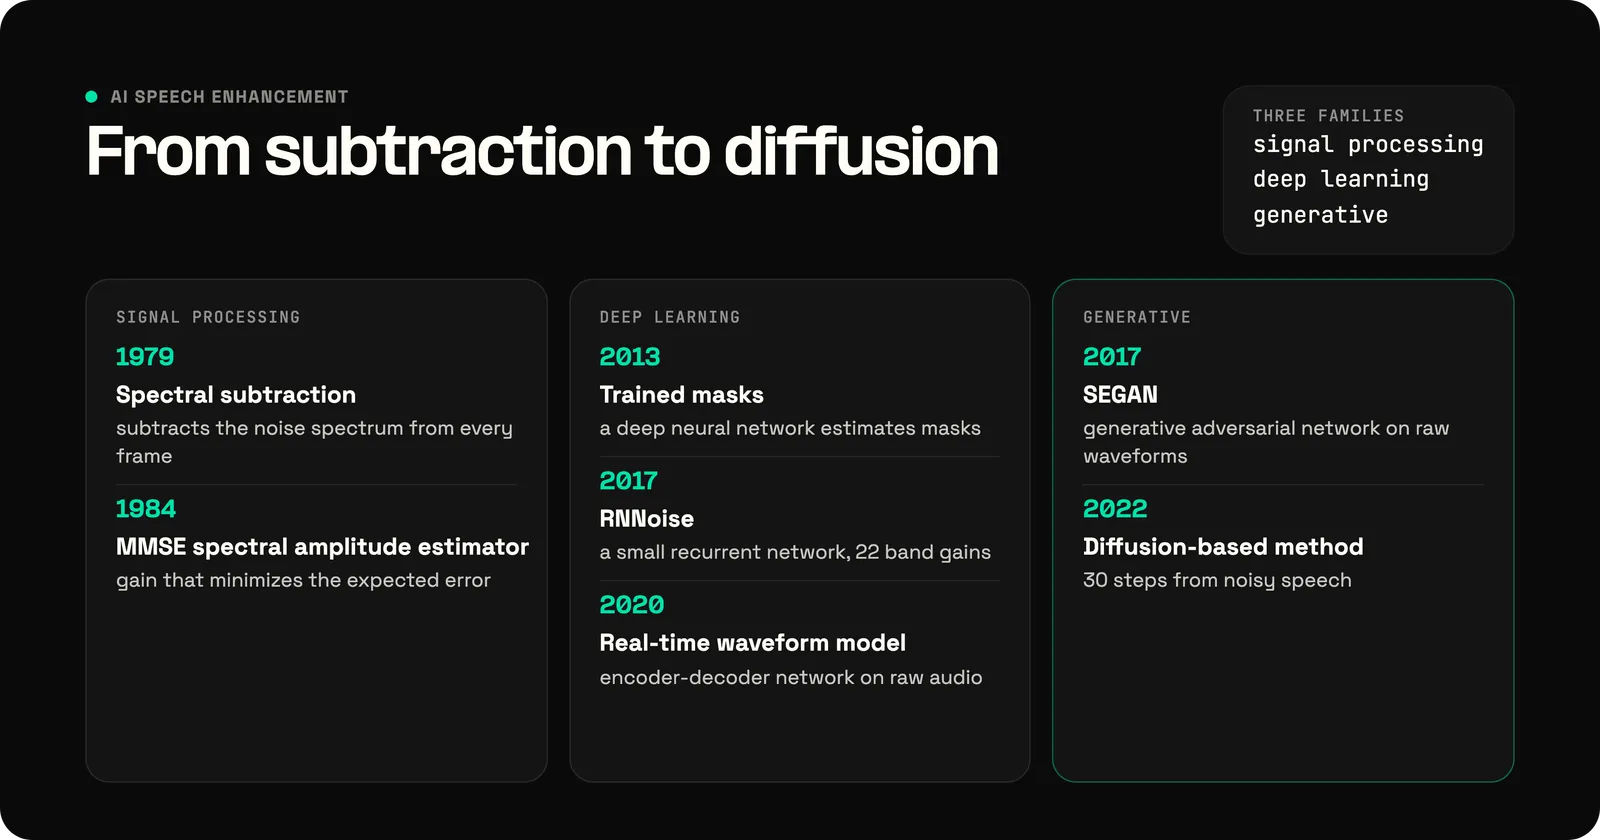
Speech enhancement methods divide into statistical signal processing, which estimates the noise from the signal itself and removes it, and deep learning, which learns what speech and noise sound like from training data. Generative models are the newest branch of deep learning methods.
Spectral subtraction, published by Steven Boll in 1979, estimates the noise spectrum during pauses in speech and subtracts it from every frame. The Wiener filter, applied to noisy speech in a review by Lim and Oppenheim the same year, scales each frequency by how much stronger speech is than noise there, so noise-dominated frequencies are cut hardest. The MMSE spectral amplitude estimator of Ephraim and Malah (1984) chooses the gain that minimizes the expected error in each band's amplitude, given a statistical model of speech and noise.
All three methods depend on an estimate of the noise. That estimate holds up for steady noise and falls behind noise that changes faster than it can be updated, such as babble and clicks. Valin's RNNoise paper starts from the same problem: classical noise suppressors work only as well as their hand-tuned estimators and parameters.
Supervised deep learning, surveyed by Wang and Chen, learns the relationship between noisy and clean speech from examples. Masking models predict a gain for each time and frequency region, as in the section above. Mapping models predict the clean spectrum directly. Waveform models skip the Fourier transform. The 2020 real-time model by Défossez and colleagues reads raw audio through an encoder-decoder network and runs on a laptop CPU. It removes stationary and non-stationary noise as well as room reverb.
Hybrid models sit between the classical and the fully neural approaches: they keep signal processing where it is cheap and use a network only where hand-tuning fails. RNNoise, published by Valin in 2017, has 215 units in four hidden layers and outputs 22 band gains, small enough to run on 48 kHz audio on a low-power processor. RNNoise also keeps a classical pitch filter, which removes noise between the harmonics of a voiced sound. DeepFilterNet learns that step instead, with a second stage that filters each frequency using neighboring frames to restore the pitch structure of voiced speech. Its real-time version runs at a real-time factor of 0.19 on one notebook CPU thread, so one second of audio takes about 0.19 seconds to process.
Generative speech enhancement produces clean speech rather than filtering noisy speech. SEGAN, from Pascual and colleagues in 2017, trained a generative adversarial network on raw waveforms. One network enhances the audio, and a second learns to tell enhanced speech from clean speech, which pushes the first to sound clean.
Diffusion models, the second generative family and the method behind many image generators, learn to remove noise step by step. The 2022 diffusion-based method of Richter and colleagues starts that process from the noisy speech mixed with random noise, rather than from pure noise, and needs 30 steps, each a full pass of its network over the audio, where a single-pass model makes one. It competes with recent discriminative models, the mask and mapping kind above, and generalized better to a test corpus it was not trained on.
General speech restoration goes further than noise removal. VoiceFixer repairs noise, reverberation, low resolution, and clipping in one model. It analyzes the damaged speech, then resynthesizes it with a neural vocoder, a network that turns a spectrogram back into audio.
Speech enhancement is measured in three ways: people rate the output in listening tests, intrusive metrics compare the output with the clean original, and non-intrusive models predict a listener's rating from the output alone. Listening tests are the reference the other two try to match. ITU-T, the UN body that sets telecom standards, defines a listening test for noise suppressors in P.835. Listeners rate the speech, the background noise, and the overall result separately, because an enhancer can improve one while harming another.
| Metric | What it measures | Needs the clean original? | Defined in |
|---|---|---|---|
| Listening test (P.835) | Listener ratings of speech, background noise, and overall quality | No | ITU-T P.835 |
| PESQ | Predicted quality of narrowband telephone speech | Yes | ITU-T P.862, deleted January 2024 |
| POLQA | Predicted listening quality, the successor to PESQ | Yes | ITU-T P.863 |
| STOI | Predicted intelligibility | Yes | Taal et al., 2011 |
| SI-SDR | Distortion between output and original in decibels, ignoring overall volume | Yes | Le Roux et al., 2018 |
| DNSMOS P.835 | Predicted P.835 ratings from the output alone | No | Reddy et al., 2021 |
| Word error rate | Share of words a speech recognizer gets wrong on the output | Needs a correct transcript, not clean audio | Standard speech recognition metric |
Intrusive metrics need the clean original, which exists only when the noise was mixed in on purpose. On a real call nobody has the clean version, so non-intrusive predictors carry the load in production. Reddy and colleagues trained DNSMOS P.835 on human ratings and report correlations of 0.94 with listeners for speech quality and 0.98 for background noise and overall quality. Papers still report PESQ, but the ITU deleted P.862 in January 2024 and now points to P.863.
Synthetic test sets, where the clean original is known, also flatter enhancement models. The organizers of the 2020 Deep Noise Suppression Challenge found that models scoring well on synthetic test sets often degraded significantly on real recordings. They also found that most conventional objective metrics did not correlate well with listening tests, which is why the challenge ranked entries by crowdsourced listener ratings.
AI speech enhancement trades noise removal against damage to the voice: the harder a model suppresses noise, the more it risks removing parts of the speech or adding sounds that were never recorded. RNNoise makes this trade explicit in training. Valin's loss compares predicted and true gains after raising both to a power, and the paper sets that power to 1/2, because lower values push the network toward suppression that is too aggressive. RNNoise also smooths its gains over time, because a fully cleaned signal can sound overly dry.
Real recordings expose the gap between training and use. Enhancement models learn from noise mixed into clean speech on a computer, and the Deep Noise Suppression Challenge results show that performance on those mixes overstates performance on real recordings. A model meets new microphones, rooms, and noises in production that its training mixes never contained.
Other talkers are the hardest noise to remove, because the noise is also speech. Separating one voice from other voices is speaker separation, which Wang and Chen treat as a different task from separating speech from non-speech noise. An enhancer needs some cue about which talker to keep, such as which voice is closest to the microphone.
Generative models add a risk of their own: invention. Richter and colleagues report that at very low signal-to-noise ratios their diffusion model sometimes produced vocalizing artifacts with no linguistic meaning, and generated breathing or speech-like sounds where no speech had been. For a transcript or a call recording kept as a record, an invented syllable is worse than leftover noise.
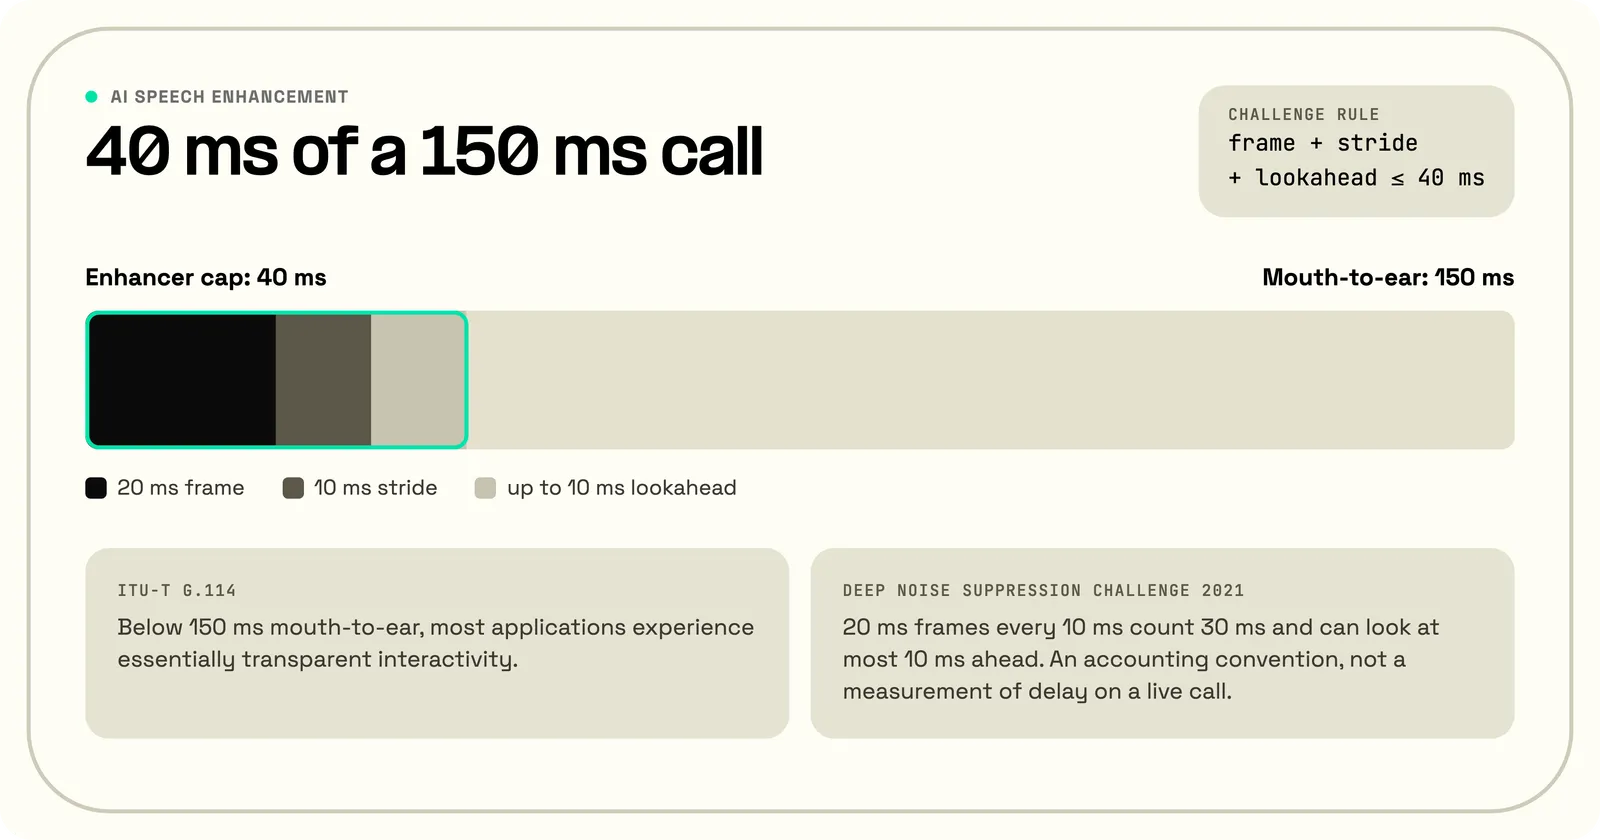
Real-time speech enhancement on a phone call processes each 10 to 20 millisecond slice of audio before the next one arrives and adds only a few tens of milliseconds of delay. The 2021 Deep Noise Suppression Challenge set a common budget for this. The frame length, the stride between frames, and any lookahead at future audio must add up to 40 ms or less. Each frame must also finish processing within the stride time on a quad-core laptop CPU. Under that rule, a model that reads 20 ms frames every 10 ms counts 30 ms toward the budget, the frame plus the stride, and can look at most 10 ms ahead. That figure is the challenge's accounting convention, not a measurement of delay on a live call.
That budget sits inside the delay a whole call can afford. The ITU's delay recommendation, G.114, says that when mouth-to-ear delay stays below 150 ms, most applications experience essentially transparent interactivity. An enhancer at the challenge's 40 ms cap would spend more than a quarter of that before the audio has crossed any network. In a voice agent, the same milliseconds add to response latency, alongside speech recognition, the language model, and speech synthesis.
Phone audio also limits what an enhancer can work with. Narrowband codecs such as G.711 sample audio at 8 kHz and carry the 300 to 3,400 Hz band of traditional telephone speech. That is about half the 50 to 7,000 Hz range that wideband codecs such as G.722 carry. RNNoise and DeepFilterNet process full-band 48 kHz audio, so a model chosen for phone calls should be tested on audio that has passed through a narrowband phone path.
Contact centers are the common case for call enhancement. Agents work in shared rooms with keyboard clicks, ventilation, and nearby conversations, the noise that Telnyx's configuration guide names for its telephony models. Network-side enhancement handles that noise on the call itself, without software on the agent's or the caller's device. Telnyx's Voice API starts noise suppression on a live call with one command, suppression_start, and can also apply it to every call on a SIP connection. Each direction of audio is processed and billed separately.
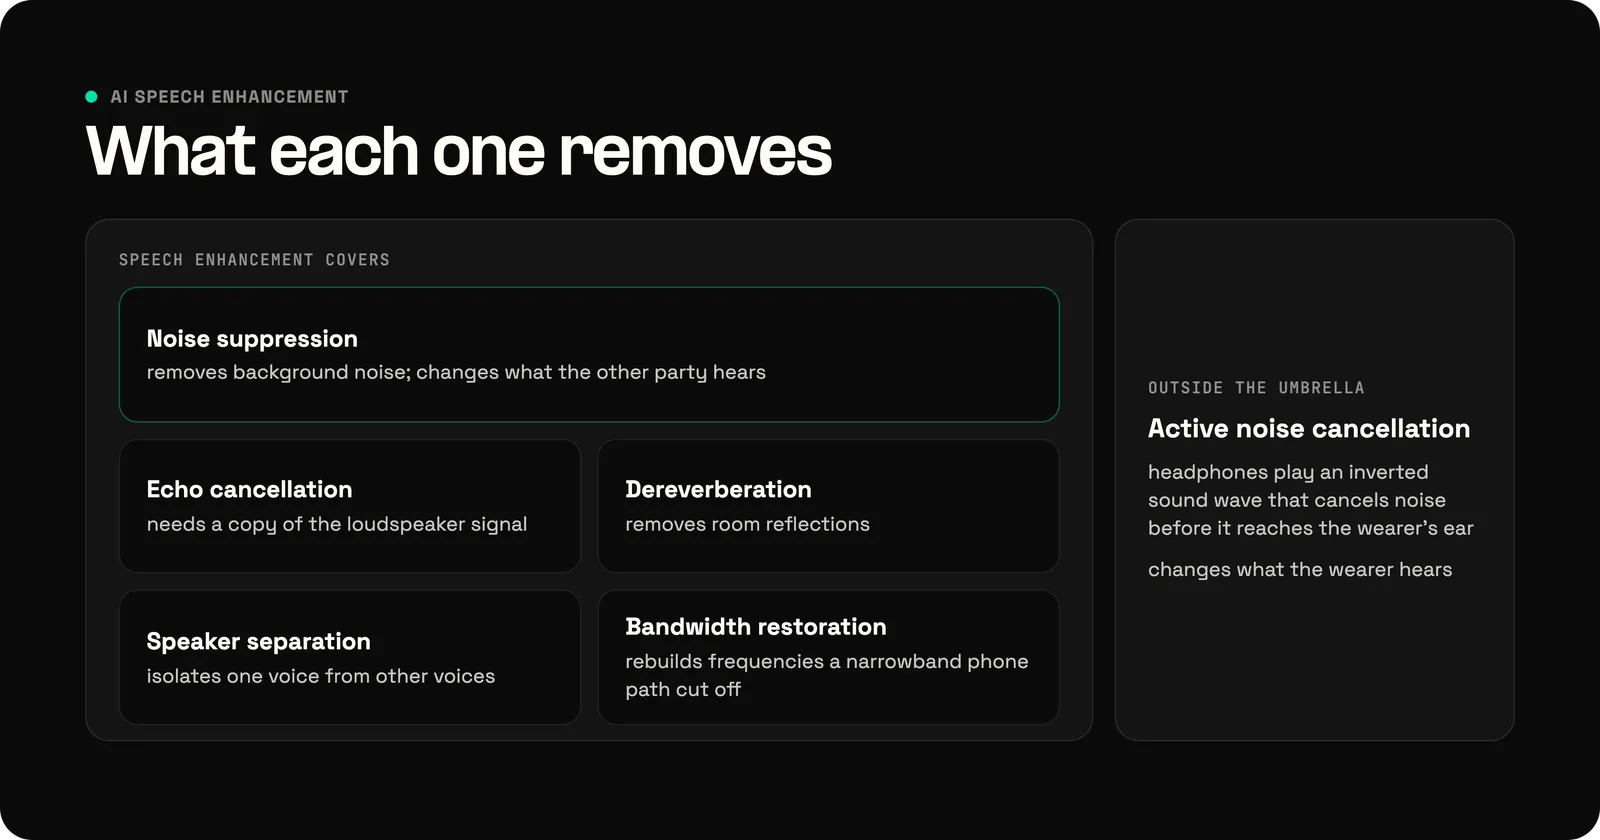
Noise suppression is the part of speech enhancement that removes background noise from a captured voice signal. Active noise cancellation works on the listener's side instead: headphones play an inverted sound wave that cancels noise before it reaches the wearer's ear. Speech enhancement is the umbrella term. It covers noise suppression plus the other cleanup steps: echo cancellation, dereverberation, speaker separation, and bandwidth restoration.
The terms blur in product names, and some calling apps label microphone noise suppression "noise cancellation." The two help different people. Noise suppression on a microphone changes what the other party hears. Active noise control, reviewed by Kuo and Morgan, changes what the wearer hears through a microphone and speaker in the earpiece. It does nothing for the other party.
Echo cancellation, dereverberation, and the remaining cleanup steps each target one degradation. Acoustic echo cancellation removes the other party's voice after a loudspeaker plays it and the microphone picks it up again. To do that, it needs a copy of the loudspeaker signal, which noise suppression does not. Dereverberation removes room reflections from the talker's own voice. Speaker separation isolates one voice from other voices. Bandwidth restoration rebuilds frequencies a narrowband phone path cut off.
Noise suppression is the right term for the setting on a call or in a meeting app. Speech enhancement is the right term for the field, and for tools that also fix echo, reverberation, or bandwidth.
Speech enhancement for a speech recognizer has a different target than enhancement for a person: the recognizer needs the acoustic detail that separates one word from another, even when the result sounds less pleasant. Iwamoto and colleagues split enhancement errors into leftover noise and artifacts, the parts of the output that are neither the speech nor the original noise. They found the artifacts were the main cause of lost recognition accuracy. Their fix was simple: adding a scaled copy of the original noisy audio back into the enhanced output improved recognition on both simulated and real recordings.
A voice AI agent therefore needs enhancement tuned for its recognizer, which can mean leaving some noise in. Telnyx tunes its call noise suppression by who listens downstream. The configuration guide pairs telephony models with human calls and contact centers, a far-field model with conference rooms and smart speakers, and a model built for speech-to-text pipelines and voice agents. That model, in the guide's words, "preserves the phonetic structure that transcription engines and voice agents depend on." Its audio may sound different to a human listener, by design. The guide does not say how that model differs internally, for example whether it limits how far it suppresses noise.
For speech recognition, Telnyx's noise suppression docs recommend suppressing the direction that carries the voice being transcribed, the setting Telnyx's voice AI agents use internally. The same docs offer the open-source DeepFilterNet as one of the engines, for full-band telephony and WebRTC audio. The docs do not publish the delay or the word error rate change for each engine, how the full-band engines handle narrowband calls, or whether any engine mixes original audio back in. All of those belong in the test below.
A team building a voice agent can measure the effect on its own calls:
The model that sounds cleanest to a person is not always the one with the lowest error rate.
Speech can be enhanced in real time on live calls and streams. Real-time models such as RNNoise and DeepFilterNet process audio in 20 ms windows and add tens of milliseconds of delay. The Deep Noise Suppression Challenge caps total algorithmic latency at 40 ms for its real-time track. Offline tools can run larger models over a whole recording, which a live call does not allow.
Noise suppression is better on for calls from noisy places, such as open offices, cars, or streets. It is better off when the sound itself matters, such as music. In a quiet room it has little noise to remove and can still alter the voice. For calls that a speech recognizer transcribes, the setting worth keeping is the one with the lower word error rate on real recordings.
AI can improve the quality of recorded and live speech, as measured by listener ratings and by metrics such as POLQA and DNSMOS. It does best on noise and rooms like those in its training data, and less well on real recordings that differ from its training mixes. AI cannot recover words that noise fully covered, except by guessing, which is what generative models do.
Free speech enhancement is available through open-source models. RNNoise is released under a BSD-style license and runs in real time on an ordinary CPU. DeepFilterNet is dual-licensed under MIT and Apache 2.0 and publishes pretrained weights. Both need some setup, such as a command-line tool, an audio plugin, or a few lines of code.
A one-click speech enhancer runs a pretrained neural network over a whole recording with preset settings, so no one has to tune it. Because the file is finished, the model can use the audio both before and after each moment, and it can be larger than a model built for live calls. Tools built on generative restoration regenerate the voice, which can rescue a muffled recording and can also add sounds that were never there.
Speech enhancement improves speech recognition accuracy when it removes noise without adding artifacts, and it can lower accuracy otherwise. Iwamoto and colleagues note that enhancement on a single microphone often gives a recognizer little benefit or makes it worse, and their experiments traced the damage mainly to the artificial sounds the enhancer added. Models tuned for machine listeners, and mixing some of the original audio back in, reduce that damage.
Speech enhancement outputs audio, cleaner speech for a person or a machine to listen to next, while speech recognition outputs text, the words in that audio. Enhancement can run before recognition in a voice pipeline. A recognizer does not need it to work, and a poorly matched enhancer can make the recognizer less accurate.
This content was generated with the assistance of AI. Our AI prompt chain workflow is carefully grounded and preferences .gov and .edu citations when available. All content is reviewed by a Telnyx employee to ensure accuracy, relevance, and a high standard of quality.