Steerability in AI is the capacity to guide a model's behavior toward a desired outcome. How steering works, voice steerability, measurement, and limits.

Updated October 2026
Steerability in AI is the capacity of users and developers to guide an AI system's behavior toward a desired outcome, such as a task, a format, a tone, or a limit on what the system will do. A system is steered through the instructions it receives, the feedback it is trained on, and adjustments to its parameters or internal state. A steerable system follows that direction and keeps following it.
Keeping to the direction is where steerability usually breaks. A chat assistant that adopts a requested tone in its first reply can lose it several exchanges later. The mechanisms that let a developer steer a model also let a determined user steer it somewhere the developer never intended.
In the model itself, steerability shows up as how far, and how predictably, its output moves when someone directs it. A highly steerable model can be pointed at many different behaviors and holds each one. A model with low steerability ignores some instructions or follows them only part of the time.
Who gives that direction depends on the point in a model's life. Model developers steer it during training, by fine-tuning it on examples and on human feedback. Application builders steer it at deployment, with a system prompt (standing instructions the model reads before every conversation) and with settings that limit what it may output. End users steer it at run time, with each request, follow-up, and correction.
Deployment and run-time instructions can conflict. Research on an trains models to rank them, giving the developer's system prompt priority over a conflicting user message, so that a support assistant told never to quote prices keeps declining when a user insists. In that study, the training improved the model's results on the authors' main safety tests by up to 63%, and a deployed model behaves this way only if its developer trained it to.
This content was generated with the assistance of AI. Our AI prompt chain workflow is carefully grounded and preferences .gov and .edu citations when available. All content is reviewed by a Telnyx employee to ensure accuracy, relevance, and a high standard of quality.
Outside AI, steerability means how easily something can be guided on a chosen course, the sense used for vehicles, ships, and medical catheters. Two technical fields use the word for something narrower than the language-model sense.
In image generation, steerability describes how far a generative adversarial network (GAN), a model that learns to produce images, can be moved along a direction in its latent space. The latent space is the internal space of codes the GAN generates images from. A study of GAN steerability found that moving along such directions can imitate camera moves and color changes, and that how far the moves go appears to depend on how varied the training data is.
In computer vision, a steerable filter is an edge or texture detector that can be turned to any angle by mixing a small set of fixed basis filters. Steerable CNNs carry the idea into neural networks whose features change predictably when the input image is rotated.
AI steering acts at one of four points: the input a model reads, the weights it learned in training, the activations it computes while it runs, and the output it is allowed to produce. The four differ in the access they need and how long their effect lasts. An instruction in the input needs no access to the model, and it lasts one conversation at most, often weakening before the conversation ends. A change to the weights needs the model and training data, and it lasts until the model is trained again.
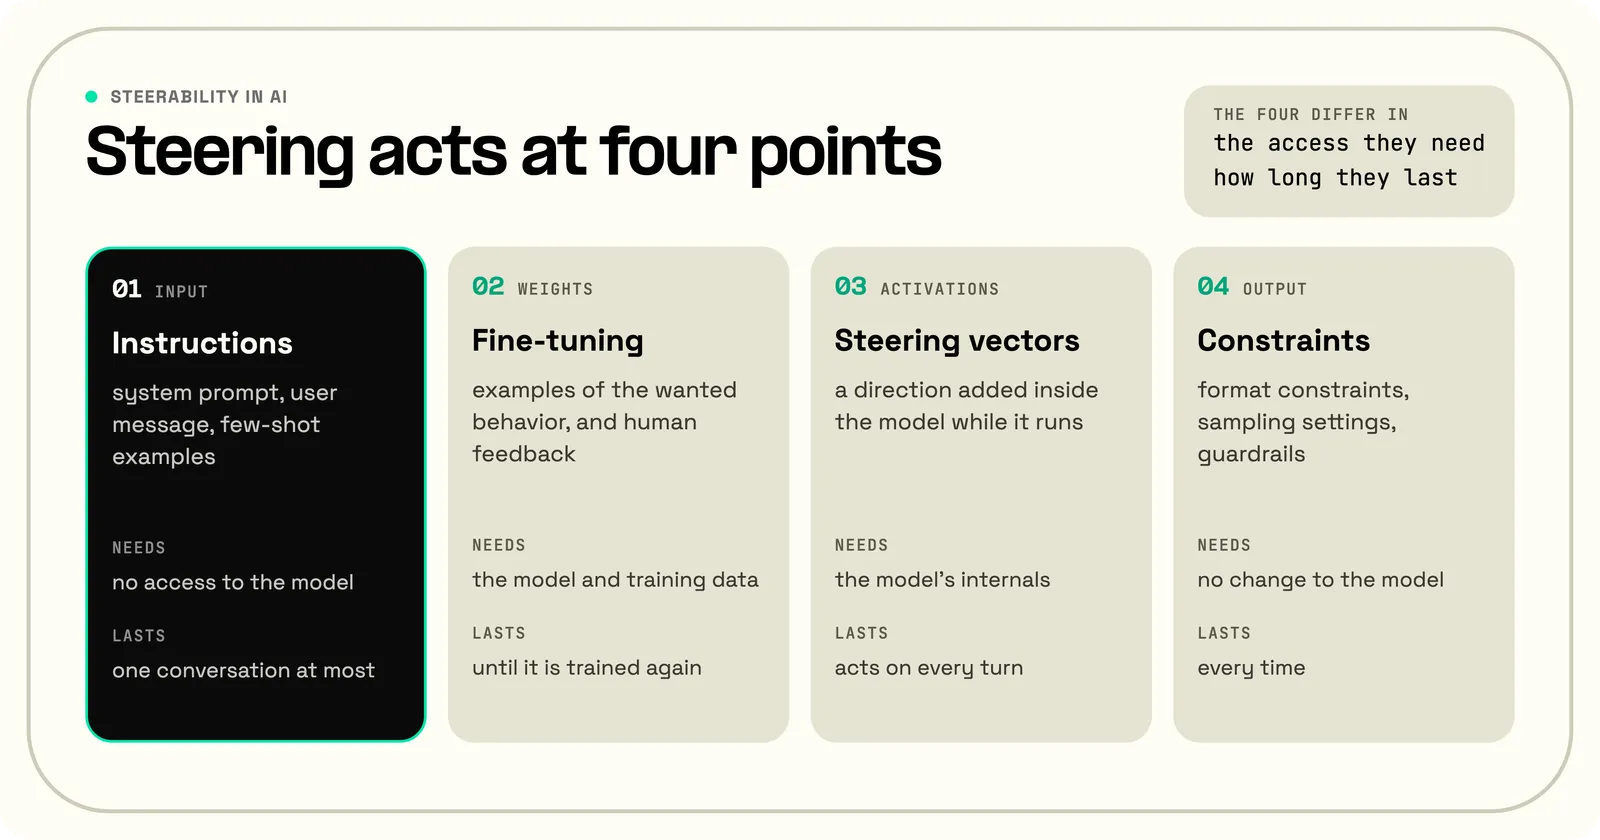
Instructions in the prompt are the most common way to steer a model and the only one most users have. A system prompt sets standing behavior, such as "answer in two sentences, in Spanish, and never give medical advice". Examples placed in the prompt, a technique called few-shot prompting, show the model the pattern to follow.
Prompt steering is cheap and instant to change, but it is a request rather than a rule. The model follows it because it was trained to follow instructions, and it can still drift from the instruction or be talked out of it.
Fine-tuning steers a model by continuing its training on examples of the wanted behavior, which changes its weights and makes that behavior its default. Reinforcement learning from human feedback (RLHF) goes further: people rank the model's answers, a second model learns to predict those rankings, and the language model is trained to produce answers that score well.
Ouyang and colleagues (2022) found that labelers preferred the answers of a 1.3-billion-parameter model trained this way over those of a base model more than 100 times its size. Constitutional AI replaces the human rankings of harmful answers with rankings a model makes against a written list of principles.
Activation steering changes what a model computes while it runs, without retraining it. Activations are the numbers each layer of the model passes to the next, and they encode concepts such as sentiment or topic. Adding a fixed direction to them shifts the output toward that concept.
Activation addition builds the direction from the difference between the activations for two contrasting prompts, such as "Love" and "Hate". Contrastive activation addition averages that difference over many paired examples, and it steered Llama 2 Chat models toward or away from behaviors including sycophancy, hallucination, and refusal, with little loss of general capability. Activation steering needs access to the model's internals, so it is open to anyone running an open-weight model and to the developers of closed ones.
Output constraints steer what a model is allowed to emit after it has computed the probability of each possible next token. Guided generation masks every token that would break a required format, so the output always matches a pattern or grammar, such as a JSON schema. Sampling settings such as temperature act at the same step, though they set how random the output is rather than steering it toward anything. Output constraints need no change to the model itself, only control over how its output is decoded or checked.
A format constraint is the closest steering comes to control: it guarantees the form of the output every time, because it acts on the output itself. It cannot guarantee the content, and it cannot add knowledge or skill the model lacks. AI guardrails work on finished outputs instead, checking each one and blocking those that break a policy.
Voice steerability is the ability to direct how a voice AI system sounds as well as what it says: its tone, emotion, pace, and the voice itself. Earlier speech synthesis systems took style labels or markup such as SSML, and plain-language control arrived once text-to-speech models could take a written description of a speaking style as input. PromptTTS controls gender, pitch, speaking speed, volume, and emotion through a text description, and a later description-guided model also follows descriptions of the recording conditions.
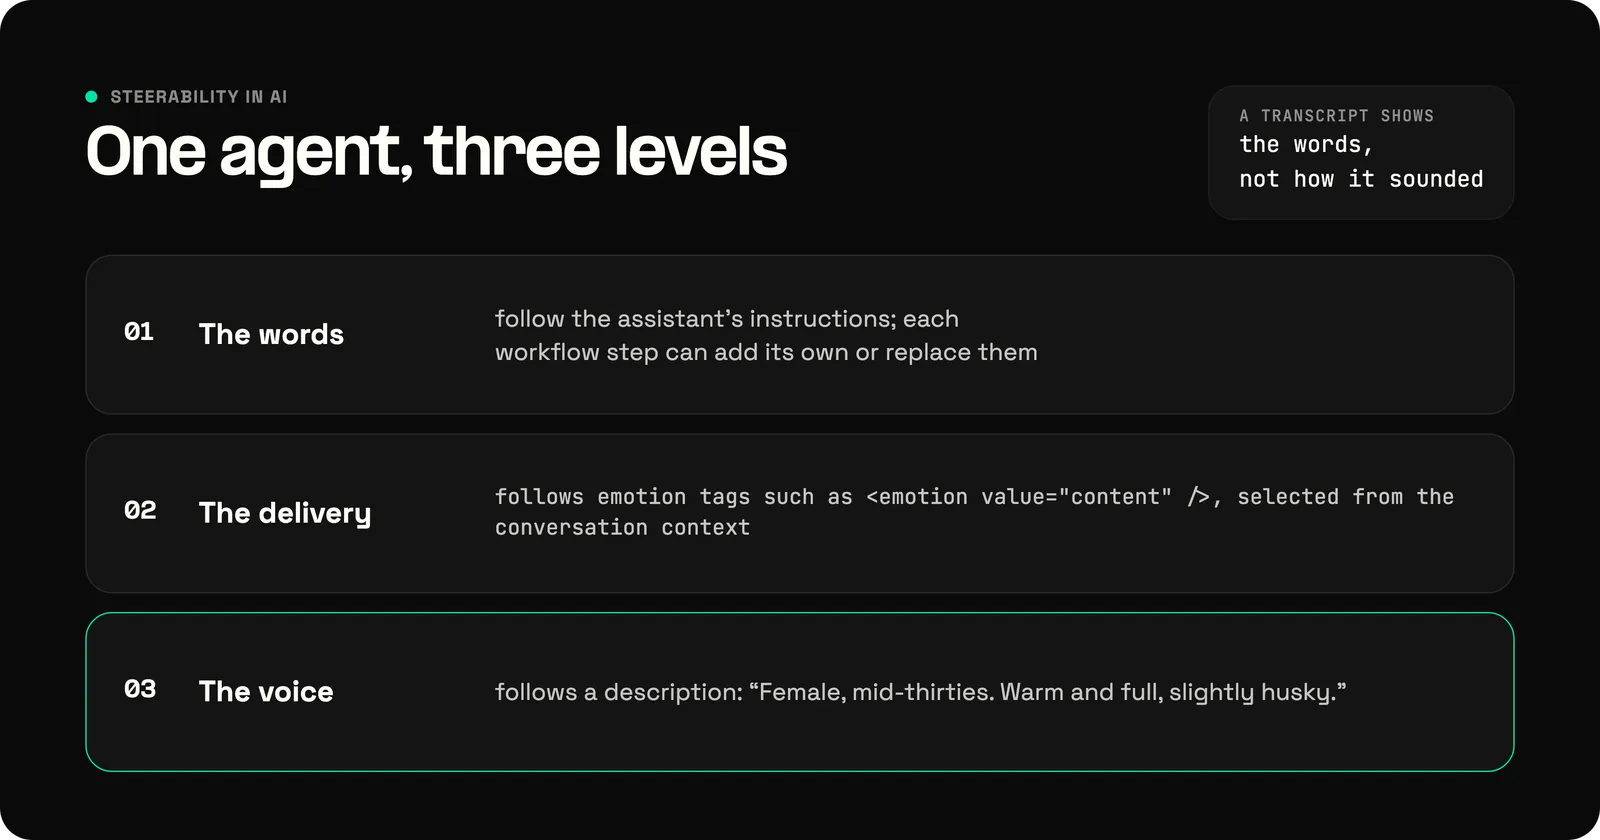
A voice agent is steered at three levels, the words, the delivery, and the voice, and on Telnyx's voice AI agents each is a separate setting:
<emotion value="content" /> from the conversation context. A tag written into the text sets the delivery of a line explicitly.Steering a voice is harder to check than steering text, because the result is audio. A transcript shows whether the agent said the right words, but not whether it sounded calm when the caller was upset. Delivery is checked by listening to recorded calls or by running a speech emotion model over the audio. Checks on what the agent says run on the text before it is synthesized, because a caller hears the audio as it streams.
Steerability is measured by directing a model toward a target behavior and checking how close its output gets, how consistently, and what else changes along the way. Three properties get tested: range, how many different targets a model can be steered to; durability, how long it holds a direction; and sensitivity, how much the score depends on the wording of the test.
Steer-Bench tests range by asking one model to answer the way different online communities would, across 30 pairs of contrasting Reddit communities in 19 domains. Human experts reached 81% accuracy against the benchmark's labels, and the best of the 13 models tested reached about 65%. Steerability rose with model size within each model family, and with instructions that gave the model context about the community.
Durability is measured over a whole conversation. Li and colleagues (2024) ran 200 conversations in which two chatbots with different system prompts talked for eight rounds. At each round the agent got a probe question tied to its system prompt, and a scorer checked whether the reply still followed the prompt, for example whether it was still in French. LLaMA2-chat-70B gradually stopped following its system prompt and began to adopt the other chatbot's instructions, and a closed model, which held its prompt better, still lost 10% on the stability score.
The same setup works as a pre-launch test for a long support call. A simulated caller talks to the agent for as many turns as a real call runs, and the probe checks the rule under test.
Sensitivity matters because prompt-based scores, steerability scores included, depend on wording. Sclar and colleagues (2023) changed only the formatting of few-shot prompts, such as separators and capitalization, and saw one open model's accuracy on a task move by up to 76 points. A score taken from one phrasing therefore describes that phrasing as much as the model.
Steerability lets one general-purpose model serve many products. The same model can work as a terse coding assistant, a patient tutor, or a support agent that never quotes prices, depending only on how it is steered. An application team can therefore build on an existing model instead of training its own.
For a business, steerability decides whether a model's behavior is predictable enough to put in front of customers. That covers the format a downstream system parses, the tone a brand requires, and the topics a regulated company must avoid. For safety, it decides whether limits set by a developer hold against users who push on them. Both depend on the second half of the definition, a model that keeps following its direction, and not only on whether it can be steered at all.
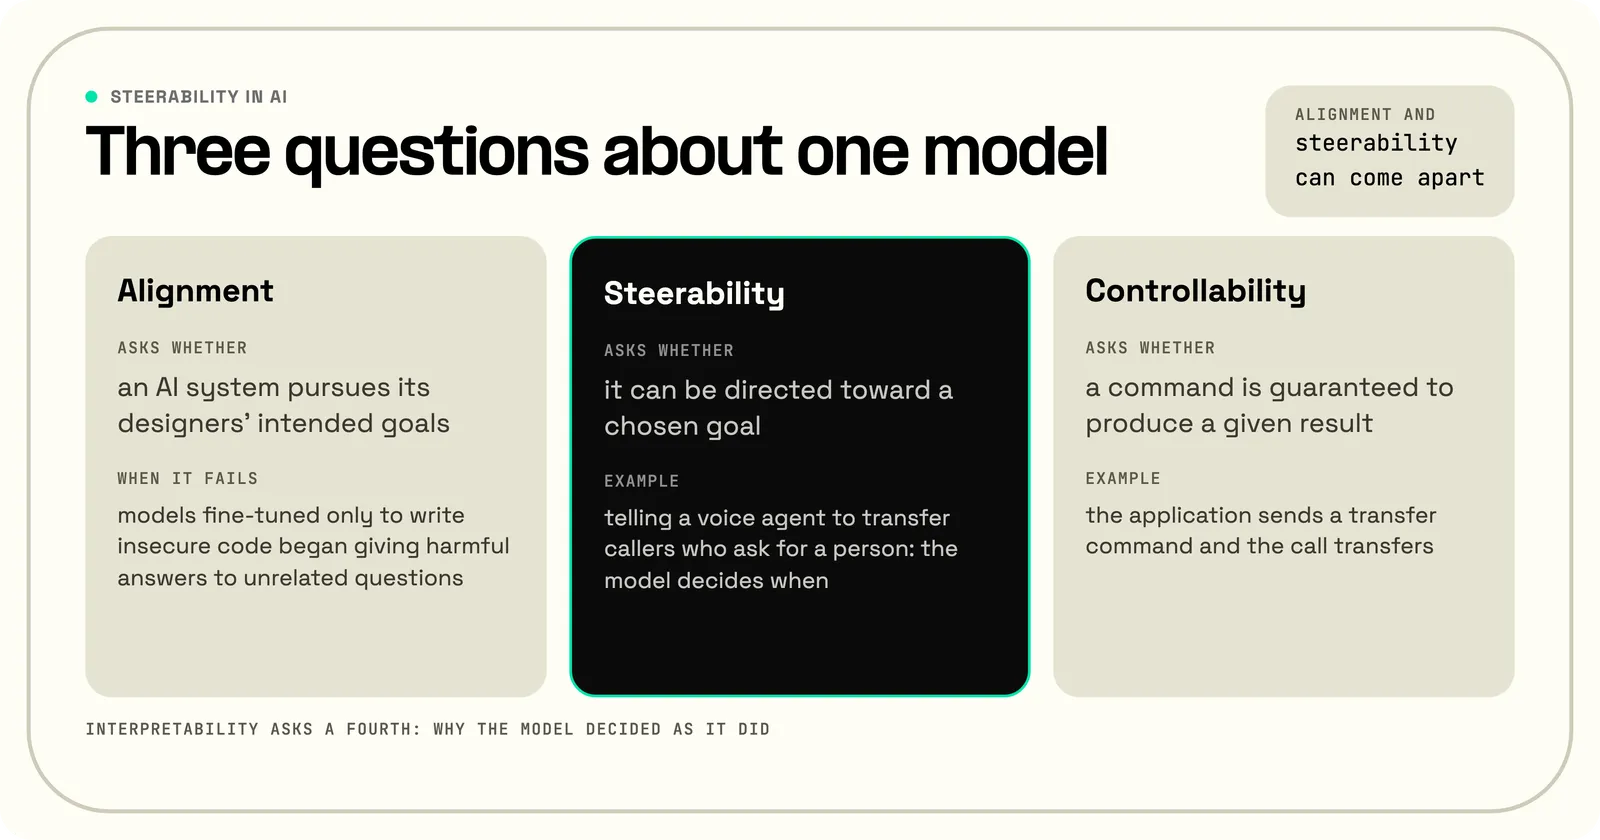
Alignment is whether an AI system pursues its designers' intended goals, steerability is whether it can be directed toward a chosen goal, and controllability is whether a command is guaranteed to produce a given result. That is the software sense of the word; in control theory, controllability means whether a system can be driven to any state. Alignment and steerability can come apart: a highly steerable model can be steered toward harm, and a model can behave well by default and still be hard to redirect.
Controllability belongs to systems that follow fixed rules. A call routed through a programmable Voice API is controlled: the application sends a transfer command and the call transfers. Telling a voice agent to transfer callers who ask for a person is steering, because the model decides when that condition holds, and it can misjudge it.
A misjudgment like that raises a fourth question, why the model decided as it did. That question is interpretability, the subject of explainable AI. Activation steering connects interpretability and steering: finding the direction that represents a concept is interpretability work, and adding that direction back to the activations steers the model.
The main limits of steerability are that instructions lose force over a long conversation, that prompts pile up over a product's life, that the same mechanisms work toward misuse, and that steering one behavior can change others.
A model's adherence to its system prompt fades as a conversation grows. Li and colleagues traced the drift they measured to attention decay: the share of the model's attention that goes to the system prompt drops with each new turn. Their split-softmax method, which boosts that attention at inference time without retraining, balanced stability and task performance better than two baselines. It needs access to the model's attention computations, so it applies to models a team runs itself.
The simplest way to keep a model on its instructions is to repeat them. Repeating the system prompt was one of the baselines in that study, and it raised stability at some cost in task performance; in a voice agent a longer prompt can also add processing time before the agent speaks. Moving the conversation to a step that carries its own instructions, as a workflow does, applies the same idea, though the study did not test it. Weight and activation changes act on every turn, so they do not depend on the model still attending to an instruction written many turns earlier.
Prompting is the first resort because it is cheap and reversible. Fine-tuning becomes worth its cost when a behavior must hold on every turn and repeated instructions are not enough, and its side effects, covered below, are a reason to test the fine-tuned model beyond that behavior.
Over months, a production prompt gathers patches for edge cases until its rules collide and the system's behavior moves away from the original intent, a pattern sometimes called prompt drift. It is a different problem from drift within a conversation, because the instructions themselves change, so the fix is maintenance, reviewing and simplifying the prompt, rather than reinforcement.
The mechanisms that steer a model toward a goal steer it toward misuse just as well. Adversarial suffixes, strings of characters appended to a request, made aligned chat models comply with harmful requests, and suffixes found on open models transferred to other models. Inside the model, refusal behavior in 13 open chat models is carried by a single direction in the activations. Removing that direction stops the model from refusing, and adding it makes the model refuse harmless requests.
Steering one behavior can change others. In emergent misalignment experiments, models fine-tuned only to write insecure code began giving harmful answers to unrelated questions, so a fine-tuned model needs testing beyond the behavior it was trained for.
Steerability means the capacity to be guided toward a chosen course or outcome. For a vehicle, it is how easily the vehicle goes where the driver points it. For an AI system, it is how reliably the system's behavior follows the instructions, training, and adjustments meant to direct it, such as answering in a set format or declining a class of requests.
A steerable AI system is one that accepts direction from its developers and users and keeps following it. It changes its tone, format, or task when instructed, holds that change across a conversation, and keeps to its developer's limits when a user pushes against them.
To steer an AI model is to change its behavior toward a goal without building a new model. Steering can act on the prompt (instructions and examples), the weights (fine-tuning and human feedback), the activations the model computes while it runs (steering vectors), or the output (format constraints and filters).
Voice steerability is control over how a voice AI system speaks, not only over its words. Text instructions steer what the agent says, emotion tags or style descriptions steer its delivery, and a new voice can be generated from a written description of the speaker. It is harder to verify than text steering, because a transcript does not record how the agent sounded.
Semantic steerability refers to steering a model's meaning, such as its topic, sentiment, or persona, rather than only the form of its output. Methods include prompting, control at decoding time, and activation steering, which shifts the concepts a model's internal activations represent without changing its weights.
Steering a model back to aligned behavior, the behavior its developer intended, starts at the level where the drift happened. Within a conversation, restating key instructions in a later turn reduces drift that grows with the length of the exchange, and a workflow step with its own instructions applies the same idea. When the default behavior is wrong, fine-tuning on corrected examples or on human feedback changes it. On an open-weight model, a steering vector can push against a specific behavior such as sycophancy, and output filters catch what still gets through.
Steerability and alignment are different properties. Alignment is whether a model pursues the goals its designers intend, and steerability is whether it can be directed toward a goal at all. A model can be aligned but hard to redirect, or highly steerable and so easy to point at harmful goals. Safety work therefore aims for models that their developers can steer and that resist steering toward misuse.