Inference
The best open source LLMs in 2026 for coding, agents, and voice
Last updated: September 28, 2026. Open model versions change monthly, so every pick below carries a release date and states whether its benchmark score is vendor-reported or independently measured.
By Eli Mogul
Takeaways
- As of September 2026, the best open source LLMs are Kimi K3 and DeepSeek-V4.1-Flash, which sit in a statistical tie on Vals AI's independent index. Kimi K3 has the higher ceiling on agentic coding; DeepSeek-V4.1-Flash costs a fraction as much per task. Gemma 4 26B A4B is the pick to run locally.
- Nearly every model on this list is open weight, not open source. The license (Apache 2.0, MIT, or a custom license with revenue or attribution clauses) matters more than the label.
- For real-time voice agents, time to first token matters more than two benchmark points. Kimi K2.6 is the default voice model on Telnyx Inference for that reason.
- The newest releases are Qwen3.8-27B (August 14, 2026), GLM-5.3-Flash (August 26), GLM-5.3 weights (August 28), and DeepSeek-V4.1-Flash (September 10).
Three popular rankings of open source LLMs name three different versions of Kimi and GLM, and none of them says which scores were measured independently. This guide fixes that. Each pick below lists its parameters, license, and release date, and it labels every benchmark by who ran it. It also covers the workload other rankings skip: agents that talk to people on a live call.
The best open source LLMs in 2026, ranked
The best open source LLM for most teams in September 2026 is Kimi K3 for maximum capability, or DeepSeek-V4.1-Flash for the best capability per dollar. On the Vals Index, an independent evaluation suite, DeepSeek-V4.1-Flash scored 57.86% and Kimi K3 scored 57.81%, inside the margin of error of each other. DeepSeek-V4.1-Flash did it at $0.30 per test against $6.47 for Kimi K3.
The right pick still depends on the workload. The table below maps each model to the job it does best.
Best open source LLMs in 2026 by use case
| Model | Best for | Main trade-off |
|---|---|---|
| Kimi K3 | Highest-ceiling agentic coding | 2.8T parameters; too large to self-host for most teams |
| DeepSeek-V4.1-Flash | Best value for coding agents | Headline scores are vendor-reported; independent runs are lower |
| GLM-5.3 and GLM-5.3-Flash | Long-horizon agents | Flagship license requires a review for the largest hosts |
| Qwen3.8-27B | Dense model on one GPU | Smaller knowledge base than frontier MoE models |
| Gemma 4 26B A4B | Running locally | Weaker on agentic coding than larger picks |
| MiniMax M3 | Low-cost multimodal agents | License requires attribution and approval at scale |
| Kimi K2.6 | Real-time voice agents | Superseded by Kimi K3 on raw capability |
How we ranked these models
Six factors set the order: task performance on the benchmark closest to the workload, developer fit (published weights, vLLM and Ollama support, OpenAI-compatible APIs), hardware reality, license freedom, cost per task, and response speed.
Every score in this guide carries one of two labels. Vendor-reported means the model's own lab ran it, usually with its own test setup. Independent means a third party such as Vals AI ran it. The gap between the two can be large: DeepSeek reports 90.6 on Terminal-Bench 2.1, while Vals measured 74.53% across three full trials.
Which benchmarks still separate models? SWE-bench Verified is close to saturated. The coding benchmarks that still separate frontier open models are SWE-bench Pro, FrontierSWE, DeepSWE v1.1, and Terminal-Bench 2.1 and 3.0. Rank by the benchmark closest to the actual workload.
1. Kimi K3: best overall for coding and agentic work
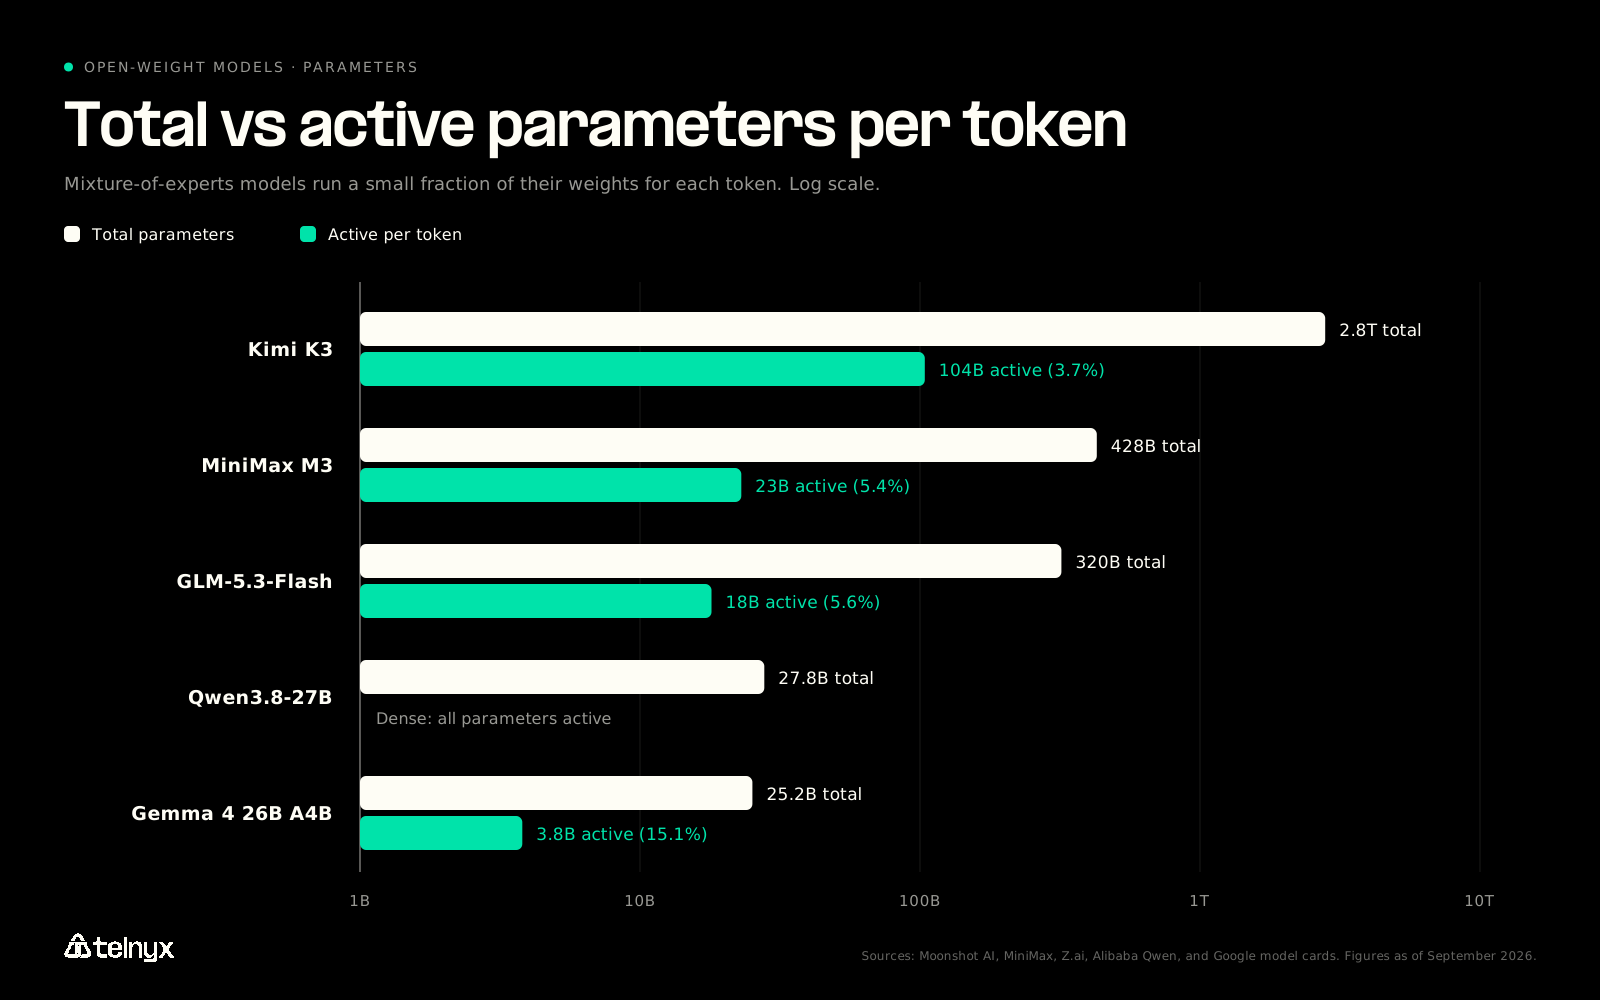
Moonshot AI's Kimi K3 is the largest open-weight model available. It is a 2.8 trillion parameter mixture-of-experts (MoE) model that routes each token to 16 of its 896 experts, activating about 104 billion parameters. It has a 1M-token context window and native text, image, and video input. Weights shipped on July 27, 2026.
Moonshot reports 88.3 on Terminal-Bench 2.1 and 81.2 on FrontierSWE (vendor-reported). Independently, Vals AI puts Kimi K3 first among open-weight models on Vibe Code Bench, 0.2 points ahead of DeepSeek-V4.1-Flash.
- License: custom Kimi K3 License. Commercial products above 100M monthly active users or $20M in monthly revenue must display "Kimi K3."
- Limit: the full weights take about 1.56 TB, and Vals measured it at about 1.5 hours per Vibe Code Bench task against 15 minutes for DeepSeek-V4.1-Flash.
- Hosted price: Kimi K3 on Telnyx Inference runs $2.70 per 1M input tokens and $13.50 per 1M output tokens.
Choose Kimi K3 if the workload is long, autonomous coding or research where the best possible answer justifies slower, costlier runs.
2. DeepSeek-V4.1-Flash: best value for coding agents
DeepSeek released V4.1 Flash on September 10, 2026 under the MIT license. It has a 552B-parameter backbone, a 1M-token context window, up to 384K output tokens, and native image input.
DeepSeek reports 90.6 on Terminal-Bench 2.1, 74.2 on DeepSWE v1.1, and a 3471 Codeforces rating (vendor-reported). Vals measured 74.53% on Terminal-Bench 2.1 (independent), second among open-weight models. On Vibe Code Bench, Vals found it about 40 times cheaper per task than Kimi K3 and about five times faster.
- License: MIT, with no usage restrictions.
- Limit: treat its vendor-reported lead over Kimi K3 as provisional; the independent results show a tie, not a win.
- Hosted price: $0.30 per 1M input tokens and $1.20 per 1M output tokens on Telnyx Inference.
Choose DeepSeek-V4.1-Flash if the workload runs many agent loops a day and cost per task decides the budget.
3. GLM-5.3 and GLM-5.3-Flash: best for long-horizon agents
Z.ai launched GLM-5.3 by API on August 14, 2026, then released the weights on August 28 after a two-week safety hold. The flagship keeps the same roughly 753B-parameter base as GLM-5.2 with a 1M-token context. According to the model card, it lifted DeepSWE v1.1 from 46.2 to 66.9 (vendor-reported). Serving speed varies by provider: in Telnyx's own GLM-5.3 latency benchmarks against three other hosts, Telnyx had the lowest median end-to-end latency in five of six workloads.
GLM-5.3-Flash, released August 26 under the MIT license, is the more practical model for most teams. It is a 320B MoE with 18B active parameters and a hybrid linear-plus-sparse attention design that Z.ai says cuts KV cache 4.44 times compared with the flagship.
- License: GLM-5.3 uses a custom license; companies that host it with more than $10B in revenue over any 12 months must pass a Z.ai security review. GLM-5.3-Flash is plain MIT.
- Limit: the flagship realistically needs an eight-GPU node to self-host.
- Hosted price: GLM-5.3 runs $1.25 input and $4.00 output per 1M tokens on Telnyx Inference; GLM-5.3-Flash runs $0.135 and $0.45.
Choose GLM-5.3-Flash if an agent needs a 1M-token context at a low serving cost under a clean license.
4. Qwen3.8-27B: best dense model on a single GPU
Alibaba released Qwen3.8-27B on August 14, 2026 under Apache 2.0. It is a dense model with about 27.8B parameters, a 262K-token native context, and image and video input. It replaces Qwen3.6-27B, which some rankings still list as current.
Qwen reports 61.7% on SWE-bench Pro (vendor-reported). At 4-bit precision, the weights take roughly 14 GB, leaving room for the KV cache on a 24 GB consumer GPU.
- License: Apache 2.0, with no commercial conditions.
- Limit: a dense 27B model holds less world knowledge than 300B-plus MoE models.
- Hosted price: $0.40 input and $3.00 output per 1M tokens on Telnyx Inference.
Choose Qwen3.8-27B if the team wants a capable coding and document model it can run on one GPU with no license questions.
5. Gemma 4 26B A4B: best to run locally
Google's Gemma 4 26B A4B is an MoE model with 25.2B total and 3.8B active parameters, a 256K-token context window, and text and image input. Gemma 4 moved to Apache 2.0, dropping the custom terms that covered Gemma 3. It supports over 140 languages.
Because only 3.8B parameters run per token, it generates text far faster than its total size suggests. It fits on laptops with 32 GB of unified memory and on a single 24 GB GPU once quantized.
- License: Apache 2.0.
- Limit: it trails the larger picks on agentic coding benchmarks, so it suits privacy-sensitive and multilingual work more than autonomous code agents.
- Hosted price: not currently on Telnyx Inference.
Choose Gemma 4 26B A4B if data must stay on a local machine or an edge device.
6. MiniMax M3: strong agent scores, read the license
MiniMax M3, released June 1, 2026, is a natively multimodal MoE with about 428B total and 23B active parameters. It accepts text, images, and video with a 1M-token context and targets agentic coding and tool use.
- License: MiniMax Community License. Commercial use requires attribution, and larger deployments require prior authorization from MiniMax.
- Limit: the license conditions need legal review before a commercial launch.
- Hosted price: $0.27 input and $1.10 output per 1M tokens on Telnyx Inference.
Choose MiniMax M3 if the goal is multimodal agent work at the lowest cost per token, and the license terms fit the product.
7. Kimi K2.6: best for real-time voice agents
Moonshot released Kimi K2.6 in April 2026. It is a 1T-parameter MoE with 32B active parameters and a 256K-token context, under a Modified MIT license. Kimi K3 beats it on capability, but K2.6 keeps a lower time to first token, which matters more on a live call.
On Telnyx Inference, Kimi K2.6 is the default model verified for voice AI assistants. Reasoning is always disabled on voice calls, so the model answers directly instead of thinking first.
"I heavily encourage people to try one of the open source models first, the recommended Kimi K2.5, 2.6, because it's just… it's good, and it's super fast, you're not going to get anything that fast with OpenAI or Anthropic." James Whedbee, Telnyx |
- License: Modified MIT, which adds an attribution clause at large scale.
- Limit: a 256K context is shorter than the 1M windows on newer models.
- Hosted price: $0.665 input and $4.00 output per 1M tokens on the default tier.
Choose Kimi K2.6 if a caller is waiting on the line and every millisecond of silence counts.
Readers who want Kimi K3 or GLM-5.3 without building a multi-GPU cluster can call them through the OpenAI-compatible Telnyx Inference API by changing a base URL and model name.
Run Kimi K3 and 7 other open models on Telnyx InferenceOpenAI-compatible API, GPUs colocated with the telephony network, in-region serving. See pricing and available models
Start buildingWhat an open source LLM is, and why most are open weight
An open source LLM is a large language model released under terms that let anyone use, study, modify, and share it. The Open Source AI Definition from the Open Source Initiative (OSI) sets a high bar: it requires the model parameters, the complete code used to train and run the model, and detailed information about the training data.
Almost no leading model meets that bar. Projects such as OLMo and Pythia publish the full recipe, but the models at the top of the benchmarks, including Kimi, DeepSeek, GLM, Qwen, Gemma, and Llama, publish their weights and little else. That makes them open weight. Our guide to open weight models covers the distinction in more depth.
Open source vs open weight vs closed
For a builder, the license matters more than the label. Open models fall into three license groups:
- Permissive: Apache 2.0 (Qwen3.8, Gemma 4) and MIT (DeepSeek-V4.1-Flash, GLM-5.3-Flash) allow commercial use with no usage conditions.
- Permissive with clauses: the Kimi K3 License and Modified MIT add attribution requirements above a revenue or user threshold.
- Conditional: the GLM-5.3 License, the MiniMax Community License, and the Llama 4 Community License add security reviews, approval steps, or user caps.
Closed models such as GPT and Claude publish nothing and are reachable only through the vendor's API.
Why open source language models are worth the effort
- Privacy and data residency: the model runs on infrastructure the team controls or chooses.
- Cost control at scale: no per-token dependency on one vendor's pricing decisions.
- Customization: weights can be fine-tuned on domain data.
- No vendor lock-in: a model can be swapped without rewriting the application.
The latest open source LLMs: releases since July 2026
The top of the open model rankings changed several times in two months. Each entry below is dated so the list stays useful as a reference.
- July 27, 2026: Kimi K3 weights. Moonshot published 2.8T-parameter weights under the Kimi K3 License, eleven days after API launch.
- August 14, 2026: Qwen3.8-27B. A dense 27.8B multimodal model under Apache 2.0, replacing Qwen3.6-27B.
- August 26, 2026: GLM-5.3-Flash. A 320B MoE with 18B active parameters under MIT.
- August 28, 2026: GLM-5.3 weights. Released after a two-week safety hold, under a new custom license that replaces GLM-5.2's MIT terms.
- September 10, 2026: DeepSeek-V4.1-Flash. MIT-licensed, 1M context, with vendor-reported scores above Kimi K3 that independent runs show as a tie.
Provisional ordering: vendor-reported scores put DeepSeek-V4.1-Flash ahead of Kimi K3 on Terminal-Bench 2.1. Independent results do not confirm that lead. Treat the order of the top two as open until more third-party runs land.
Previous generation: still worth running?
Teams already in production need a migrate-or-stay answer, not a new ranking:
- Kimi K2.6 → Kimi K3: stay on K2.6 for voice and latency-bound work; migrate for long autonomous coding.
- Qwen3.6-27B → Qwen3.8-27B: migrate; same size class, same Apache 2.0 license, newer training.
- GLM-5.2 → GLM-5.3-Flash: migrate if the MIT license matters; GLM-5.3 flagship changed to a custom license.
- DeepSeek V4 Flash → DeepSeek-V4.1-Flash: migrate; Vals measured a 4.3-point gain on its index and lower cost per test on most agentic benchmarks.
- Llama 4 Scout: stay if the workload needs its 10M-token context window, which newer open models do not match.
How to choose the best open source LLM for a workload
The best open source LLM for a given product comes down to three checks: the license, the hardware, and the cost of the path to production. A model that scores two points higher but carries a confusing commercial license may be the worse choice.
License conditions to check before building
Before shipping, confirm each of these against the model's license file:
- Revenue thresholds: GLM-5.3 requires a Z.ai security review above $10B in 12-month revenue; Kimi K3 requires a "Kimi K3" display above $20M in monthly revenue.
- User caps: the Llama 4 Community License requires a separate license above 700M monthly active users.
- Attribution and approval: MiniMax M3 requires attribution for commercial use and authorization for large deployments.
- Distillation rights: MIT-licensed models such as DeepSeek-V4.1-Flash allow training smaller models on their outputs, which is why many small reasoning models descend from them.
Hardware tiers: what fits on each machine
Match the model to the memory available:
- 16 GB or less: small Gemma 4 or Qwen models, quantized.
- 24 GB of VRAM: Qwen3.8-27B or Gemma 4 26B A4B at 4-bit.
- 32 to 64 GB of unified memory: Gemma 4 26B A4B at higher precision, with room for longer contexts.
- Multi-GPU cluster: GLM-5.3-Flash, GLM-5.3, or DeepSeek-V4.1-Flash, served with vLLM or SGLang.
- No GPU: a hosted OpenAI-compatible endpoint for Kimi K3 and other frontier models.
A 1M-token context window multiplies KV-cache memory per request, so pick the smallest window that fits the task.
Cost: self-host, vendor API, or hosted endpoint
Self-hosting trades per-token fees for GPU capital and operations work. A vendor's own API is the fastest start but ties the product to one provider. A hosted OpenAI-compatible endpoint sits between the two: open weights, no GPUs to manage, and the option to switch models by changing one parameter.
Cached input changes the math. On Telnyx Inference pricing, cached input for Kimi K3 costs $0.27 per 1M tokens, one-tenth of the uncached rate. Log cache hits and misses separately to see the real bill.
"My feed is full of people proudly showing off their '10 Billion Token' trophies. What I see: 'I just paid OpenAI a premium for something I could've run with open-source models at 90% less cost.'" David Casem, CEO at Telnyx |
For most teams, a hybrid works best: small models locally for privacy-sensitive work, and frontier open models through a hosted endpoint.
Which open source LLM works for real-time voice agents
For a real-time voice agent, the best open source LLM is the one with the lowest time to first token (TTFT) that still handles function calls reliably. Today that is Kimi K2.6, with fast MoE models such as GLM-5.3-Flash and DeepSeek-V4.1-Flash as options for text-side agent work.
Why time to first token beats two benchmark points
A voice turn runs in order: speech-to-text (STT), then the LLM, then text-to-speech (TTS). The caller hears silence until the LLM's first token reaches TTS. Every millisecond of TTFT is dead air, so a model that answers fast beats one that is marginally more accurate but slower. Our breakdown of inference latency shows where those milliseconds go.
MoE models help because only a fraction of their parameters run per token. Gemma 4 26B A4B activates 3.8B, GLM-5.3-Flash 18B, and Kimi K2.6 32B.
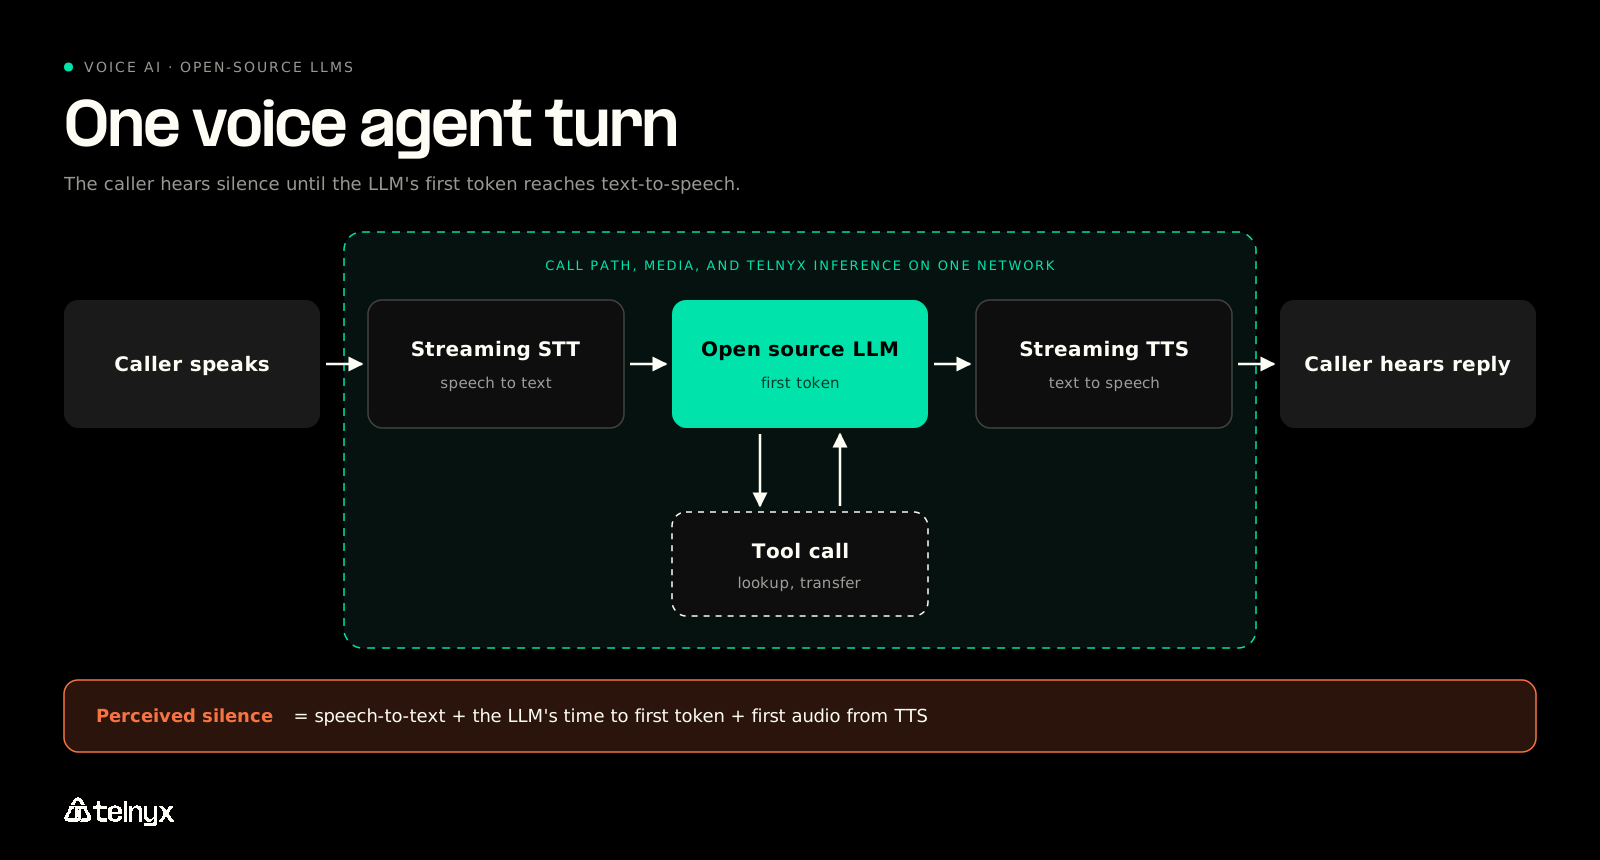
Voice selection checklist: time to first token, streaming tokens per second, reliable function calling for transfers and lookups, structured output, and recovery when the first plan fails. No public benchmark measures these end to end, so test on real calls.
"The question is how much of the production system you want to own and debug yourself. Once you add streaming STT, an LLM, TTS, tool calls, observability, failover, latency tuning, transfers, voicemail handling, and carrier deliverability, you are no longer just wrapping an LLM around a call. You are building a real-time distributed voice system." James Whedbee, VP of Engineering at Telnyx |
Calling an open source LLM from a live phone call
Telnyx Voice AI Agents run STT, TTS, orchestration, and inference on one network, with Kimi K2.6 as the default voice model. Teams with their own model can also bring any OpenAI-compatible LLM to a Telnyx assistant.
To check how fast a model will answer before putting it on a call, the script below streams a short phone-style reply from Kimi K2.6 and times the first token. It needs Python 3.8 or later, pip install openai, and a Telnyx API key exported as TELNYX_API_KEY.
Run it from the region where callers live. Swap the model value to compare candidates on the same prompt.
Open source LLM community support and development ecosystems
After picking a model, a builder depends on the ecosystem around it: where the weights live, which tools serve them, and how the community adapts them.
Where the weights live: Hugging Face and model cards
Hugging Face is the main distribution point for open weights. Each model card is the source of truth for license, parameter count, context length, and the lab's own benchmark scores. Read the license file itself, not a summary of it; some coverage still describes Kimi K3 as Modified MIT when it ships under its own license.
Serving and local tools: Ollama, vLLM, llama.cpp, and hosted endpoints
- Ollama: the easiest way to run a model from the terminal.
- LM Studio: a desktop app for non-technical users.
- llama.cpp: CPU and mixed CPU-GPU inference with GGUF files.
- vLLM and SGLang: production serving with batching and OpenAI-compatible APIs.
- Hosted endpoints: OpenAI-compatible APIs for models too large to self-host.
Because vLLM, SGLang, and hosted endpoints all speak the OpenAI API format, the same client code works everywhere. A team can prototype with Gemma 4 on a workstation and move to Kimi K3 on a hosted endpoint by changing a base URL and a model name.
Community practice fills in the rest: 4-bit quantization for consumer GPUs, LoRA fine-tuning on domain data, distillation from MIT-licensed outputs, and pairing a model with a vector database for retrieval over company documents.
Best open source LLMs FAQ
Run the best open source LLMs on Telnyx Inference
Picking a model is half the work. The other half is serving it fast enough, close enough to users, and at a price that holds at scale. Telnyx Inference hosts Kimi K3, Kimi K2.6, GLM-5.3, GLM-5.3-Flash, DeepSeek-V4.1-Flash, MiniMax M3, and Qwen3.8-27B on GPUs Telnyx owns, colocated with its global telephony network. The API is OpenAI-compatible, inference runs in-region, and the same platform carries the call when the agent needs to talk.
Run the best open source LLMs on Telnyx InferenceOpenAI-compatible API, in-region serving, GPUs colocated with the telephony network.
Start building with Telnyx InferenceShare on Social


