Inference
How machine learning inference works, from forward pass to live call
The inference process in machine learning is the production stage where a trained model takes new inputs and produces predictions.
By Eli Mogul
Takeaways
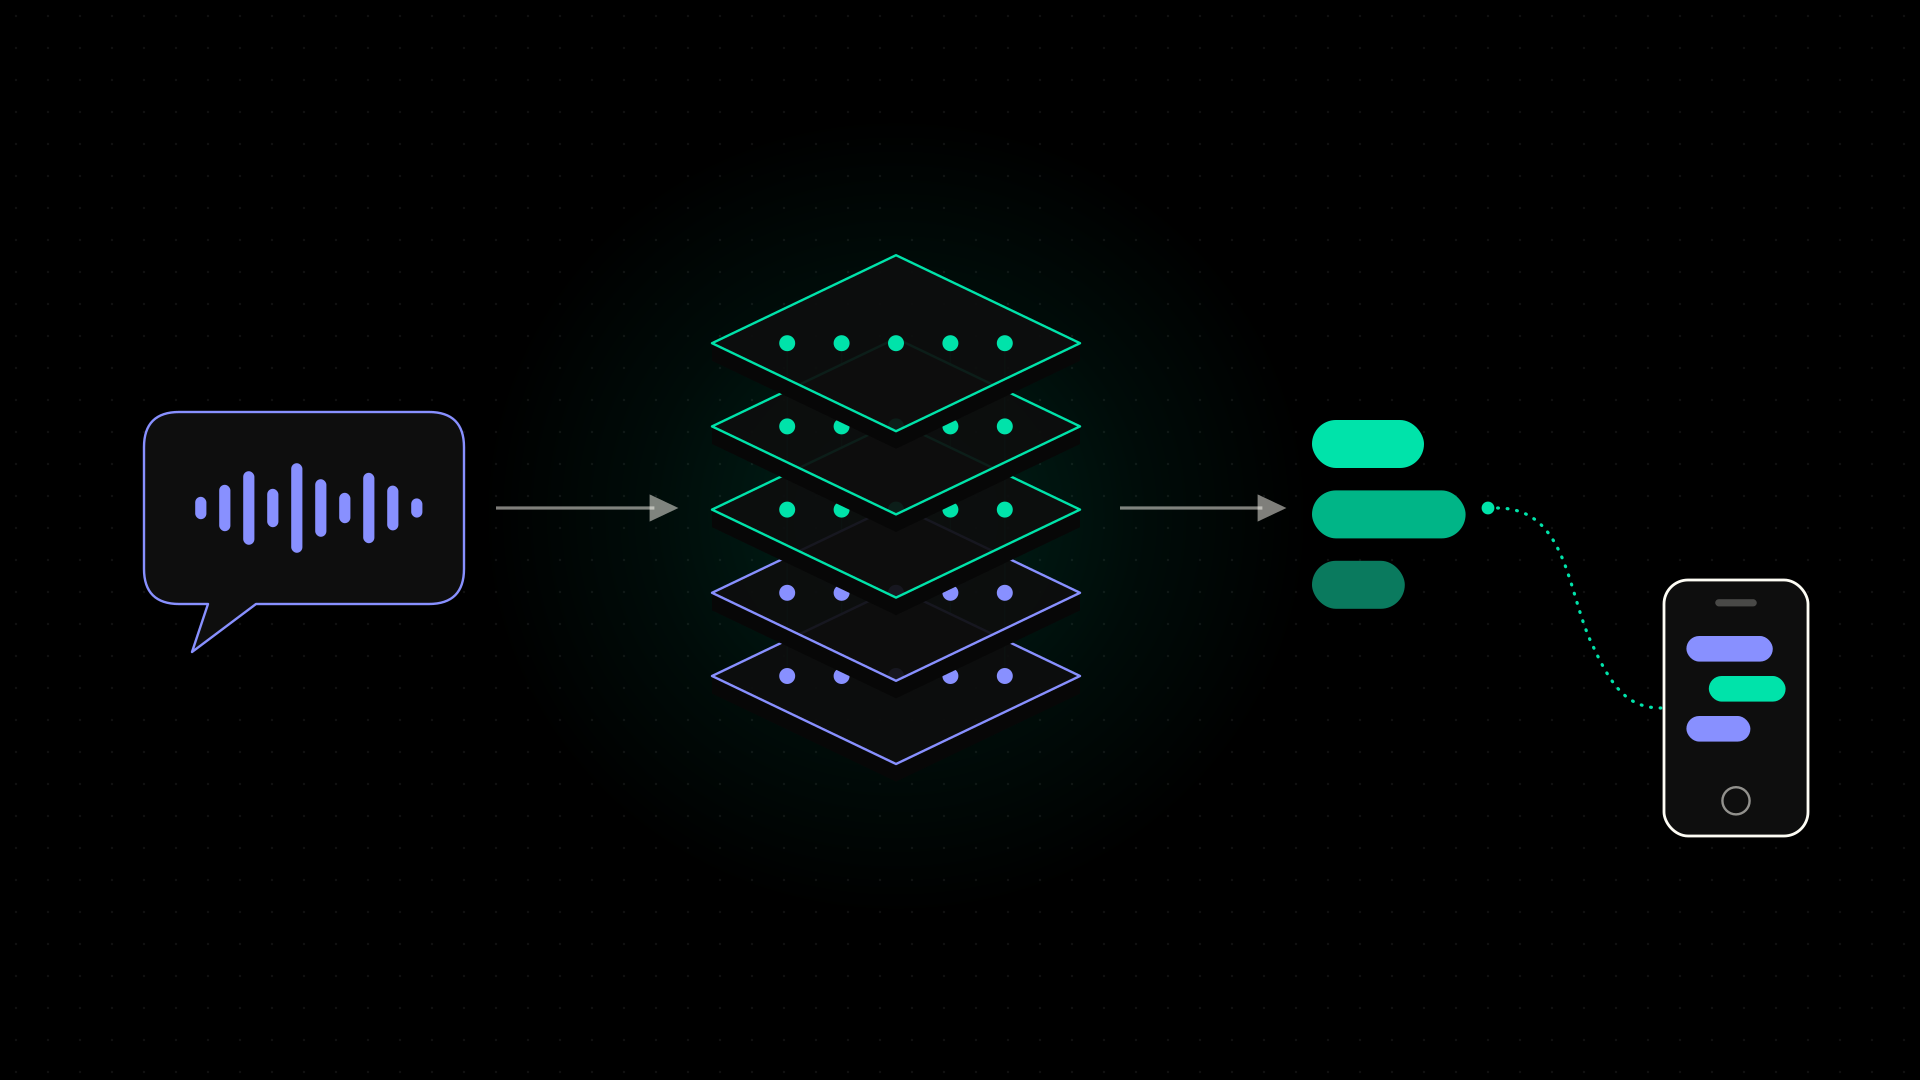
Machine learning inference is the step where a trained model is applied to new input to produce an output. The time it takes is spent in three places: the forward pass, the inference engine, and the network path to the user.
- Training happens once or on a schedule. Inference runs on every request, so it's the cost and latency that grow with your usage.
- An inference engine is the runtime that executes a model without training machinery like gradient tracking and optimizer state.
- In generative AI, inference is autoregressive: the model produces one token per forward pass, so a long reply is many passes in a row.
- A fast benchmark doesn't guarantee a fast product. Measure inference latency at the user, not at the GPU.
What is machine learning inference?
Machine learning inference is the phase where a trained model receives new, unseen input and produces an output, such as a label, a score, a token, or an embedding. Two artifacts make it happen: the trained weights, which hold everything the model learned, and the inference engine, which runs those weights against each new input.
IBM defines AI inference as a trained model's ability to recognize patterns and draw conclusions from information it hasn't seen before. In practice, that plays out in four steps:
- A model is trained once on historical data, and its weights are frozen.
- Inference loads those frozen weights into memory.
- Each new input runs through the weights to produce an output.
- Nothing is learned along the way. The weights stay exactly as they were.
It helps to separate "the model" from "inference." The model is a file: an architecture plus billions (or thousands) of learned numbers. Inference is the act of running that file against real data. You'll also see the process called model inference, ML inferencing, or inference in ML. They all mean the same thing.
Definition: Machine learning inference is the act of running new input through a trained model to get an output. Training is over; the weights do not change; every call is the same computation on different data.
A machine learning inference example
Consider a spam classifier sitting behind an email inbox. Here's what happens when a new message lands:
- An email arrives at the mail server.
- The text is tokenized and converted into numerical model input.
- The model runs a forward pass and returns a probability of 0.97 that the message is spam.
- The application compares that score to its threshold and labels the email spam.
A large language model (LLM) follows the same pattern with a different output. Instead of a probability, each forward pass returns the next token in a sentence. That small difference has big consequences for speed, covered in the generative AI section below.
If you want to run an inference call against an open-source model without standing up an engine yourself, Telnyx Inference exposes one through an OpenAI-compatible API.
What is an inference engine?
An inference engine is the software runtime that loads a model's trained weights and executes the forward pass efficiently on a specific hardware target, like a GPU or CPU. It's the part of the stack that actually does the work every time a request comes in.
Engines exist because training frameworks carry a lot of machinery that inference doesn't need. During training, a framework tracks gradients, stores optimizer state, and builds autograd graphs so it can adjust weights after every batch. None of that is useful once the weights are frozen. PyTorch's torch.inference_mode context manager is a simple example of this idea: it switches off gradient tracking so the model runs forward only.
A dedicated engine goes further. It takes a model exported from a training framework and applies graph optimizations: fusing operators into fewer steps, quantizing weights to smaller number formats, and selecting kernels tuned for the target chip. Then it exposes a call interface your application can hit. ONNX Runtime, NVIDIA TensorRT, vLLM, and llama.cpp are all widely used examples.
Inference engine vs. model vs. framework
These three terms get used interchangeably, but they describe different things:
| Component | What it is | Job at inference time |
|---|---|---|
| Model (e.g., Llama, a fine-tuned BERT) | Learned weights plus architecture | Provides the computation |
| Framework (e.g., PyTorch, TensorFlow) | Training and export toolkit | Exports the model; not used to serve it |
| Inference engine (e.g., ONNX Runtime, TensorRT, vLLM) | Optimized runtime | Loads weights, runs the forward pass, and serves calls |
Inference vs. training vs. prediction
Inference vs. training
The mechanical difference is simple. Training runs a forward pass and a backward pass, then updates the weights based on the error. Inference runs the forward pass only, and the weights stay frozen.
The operational difference follows from that. Training is scheduled and batched: you run it once, or on a regular cadence when you retrain. Inference is on demand and often handles one request at a time, because a user is waiting on the other end. Training is judged on throughput. Inference is judged on latency and cost per call.
The cost difference is where the business impact shows up. Training spend is a one-off or periodic bill, closer to a capital cost. Inference spend recurs with every user interaction, closer to an operating cost that scales with usage. That's why a model that's cheap to train can still be expensive to run at volume.
Hardware follows the same split. Training typically runs on large GPU clusters, while inference runs on a GPU, CPU, or specialized accelerator sized to the request.
Inference vs. prediction
Prediction is the label people use for a classifier's or regressor's output. Inference is the broader process, and it covers every output type a model can produce. Plenty of inference outputs aren't predictions at all:
- An embedding vector that represents a document's meaning for semantic search
- A generated reply from an LLM in a chat or voice conversation
- A ranked list of products or articles from a recommendation model
Put simply, every prediction is an inference, but not every inference is a prediction.
How do inference engines work?
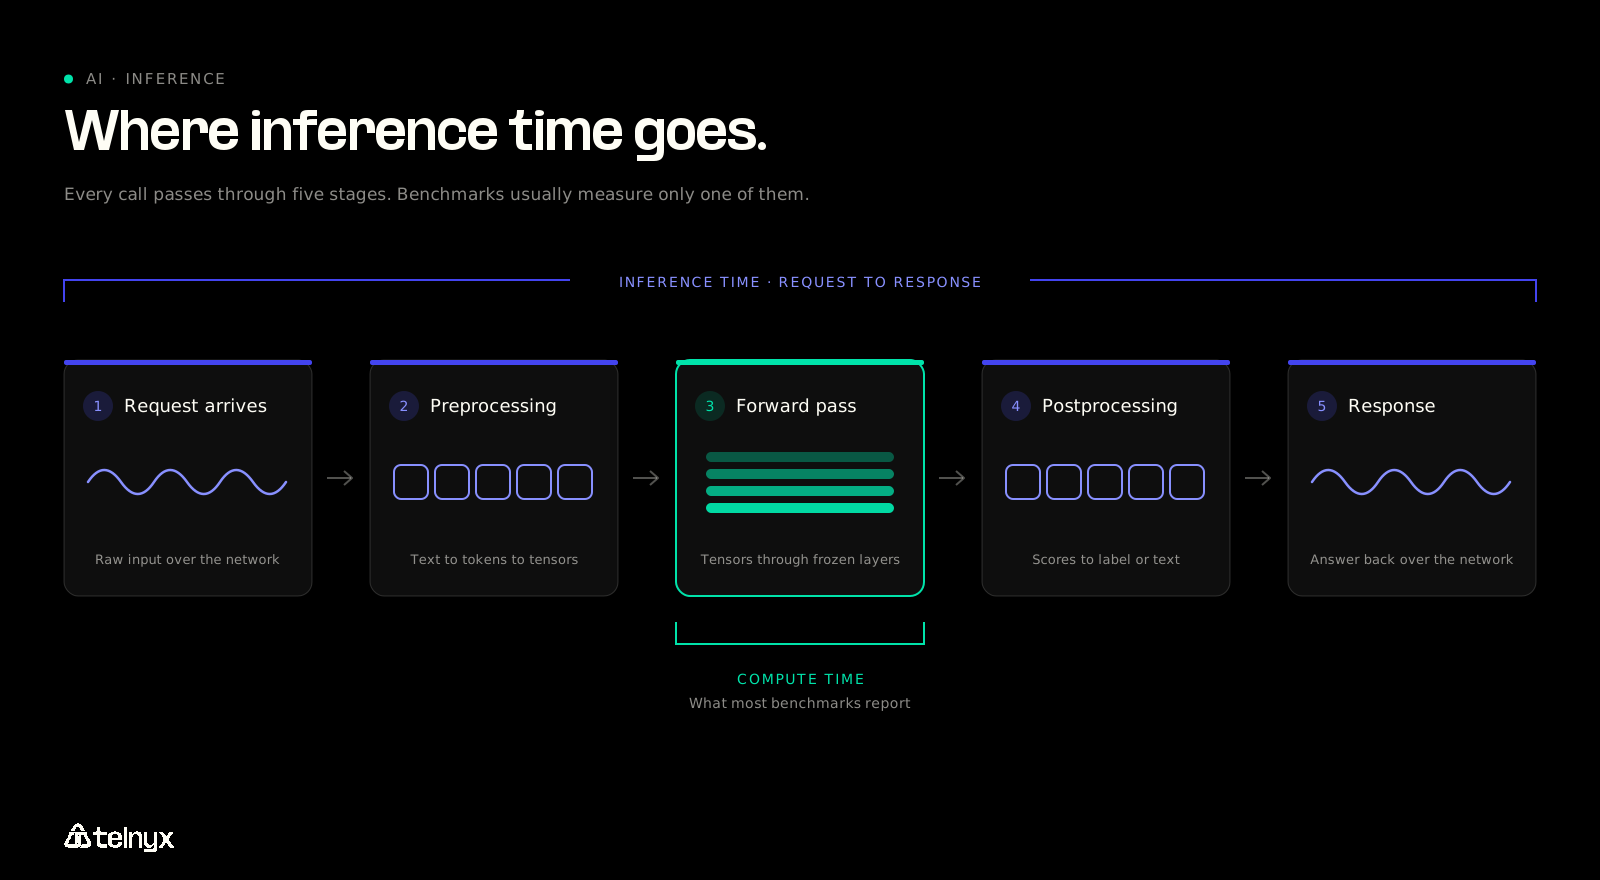
Here's what happens after the user sends input:
- Request arrives. The endpoint receives raw input (text, audio, or an image) over the network.
- Preprocessing. Raw input becomes tensors. For text, that means tokenization. For images, it means resizing and normalization.
- Forward pass. Tensors flow through the network's layers and come out as output tensors.
- Postprocessing. Output tensors become an answer: a softmax turns scores into a label, or a decoder turns a token ID back into text.
- Response returned. The answer travels back over the network to the caller.
What happens during the forward pass
During the forward pass, input tensors are multiplied through each layer's frozen weights in sequence. Activations from one layer become inputs to the next, and no gradients are computed along the way.
In a transformer, the architecture behind most modern LLMs, attention layers compare every token in the input with every other token to work out which ones matter to each other. That mechanism comes from the 2017 paper Attention Is All You Need, and it's why longer inputs cost more compute.
Nearly every optimization an inference engine offers acts on this stage. Fused kernels cut the number of memory trips, quantized weights shrink the data the chip has to read, and batching lets one pass serve several requests at once.
What is inference time?
Inference time is the end-to-end, wall-clock time from the moment a request is sent to the moment the response arrives. It splits into two parts:
- Compute time: the forward pass (stage 3)
- Everything else: request handling, preprocessing, postprocessing, response delivery, and the network hops on either side (stages 1, 2, 4, and 5)
Most benchmark numbers only measure compute time. Queueing, preprocessing, and the network round trip are also on the clock, and your users feel all of it.
Remember: Inference time is measured from request to response. The forward pass is usually the largest slice, but it is never the whole clock.
Types of inference engines
"Type" can mean three different things here, and you need to make a choice on each axis: serving mode, deployment location, and hardware target.
Which inference engine fits your model?
Pick the case that matches what you are serving and where it runs.
Real-time vs. batch inference
Serving mode shapes everything downstream, and it matters more than which vendor you pick. There are three options:
- Real-time inference answers one request at a time and is judged on latency. Fraud checks and chatbot replies are typical uses.
- Batch inference processes a queue of requests on a schedule and is judged on throughput and cost. Nightly scoring jobs and embedding a large document set are common examples.
- Streaming inference is real-time inference that returns partial output as it's produced. It's judged on time to first token, and it's how LLM chat and voice agents feel responsive.
Cloud, edge, and on-device engines
Where the engine runs determines how far data has to travel:
- Cloud: Centralized GPUs make scaling easy, but every request adds a network round trip. Good for large models serving many users.
- Edge: Engines run close to the user, cutting that round trip, at the price of more complex operations. Good for latency-sensitive regional traffic.
- On-device: Phones and browsers run the model locally with no network at all, but device memory limits model size. Good for offline features like keyboard suggestions.
Hardware targets: GPU, TPU, CPU, and LPU
GPUs are the default for deep learning inference because they run thousands of operations in parallel. TPUs are Google's custom accelerators, built for the same matrix math. CPUs work well for small models and batch jobs where latency isn't critical. Newer LPU-style chips target one job specifically: LLM token generation.
Inference engines in modern AI and LLMs
Deep learning and generative AI use the same basic mechanism covered above, but model size and output format change where the bottlenecks sit.
What is inference in deep learning?
Deep learning inference is the general case: a forward pass through many stacked layers. The practical consequence is about memory, not math. A model with billions of parameters has to read its weights from memory on every pass, so memory bandwidth and batch size govern speed more than raw compute power does. That's why accelerator choice and quantization have such a large effect on deep learning inference.
What is inference in generative AI?
Generative AI inference is autoregressive. The model produces one token per forward pass, then feeds that token back in to produce the next one. A 200-token reply means 200 forward passes, in order. Here's the loop:
- Tokenize the prompt.
- Run a forward pass to produce the first token.
- Append that token to the input.
- Run another forward pass to produce the next token.
- Repeat until the model emits a stop token.
- Detokenize and return the full reply, or stream each token as it's produced.
Two metrics describe this loop. Time to first token measures how long a user waits before anything appears. Tokens per second measures how fast the rest of the reply arrives. Streaming exists because of this loop: instead of waiting for all 200 passes, users see words as they're generated.
Those metrics only tell part of the story, though.
“
"We often obsess over LLM inference speeds, but in Voice AI, the network is often the silent killer."
In a voice or messaging product, a model with excellent tokens per second can still feel sluggish if the request crosses several networks to reach it.
Applications of inference engines
Every application uses the same mechanism: frozen weights, a forward pass, and an output. What differs is how latency-sensitive the surrounding product is.
Voice and messaging
A language-learning flashcard app shows how this works in practice: text-to-speech (TTS) speaks a phrase, the learner repeats it, speech-to-text (STT) transcribes the audio, and inference scores the transcript against the target phrase. That's three AI steps inside one live phone call, and every one of them sits on the critical path.
Code example: a phone-based pronunciation coach
The example below is a trimmed version of the Telnyx language-learning flashcards app. A learner dials one of the Telnyx phone numbers assigned to the app, hears a phrase in Spanish, repeats it, and gets a score with one tip for improvement.
Before you run it, you'll need:
- A Telnyx account and API key, stored as the
TELNYX_API_KEYenvironment variable - A Telnyx phone number assigned to a Voice API (Call Control) application
- A public webhook URL on that application, so your server receives call events
How the flow works: your server responds to call events in order.
- When the call is answered (
call.answered),speak_phrase()reads the target phrase to the learner. - When playback finishes (
call.speak.ended),start_listening()begins transcribing the learner's reply. - When a transcription event arrives (
call.transcription),score_attempt()sends the transcript and the target phrase to the model. - Your server passes the model's feedback back to
speak_phrase(), then moves on to the next card.
The first call plays the phrase, the second transcribes the learner's answer, and the third is the inference call: it sends the target and transcript to an open-source model and gets back a score with a tip. All three run on one platform, inside one phone call.
Classification, search, and recommendation
Classic supervised uses follow the same mechanism with a different place in the request path:
- Classification: Inference produces a probability. The application applies a threshold and assigns a label, alongside logging, rules checks, and business logic.
- Search: Inference produces an embedding vector. A vector database handles the nearest-neighbor lookup that finds matching results.
- Recommendation: Inference scores a set of candidates. Retrieval, filtering, and ranking logic decide what the user actually sees.
In these cases, the inference call is often a small share of the total request path. In voice, it sits directly on the critical path of a live conversation, and that changes how you have to think about latency.
Running inference in production
Once a model serves real traffic, the question isn't how fast it runs on a benchmark. It's how long the user waits.
What an inference call looks like
An inference call is an HTTP request to an endpoint. It names a model, carries an input payload and parameters like maximum tokens, and returns the model's output in the response.
The multi-model inference switcher example below shows a production pattern. The model name isn't hardcoded. It's read from a KV feature flag at request time:
Swapping models becomes a config change, not a deploy. The engine and the model are decoupled from your application, so you can test, compare, and roll back models without touching the service that calls them.
Where production inference latency actually goes
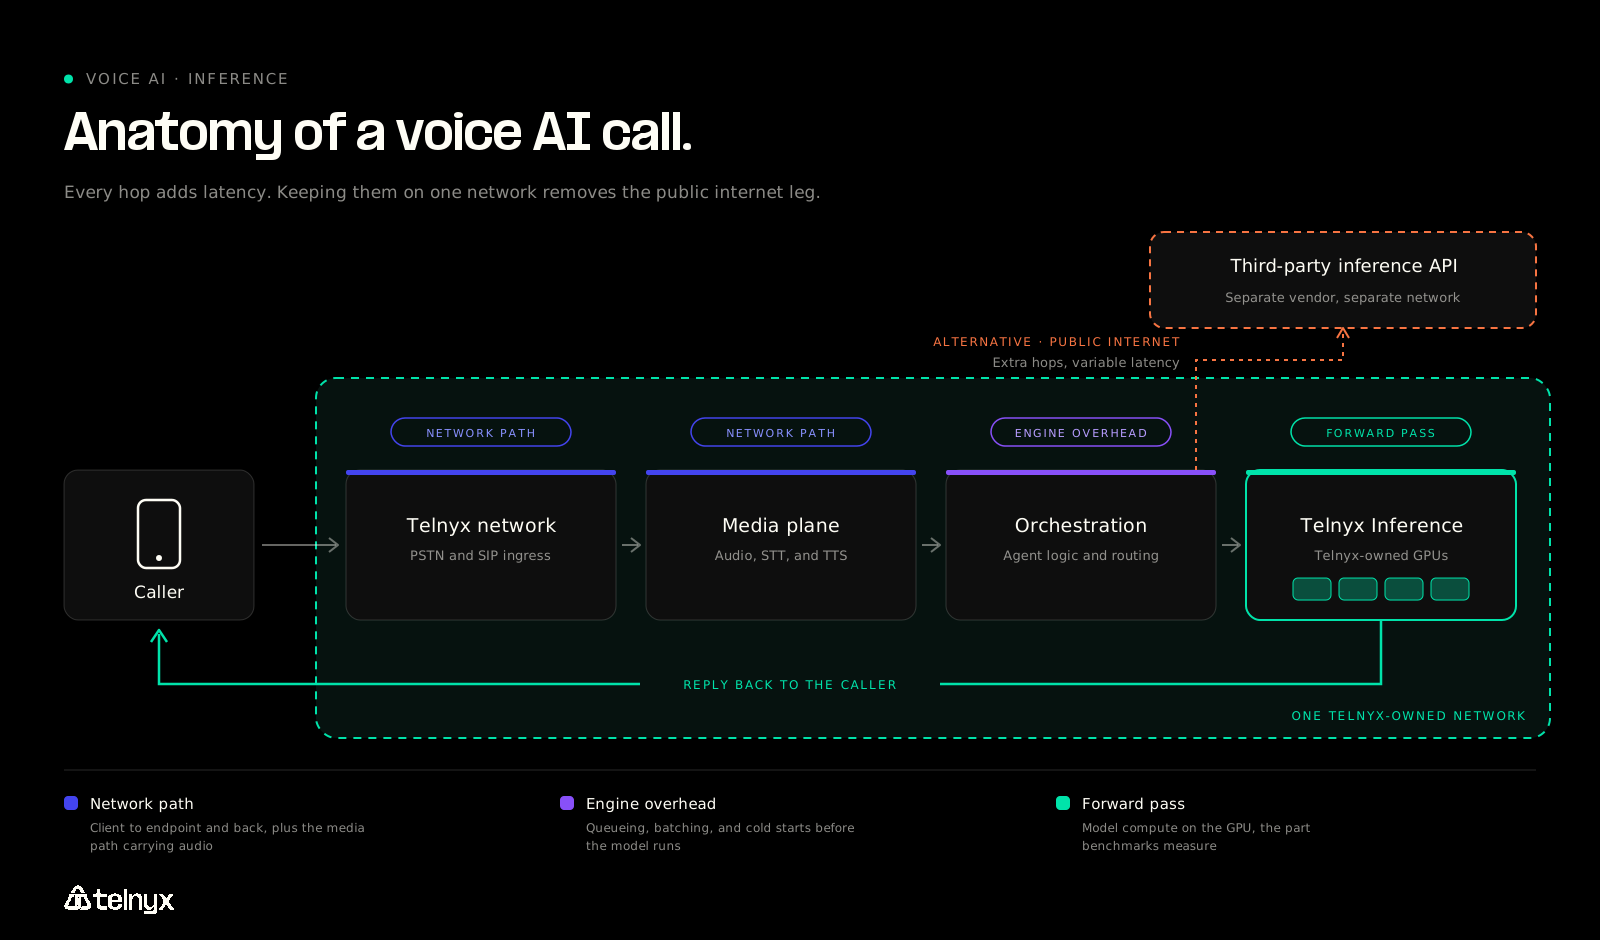
Production inference latency falls into three buckets:
- Forward pass: the model's compute time. This is what benchmarks report.
- Engine overhead: queueing, batching delays, and cold starts when a model has to load before it can serve.
- Network path: the trip from the client to the endpoint and back. For voice, that also includes the media path carrying audio between the caller and the AI.
Only the first bucket shows up in most benchmark results. If your product feels slow despite strong tokens-per-second numbers, measure the third bucket first. A voice agent built with Telnyx Voice AI shows why: the audio, the transcription, the model, and the synthesized reply all have to move between systems, and every hop between vendors adds time the benchmark never saw.
Telnyx Inference
Telnyx Inference serves open-source models through an OpenAI-compatible API, running on Telnyx-owned GPUs. Those GPUs sit on the same private network that carries Telnyx voice and messaging traffic, so the network leg of a voice or SMS inference call doesn't cross the public internet to reach the model.
Because the API is OpenAI-compatible, existing client code usually needs only a new base URL and model name. You can browse the available models in the developer docs, and teams already running voice agents can connect Telnyx Voice AI Assistants to any OpenAI-compatible LLM. For background on why we built it this way, read how Telnyx started building its AI Inference tools.
“
"Most 'end-to-end Voice AI' claims fall apart when you measure what actually matters: the end customer experience in real time. Turn latency, jitter, interruption handling. Not benchmarks on a slide, but behavior on a live call. That only happens when you control the full stack. Network, media plane, orchestration, and inference paths, not a fragile chain of third-party services over the public internet. This is the bar Voice AI should be held to."
Frequently asked questions
Know where your latency lives. Then fix it.
You can now look at any slow inference call and ask the right question: is the delay in the forward pass, the engine, or the network? For voice and messaging AI, the network is often the answer. Run inference where the network isn't the bottleneck, on GPUs that share a network with your calls and messages.
Try Telnyx InferenceShare on Social


