AGENT RUNTIME
Frontier models that earn their place
Hosted models are chosen deliberately, not to fill a dropdown. Kimi K3 for real-time voice AI, GLM-5.2 for dev work, and MiniMax-M3 for cost.
The shift to open-weight
Open-weight models are leaving closed-source behind. Same quality, fraction of the cost. Telnyx hosts OS models on GPU infrastructure we own, so there's no cloud provider markup in your per-token price. Switch from closed-source models and save up to 75%, no compromise on quality, no vendor lock-in.
Ultra-low latency
Run state-of-the-art models at the edge close to your edge users. Consistently deliver sub-100 ms response times across the Americas, Europe, MENA, and APAC.
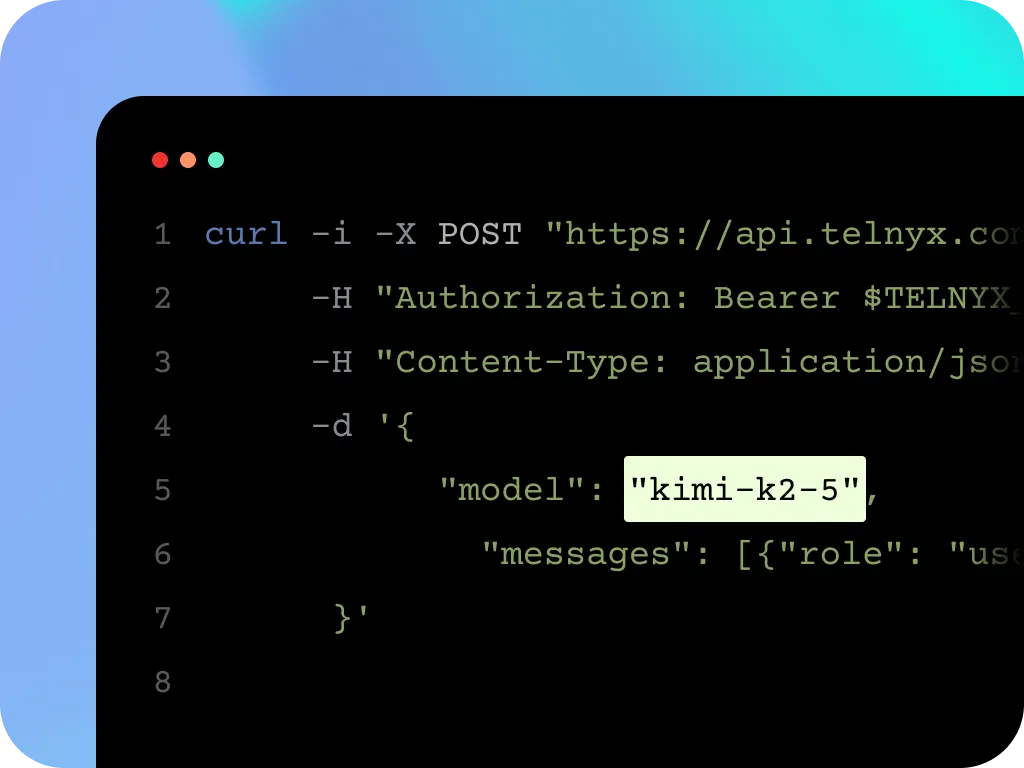
No vendor lock-in
Save up to 75% vs proprietary models with OpenAI compatible endpoints that work with existing SDKs, so you can switch models easily without rewriting code.
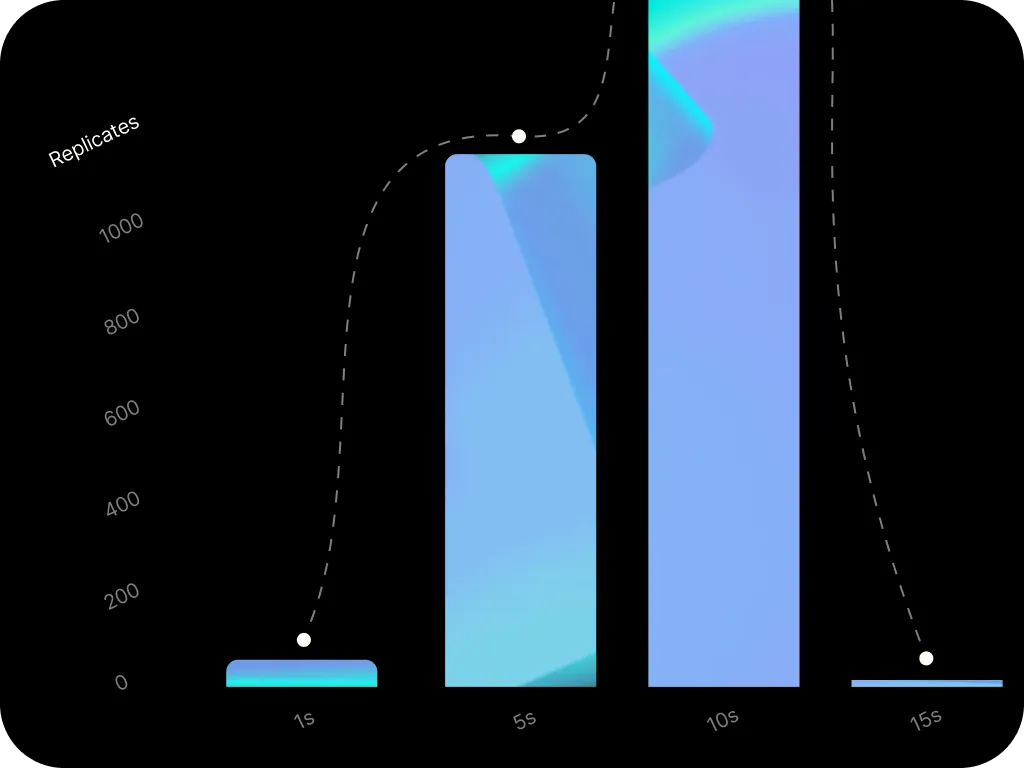
Autoscaling by default
Go from 0 to 1000s of requests per second without planning around available capacity. Pay only for what you use.
FEATURES
Production-ready inference APIs
OpenAI-compatible endpoints that work with your existing SDK and deploy globally.
In-region deployment
Inference runs in the Americas, Europe, MENA and APAC with LATAM coming soon. Your data stays where your users are, and stays private.
OpenAI-compatible API
Save up to 75% on your inference bills using your existing OpenAI SDK by changing the base URL to access open-source models.
Function calling
Connect LLMs to external tools and APIs to build agents that take action, not just generate text.
Autoscaling
Dedicated GPUs handle concurrent requests and scale automatically with your workload, no capacity planning or cold starts to worry about.
Fine-tuning
Customize models with your own data via the Fine-Tuning API using the same infrastructure and API key.
Structured output
JSON mode and regex constraints ensure inference output conforms to your schema for production-grade reliability.
HOW IT WORKS
Migrate in minutes
OpenAI-compatible. Change your base URL, that's it.
PRODUCTS
Building AI that reaches beyond the chat?
Your AI doesn't have to stop at text. Telnyx runs text-to-speech, voice AI, and telephony on the same infrastructure. Same API key, same network, same bill.