Voice
How does AI voice work? The audio path from caller to reply
AI voices cover the whole conversational loop from speech recognition to text-to-speech output.
By Osman Husain
Quick answer: AI voice works in a loop: speech recognition turns the caller's audio into text, a language model decides what to say, orchestration logic tracks the conversation, and text-to-speech speaks the reply. Real-time systems overlap some steps: they start speaking before the full reply is written, so answers can arrive in about the pause people leave in conversation. Telnyx's Voice AI agents integrate speech-to-text, LLM hosting, and text-to-speech on the same carrier network that carries the call.
What is AI voice?
AI voice is software that hears speech, understands what was meant, and answers in spoken audio. AI voice covers the full conversational loop, because a text-to-speech tool can only read text aloud and a speech recognizer can only transcribe.
A voice AI agent is a system that holds a conversation using that loop, usually over a phone call. Speech AI is the umbrella term for technologies that recognize, interpret and generate speech, and text-to-speech is one component inside it. The quality of the output depends on how fast the loop closes and how well each stage copes with real phone audio.
How does AI voice work?
Voice AI works by connecting the parts: every turn of a call runs the same stages of capture, recognition, understanding, orchestration and speech, with some parts overlapping each other for lower latency.
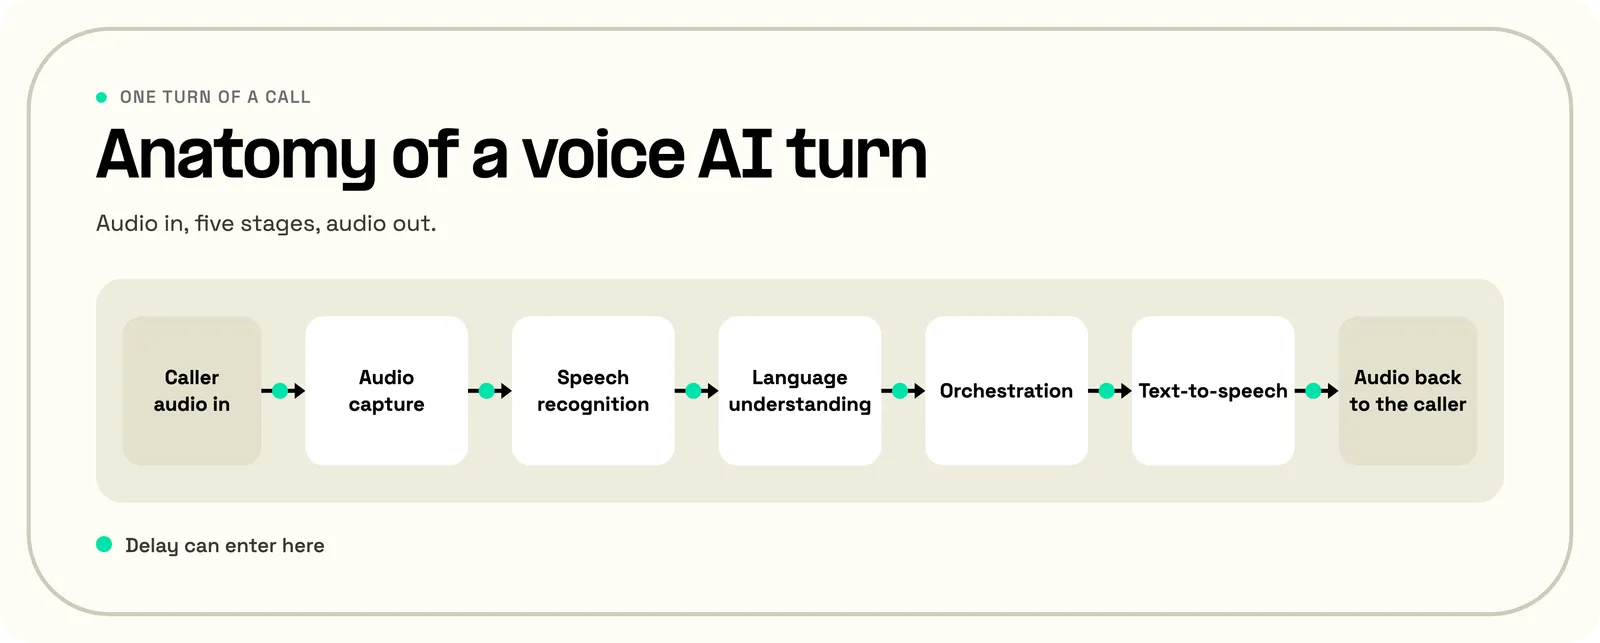
Speech recognition and text-to-speech both work on partial output, so they overlap with the surrounding stages. The language model usually waits until the caller finishes, and that wait is the main tuning trade-off: too short cuts callers off, too long adds delay to every turn.
Audio capture and streaming
Phone audio reaches the system as a continuous stream, not as a finished recording. Voice activity detection marks where the caller starts and stops speaking, and the audio moves onward in short frames. Deciding that an utterance is finished is a setting, usually called endpointing: how long the system waits after silence.
The same detection runs while the reply plays, because callers interrupt. That is barge-in: the caller talks over the assistant and it stops speaking. It is on by default for Telnyx assistants, and interruption prediction lets builders set how confident the assistant must be before it yields, so a "yeah" or "uh-huh" does not cut it off. Builders can also turn interruptions off in the interruption settings.
Speech recognition
Speech recognition turns the caller's audio into text. Streaming recognition emits words as they are spoken instead of waiting for the end of the sentence, which lets the next stage start early. Telnyx's speech-to-text API returns those partial transcripts as interim results when the interim_results parameter is on.
Language understanding
A language model reads the transcript, infers what the caller wants, and drafts the reply or requests a tool call, such as a calendar lookup. Larger models tend to follow long or messy utterances better and answer more slowly, so model choice is a latency decision as much as a quality one.
Telnyx Inference hosts open-weight models, and the available models list shows which ones voice assistants can use.
Orchestration
Orchestration logic wraps the model: it holds the call state, sends the model the context for each turn, and decides what the system may do with the output. That includes what policy requires next and when to hand off to a person.
It also shapes the reply for the listener, with short clauses and speakable numbers and dates. Any required disclosure goes in before text-to-speech, so the audio matches what legal approved.
Text-to-speech
Modern text-to-speech usually runs as two models: an acoustic model predicts a spectrogram from the text, and a vocoder turns the spectrogram into a waveform. Streaming the output in small chunks lets speech begin before the whole reply exists.
Voice controls depend on the engine. SSML tags work on AWS Polly and Azure voices, and speed settings vary by provider, so each voice needs its own test on the text-to-speech API.
AI voice recognition: accuracy, accents and noise
AI voice recognition is speech recognition built on neural networks, and its accuracy is reported as word error rate. Word error rate counts the words a system gets wrong against a human transcript and divides by the words spoken.
Three conditions push the rate up: background noise and overlapping speech, accents the training audio underrepresented, and vocabulary the model has rarely seen, such as product names or drug names. Builders counter them with noise suppression and echo cancellation ahead of the model, vocabulary hints for the recognizer where the engine supports them, and tests on the deployment's own audio, sliced by accent and noise level. An average across all calls can hide a failure that lands on one accent group.
Domain vocabulary has a second lever on the model side: retrieval or lookups that supply the right product or drug name after recognition. Recognition hints and retrieval fix different stages.
AI voice technology: latency and the call path
AI voice technology runs three neural models, speech recognition, a language model and text-to-speech, over the telephony network that carries the call. The models set how accurate and natural the agent sounds. Latency and the call path set how fast it answers.
The latency budget
Latency is the time from the caller's last word to the first audio of the reply, and human conversation sets the benchmark for it. Across ten languages the mean gap between turns is 208 ms, with language means from 7 ms (Japanese) to 469 ms (Danish), and a literature review puts median gaps at 0 to 300 ms.
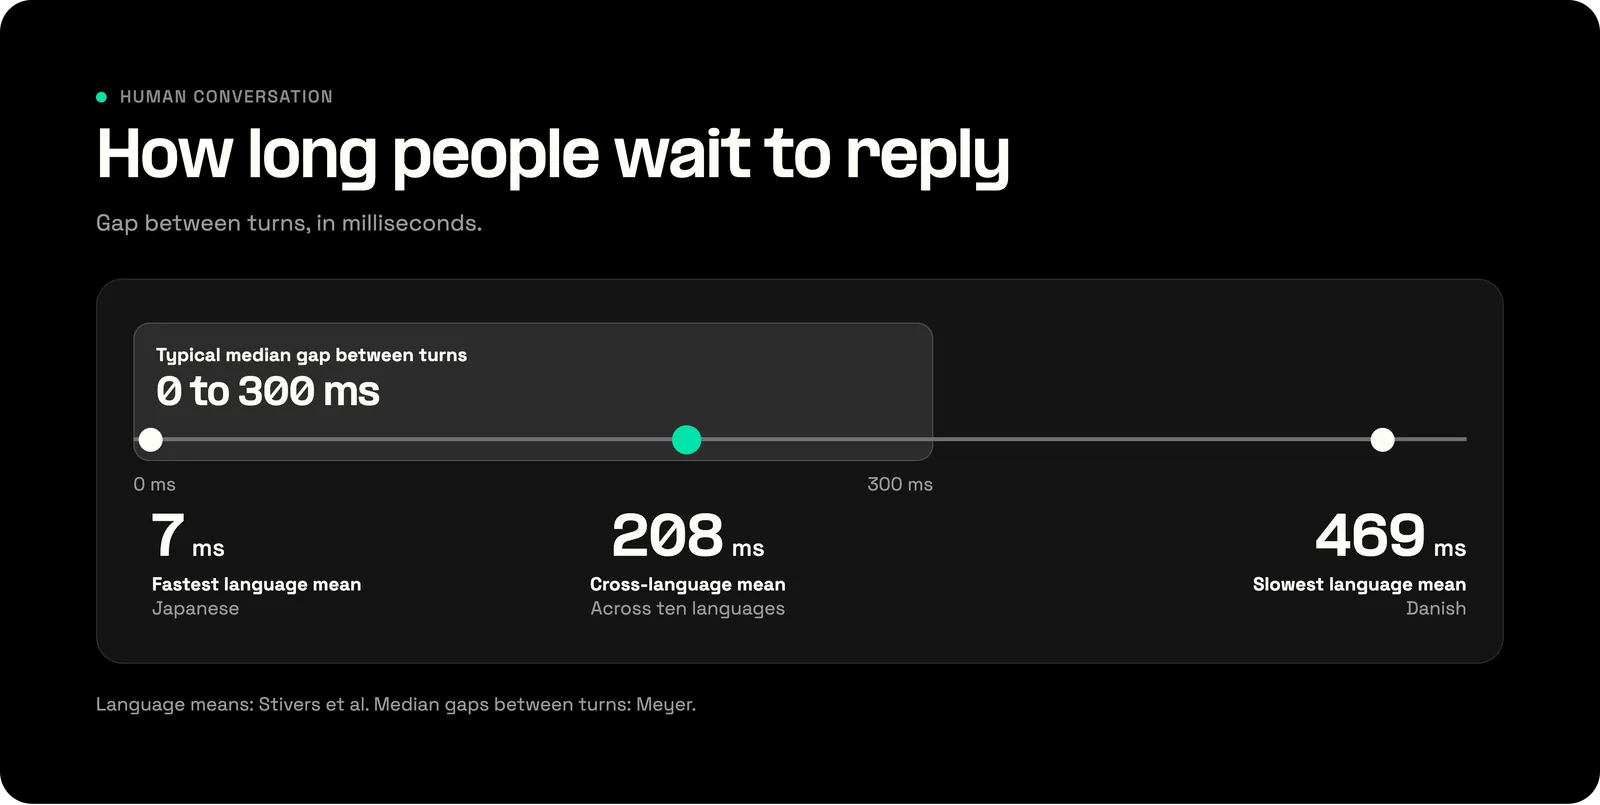
Each stage of the loop adds delay, and only some of it comes from the models.
Where delay enters at each stage of a voice AI turn.
| Stage | What happens | What adds delay |
|---|---|---|
| Capture | Audio arrives and the end of the utterance is detected | The wait after silence before finalizing; network jitter |
| Recognition | Speech becomes text | Waiting for the full sentence instead of streaming |
| Understanding | The reply is generated | Model size; tool calls; a hop to a separate inference vendor |
| Orchestration | Policy, tools and disclosures are applied | Each call to an external system |
| Speech | The reply becomes audio and returns to the caller | Waiting for the full reply; a hop to a separate speech vendor; the return path over the network |
Every network hop between providers adds to the wait. A stack that rents telephony from one provider and buys recognition, inference and speech from others crosses a network between every pair.
How a call reaches the model
A phone call enters through a carrier, which passes the audio to recognition, then the language model, then text-to-speech, and returns the reply on the same call. Telnyx co-locates its GPU infrastructure with its telephony network in the same data centers, so audio reaches transcription, LLM inference and text-to-speech without leaving the private network.
Telnyx holds sub-200 ms end-to-end round-trip latency in production, over a backbone of 17 points of presence, with inference routed to the nearest GPU region on a best-effort basis. Voices and transcription engines from other providers, such as AWS Polly or Azure, are offered alongside Telnyx-hosted models and sit outside that claim.
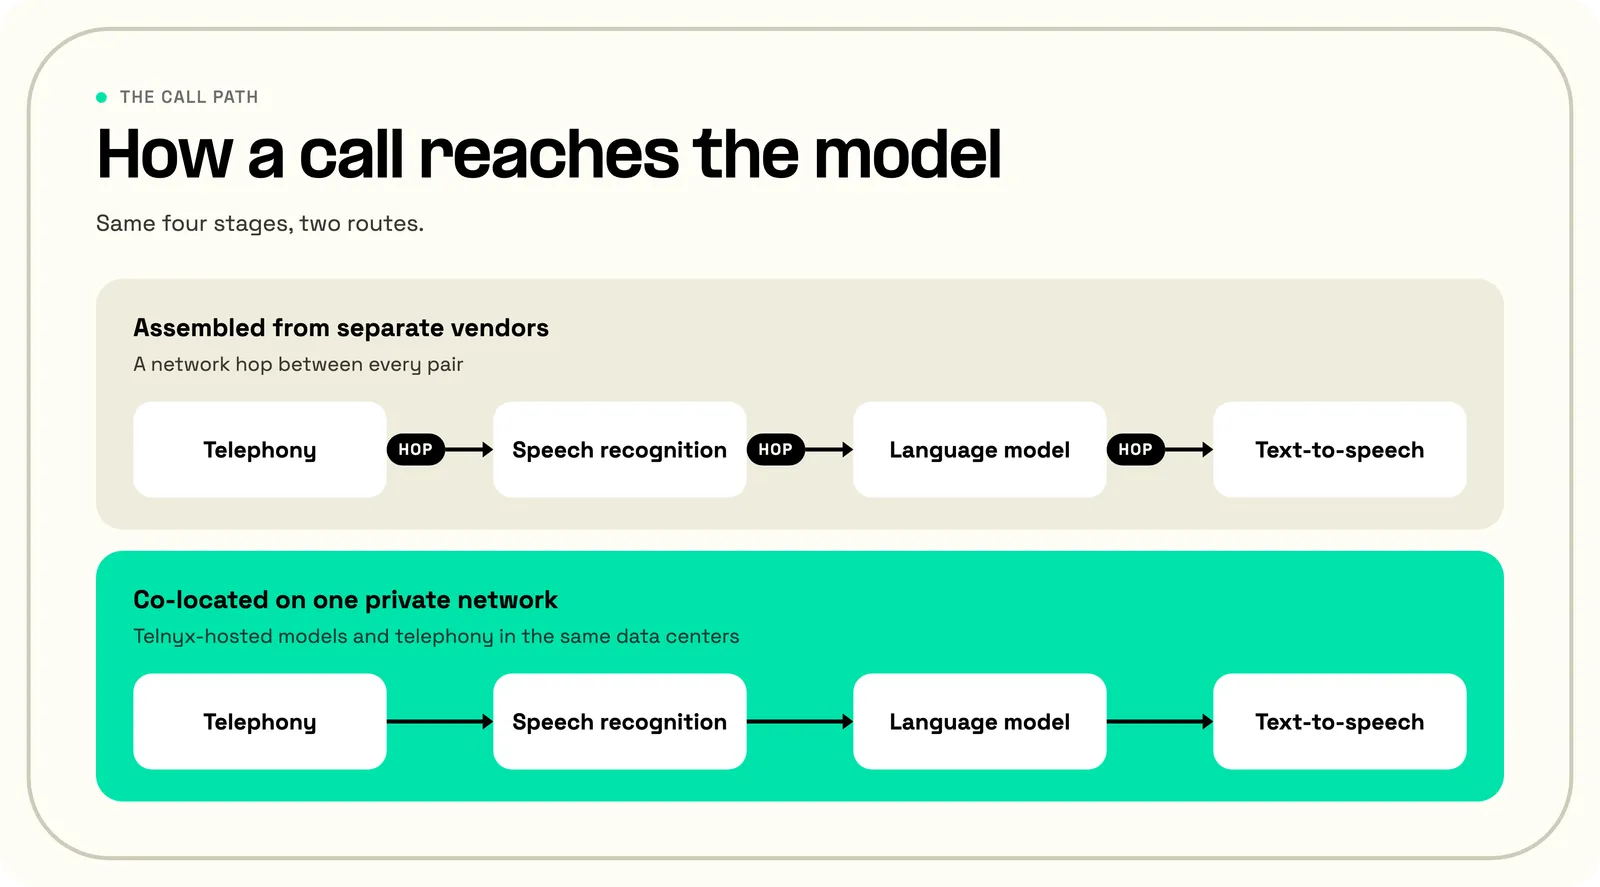
The Voice API runs call control, the commands that act on a live call, on the same call that carries an AI assistant.
AI voice use cases and benefits
AI voice is used in multiple industries and benefits most when paired with a human in the loop.
Customer support
Support lines exhibit the highest volumes with repetitive questions, so a voice agent can be trained to address those without human intervention. In customer service the loop runs once per caller turn, and the orchestration layer decides when to escalate. The voice AI agents platform packages that loop: an assistant attached to a call handles recognition and answers in a chosen voice.
Each call also leaves structured data: the intent, the outcome and the fields collected. This can be used to refine the model further for better responses.
Outbound sales
Outbound is harder than inbound because consent comes first. The benefit is a qualified, context-rich handoff to a sales rep, and the technical work lies in detecting voicemail greetings and exiting cleanly.
Healthcare
Healthcare teams use AI voice for scheduling, intake, and refills. In a physician-supervised text-chat deployment at the health and insurance company Alan, physicians rated 95% of 298 AI-handled conversations good or excellent, and none potentially dangerous. Separately, half of healthcare leaders report their organizations have already implemented generative AI, up from 47% a year earlier.
Accessibility
More than 2.5 billion people need at least one assistive product. Voice interfaces can lower barriers for people with motor impairments, low vision or limited reading ability, and for older callers who prefer a phone call to an app.
How to use AI voice in a product
Teams that add AI voice to a product take five steps: choose an architecture, define what the agent handles, connect it to the call, test on real audio, and monitor the results.
- Choose the architecture. A managed assistant on one platform takes the least work, a loop run in-house gives the most control, and separate vendors add a network hop with each vendor.
- Define the call flow. List the intents the agent handles, the knowledge and tools behind them, and what it hands to a person. Knowledge reaches the model as retrieved documents or tool calls.
- Connect the agent to the call. Telnyx's Voice API starts a Telnyx AI assistant on a live call and hands the caller to a human by bridging the original call leg to a new leg. A leg is one side of a call, and if a transfer fails, the original call stays active.
- A managed assistant attaches with the ai_assistant_start command, using the call's
call_control_id, and any OpenAI-compatible custom LLM can serve as the model. - A loop run in-house uses call control and webhooks with streaming speech-to-text and text-to-speech WebSockets.
- A managed assistant attaches with the ai_assistant_start command, using the call's
- Test on real audio. Record real calls and measure accuracy and delay on them, sliced by accent and noise level. Both depend on the audio and on the route it takes, so a team's own calls settle the question.
- Monitor and improve. Track misrecognized calls, escalations and caller feedback, then change prompts, vocabulary hints or the engine where problems cluster. Evaluate on recorded calls held out from any tuning, because tuning on the test calls hides the failures production will show.
Consent and compliance for AI voice
Consent rules attach to the call, so every AI voice deployment has to meet them.
In the United States, the FCC ruled in February 2024 that the TCPA's limits on artificial or prerecorded voice cover AI-generated voices, so those calls need the called party's prior express consent. Telemarketing calls to wireless numbers need prior express written consent under 47 CFR 64.1200.
In the EU, Article 50 of the AI Act requires providers to tell people when they interact with an AI system, unless that is obvious, and to mark synthetic audio in a machine-readable format.
Recording consent varies by state and country, so announcements, pause and resume, and redaction need configuring per jurisdiction. Voice cloning needs explicit consent from the person whose voice it is, plus fraud controls.
Card entry is a special case. Pay over Voice collects card details as keypad tones and keeps them out of recordings, transcripts, DTMF logs and the assistant's audio for the session.
Frequently asked questions about AI voice
How does AI voice work on a phone call?
Voice AI works on a phone call by passing each caller turn through recognition, a language model, orchestration and text-to-speech, with each stage streaming into the next. Delay builds at every network hop between vendors, so the route the audio takes matters as much as the models on it.
What is the primary function of speech AI?
The primary function of speech AI is to turn spoken language into text, interpret it, and generate spoken replies. Recognition covers the first step, a language model the second, and text-to-speech the third. A system that covers only one of them is usually called speech recognition or text-to-speech.
How does AI text to speech work?
AI text-to-speech usually runs as two models: an acoustic model predicts a spectrogram from the text, and a vocoder turns it into audio. Streaming the output in small chunks lets speech begin before the full reply exists.
How accurate is AI voice recognition?
Accuracy is reported as word error rate, the share of words a system gets wrong against a human transcript, and it varies with the audio. Noise, accents and unfamiliar vocabulary raise it.
Can AI voice handle accents, noise and technical jargon?
AI voice can handle all three under conditions. Noise suppression and echo cancellation clean the signal before recognition, training audio with varied accents helps, and domain vocabulary such as drug or product names needs vocabulary hints or a lookup.
What is the difference between AI voice and traditional IVR?
Traditional IVR relies on touch-tone input or fixed menus. AI voice takes open-ended speech, infers intent, and answers in natural language, so callers use their own words. The trade is predictability: a menu behaves the same every time, while a model needs testing on real audio.
Is using AI voice legal?
Using AI voice is legal, with consent and disclosure rules attached. In the United States, calls with an AI-generated voice need the called party's prior express consent, and telemarketing to wireless numbers needs written consent. In the EU, Article 50 of the AI Act adds disclosure duties from 2 August 2026.
What latency is acceptable for real-time AI voice?
Human turn-taking averages a 208 ms gap across ten languages, with typical medians between 0 and 300 ms in a literature review. A reply that starts well above that range starts to feel slow.
For build questions, contact us.
Share on Social
Osman is the Global AEO/SEO Lead at Telnyx, helping make voice AI and communications products clearer for builders. With almost a decade of experience in SEO, he previously led growth at Windscribe and Enzuzo, shipping and scaling organic programs that reached millions.


