Edge Compute
A home for real-time agents
Run your agents on one platform instead of wiring together five vendors. One runtime, one bill, and compliance built into the network.

How it fits together
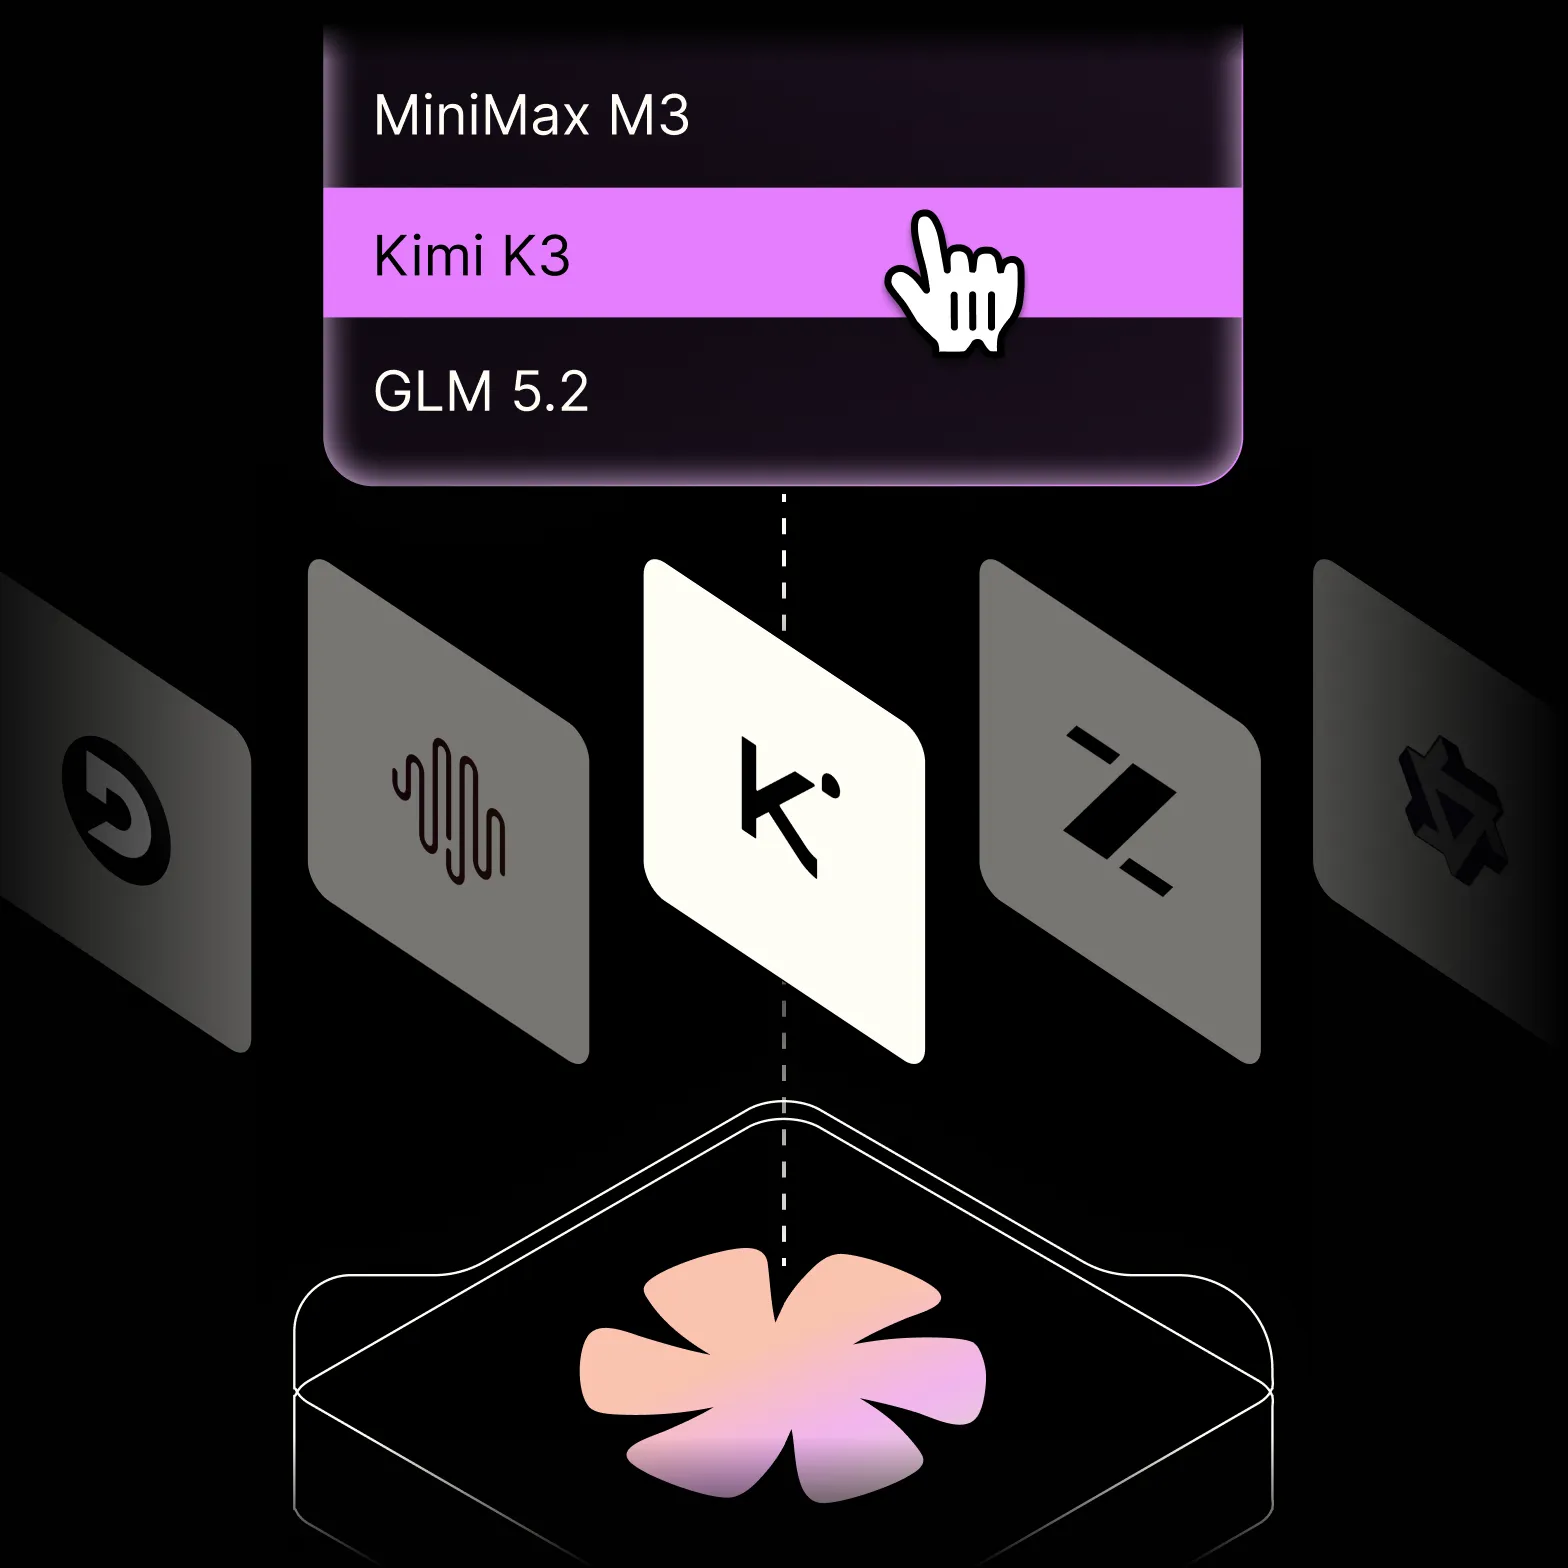
One system, not a stack of integrations.
View all demosYour agent
Your code, your framework.
Layer one - runtime, where it lives
FunctionsStateful ActorKVCloud FSCloud StorageSQLWebSocket
Layer two - primitives. What it uses
InferenceVoiceMessagingWirelessEmailPayments
Telnyx network - where it runs.
6 edge compute sitesOwned TelephonyOwned GPUsPrivate backbone
Live demos
Primitives every agent needs
Primitives that allow agents to interact with the physical world. Real phones, real inboxes, real money, each a standalone API, wherever your agent runs.
- ComputeFunctions
Functions
Run event-driven code at the telecom edge without managing servers.
- ComputeStateful Actor
Stateful Actor
Long-lived actors that keep state between invocations, close to your traffic.
- StorageCloud Storage
Cloud Storage
S3-compatible object storage colocated with compute and the network.
- StorageKV
KV
Low-latency key-value storage for session state and configuration.
- StorageCloudFS
CloudFS
A shared file system your agents can mount from any edge site.
- StorageSQLDB
SQLDB
Serverless SQL databases provisioned per agent or per workload.
COMPETITION
Voice, inference, and compute on one network.
No one else operates the telephony, the GPUs, and the runtime as a single system. Here's an honest look at how the platforms compare.
CAPABILITY


Owns the underlying carrier & PSTN network
Partial(aggregator)
Voice, messaging & inference on one owned network
Partial
Global edge footprint for low-latency inference
Partial
Durable state at the edge
In-region data residency
(by architecture)
(via config)
Partial
Bring your own agent framework
Partial
Partial
Proprietary voice / TTS model quality
Partial
Single vendor across voice + compute + AI
SECURITY
Sovereign by architecture.
In-region traffic is processed by in-region compute, not because you configured it, but because that is how the network is built. We run live sites across North America, Europe, APAC, and MENA, so the data boundary follows the traffic. One boundary, one DPA, one audit.