
AGENT RUNTIME
Frontier models hosted on in-region GPUs
Hosted models are chosen deliberately. Each one is the best at something real: high-throughput reasoning, cost-efficient intelligence at scale, and real-time interactive workloads. For the current lineup, see telnyx.com/pricing/inference-api.
The shift to open-weight
Open-weight models have caught up with models from frontier labs. Same quality, fraction of the cost. Telnyx hosts models on GPU infrastructure we own, so there's no cloud provider markup in your per-token price. Switch workloads from the frontier and save up to 75%, no compromise on quality, no vendor lock-in.
Ultra-low latency
Run state-of-the-art models on GPUs colocated with the network that serves your users. Inference happens in-region across the Americas, Europe, MENA, and APAC, so data stays where your users are with zero data retention. No inter-provider hops, no cross-border routing, no training on your data.
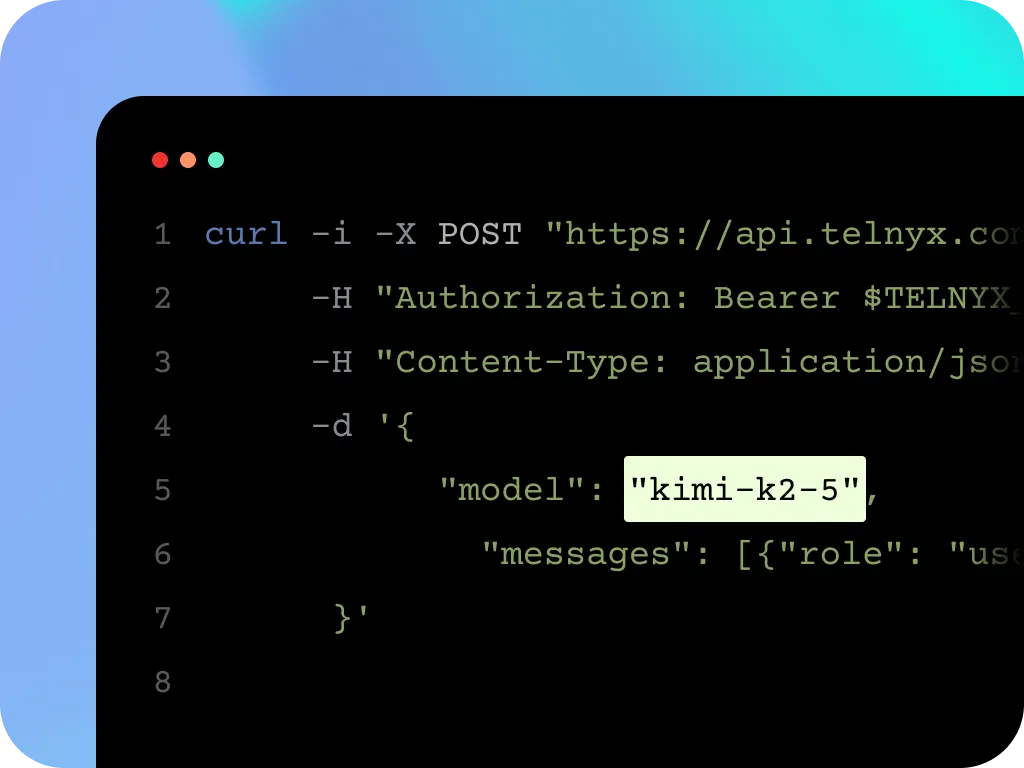
Cut costs, gain flexibility
Save up to 75% vs proprietary models with OpenAI compatible endpoints that work with existing SDKs, so you can switch models easily without rewriting code.
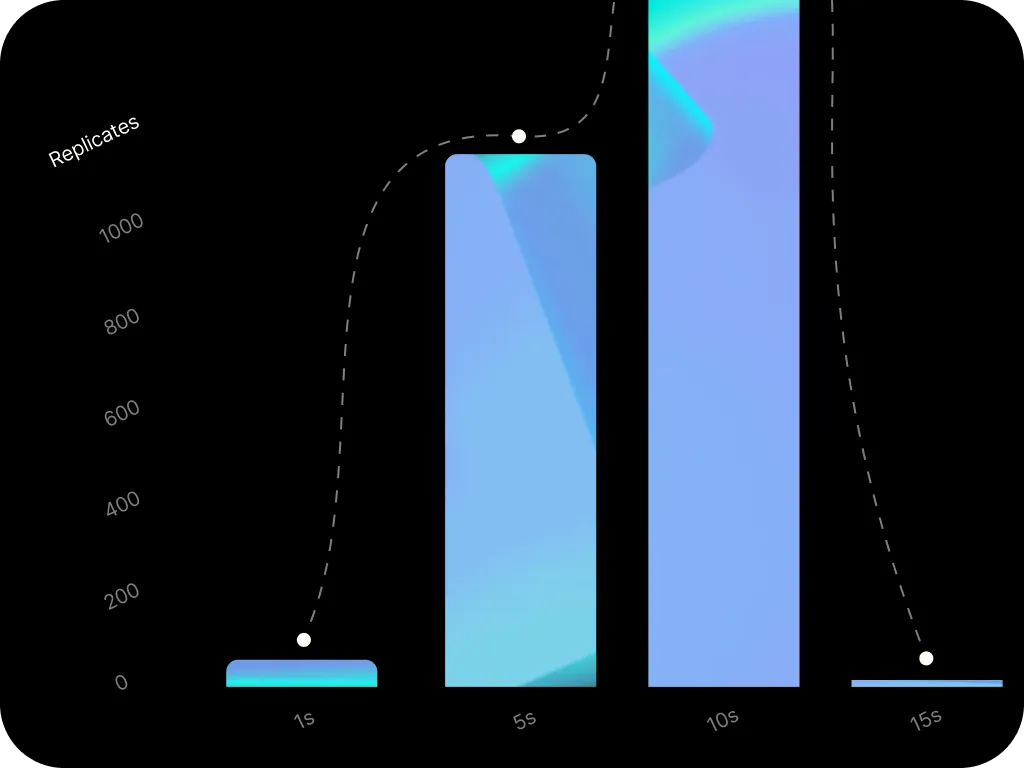
Autoscaling by default
Go from 0 to 1000s of requests per second without planning around available capacity. Pay only for what you use.
Route each request based on latency requirements
A single parameter on each request controls serving capacity and price. Set service_tier to flex, default, or priority on any chat completion call. Omit the field and you get Default. Same model IDs, same synchronous API, no new endpoints to integrate.
Default
Standard serving capacity at standard rates. This is what every existing inference call already uses. All published pricing comparisons and benchmark results refer to Default tier. Omit service_tier and this is what you get.
Priority
Serving capacity optimized for low-latency interactive workloads, including voice orchestration. Priority does not change the model or the context window. It selects faster serving capacity at a different rate. Live on select models today, more models and regions coming soon.
Flex
Lowest rates, optimized for throughput where minutes of end-to-end latency is acceptable. Flex is for background work: offline evaluation, document processing, background summarization. All requests remain synchronous. Available in US on select models.
FEATURES
Production-ready inference APIs
OpenAI-compatible endpoints that work with your existing SDK and deploy globally.
In-region deployment
Inference runs in the Americas, Europe, MENA and APAC with LATAM coming soon. Your data stays where your users are, and stays private.
OpenAI-compatible API
Save up to 75% on your inference bills using your existing OpenAI SDK by changing the base URL to access open-source models.
Priority tiers
Tiers run on Telnyx-hosted models, so you change one field in the request body rather than adding a second inference provider.
Autoscaling
Owned GPU infrastructure handles concurrent requests and scales automatically with your workload. No capacity planning, no cold starts.
Vendor flexibility
Access leading open-weight models from z.ai, DeepSeek, Minimax and more as they launch.
Structured output
JSON mode and regex constraints ensure inference output conforms to your schema for production-grade reliability.
HOW IT WORKS
Migrate in minutes
OpenAI-compatible. Change your base URL, that's it.
PRODUCTS
Building AI that reaches beyond the chat?
Your AI doesn't have to stop at text. Telnyx runs text-to-speech, voice AI, and telephony on the same infrastructure. Same API key, same network, same bill.