Author
Sonam Gupta, PhD
Developer Evangelist
Sonam is a San Francisco-based developer advocate, originally from India. She has completed 2 Master's Degrees and her PhD in Data Science from the Harrisburg University of Science & Technology. Previously, Sonam worked for the startups Ozmosi and aiXplain. In her free time, you will find Sonam dancing, writing, and exploring local coffee shops.
- 8
- Articles
- 2025
- Joined
Latest articles
Everything Sonam has published, most recent first.
- Inference
GLM-5.3 latency benchmarks across four inference providers
We benchmarked GLM-5.3 latency across Telnyx, Baseten, Together AI, and Fireworks using the same 60 prompts. Telnyx delivered the lowest median completed-response time in five of six workloads and the lowest observed p95 E2E in all six.
 Conversational AI
What Is Voice AI Latency? Typical Numbers, Standards, and How to Measure It
Learn about voice AI latency, benchmark response time, and how it is measured end to end for real phone calls.
- Inference
Inference Benchmark: Which Latency Metric Should You Optimize For?
A head-to-head latency benchmark of three leading inference providers across 540 streamed requests.
 Inference
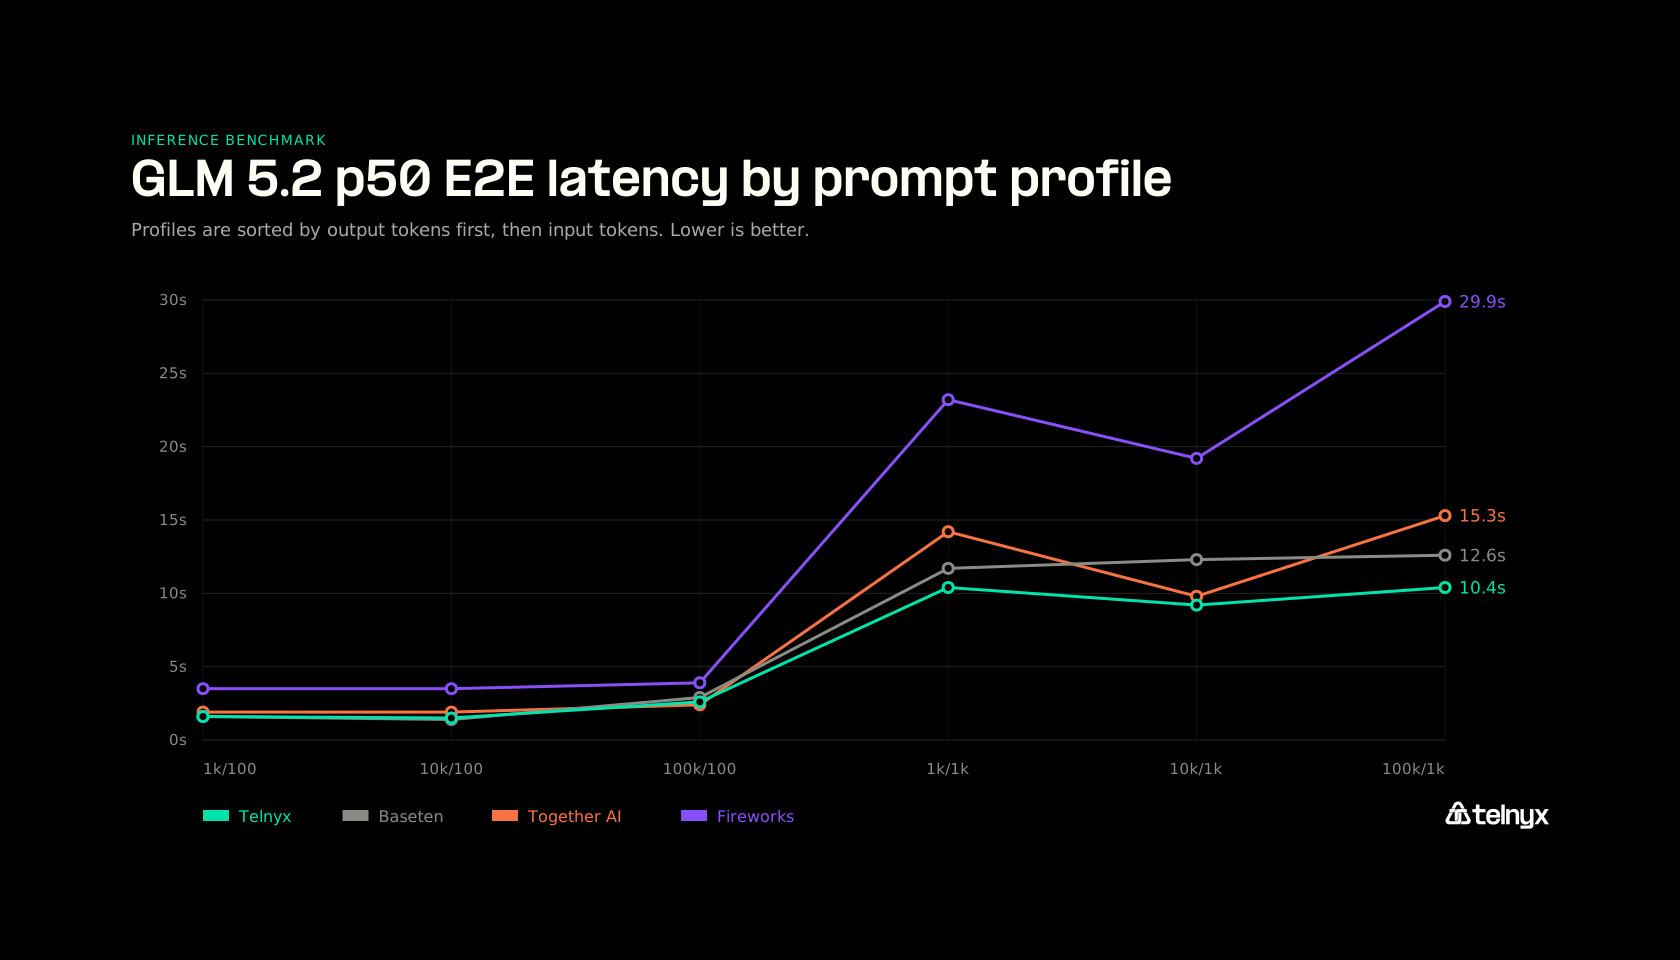
GLM 5.2 Inference benchmarks across 4 providers
This report compares GLM 5.2 inference latency across Telnyx, Baseten, Together AI, and Fireworks using the same six prompt profiles and 10 streamed runs per provider/profile cell.
 Inference
GLM-5.3-Flash Benchmarks
GLM-5.3-Flash inference benchmarks comparing Telnyx, Baseten, Together AI, and Fireworks on throughput and completion reliability.
 Inference
DeepSeek V4 Flash inference benchmarks on Telnyx
DeepSeek V4 Flash inference benchmarks comparing Telnyx StatefulActor, Baseten, Fireworks, and Together AI on E2E latency and throughput.
 Insights and Resources
Running Repeatable LLM Latency Benchmarks with Telnyx stateful actors
How Telnyx stateful actors cut TTFT by 67% for MiniMax M3 and 32% for GLM 5.2 in repeatable LLM inference latency benchmarks, and why stateful compute fits production AI workflows.
- Inference
MiniMax M3 Runs Best on Telnyx Inference
We benchmarked MiniMax M3 across Telnyx, Together AI, and Fireworks. Same model, same prompts, same streaming setup. Telnyx delivered the fastest E2E latency, 21% higher throughput, and the most consistent performance.


