What is hyperparameter optimization? Tuning methods and examples
Hyperparameter optimization, or tuning, finds the settings that control how a model learns. What hyperparameters are, how tuning works, and the methods.

Editor: Andy Muns
Updated October 2026
Hyperparameter optimization (HPO), also called hyperparameter tuning, is the search for the hyperparameter values that give a machine learning model its best performance on data it was not trained on. Hyperparameters are the settings fixed before training starts, such as the learning rate or the depth of a decision tree. The model learns its parameters from data; its hyperparameters decide how that learning runs.
Tuning can matter as much as the model itself. When Melis, Dyer and Blunsom carefully re-tuned an older kind of language model, it outperformed newer designs.
What is hyperparameter optimization?
Hyperparameter optimization chooses the settings that training runs under. Training, sometimes called parameter optimization, fits a model's parameters to data.
One example is a model that tells a voice AI agent why someone is calling, built with gradient-boosted trees. Before training, someone has to pick its learning rate and how deep each tree can grow.
Each choice gives a different model. HPO tries candidate settings, trains a model with each, scores it on calls held out from training and keeps the best.
What is a hyperparameter?
A hyperparameter is a setting that is fixed before training and is not learned from the data. Each kind of model has its own:
- A neural network has a learning rate, how big a step training takes each time it adjusts the weights, and a batch size, how many examples it looks at before each step.
- It also has a number of epochs, or full passes through the training data, and a number of layers.
- Gradient-boosted trees, as in XGBoost, have a learning rate too, plus the depth of each tree and the number of trees.
- A support vector machine has C, which trades training errors against a wider margin, and gamma, which sets how far one training example's influence reaches.
For a neural network, the learning rate is usually the first to tune. Bengio calls it often the single most important hyperparameter.
Hyperparameters vs parameters
Parameters are what the model learns. In a neural network they are the weights; in gradient-boosted trees they are the split points and the values in each leaf. The finished model is made of them.
Hyperparameters are set outside training, by a person or a tuning method. A learning rate shapes the weights a network ends up with, but the finished model does not contain it.
A quick test: if training changes it, it is a parameter. If it has to be set before training starts, it is a hyperparameter.
Why hyperparameter optimization matters
The same model can look weak or strong depending on its settings. They decide whether it underfits or overfits, the balance known as the bias-variance tradeoff.
For the call-intent model, trees that are too shallow miss patterns in the calls. Trees that are too deep memorize the training calls and fail on new ones.
Tuning also decides which of two models looks better. In a large study of image-generating models known as GANs, Lucic and colleagues found that most could reach similar scores with enough tuning and repeated runs.
How hyperparameter optimization works
A tuning run is a loop. Bischl and colleagues describe it as proposing a configuration, evaluating it and updating the tuning method with the result.
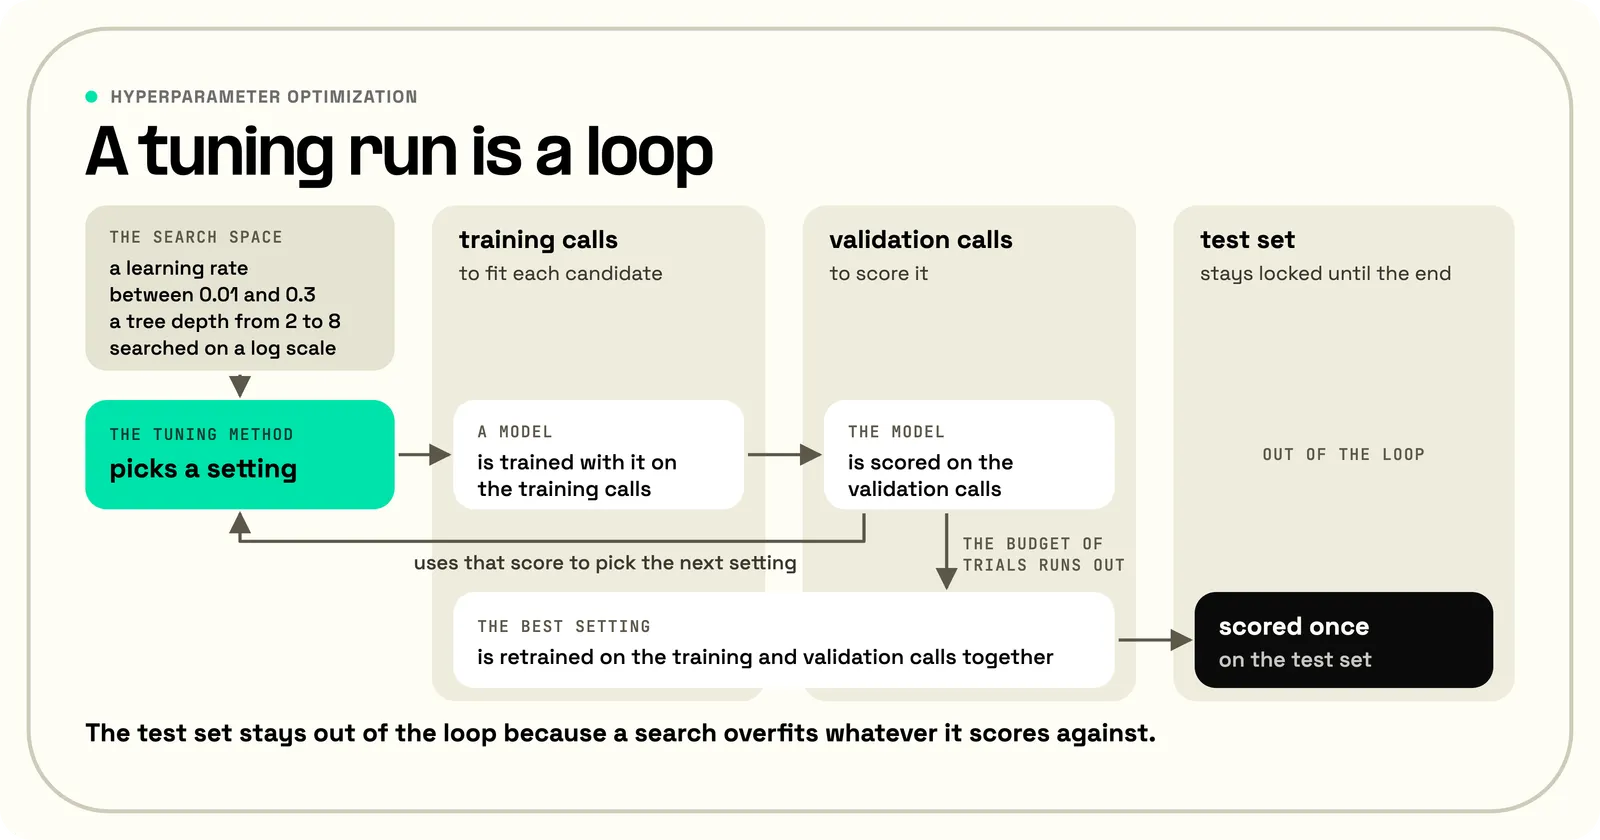
Before the loop starts, the data is split three ways: training calls to fit each candidate, validation calls to score it, and a test set that stays locked until the end. For the call-intent model, one run looks like this:
- The search space lists each hyperparameter and the range it can take: a learning rate between 0.01 and 0.3, and a tree depth from 2 to 8. The learning rate is searched on a log scale, so 0.01 to 0.03 gets as many tries as 0.1 to 0.3.
- A validation metric is chosen, such as accuracy on the validation calls.
- The tuning method picks a setting, a model is trained with it on the training calls, and the model is scored on the validation calls.
- The method uses that score to pick the next setting, and the loop repeats until the budget of trials runs out.
- The best setting is retrained on the training and validation calls together and scored once on the test set.
Instead of one fixed validation split, cross-validation rotates it. Everything except the test set is split into k folds; each candidate trains k times, holding out a different fold each time, and its score is the average.
The test set stays out of the loop because a search overfits whatever it scores against. Picking the best of many settings on one validation set makes that score look better than the model really is.
Nested cross-validation does the same job without a fixed test set: it runs the whole tuning loop inside each fold of an outer cross-validation. Bischl and colleagues recommend it for reporting an unbiased score.
Hyperparameter optimization methods
Tuning methods differ mainly in how they choose the next setting to try. A run that tries many settings is often called a hyperparameter sweep.
Manual search, a person adjusting settings by hand, is still common. Bergstra and Bengio named grid search and manual search as the most widely used strategies.
Grid search
Grid search lists a few values for each hyperparameter and trains a model on every combination. Three learning rates and three tree depths make nine runs.
The number of runs grows exponentially with each hyperparameter added, which Feurer and Hutter call the curse of dimensionality. Five values each for four hyperparameters already means 625 runs.
Random search
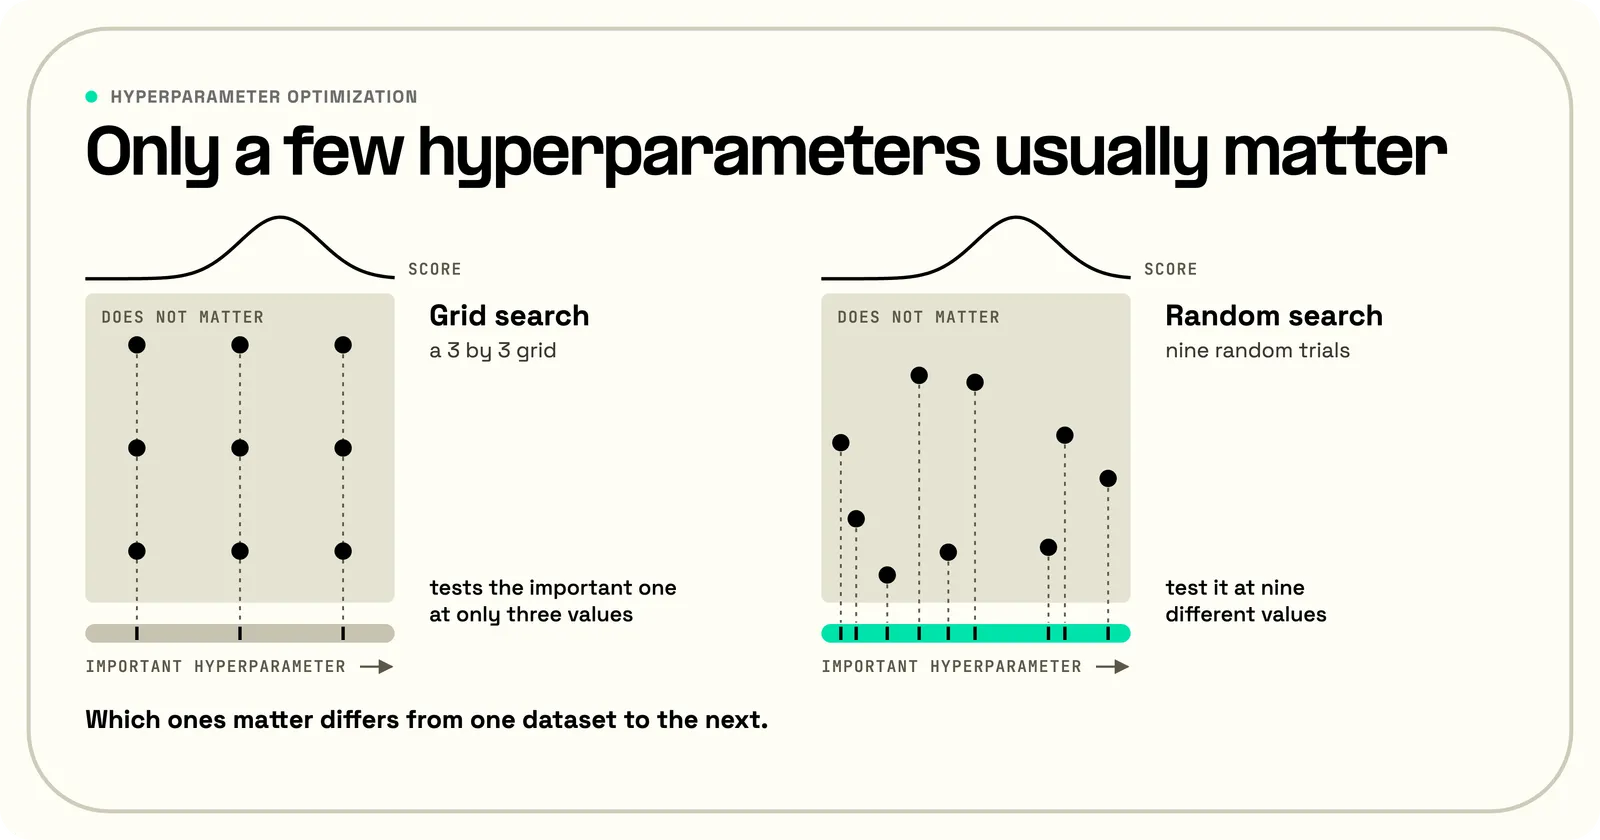
Random search samples each setting from a range instead of a fixed list. In Bergstra and Bengio's tests on neural networks, it found models as good as or better than grid search did, in a small fraction of the computation time.
The reason is that only a few hyperparameters usually matter, and which ones matter differs from one dataset to the next.
With nine trials and one important hyperparameter, a 3 by 3 grid tests the important one at only three values. Nine random trials test it at nine different values.
Bayesian optimization
Bayesian optimization learns from the trials it has already run. It fits a model of how settings relate to scores and uses it to choose the most promising next setting.
Snoek, Larochelle and Adams model performance with a Gaussian process, which predicts a score for settings not yet tried and how uncertain that prediction is.
The next trial goes where the predicted score is good or the uncertainty is high, balancing settings known to work against ones not yet explored. With careful choices, Snoek and colleagues showed, this can exceed expert-level tuning.
The tree-structured Parzen estimator (TPE) instead splits past trials into good and bad scores and picks settings that look like the good group. It is the default method in Optuna.
SMAC, another common method, uses random forests in place of a Gaussian process.
Feurer and Hutter note that guided methods like these usually outperform random search.
Early stopping and Hyperband
Early stopping here means dropping a candidate setting partway through, not the rule that ends one training run when validation loss stops improving. Many settings look bad early, so there is no need to train them to the end.
Methods that judge settings on cheap, partial training like this are called multi-fidelity methods.
Successive halving gives every candidate the same small budget, drops the worse half and repeats with the rest. With 64 settings, each gets one training round; the best 32 get two rounds, the best 16 get four, and so on until one remains.
Successive halving has to guess how much training a setting needs before its quality shows. Too little, and slow starters are dropped; too much, and few settings get tried.
Hyperband runs successive halving at several starting budgets to cover both cases. Li and colleagues report over an order-of-magnitude speedup over popular Bayesian optimization methods on deep learning and kernel-based problems.
Population-based training
Population-based training tunes while it trains. A population of models trains in parallel.
From time to time, a weak model copies the weights and hyperparameters of a stronger one. It then changes the hyperparameters slightly and keeps training.
The result is a schedule of hyperparameter settings rather than one fixed set for the whole run.
Hyperparameter tuning tools
Libraries run the tuning loop, so the code mostly defines the search space and the score. In scikit-learn, the run from the steps above fits in a short script. Its built-in breast cancer dataset (569 examples) stands in for call data here:
RandomizedSearchCV tried 20 settings, scoring each with 5-fold cross-validation on the 455 examples outside the test set. It picked a learning rate of 0.142 and a tree depth of 8, with a cross-validation accuracy of 0.974.
On the 114 test examples it never saw, the tuned model scored 0.956, and that is the number to report. The 0.974 was the best of 20 scores, so it can run high, though one run cannot show by how much.
- scikit-learn also has GridSearchCV, which tries every combination of the values it is given, and halving versions of both tools that apply successive halving.
- Optuna lets each trial pick its hyperparameters as it runs, so one choice can depend on another, and it stops unpromising trials early, which its authors call pruning.
- Optuna also offers a web dashboard for following a study's trials as they run.
- Hyperopt implements random search and TPE.
- Keras Tuner comes with Bayesian optimization, Hyperband and random search built in, for models written in Keras.
- Ray Tune runs tuning jobs across many machines and includes population-based training and Hyperband.
AutoML frameworks go further, treating the choice of algorithm as one more hyperparameter and searching over it along with the rest.
Challenges of hyperparameter optimization
Cost comes first, because every trial is a training run. Feurer and Hutter note that each evaluation can be extremely expensive for large models, such as in deep learning.
The search space needs care. Bischl and colleagues recommend a logarithmic scale for many hyperparameters, because the ratio often matters: a learning rate moving from 0.01 to 0.02 doubles, while 0.28 to 0.29 barely changes.
Scores are noisy. The same setting can score differently with another random seed or data split. After many trials, a search can pick a setting that only looked best by chance, an effect Bischl and colleagues describe as overtuning.
What is known about the problem narrows the search, and a search space copied from another task can waste trials.
Hyperparameter tuning vs model training vs fine-tuning
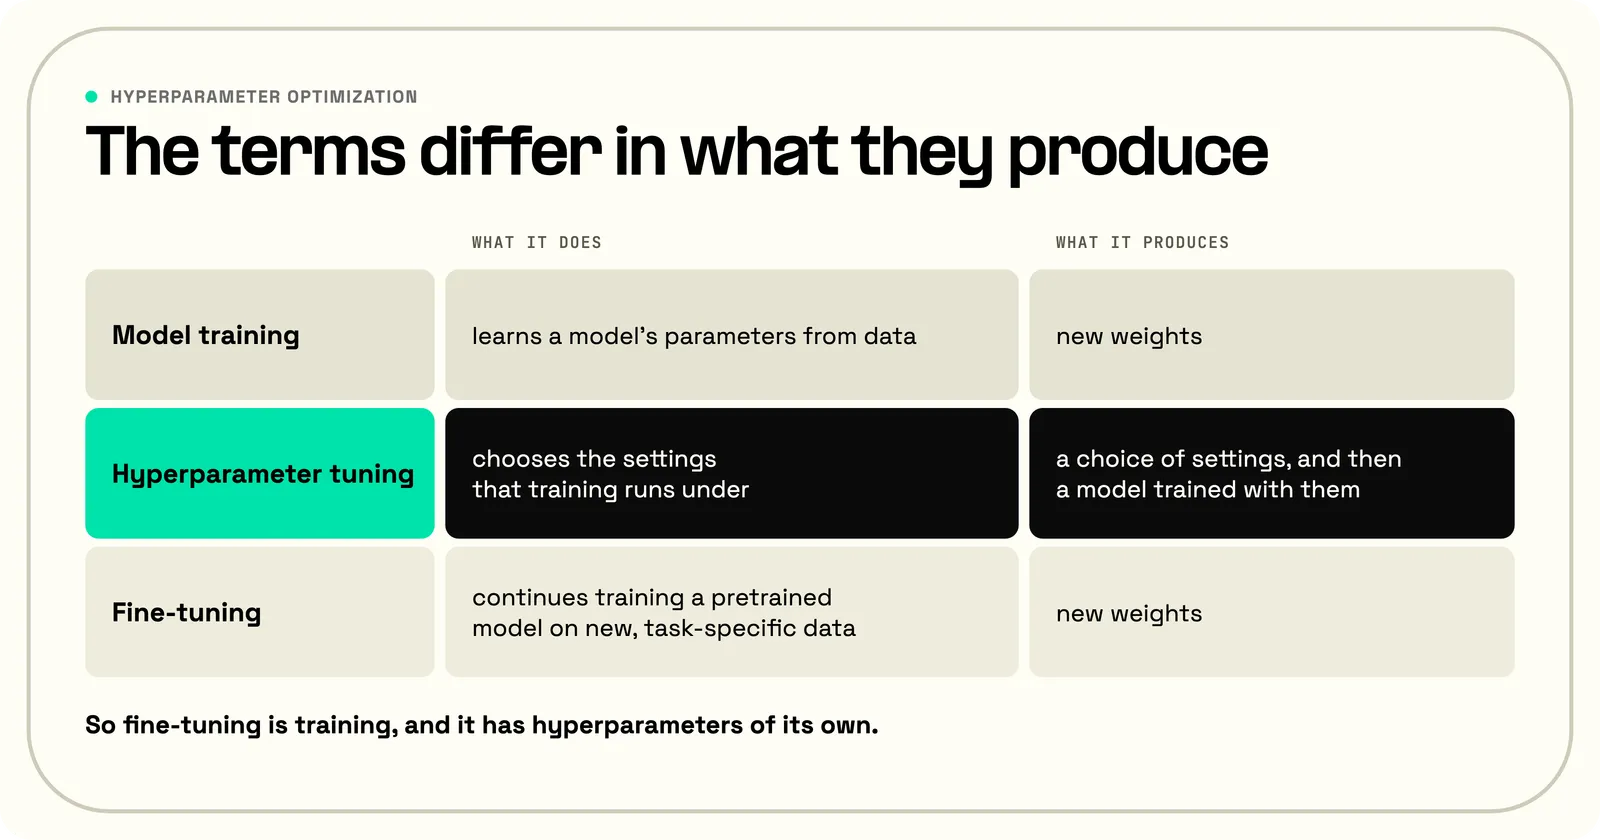
Training, tuning and fine-tuning sound alike but change different things. Training learns a model's parameters from data, and tuning chooses the settings that training runs under.
Fine-tuning continues training a pretrained model on new, task-specific data. So fine-tuning is training, and it has hyperparameters of its own, such as the learning rate and the number of epochs.
Fine-tuning methods can add settings too. LoRA trains small add-on matrices instead of all the weights, and the size of those matrices, set by their rank, is a hyperparameter.
The terms also differ in what they produce. Training and fine-tuning produce new weights. Tuning produces a choice of settings, and then a model trained with them.
Hyperparameters in LLMs and voice AI agents
A large language model has two kinds of settings, and only one kind changes its weights.
Training and fine-tuning hyperparameters, such as the learning rate and the number of epochs, shape the weights. Generation settings, such as temperature, are chosen for each request and leave the weights alone.
Generation settings are often called hyperparameters too, but no training run sets them. Teams choose them by testing outputs, the same tuning loop run on a fixed model.
On Telnyx, the Fine-tuning API trains a model on a dataset and takes one hyperparameter, the number of epochs, which defaults to 3.
The chat completions endpoint takes generation settings with each request, including temperature (default 0.1), a top-p cutoff and a seed for repeatable sampling.
The top-p cutoff samples only from the most likely next words, up to a set share of the total probability.
For a voice AI agent, the loop does not change. A fine-tuned model is scored on held-out calls before it takes live ones, like the evaluation run MLOps pipelines attach to every retraining.
A team running its own call-intent model can get the call audio it needs from the Voice API over WebSockets, through media streaming.
Frequently asked questions
What is GridSearchCV used for?
GridSearchCV is scikit-learn's grid search tool. It trains a model on every combination of the values it is given, scores each with cross-validation and keeps the best. It fits small searches with a few values per hyperparameter.
Which is better, GridSearchCV or RandomizedSearchCV?
RandomizedSearchCV is usually the better start when there are several hyperparameters. Its budget does not grow with their number. Per scikit-learn's guide, adding ones that do not matter does not reduce its efficiency.
Is 0.01 a good learning rate?
It can be, but no single value suits every model. The Adam optimizer suggests 0.001, and scikit-learn's guide recommends 0.1 or lower for gradient boosting. Random searches typically sample it on a log scale.
Does more parameters mean better AI?
Not on its own. More parameters help only with enough training data. Hoffmann and colleagues found that a 70-billion-parameter model trained on four times more data beat a 280-billion-parameter one on the same compute.
Why is it called a hyperparameter?
The word comes from Bayesian statistics. In Bayesian Data Analysis, Gelman and colleagues write that the parameters of a prior distribution are often called hyperparameters, one level above the model's own parameters.
Sources
- Bergstra, J., and Bengio, Y. (2012). Random search for hyper-parameter optimization. Journal of Machine Learning Research, 13, 281-305.
- Snoek, J., Larochelle, H., and Adams, R. P. (2012). Practical Bayesian optimization of machine learning algorithms. NeurIPS 2012.
- Li, L., Jamieson, K., DeSalvo, G., Rostamizadeh, A., and Talwalkar, A. (2018). Hyperband: a novel bandit-based approach to hyperparameter optimization. Journal of Machine Learning Research, 18.
- Jaderberg, M., et al. (2017). Population based training of neural networks.
- Feurer, M., and Hutter, F. (2019). Hyperparameter optimization. In Automated Machine Learning: Methods, Systems, Challenges. Springer.
- Bischl, B., et al. (2023). Hyperparameter optimization: foundations, algorithms, best practices, and open challenges. WIREs Data Mining and Knowledge Discovery.
- Akiba, T., Sano, S., Yanase, T., Ohta, T., and Koyama, M. (2019). Optuna: a next-generation hyperparameter optimization framework. KDD 2019.
- Melis, G., Dyer, C., and Blunsom, P. (2018). On the state of the art of evaluation in neural language models. ICLR 2018.
- Lucic, M., Kurach, K., Michalski, M., Gelly, S., and Bousquet, O. (2018). Are GANs created equal? A large-scale study. NeurIPS 2018.
- Kingma, D. P., and Ba, J. (2014). Adam: a method for stochastic optimization.
- Bengio, Y. (2012). Practical recommendations for gradient-based training of deep architectures.
- Hu, E. J., et al. (2021). LoRA: low-rank adaptation of large language models.
- Hoffmann, J., et al. (2022). Training compute-optimal large language models.
- Gelman, A., et al. (2013). Bayesian Data Analysis, third edition.
- Hyperopt. Hyperopt documentation.
- Telnyx. Create a fine-tuning job, Create a chat completion and Media streaming. Telnyx developer documentation.
Share on Social
Jump to:
What is hyperparameter optimization?What is a hyperparameter?Why hyperparameter optimization mattersHow hyperparameter optimization worksHyperparameter optimization methodsHyperparameter tuning toolsChallenges of hyperparameter optimizationHyperparameter tuning vs model training vs fine-tuningHyperparameters in LLMs and voice AI agentsFrequently asked questionsSourcesSign up for emails of our latest articles and news
This content was generated with the assistance of AI. Our AI prompt chain workflow is carefully grounded and preferences .gov and .edu citations when available. All content is reviewed by a Telnyx employee to ensure accuracy, relevance, and a high standard of quality.


