Inference
AI DLP Test: Six Data Types, Six Blocks, $0 Charged
AI DLP (AI data loss prevention) stops sensitive data from reaching a language model. We tested Telnyx AI Gateway with 917 live requests. It blocked all six sensitive data types we sent and charged $0 for every block.
What is AI DLP?
AI DLP (AI data loss prevention) stops sensitive data, such as card numbers, API keys and Social Security numbers, from reaching a language model or leaving in its output. It checks each prompt before the provider receives it and each response before your app does, then blocks or flags what it finds.
Where sensitive data enters AI workloads
Once a prompt reaches a model provider, that provider's retention policy applies and you cannot take it back. That is the AI data leakage problem in one sentence. The risk shows up wherever people send text to an LLM:
- Customer support transcripts: callers read card numbers and phone numbers aloud, and the transcript goes to a model for summarization or scoring.
- Internal tools: developers paste config files with API keys into prompts for debugging or code review.
- Document processing: teams send contracts, invoices and intake forms through an LLM for extraction, and those documents carry IBANs, emails and phone numbers.
Any application that sends prompts to a model through Telnyx AI Gateway can run AI DLP checks before the call goes out.
How Telnyx AI Gateway handles AI DLP
Telnyx AI Gateway sits between your application and the models it calls. For every request, it checks the prompt before the model is called and the response before your app receives it.
- Blocking a prompt returns
400 prompt_blockedand charges $0. - Flag lets the prompt through and adds an
x-ltg-policyheader naming what was found. - Detectors cover secrets and data loss prevention: AWS keys, card numbers, IBANs, SSNs, email addresses and phone numbers.
- Logs keep a detector code and a count, never the value itself. No prompts or responses are stored.

We sent 917 live inference requests through the gateway and recorded every result. The run tested AI DLP, budgets, burst spend and key revocation. The DLP results come first, followed by the rest.
AI DLP test: six data types, six blocks, $0 charged
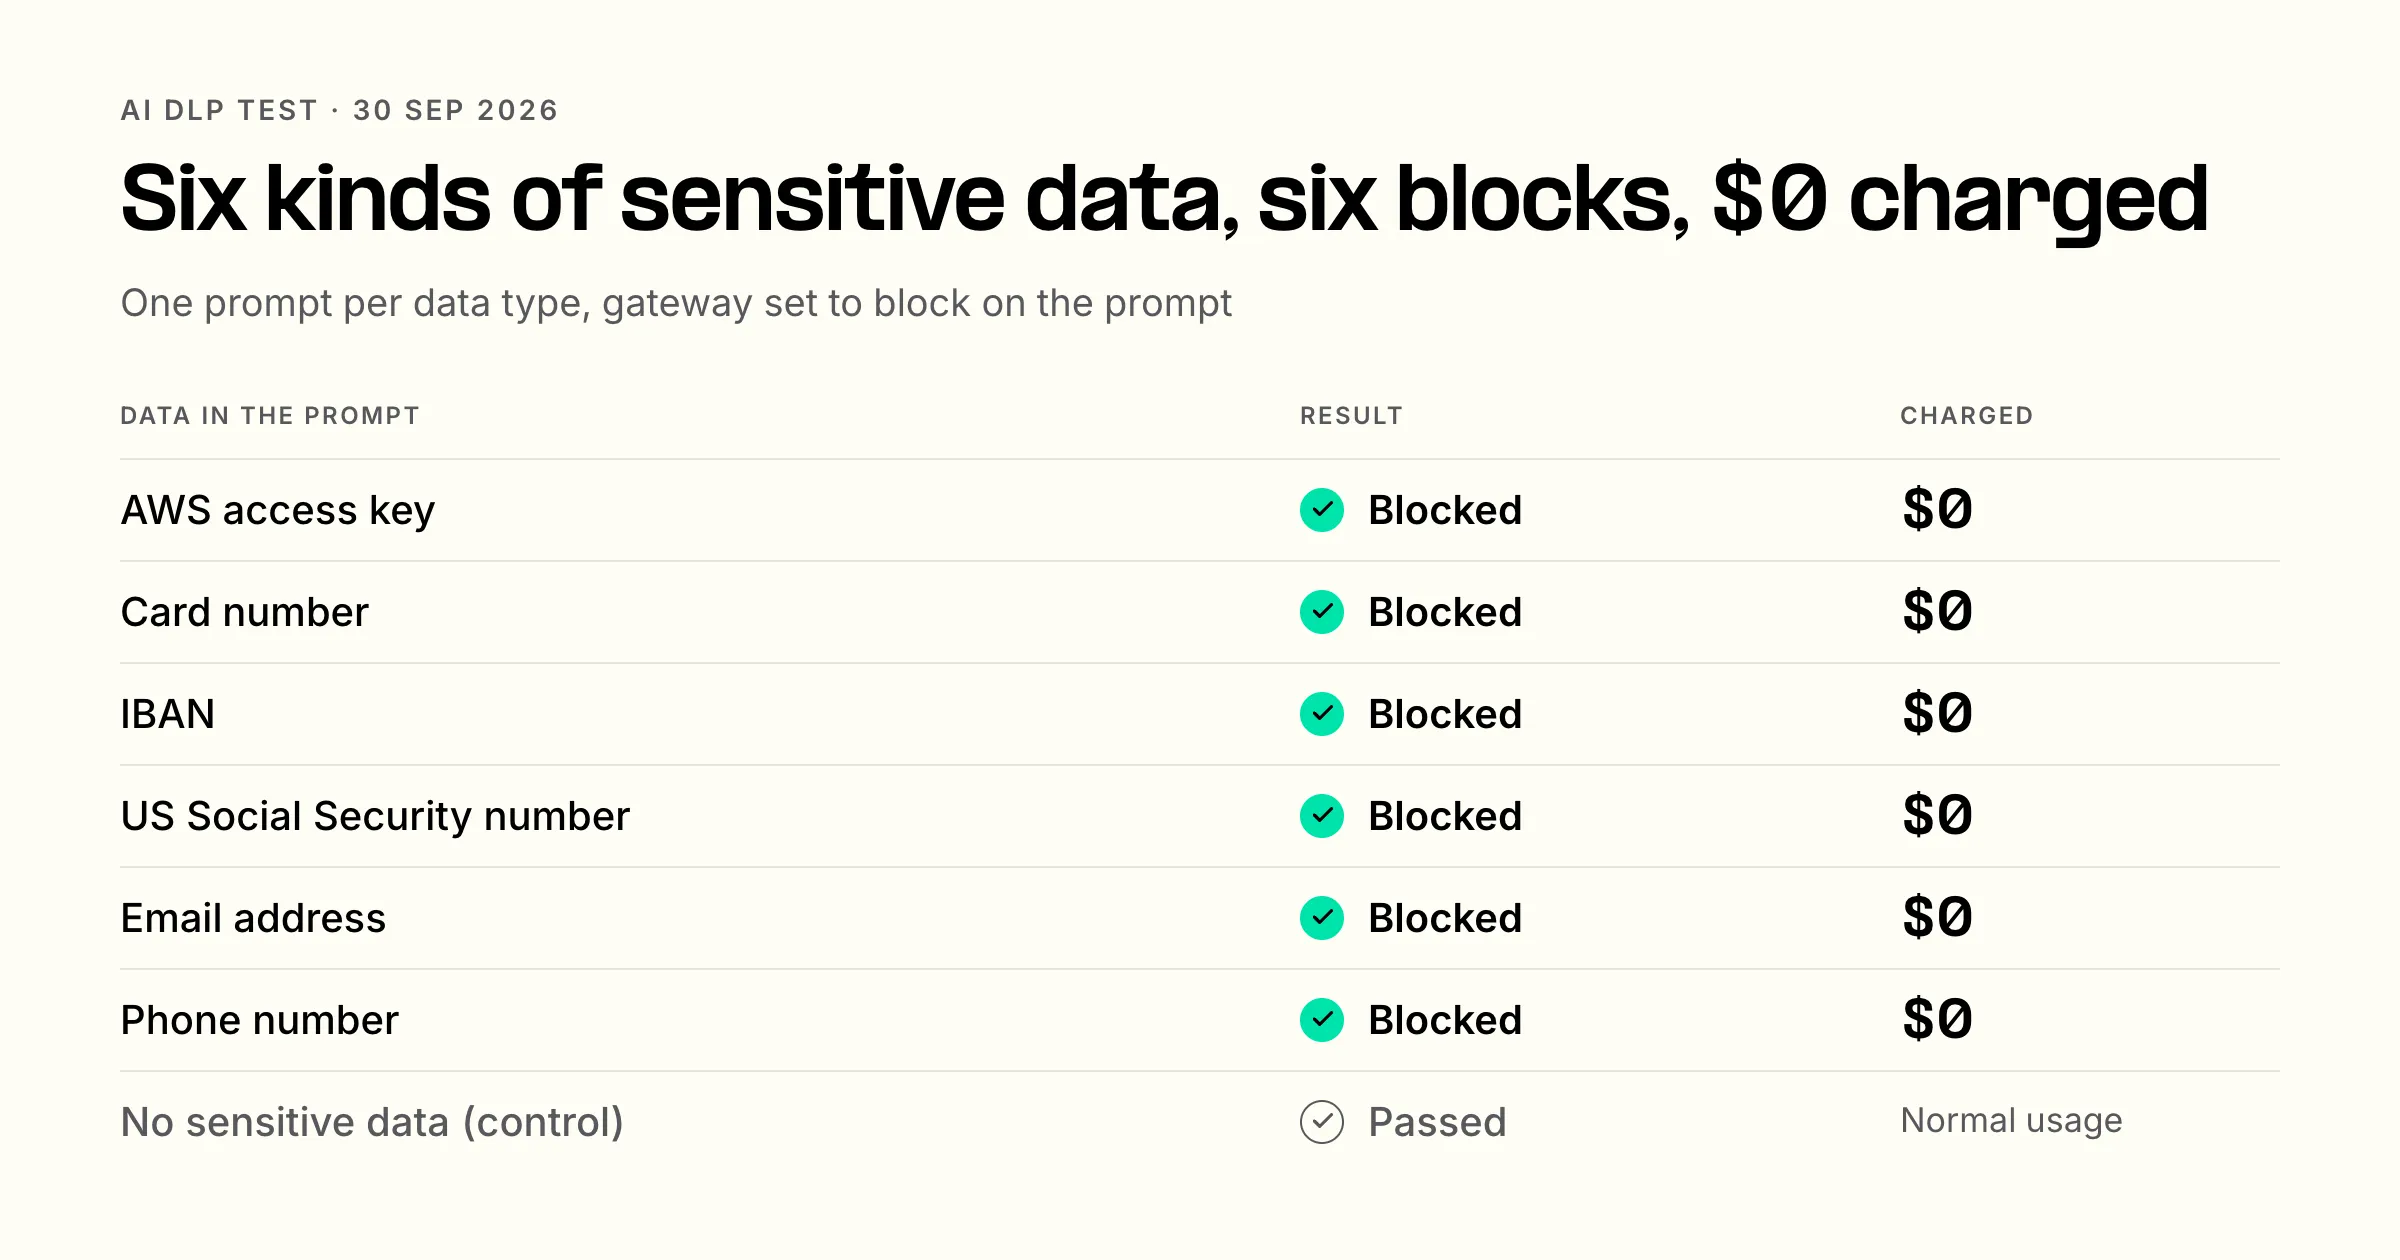
We set a gateway to block secrets and sensitive data in prompts. Then we sent one prompt each containing an AWS access key, a card number, an IBAN, a US Social Security number, an email address and a phone number.
All six were refused with 400 prompt_blocked, and none was charged. A clean control prompt went through normally. Each block was logged as a guardrail event with the right detector: secrets for the AWS key, and dlp for the other five.
With the action switched from block to flag, all six prompts went through. Each response carried an x-ltg-policy header naming what was found.
Two AI DLP edge cases to plan for
- A blocked response is still charged. When we asked the model to repeat an IBAN and a card number back, the gateway withheld the response. The model had already done the work, so the usage was billed.
- A streamed response fails inside a 200. With streaming on, the gateway sends 200 headers, holds the output while it inspects it, then sends an error event in place of the text. No model output reached the client, but your code needs to handle an error after a 200.
AI DLP checks are pattern checks for structured data. They do not detect free text such as names or postal addresses.
What AI DLP logs keep about your prompts
Every gateway keeps records, because budgets and audit trails depend on them. The question is whether those records include what your people typed.
We put a unique marker string in five prompts, three of which also held sensitive data the guardrails flagged. Then we searched every field returned by the gateway's three reporting endpoints: spend events, spend summaries and guardrail events. The marker appeared in none of them, and neither did any prompt or response text.
The records hold IDs, token counts, cost and status. A guardrail finding holds a detector code and a count, so a flagged Social Security number is recorded as us_ssn, count 1, never the digits.

The gateway stores no prompt or response content internally. Telnyx-hosted models run on GPUs we own, including NVIDIA B300s, with zero data retention, so prompts and completions are not kept after the response. Requests sent to your own Anthropic or OpenAI keys follow those providers' policies.
The rest of the test: budgets, bursts and revocation
The same run tested spend controls and key revocation on the live gateway.
| Test | What we did | Result |
|---|---|---|
| Budgets | 25 requests whose worst-case cost exceeded a $0.01 cap, at gateway, key, person and end-user level | All 25 refused before reaching a model, $0 recorded |
| Burst spend | 50 keys firing at once against one gateway capped at $0.02, three trials | Spend never passed the cap (highest $0.0036) |
| Key revocation | Delete a key, then call again straight away, 20 times | Every call refused, median 294 ms |
| Rate limits | A key limited to 2 requests a minute, 6 calls | 2 served, the rest returned 429 with Retry-After |
| Model access | 5 calls to a model outside the gateway's list | All 5 refused with a 403 |
Telnyx's AI Gateway reserves the worst-case cost of a request, the prompt size plus max_tokens, before sending it. An over-budget request is refused with a 403 and never reaches a model, which is why all 25 recorded $0. Set max_tokens on every call, because without it the gateway reserves the model's full output allowance.
In the burst trials, the highest spend was $0.0036 against a $0.02 cap. Each key runs one request at a time by design, and a second simultaneous call on the same key returns 409. That is why the trial used 50 keys under one gateway, which is also how a team or a fleet of agents shares a budget.
A revoked key stopped working fast: the refused call came back a median of 294 ms after the delete, and never later than 383 ms.
How we tested
| Item | Detail |
|---|---|
| Date | 30 September 2026, 12:10 to 17:26 UTC |
| Model | DeepSeek-V4.1-Flash, Telnyx-hosted, one US region |
| Volume | 917 inference requests and 29 management calls |
| Not tested | Bring-your-own-key models (Anthropic, OpenAI) |
| Clean-up | Every test gateway, key, person and end user deleted afterwards |
Turn on AI DLP in Telnyx AI Gateway
Create a gateway for a team, choose its models, set its budget and rate limits, turn on guardrails, then give each person a key scoped to the models they need. The AI Gateway docs walk through every setting via API or you can get started in the Mission Control Portal. AI Gateway is free, You pay only for inference on open-source models that are hosted on Telnyx-owned B300 GPU clusters.
Share on Social
Fiona McDonnell is Product Marketing Lead at Telnyx. Rather than writing about AI infrastructure and messaging compliance from the outside, she's run go-to-market directly for Telnyx's inference products and its trust-focused messaging and voice capabilities. That means she's see


