Author
Eli Mogul
Content Writer & Editor
Eli is the content writer and editor at Telnyx. Born and raised in Chicago, Eli attended the University of Missouri where he obtained a BA in Journalism. Eli joined Telnyx in August of 2025. In his spare time, you'll find Eli reading, playing video games, or running.
- 65
- Articles
- 2023
- Joined
Latest articles
Page 1 of 2 · 65 articles, most recent first.
 Email API
Dedicated IP vs shared IP: which one your email sends need
Shared or dedicated email IP? How to tell if your volume justifies one, and how to warm it up safely.
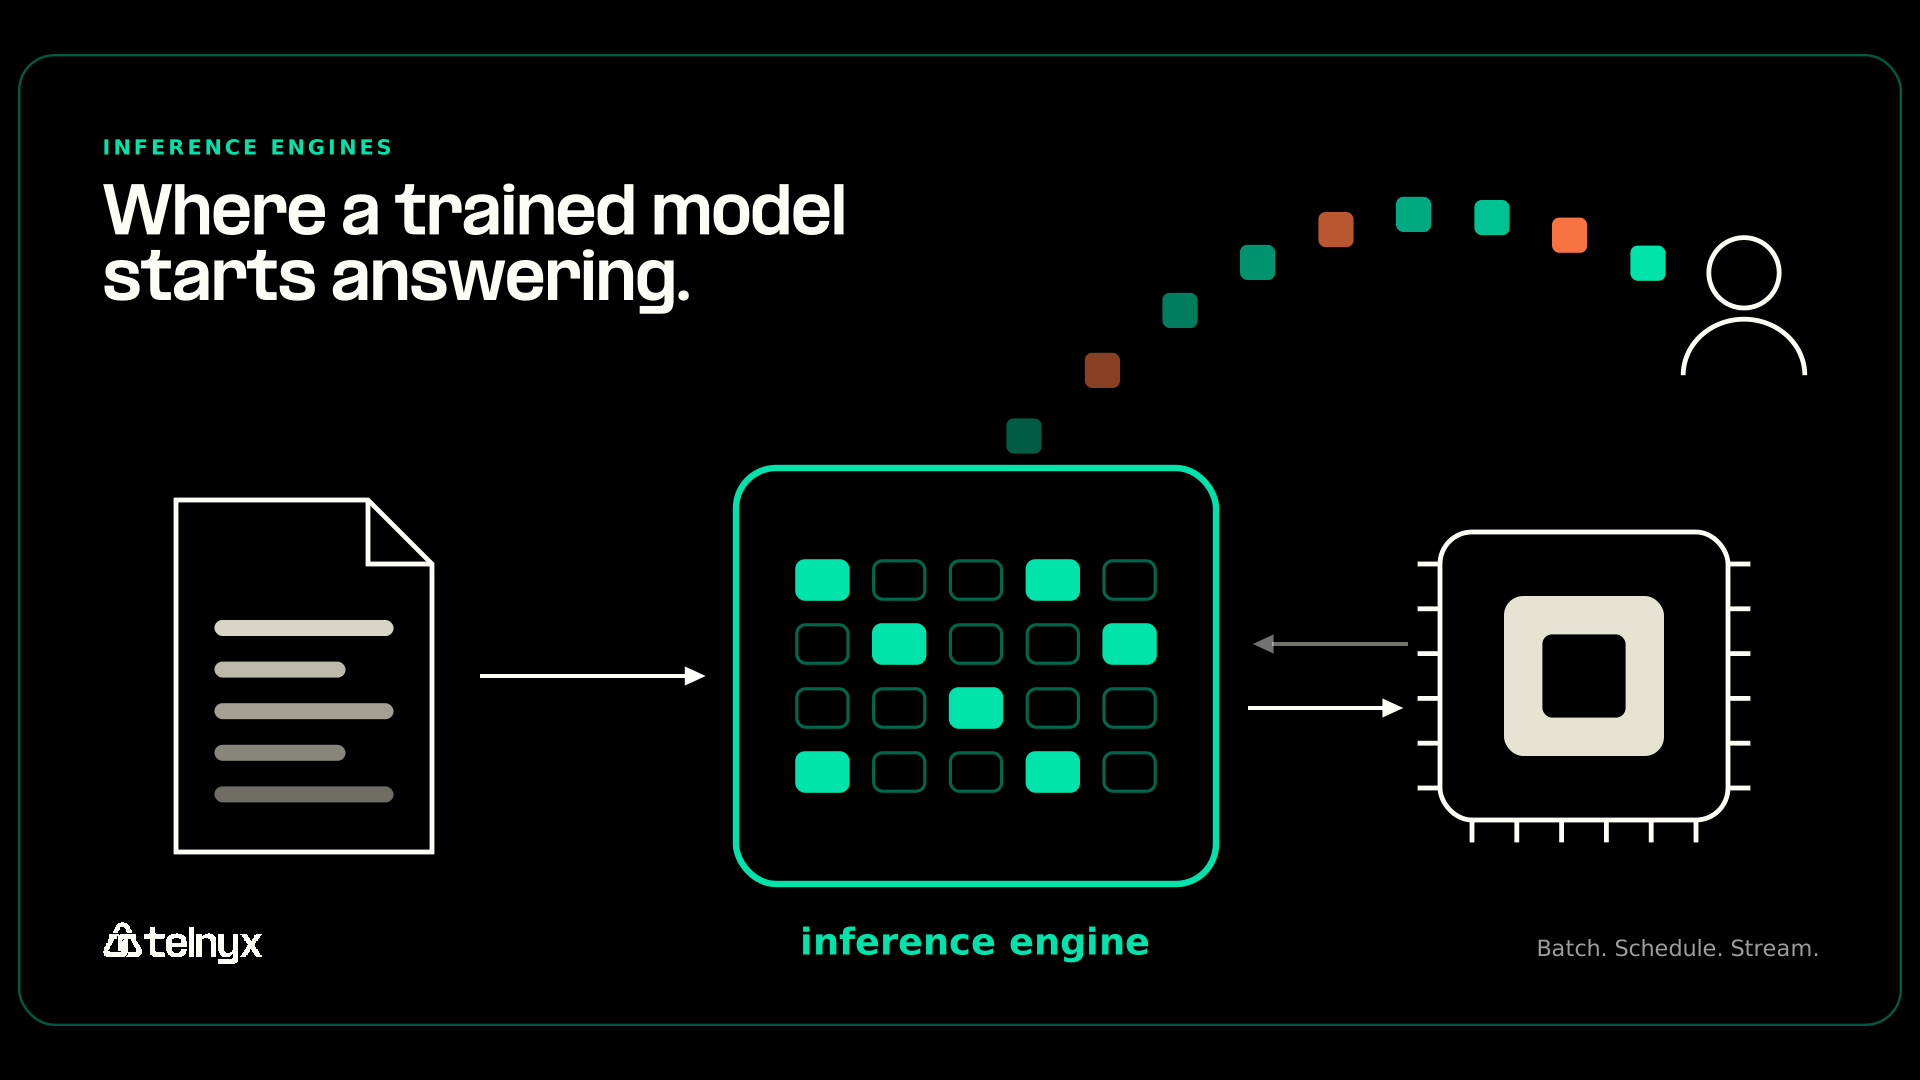 Inference
What is an inference engine? Types and uses
An inference engine is the software component of an AI system that applies logical rules or trained models to data to produce conclusions, decisions, or predictions. Learn how they work and where they are used.
 Inference
What is vLLM? The open-source LLM serving engine, explained
vLLM is an open-source engine that serves LLMs on your own GPUs. See how it works, what it runs on, how it compares, and when a hosted API fits better.
 Inference
LLM inference: how it works, from prefill to decode
What happens between sending a prompt and getting a reply, and why long documents, big contexts, and distant GPUs make you wait.
 Inference
Machine learning inference: how trained models make predictions in production
Machine learning inference is the moment a trained model starts working for you. See what it produces, how to serve it, and when you need a GPU.
 Inference
Top AI inference platforms: how to evaluate providers on real cost
Six checks to predict your inference bill and latency, plus how the top AI inference platforms compare on pricing.
 Inference
What is an inference pipeline? Stages, types, and examples
An inference pipeline is everything that happens around your model before its answer reaches a user. Here’s how each stage works.
 Inference
Time to first token (TTFT): what it measures and how to reduce it
Your dashboard says 300 ms, but users still wait. Here’s what time to first token really measures, how to time it yourself, and the fixes that bring it down.
 Product
WhatsApp banking: what SBI offers, what it costs, how to build it
What SBI’s live WhatsApp banking service offers, what each message costs a bank, and how to run alerts, OTPs, and AI on one Telnyx number.
 Telnyx
Inference benchmarks: which numbers predict latency on your traffic
Inference benchmarks only predict your latency when they match your traffic. Learn which metric fits your workload, then run your own tail-latency check in an afternoon.
 Telnyx
IoT network security: keep your device fleet off the public internet
Your IoT devices can’t defend themselves, so here’s how to protect them from the network side and keep them off the public internet.
 Inference
 cost explained: why your AI bill rises as prices fall
Token prices fell 280-fold, yet AI bills keep rising. Learn what drives inference cost and five steps to cut it by up to 75%.
 Inference
Open weight models: what they are and how to use them
Learn how open weight models differ from open source, which lead in 2026, and how to run them on your terms.
- IoT
Securing IoT devices from the SIM up: a guide for fleet owners
Securing IoT devices starts with one rule: no device should be reachable from the public internet. The five controls, in order, and what they cost.
 Wireless
IoT hacking: how devices get breached and how to stop it
IoT hacking usually starts with a public IP and a default password. See how attackers take over connected devices and how to lock down a cellular fleet.
 Networking
AI data residency vs sovereign AI: what to check in vendors
AI data residency is more than where files sit. See what to ask vendors about transcripts, inference, and logs before you buy.
 Inference
 as a service: how it works and what it costs
Inference as a service wraps that serving layer in a managed product. Rather than standing up an inference engine, provisioning GPUs...
 Inference
AI inference hardware: How to choose chips and placement
Rank inference chips by bandwidth and VRAM per dollar, then decide what to own, rent, or run on GPUs in your users’ region.
 Inference
 optimization: cut LLM latency and cost
Learn which inference optimization techniques cut LLM latency and cost per token, from quantization and KV cache paging to continuous batching.
 Inference
Real-time voice inference: where every millisecond goes on a live call
Real-time voice inference starts at the carrier. Trace every hop in a caller’s wait and find the one to cut first.
 Inference
Edge inference: where to run AI models for low latency
Where your model runs sets how fast your agent can answer. Compare device, on-prem, network edge, and cloud inference for real-time AI.
 Inference
Open Source vs Frontier Models: Which Should Your Agents Run On?
GLM-5.3 output costs $4.00 per million tokens. GPT-6 Astra costs $50.00. Here's where open-weight models already match frontier models for agents, where closed models still win, and how to route between them.
 Insights and Resources
B300 GPU rental price per hour in 2026: what you actually pay
B300 GPU rental costs $7.10 to $17.80 per hour in 2026. Here's what each provider charges and when paying per token beats renting.
 Telnyx
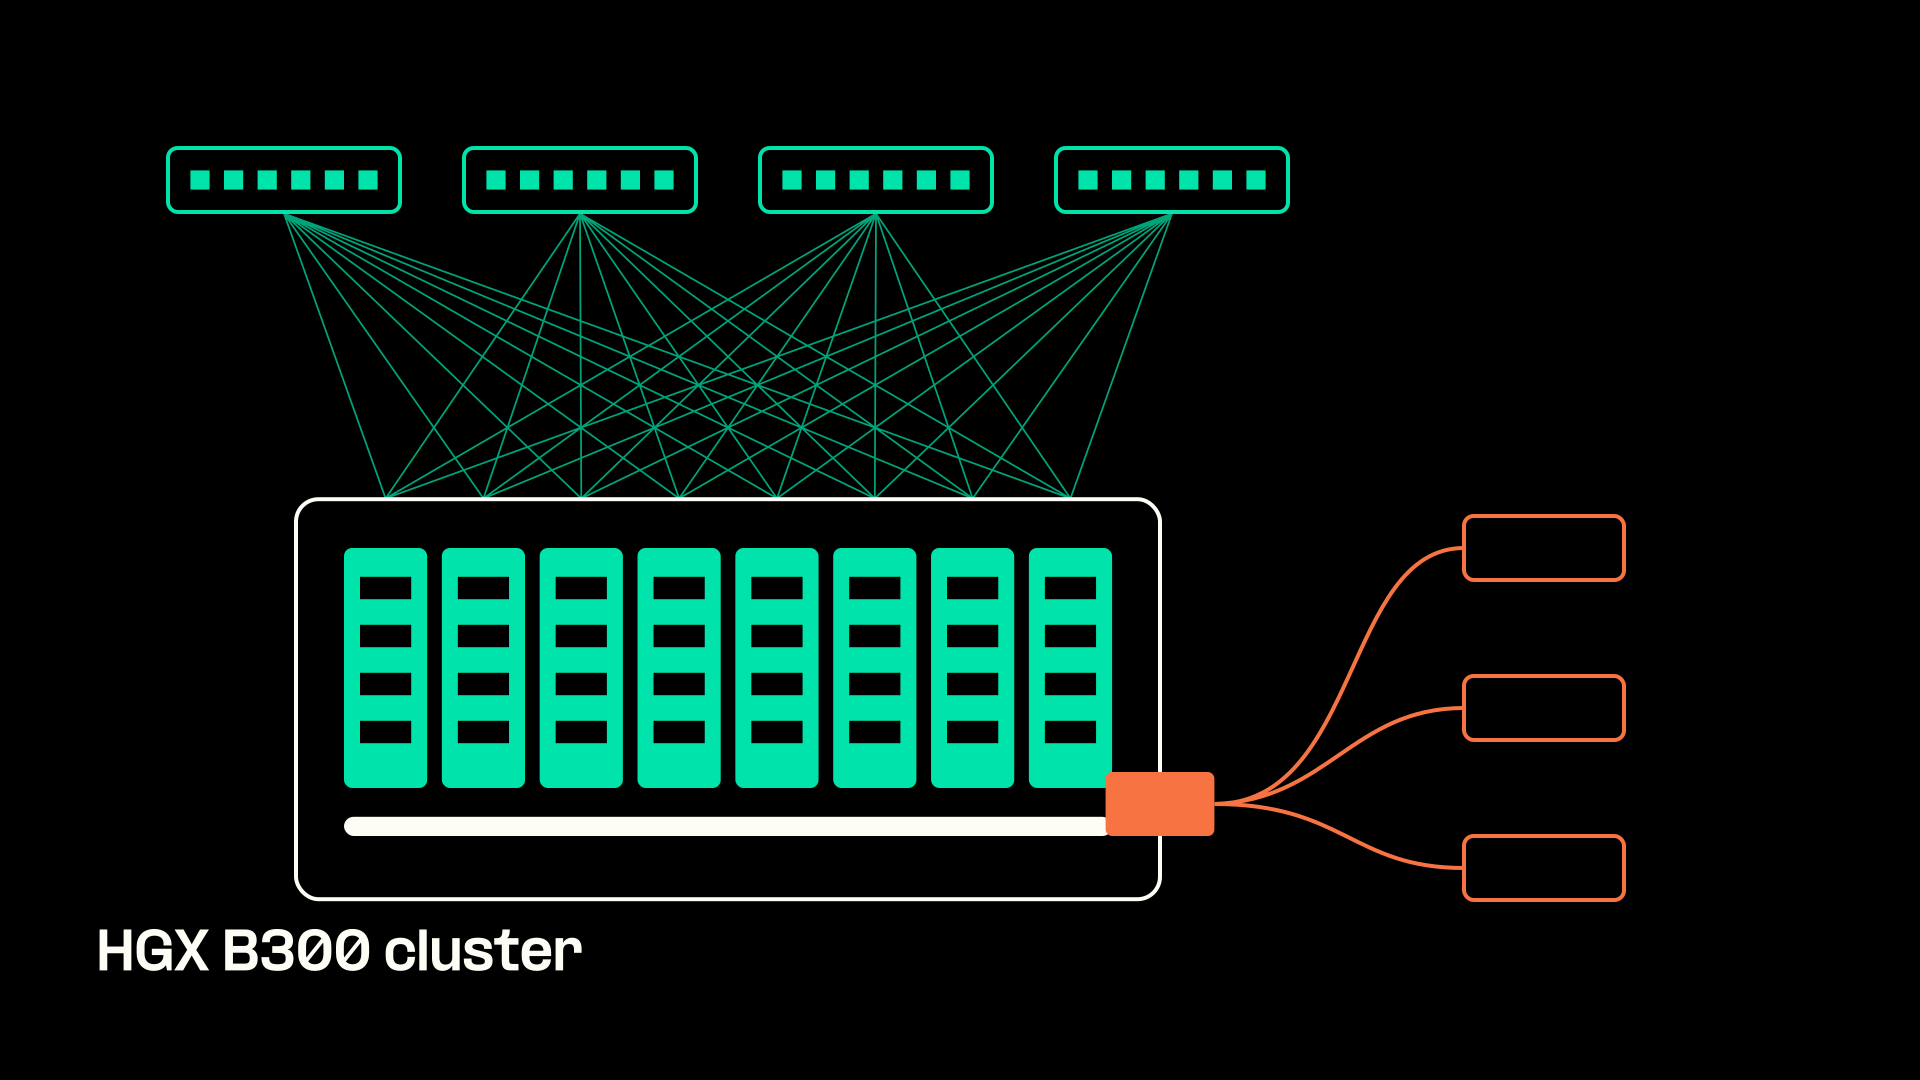
HGX B300 cluster sizing: the node, network and control plane numbers
Every number you need to size an HGX B300 cluster, from 288 GB GPUs to control plane nodes, plus why vendor spec sheets disagree on the same board.
 Inference
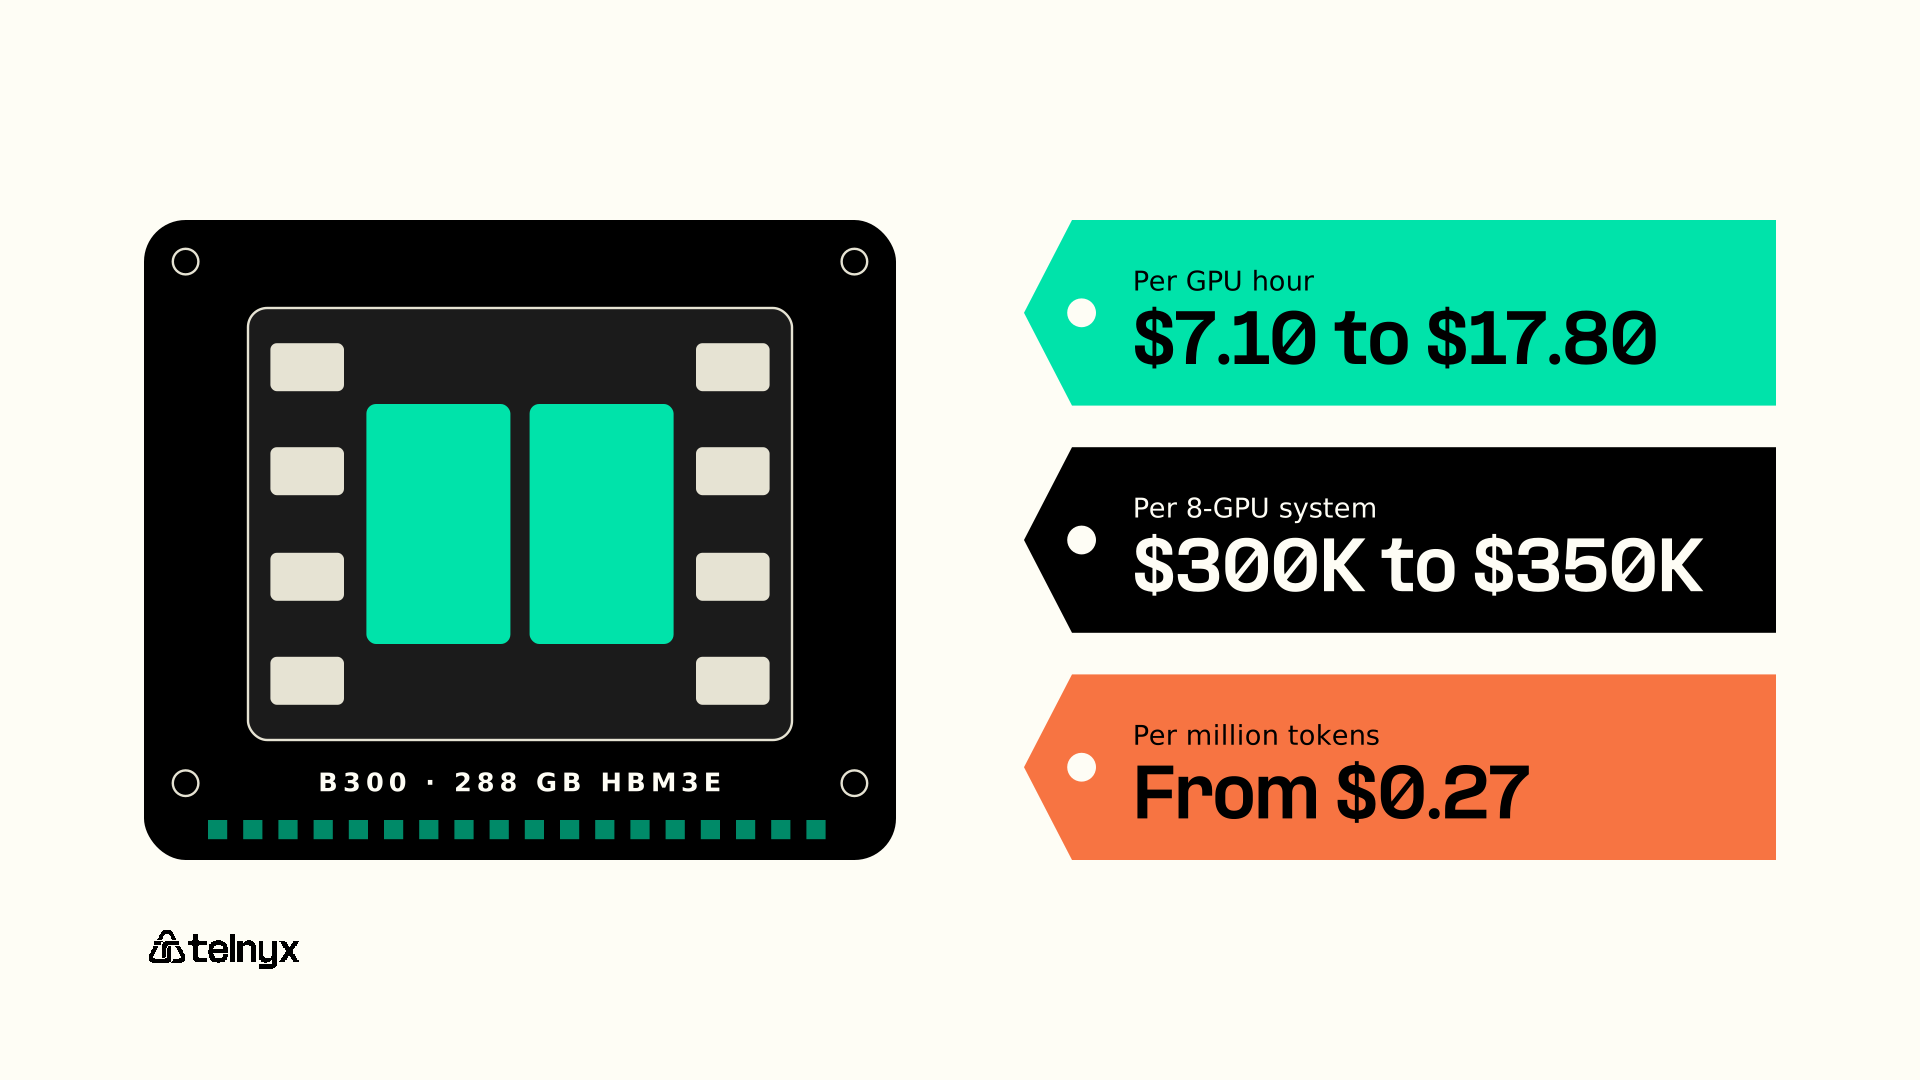
NVIDIA B300 pricing in 2026: per hour, per system and per token
B300 pricing runs $7.10 to $17.80 per GPU hour. Here's when the extra memory pays off, and when per-token pricing costs less.
 Inference
 Infrastructure: What to Run Where and Why It Matters
Hosted API, hyperscaler GPUs, or bare metal? Compare the three ways to run AI inference, see where latency comes from, and pay for speed only where it earns revenue.
 Voice
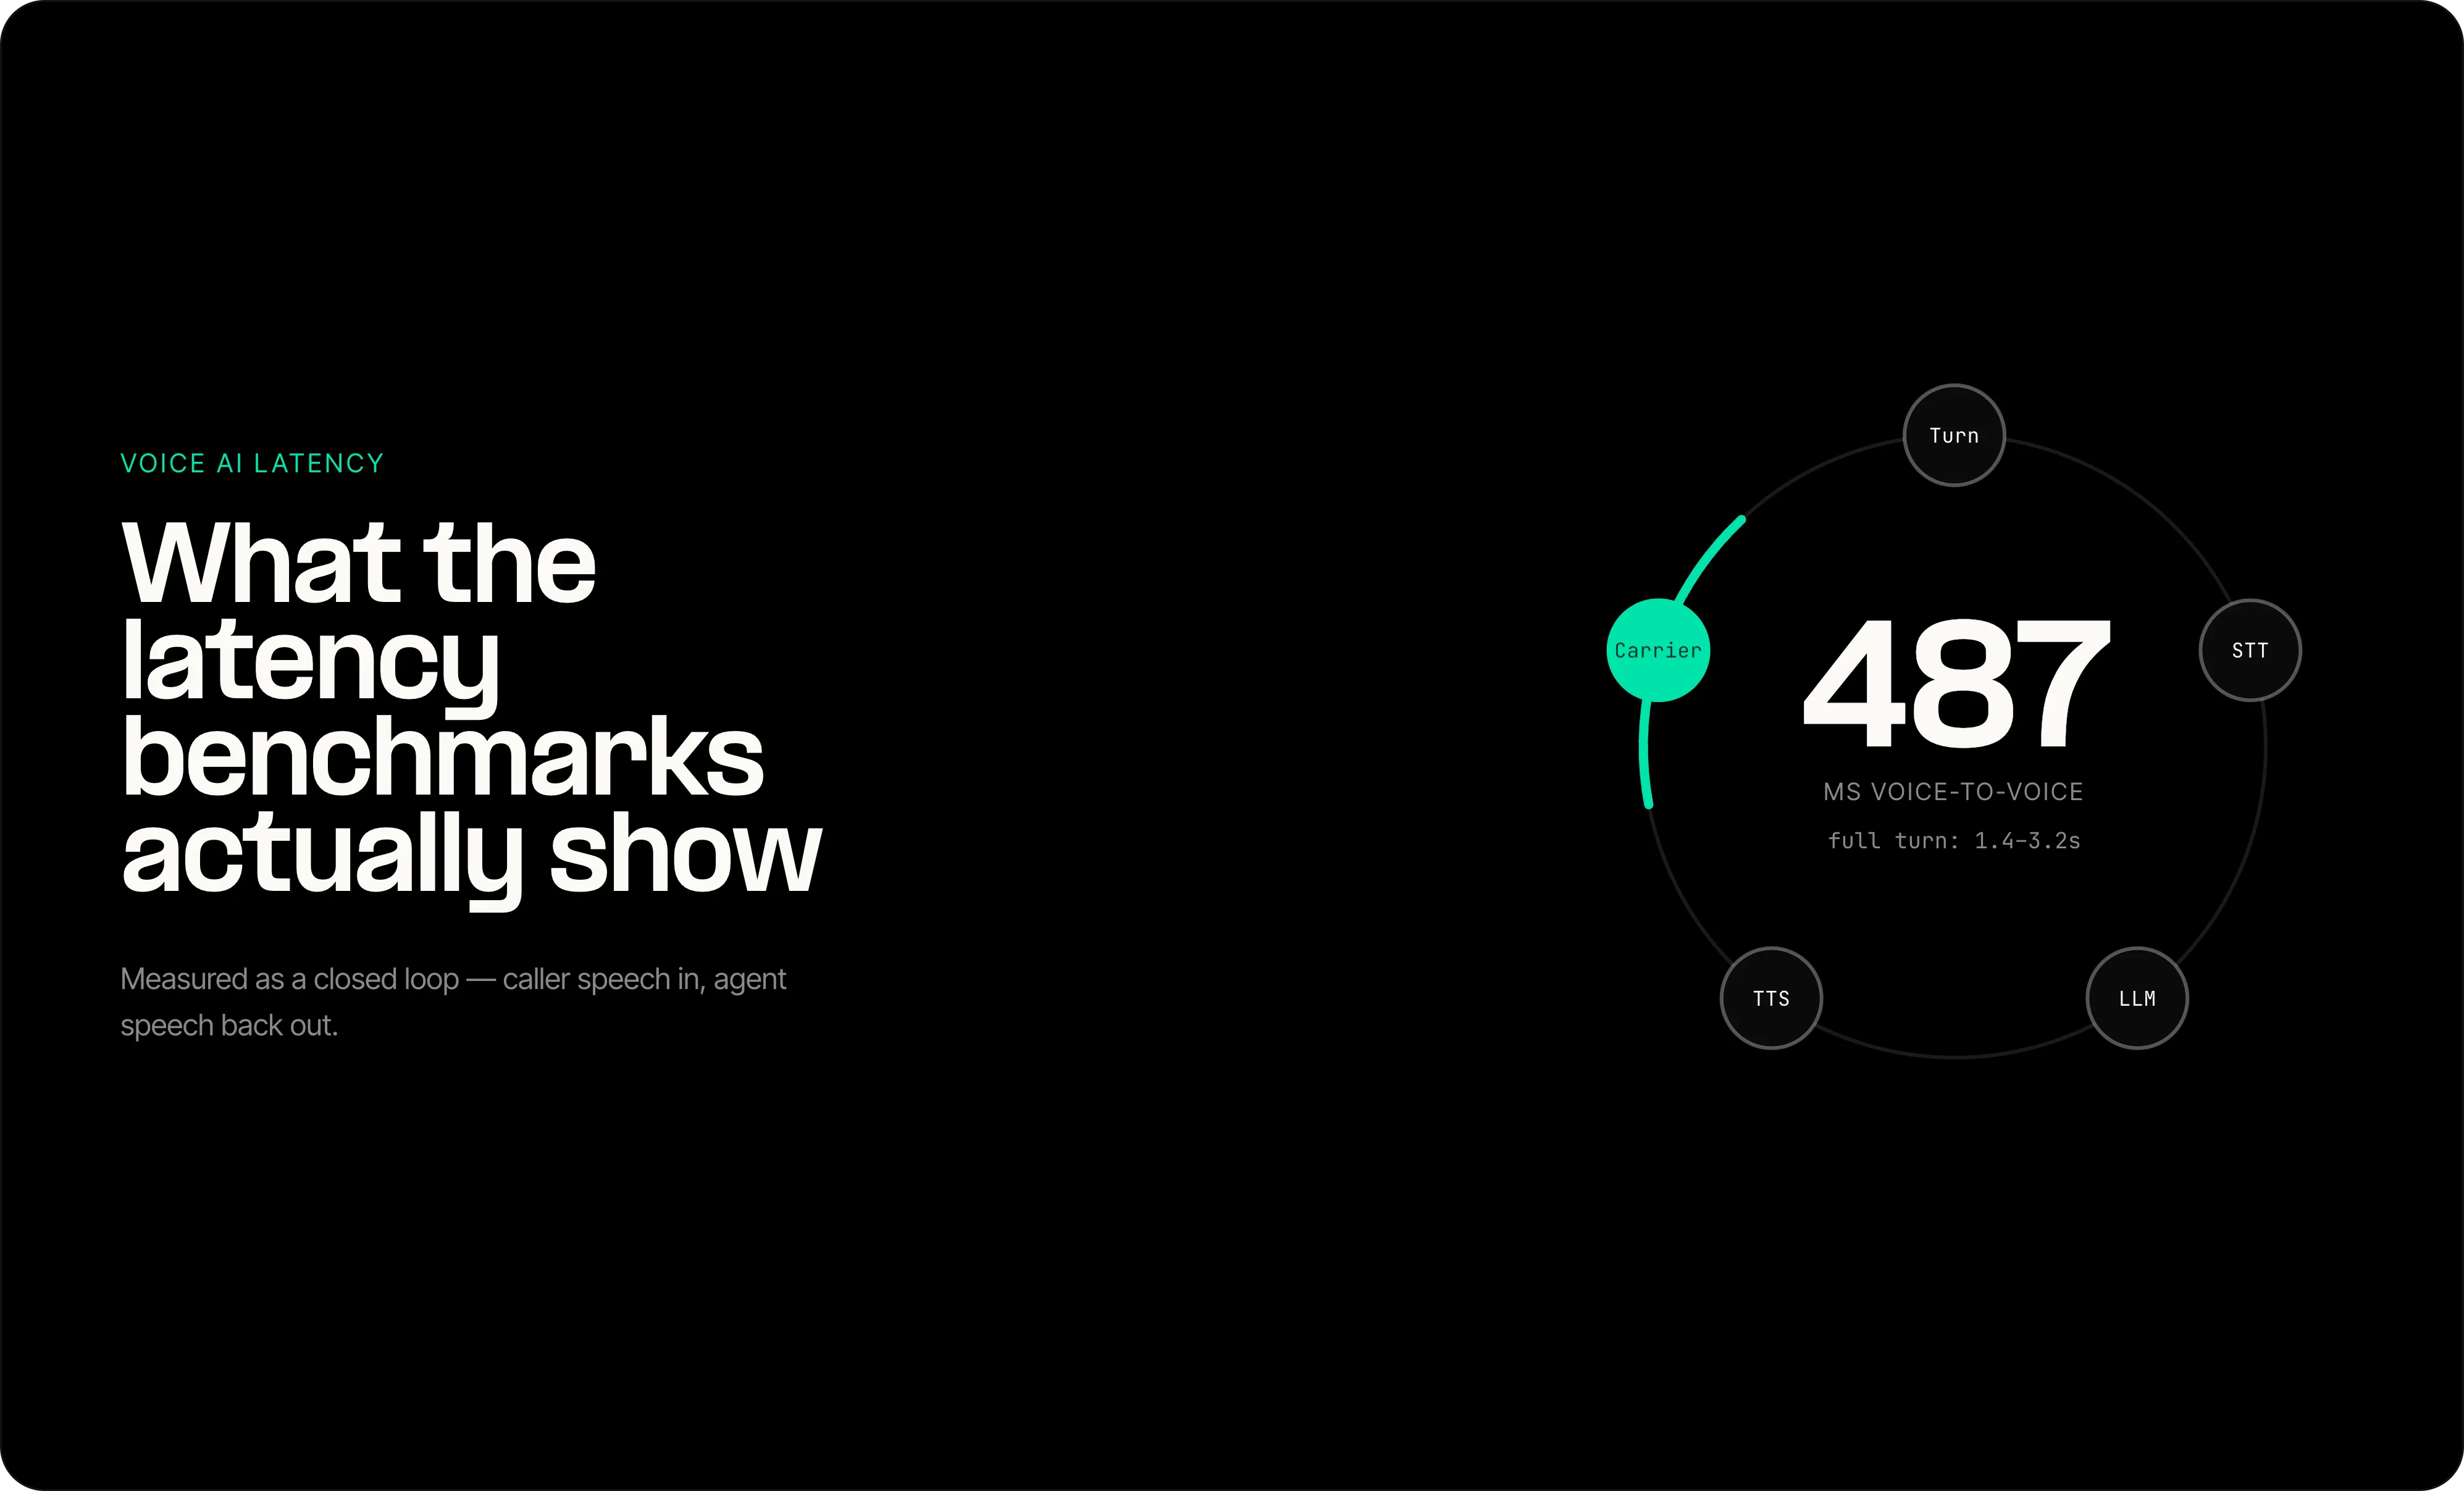
Voice AI Agents Compared on Latency: 2026 Benchmarks
Telnyx had the lowest median latency of five voice AI platforms in a caller-side test over real phone calls. Here's how six platforms compare across four third-party benchmarks.
 Voice
VoIP infrastructure explained: find the layer behind every bad call
Bad call quality starts in one of seven VoIP infrastructure layers. See what each one does and where calls break.
 Insights and Resources
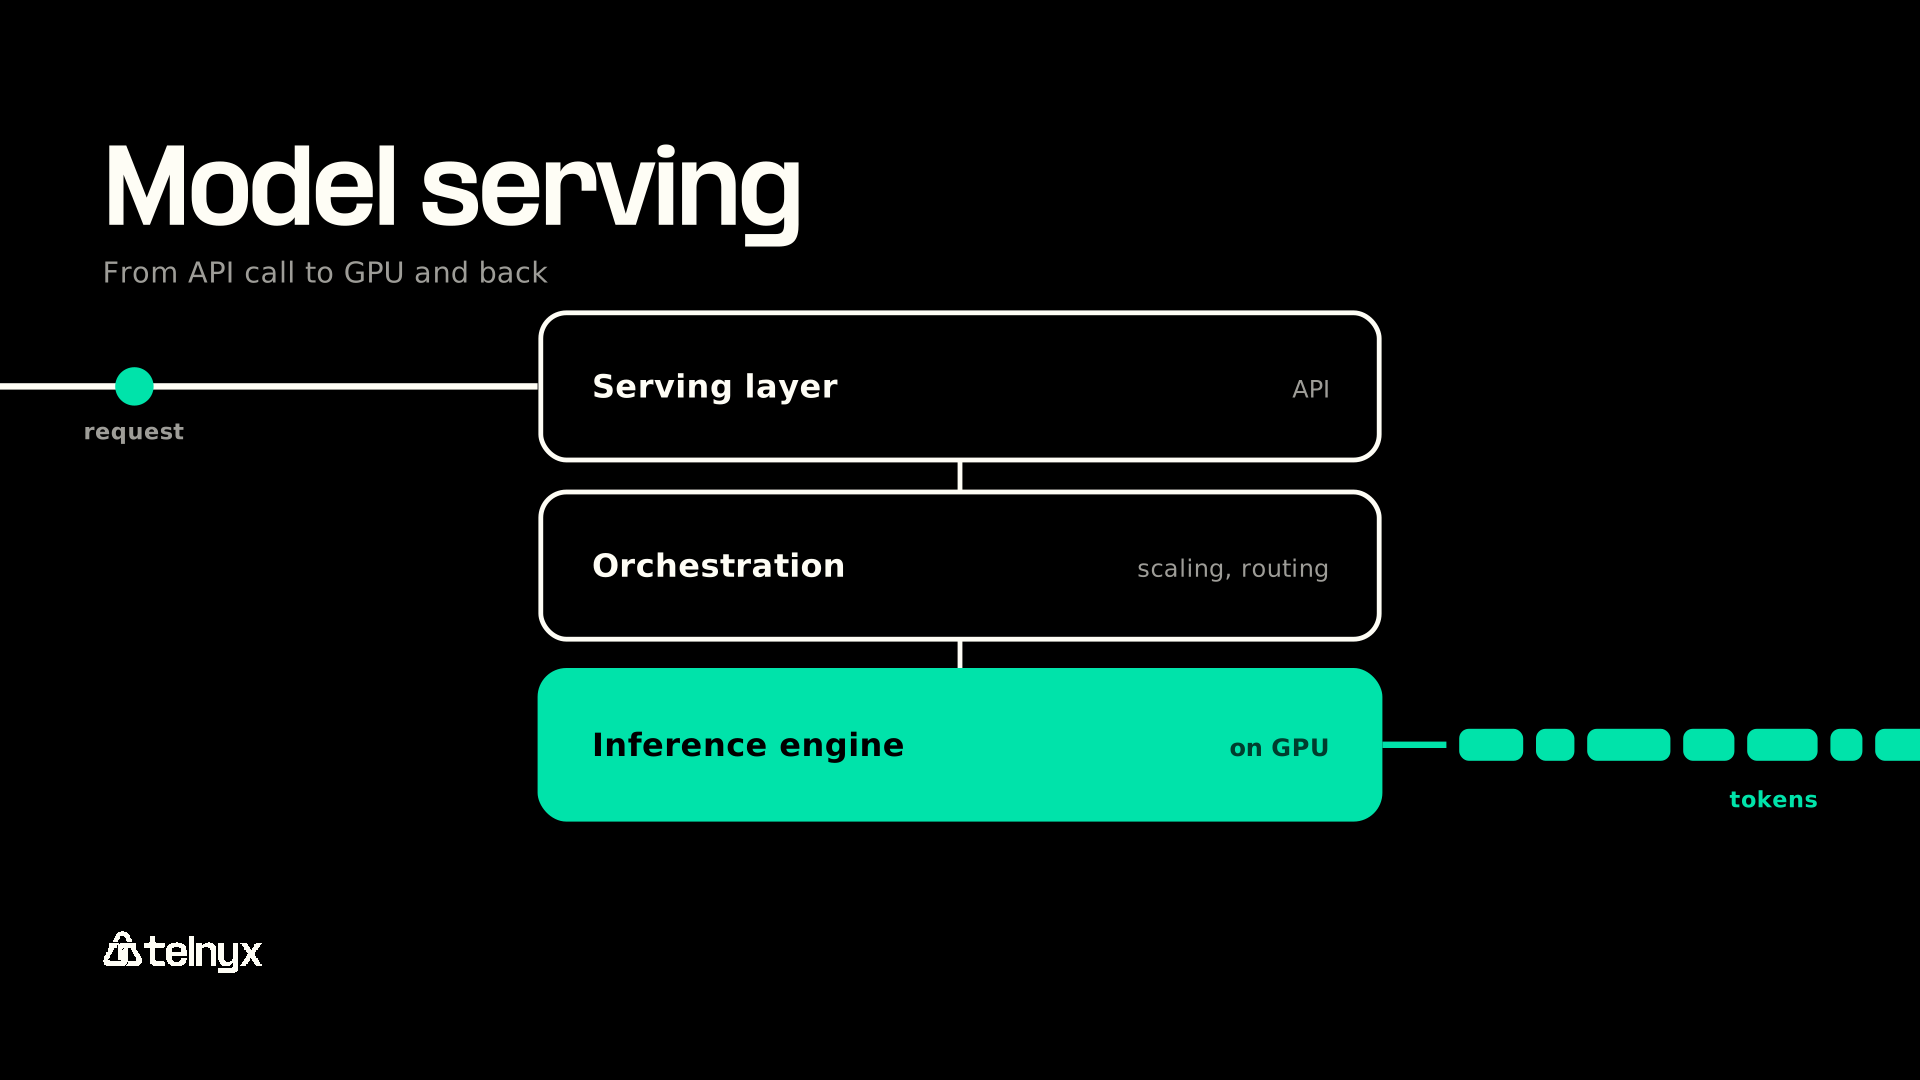
Model serving: how to run open-weight LLMs close to your users
Model serving keeps a trained model on GPUs and answers requests through an API. Learn the three layers of LLM serving and how to run open-weight models in-reg...
 Edge Compute
Edge computing applications: 12 real use cases and latency budgets
Real edge computing applications, what they solve, and how teams deploy edge architectures in production.
 Inference
The best open source LLMs in 2026 for coding, agents, and voice
Last updated: September 28, 2026. Open model versions change monthly, so every pick below carries a release date and states whether its benchmark score is vendor-reported or independently measured.
 Conversational AI
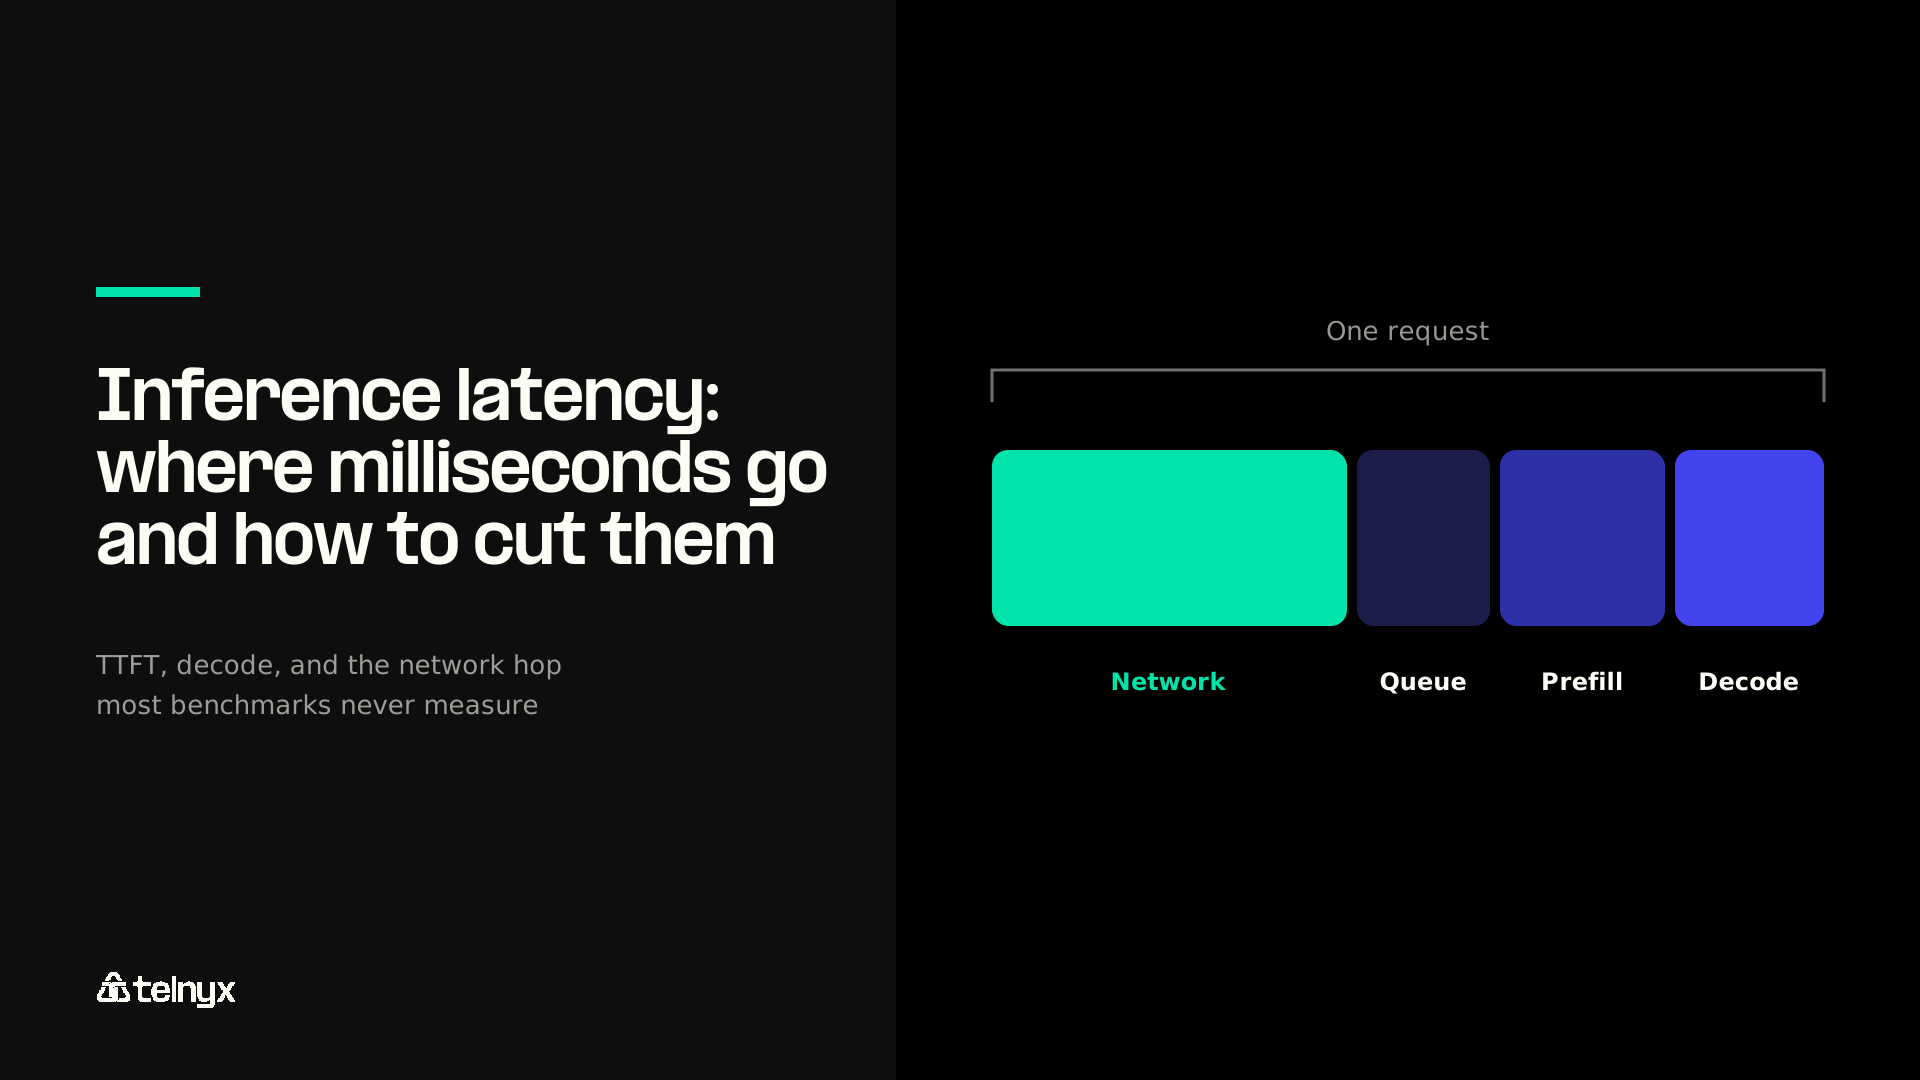
Inference latency: where milliseconds go and how to cut them
Inference latency is a systems problem, not just a model problem. The model is one of three layers, and for real-time AI it is rarely the layer with the most latency to give back.
 Guides and Tutorials
Synthetic speech detection: Why infrastructure ownership decides who wins
Practical synthetic speech detection for real world voice: What works, what breaks, and how to deploy it.
 Inference
TPU vs GPU Compared for AI Training and Inference
This guide covers the architecture behind each chip, verified benchmark and migration data, framework ecosystems...
 Insights and Resources
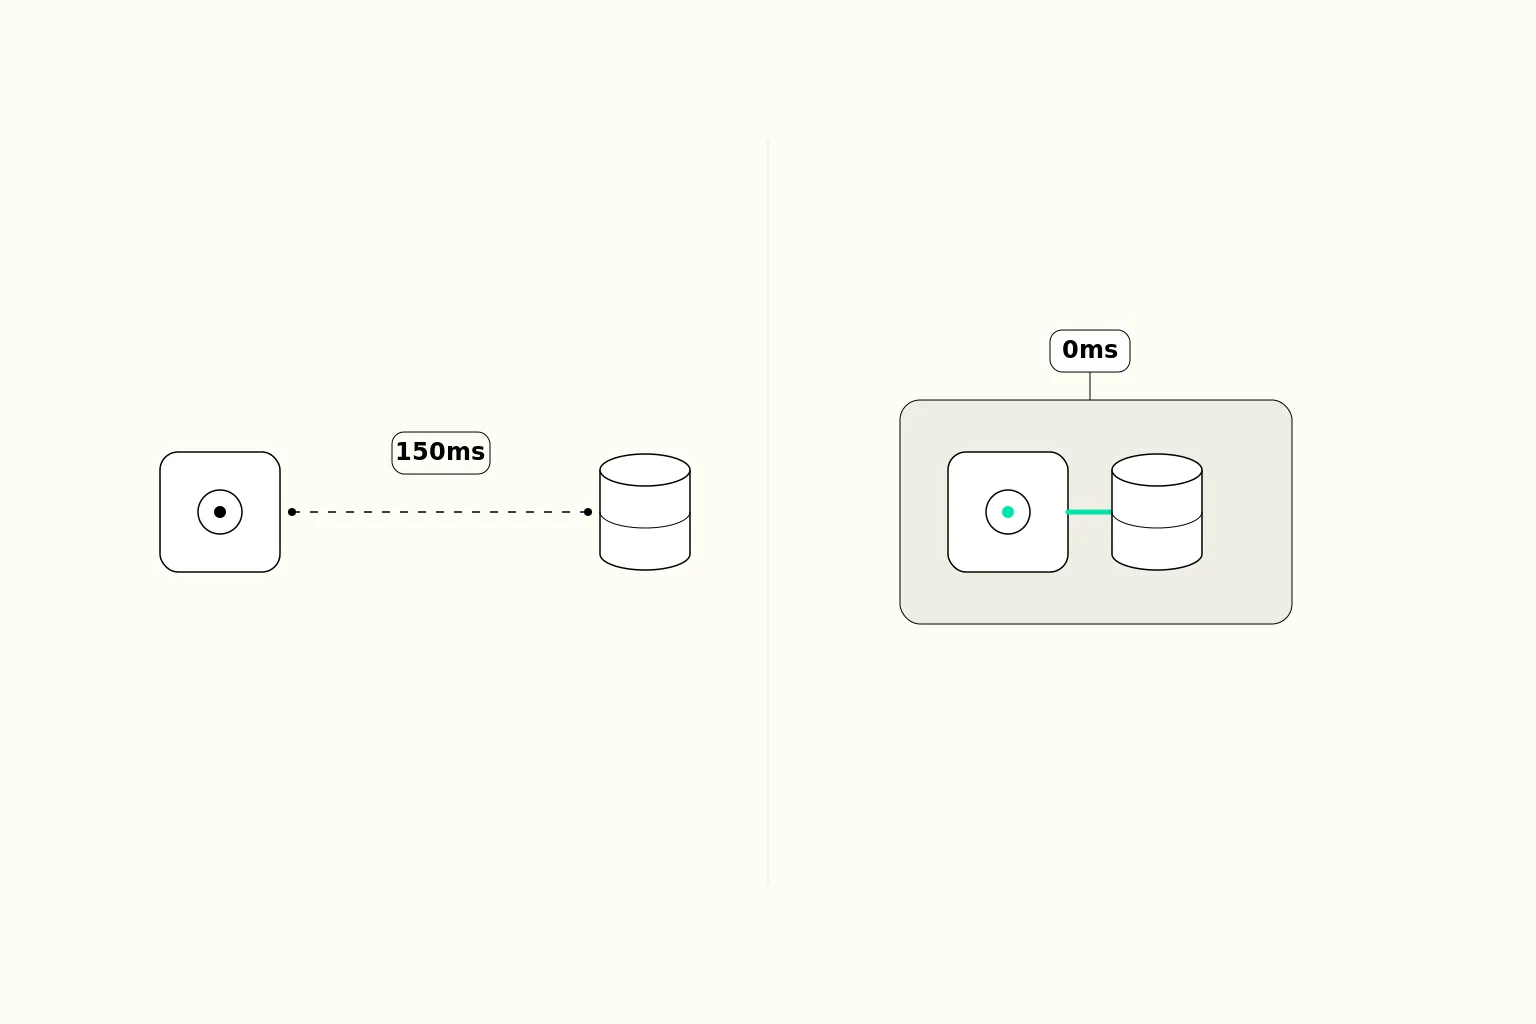
Stateful Edge Functions
Stateful edge functions give edge compute persistent state without database round trips. Learn what they are, how they work, and why SQL at the edge matters.
 Telnyx
The 6 Best SMS Marketing Platforms in 2026
The 6 best SMS marketing platforms compared by API access, pricing, compliance tools, and deliverability. Find the right platform for your business.
 SIP Trunking
SIP trunking cost: what you actually pay by pricing model
This guide breaks down the two dominant SIP trunking pricing models...
 Insights and Resources
How to use a serverless SQL database for edge functions
A serverless SQL database for edge functions scales to zero, speaks HTTP, and places data near the function runtime. Learn how it works, compare providers, and set up Telnyx SQL Database with TypeScript.
 Edge Compute
DevOps Automation Tools for AI Agents
DevOps automation tools for AI voice agents cover six stages. See what a multi-vendor stack adds and where an integrated platform reduces the work.
 Guides and Tutorials
What is a fine-tuning API, and where should the weights actually run?
This guide defines the term, walks through the parameter-efficient methods that made fine-tuning affordable, covers the safety guardrails the research community now considers mandatory...
 Voice
Conversational AI vs. Generative AI
Compare conversational AI and generative AI by purpose, intent, and use cases. Learn the key differences and how they complement each other.
 Wireless
What is a machine-to-machine (M2M) SIM card?
Machine-to-machine (M2M) SIM cards are the key to innovation, optimization, and enhanced IoT security. Keep reading to learn why.
 IoT
What is IMSI switching, and how does it work?
IMSI switching allows devices to natively connect to multiple different networks across the globe. Learn about IMSI switching, its benefits, and use cases.
 Conversational AI
E-commerce and contact centers: Selling digitally
Learn how an e-commerce contact center with the right tools can boost customer satisfaction and sales.
 Conversational AI
What is distributed inference?
Distributed inference is the practice of running model inference across multiple machines or geographic regions rather than a single server.
 Networking
What is inference engineering and why it matters
Inference engineering optimizes how a model serves predictions, not what the model says.
 Insights and Resources
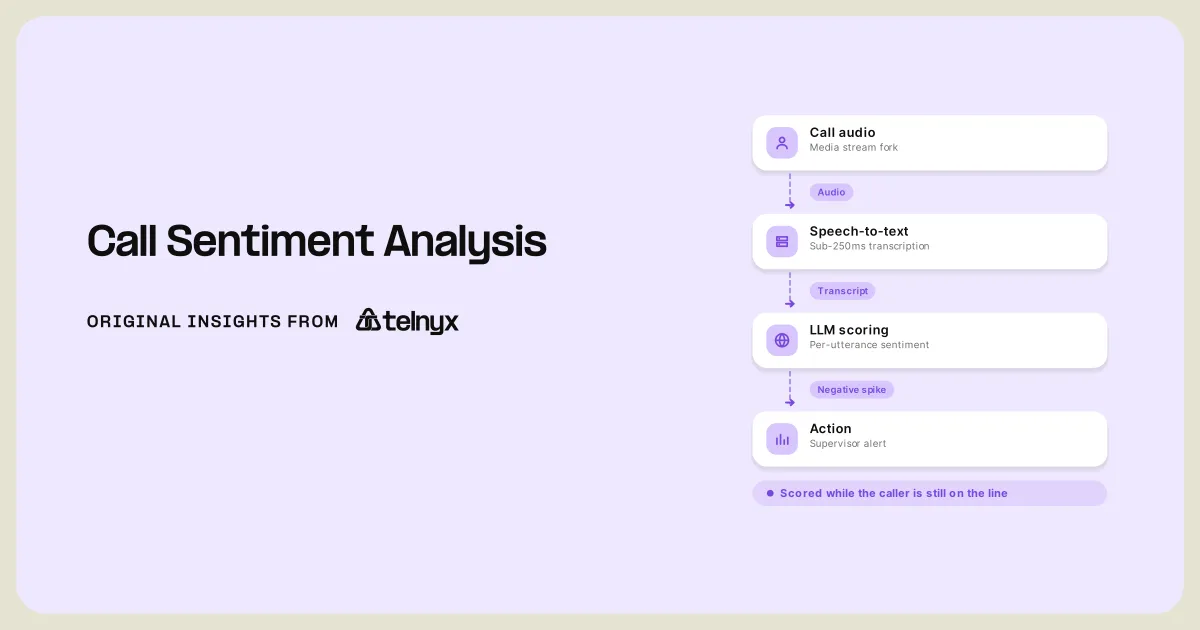
Call Sentiment Analysis How It Works and Why It Matters
Learn how call sentiment analysis works, the customer insight use cases it unlocks, and the tools and providers that turn every call into action.
 Conversational AI
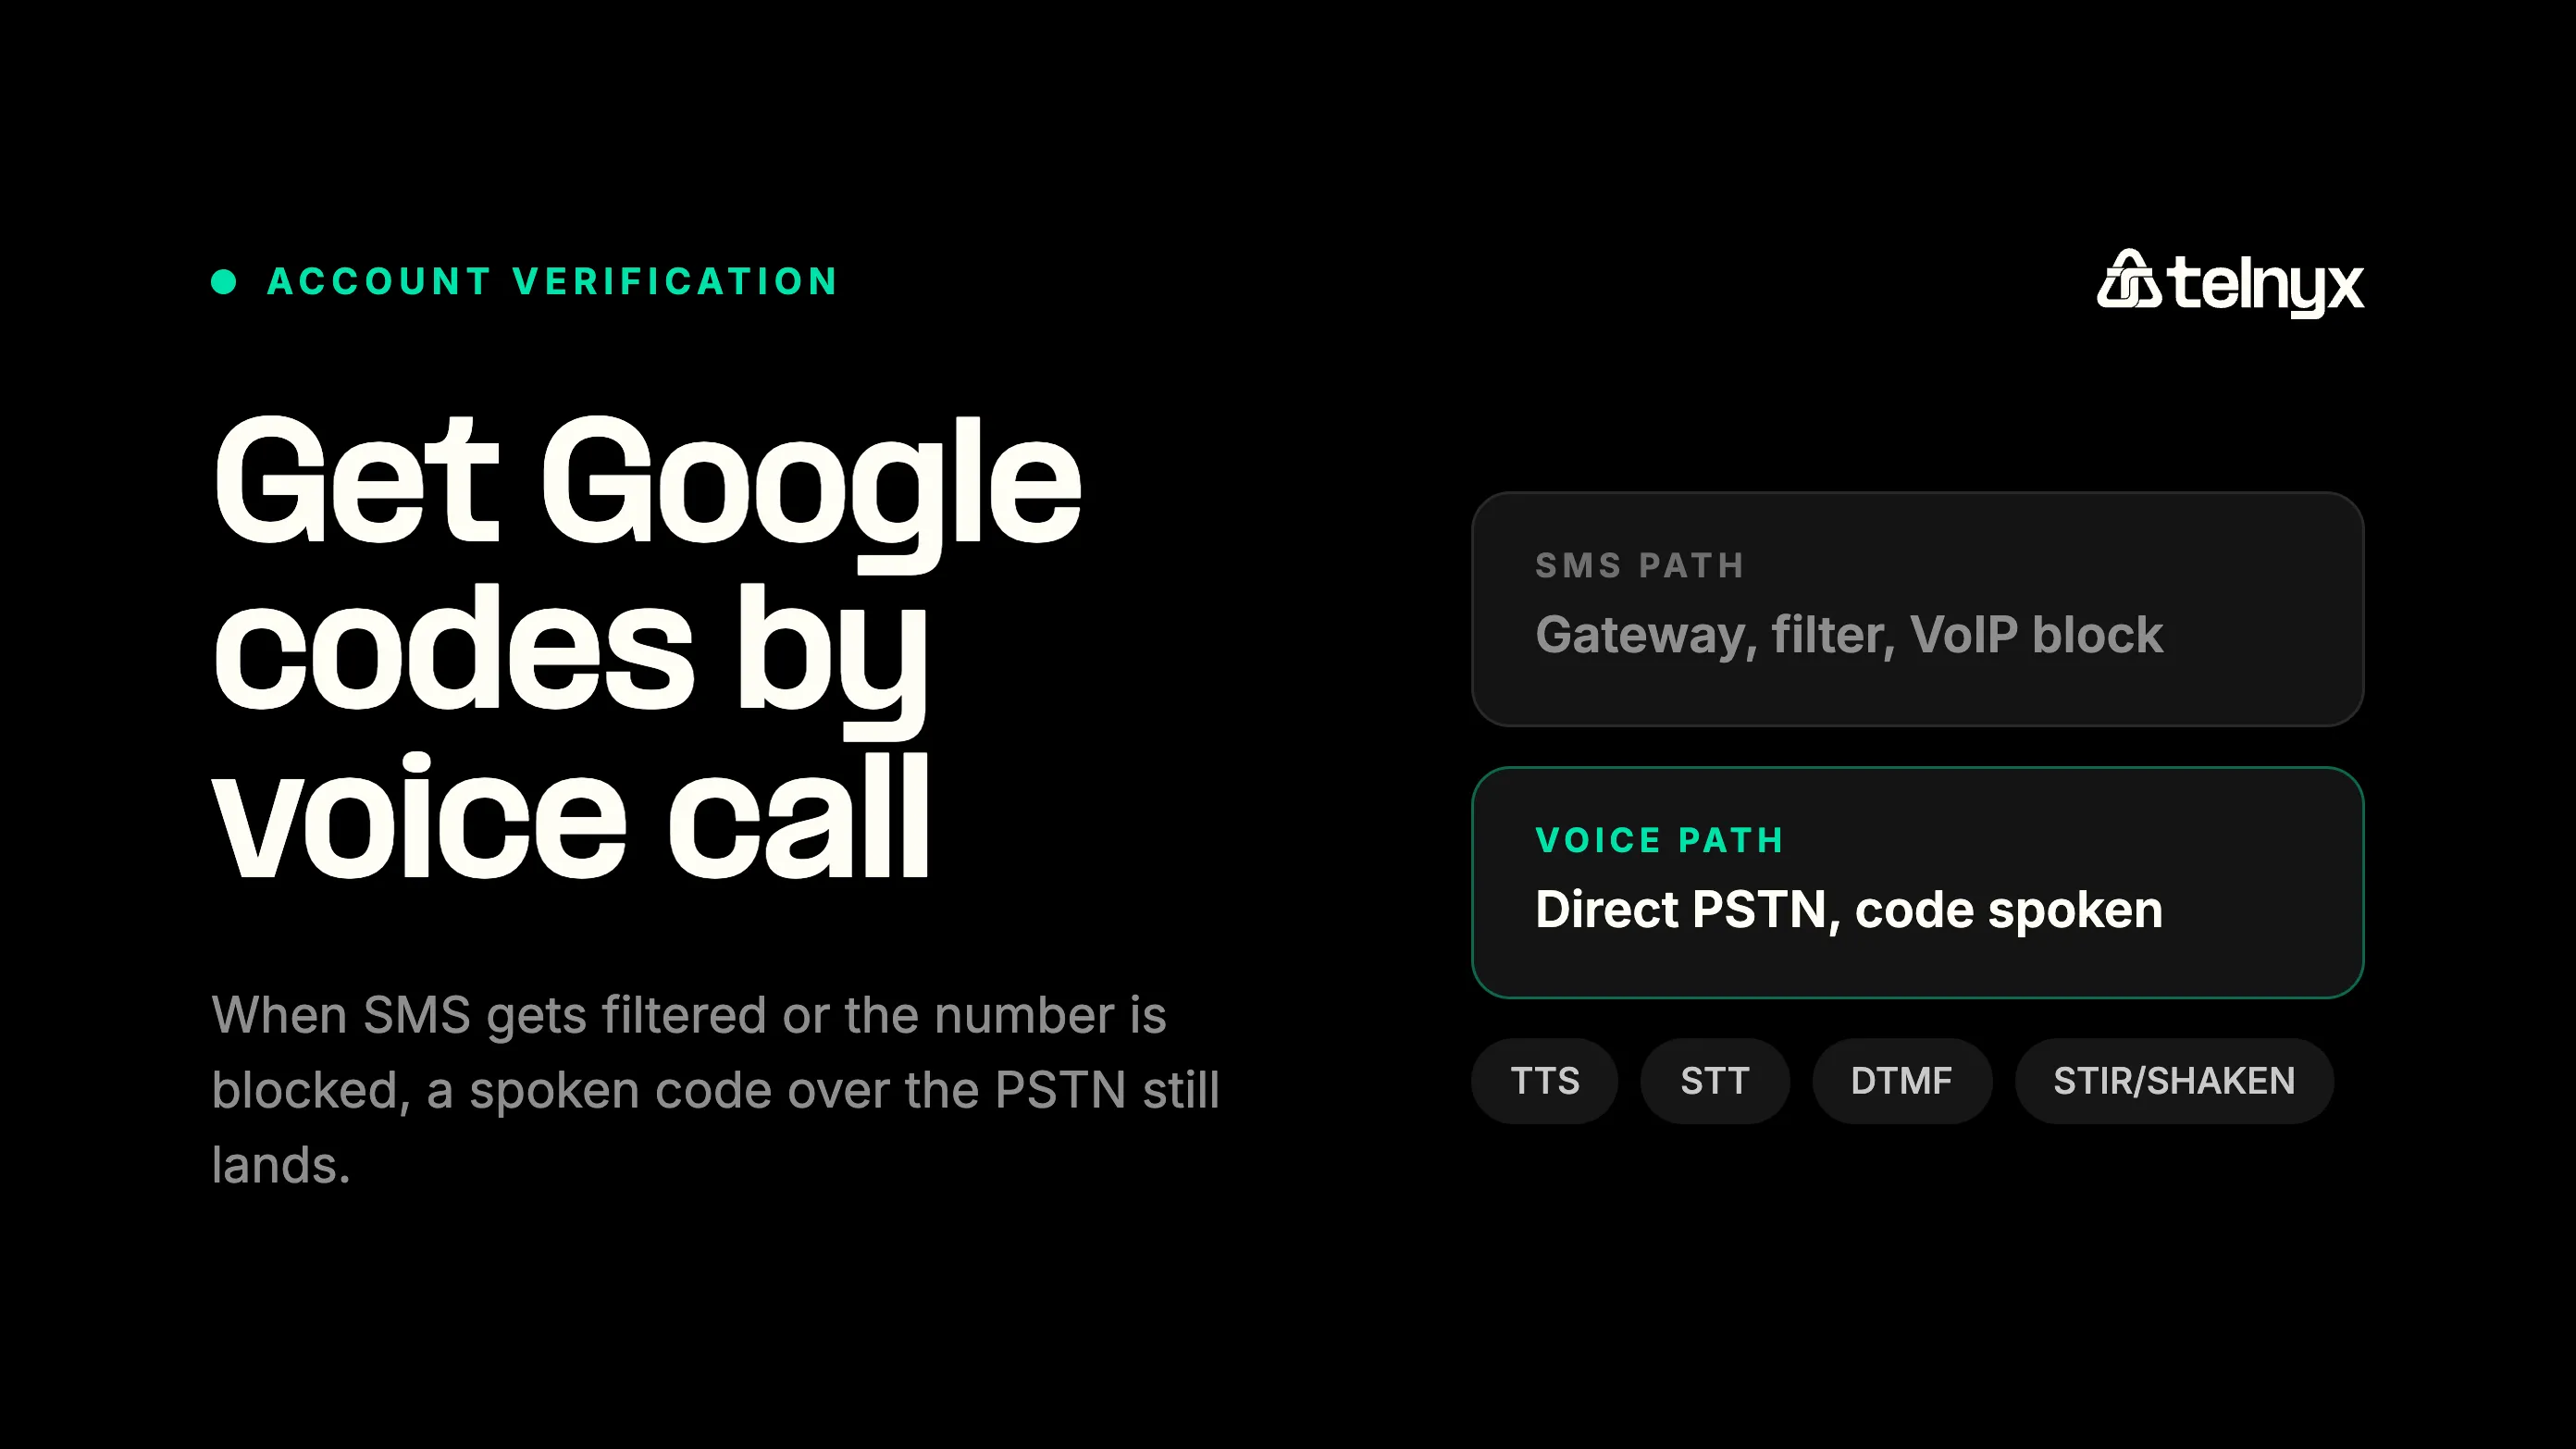
Google voice verification: why voice beats SMS
SMS works for most verification flows. But when carrier filtering or VoIP restrictions block delivery, voice calls provide a reliable fallback.
 Insights and Resources
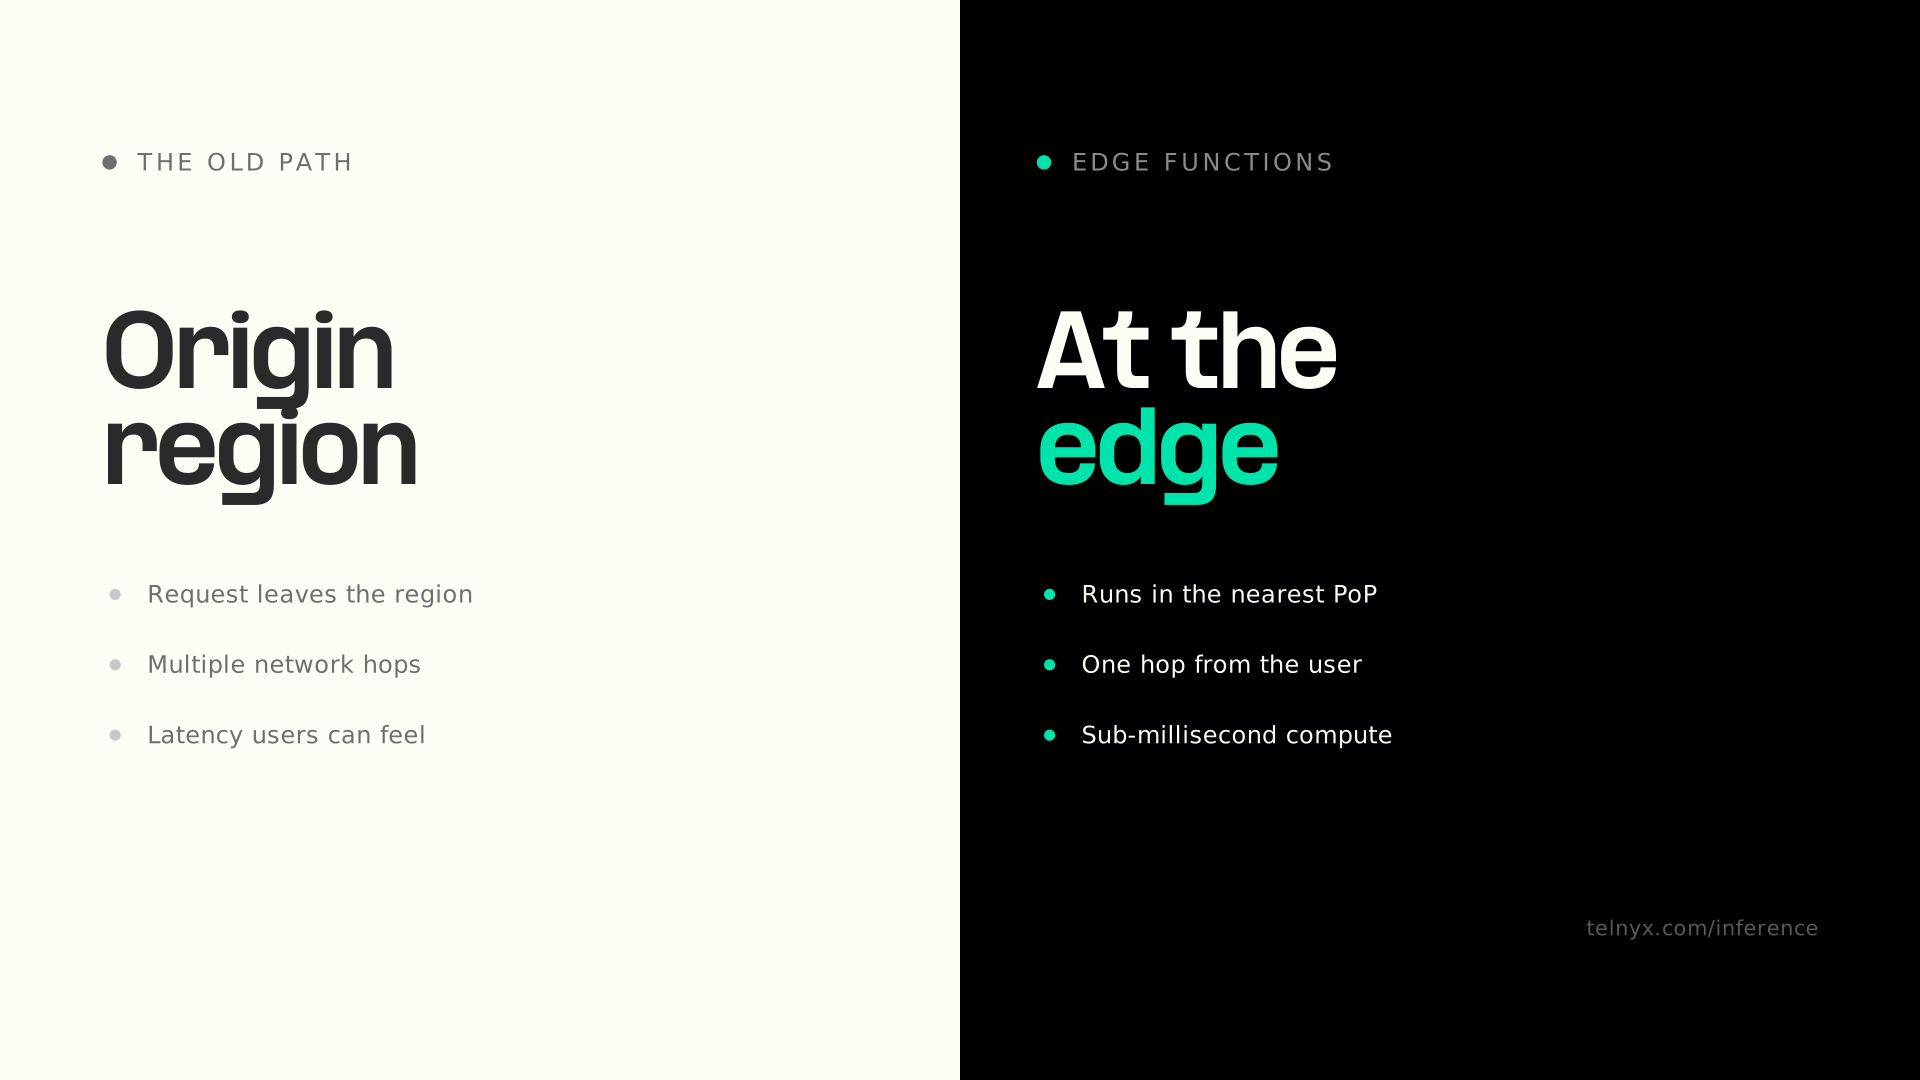
What are edge functions and how they work
Edge functions run server-side code at data centers close to your users. Learn how they work, how they compare to serverless, and how to choose the right edge platform.
 Telnyx
AI Dev Ops: Practical guide to automate IT operations
Learn how AI Ops cuts alert noise, automates root cause analysis and remediation, and keeps large-scale voice and AI agent operations reliable, high-quality, and cost-efficient.


